Intel 64 and IA-32 Architectures. Software Developer’s Manual (2026) - page 40
Intel C/C++ Compiler Intrinsic Equivalent
VPSLLVW __m512i _mm512_sllv_epi16(__m512i a, __m512i cnt);
VPSLLVW __m512i _mm512_mask_sllv_epi16(__m512i s, __mmask32 k, __m512i a, __m512i cnt);
VPSLLVW __m512i _mm512_maskz_sllv_epi16( __mmask32 k, __m512i a, __m512i cnt);
VPSLLVW __m256i _mm256_mask_sllv_epi16(__m256i s, __mmask16 k, __m256i a, __m256i cnt);
VPSLLVW __m256i _mm256_maskz_sllv_epi16( __mmask16 k, __m256i a, __m256i cnt);
VPSLLVW __m128i _mm_mask_sllv_epi16(__m128i s, __mmask8 k, __m128i a, __m128i cnt);
VPSLLVW __m128i _mm_maskz_sllv_epi16( __mmask8 k, __m128i a, __m128i cnt);
VPSLLVD __m512i _mm512_sllv_epi32(__m512i a, __m512i cnt);
VPSLLVD __m512i _mm512_mask_sllv_epi32(__m512i s, __mmask16 k, __m512i a, __m512i cnt);
VPSLLVD __m512i _mm512_maskz_sllv_epi32( __mmask16 k, __m512i a, __m512i cnt);
VPSLLVD __m256i _mm256_mask_sllv_epi32(__m256i s, __mmask8 k, __m256i a, __m256i cnt);
VPSLLVD __m256i _mm256_maskz_sllv_epi32( __mmask8 k, __m256i a, __m256i cnt);
VPSLLVD __m128i _mm_mask_sllv_epi32(__m128i s, __mmask8 k, __m128i a, __m128i cnt);
VPSLLVD __m128i _mm_maskz_sllv_epi32( __mmask8 k, __m128i a, __m128i cnt);
VPSLLVQ __m512i _mm512_sllv_epi64(__m512i a, __m512i cnt);
VPSLLVQ __m512i _mm512_mask_sllv_epi64(__m512i s, __mmask8 k, __m512i a, __m512i cnt);
VPSLLVQ __m512i _mm512_maskz_sllv_epi64( __mmask8 k, __m512i a, __m512i cnt);
VPSLLVD __m256i _mm256_mask_sllv_epi64(__m256i s, __mmask8 k, __m256i a, __m256i cnt);
VPSLLVD __m256i _mm256_maskz_sllv_epi64( __mmask8 k, __m256i a, __m256i cnt);
VPSLLVD __m128i _mm_mask_sllv_epi64(__m128i s, __mmask8 k, __m128i a, __m128i cnt);
VPSLLVD __m128i _mm_maskz_sllv_epi64( __mmask8 k, __m128i a, __m128i cnt);
VPSLLVD __m256i _mm256_sllv_epi32 (__m256i m, __m256i count)
VPSLLVQ __m256i _mm256_sllv_epi64 (__m256i m, __m256i count)
SIMD Floating-Point Exceptions
None.
Other Exceptions
VEX-encoded instructions, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded VPSLLVD/VPSLLVQ, see Table 2-51, “Type E4 Class Exception Conditions.”
EVEX-encoded VPSLLVW, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPSLLVW/VPSLLVD/VPSLLVQ-Variable Bit Shift Left Logical
Vol. 2C
5-640

VPSRAVW/VPSRAVD/VPSRAVQ-Variable Bit Shift Right Arithmetic
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 46 /r
A
V/V
AVX2
Shift doublewords in xmm2 right by amount
VPSRAVD xmm1, xmm2, xmm3/m128
specified in the corresponding element of
xmm3/m128 while shifting in sign bits.
VEX.256.66.0F38.W0 46 /r
A
V/V
AVX2
Shift doublewords in ymm2 right by amount
VPSRAVD ymm1, ymm2, ymm3/m256
specified in the corresponding element of
ymm3/m256 while shifting in sign bits.
EVEX.128.66.0F38.W1 11 /r
B
V/V
(AVX512VL AND
Shift words in xmm2 right by amount specified
VPSRAVW xmm1 {k1}{z}, xmm2,
AVX512BW) OR
in the corresponding element of xmm3/m128
xmm3/m128
AVX10.1
while shifting in sign bits using writemask k1.
EVEX.256.66.0F38.W1 11 /r
B
V/V
(AVX512VL AND
Shift words in ymm2 right by amount specified
VPSRAVW ymm1 {k1}{z}, ymm2,
AVX512BW) OR
in the corresponding element of ymm3/m256
ymm3/m256
AVX10.1
while shifting in sign bits using writemask k1.
EVEX.512.66.0F38.W1 11 /r
B
V/V
AVX512BW
Shift words in zmm2 right by amount specified in
VPSRAVW zmm1 {k1}{z}, zmm2,
OR AVX10.1
the corresponding element of zmm3/m512
zmm3/m512
while shifting in sign bits using writemask k1.
EVEX.128.66.0F38.W0 46 /r
C
V/V
(AVX512VL AND
Shift doublewords in xmm2 right by amount
VPSRAVD xmm1 {k1}{z}, xmm2,
AVX512F) OR
specified in the corresponding element of
xmm3/m128/m32bcst
AVX10.1
xmm3/m128/m32bcst while shifting in sign bits
using writemask k1.
EVEX.256.66.0F38.W0 46 /r
C
V/V
(AVX512VL AND
Shift doublewords in ymm2 right by amount
VPSRAVD ymm1 {k1}{z}, ymm2,
AVX512F) OR
specified in the corresponding element of
ymm3/m256/m32bcst
AVX10.1
ymm3/m256/m32bcst while shifting in sign bits
using writemask k1.
EVEX.512.66.0F38.W0 46 /r
C
V/V
AVX512F
Shift doublewords in zmm2 right by amount
VPSRAVD zmm1 {k1}{z}, zmm2,
OR AVX10.1
specified in the corresponding element of
zmm3/m512/m32bcst
zmm3/m512/m32bcst while shifting in sign bits
using writemask k1.
EVEX.128.66.0F38.W1 46 /r
C
V/V
(AVX512VL AND
Shift quadwords in xmm2 right by amount
VPSRAVQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
specified in the corresponding element of
xmm3/m128/m64bcst
AVX10.1
xmm3/m128/m64bcst while shifting in sign bits
using writemask k1.
EVEX.256.66.0F38.W1 46 /r
C
V/V
(AVX512VL AND
Shift quadwords in ymm2 right by amount
VPSRAVQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
specified in the corresponding element of
ymm3/m256/m64bcst
AVX10.1
ymm3/m256/m64bcst while shifting in sign bits
using writemask k1.
EVEX.512.66.0F38.W1 46 /r
C
V/V
AVX512F
Shift quadwords in zmm2 right by amount
VPSRAVQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
specified in the corresponding element of
zmm3/m512/m64bcst
zmm3/m512/m64bcst while shifting in sign bits
using writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
VPSRAVW/VPSRAVD/VPSRAVQ-Variable Bit Shift Right Arithmetic
Vol. 2C
5-641
Description
Shifts the bits in the individual data elements (word/doublewords/quadword) in the first source operand (the
second operand) to the right by the number of bits specified in the count value of respective data elements in the
second source operand (the third operand). As the bits in the data elements are shifted right, the empty high-order
bits are set to the MSB (sign extension).
The count values are specified individually in each data element of the second source operand. If the unsigned
integer value specified in the respective data element of the second source operand is greater than 15 (for words),
31 (for doublewords), or 63 (for a quadword), then the destination data element is filled with the corresponding
sign bit of the source element.
VEX.128 encoded version: The destination and first source operands are XMM registers. The count operand can be
either an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination register
are zeroed.
VEX.256 encoded version: The destination and first source operands are YMM registers. The count operand can be
either an YMM register or a 256-bit memory. Bits (MAXVL-1:256) of the corresponding destination register are
zeroed.
EVEX.512/256/128 encoded VPSRAVD/W: The destination and first source operands are ZMM/YMM/XMM registers.
The count operand can be either a ZMM/YMM/XMM register, a 512/256/128-bit memory location or a
512/256/128-bit vector broadcasted from a 32/64-bit memory location. The destination is conditionally updated
with writemask k1.
EVEX.512/256/128 encoded VPSRAVQ: The destination and first source operands are ZMM/YMM/XMM registers.
The count operand can be either a ZMM/YMM/XMM register, a 512/256/128-bit memory location. The destination
is conditionally updated with writemask k1.
Operation
VPSRAVW (EVEX encoded version)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN
COUNT := SRC2[i+3:i]
IF COUNT < 16
THEN DEST[i+15:i] := SignExtend(SRC1[i+15:i] >> COUNT)
ELSE
FOR k := 0 TO 15
DEST[i+k] := SRC1[i+15]
ENDFOR;
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0;
VPSRAVD (VEX.128 version)
COUNT_0 := SRC2[31 : 0]
(* Repeat Each COUNT_i for the 2nd through 4th dwords of SRC2*)
COUNT_3 := SRC2[127 : 96];
DEST[31:0] := SignExtend(SRC1[31:0] >> COUNT_0);
VPSRAVW/VPSRAVD/VPSRAVQ-Variable Bit Shift Right Arithmetic
Vol. 2C
5-642
(* Repeat shift operation for 2nd through 4th dwords *)
DEST[127:96] := SignExtend(SRC1[127:96] >> COUNT_3);
DEST[MAXVL-1:128] := 0;
VPSRAVD (VEX.256 version)
COUNT_0 := SRC2[31 : 0];
(* Repeat Each COUNT_i for the 2nd through 8th dwords of SRC2*)
COUNT_7 := SRC2[255 : 224];
DEST[31:0] := SignExtend(SRC1[31:0] >> COUNT_0);
(* Repeat shift operation for 2nd through 7th dwords *)
DEST[255:224] := SignExtend(SRC1[255:224] >> COUNT_7);
DEST[MAXVL-1:256] := 0;
VPSRAVD (EVEX encoded version)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
COUNT := SRC2[4:0]
IF COUNT < 32
THEN DEST[i+31:i] := SignExtend(SRC1[i+31:i] >> COUNT)
ELSE
FOR k := 0 TO 31
DEST[i+k] := SRC1[i+31]
ENDFOR;
FI
ELSE
COUNT := SRC2[i+4:i]
IF COUNT < 32
THEN DEST[i+31:i] := SignExtend(SRC1[i+31:i] >> COUNT)
ELSE
FOR k := 0 TO 31
DEST[i+k] := SRC1[i+31]
ENDFOR;
FI
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
DEST[31:0] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0;
VPSRAVQ (EVEX encoded version)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
VPSRAVW/VPSRAVD/VPSRAVQ-Variable Bit Shift Right Arithmetic
Vol. 2C
5-643
THEN
COUNT := SRC2[5:0]
IF COUNT < 64
THEN DEST[i+63:i] := SignExtend(SRC1[i+63:i] >> COUNT)
ELSE
FOR k := 0 TO 63
DEST[i+k] := SRC1[i+63]
ENDFOR;
FI
ELSE
COUNT := SRC2[i+5:i]
IF COUNT < 64
THEN DEST[i+63:i] := SignExtend(SRC1[i+63:i] >> COUNT)
ELSE
FOR k := 0 TO 63
DEST[i+k] := SRC1[i+63]
ENDFOR;
FI
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
DEST[63:0] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0;
VPSRAVW/VPSRAVD/VPSRAVQ-Variable Bit Shift Right Arithmetic
Vol. 2C
5-644
Intel C/C++ Compiler Intrinsic Equivalent
VPSRAVD __m512i _mm512_srav_epi32(__m512i a, __m512i cnt);
VPSRAVD __m512i _mm512_mask_srav_epi32(__m512i s, __mmask16 m, __m512i a, __m512i cnt);
VPSRAVD __m512i _mm512_maskz_srav_epi32(__mmask16 m, __m512i a, __m512i cnt);
VPSRAVD __m256i _mm256_srav_epi32(__m256i a, __m256i cnt);
VPSRAVD __m256i _mm256_mask_srav_epi32(__m256i s, __mmask8 m, __m256i a, __m256i cnt);
VPSRAVD __m256i _mm256_maskz_srav_epi32(__mmask8 m, __m256i a, __m256i cnt);
VPSRAVD __m128i _mm_srav_epi32(__m128i a, __m128i cnt);
VPSRAVD __m128i _mm_mask_srav_epi32(__m128i s, __mmask8 m, __m128i a, __m128i cnt);
VPSRAVD __m128i _mm_maskz_srav_epi32(__mmask8 m, __m128i a, __m128i cnt);
VPSRAVQ __m512i _mm512_srav_epi64(__m512i a, __m512i cnt);
VPSRAVQ __m512i _mm512_mask_srav_epi64(__m512i s, __mmask8 m, __m512i a, __m512i cnt);
VPSRAVQ __m512i _mm512_maskz_srav_epi64( __mmask8 m, __m512i a, __m512i cnt);
VPSRAVQ __m256i _mm256_srav_epi64(__m256i a, __m256i cnt);
VPSRAVQ __m256i _mm256_mask_srav_epi64(__m256i s, __mmask8 m, __m256i a, __m256i cnt);
VPSRAVQ __m256i _mm256_maskz_srav_epi64( __mmask8 m, __m256i a, __m256i cnt);
VPSRAVQ __m128i _mm_srav_epi64(__m128i a, __m128i cnt);
VPSRAVQ __m128i _mm_mask_srav_epi64(__m128i s, __mmask8 m, __m128i a, __m128i cnt);
VPSRAVQ __m128i _mm_maskz_srav_epi64( __mmask8 m, __m128i a, __m128i cnt);
VPSRAVW __m512i _mm512_srav_epi16(__m512i a, __m512i cnt);
VPSRAVW __m512i _mm512_mask_srav_epi16(__m512i s, __mmask32 m, __m512i a, __m512i cnt);
VPSRAVW __m512i _mm512_maskz_srav_epi16(__mmask32 m, __m512i a, __m512i cnt);
VPSRAVW __m256i _mm256_srav_epi16(__m256i a, __m256i cnt);
VPSRAVW __m256i _mm256_mask_srav_epi16(__m256i s, __mmask16 m, __m256i a, __m256i cnt);
VPSRAVW __m256i _mm256_maskz_srav_epi16(__mmask16 m, __m256i a, __m256i cnt);
VPSRAVW __m128i _mm_srav_epi16(__m128i a, __m128i cnt);
VPSRAVW __m128i _mm_mask_srav_epi16(__m128i s, __mmask8 m, __m128i a, __m128i cnt);
VPSRAVW __m128i _mm_maskz_srav_epi32(__mmask8 m, __m128i a, __m128i cnt);
VPSRAVD __m256i _mm256_srav_epi32 (__m256i m, __m256i count)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPSRAVW/VPSRAVD/VPSRAVQ-Variable Bit Shift Right Arithmetic
Vol. 2C
5-645

VPSRLVW/VPSRLVD/VPSRLVQ-Variable Bit Shift Right Logical
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 45 /r
A
V/V
AVX2
Shift doublewords in xmm2 right by amount
VPSRLVD xmm1, xmm2,
specified in the corresponding element of
xmm3/m128
xmm3/m128 while shifting in 0s.
VEX.128.66.0F38.W1 45 /r
A
V/V
AVX2
Shift quadwords in xmm2 right by amount
VPSRLVQ xmm1, xmm2,
specified in the corresponding element of
xmm3/m128
xmm3/m128 while shifting in 0s.
VEX.256.66.0F38.W0 45 /r
A
V/V
AVX2
Shift doublewords in ymm2 right by amount
VPSRLVD ymm1, ymm2,
specified in the corresponding element of
ymm3/m256
ymm3/m256 while shifting in 0s.
VEX.256.66.0F38.W1 45 /r
A
V/V
AVX2
Shift quadwords in ymm2 right by amount
VPSRLVQ ymm1, ymm2,
specified in the corresponding element of
ymm3/m256
ymm3/m256 while shifting in 0s.
EVEX.128.66.0F38.W1 10 /r
B
V/V
(AVX512VL AND
Shift words in xmm2 right by amount specified in
VPSRLVW xmm1 {k1}{z}, xmm2,
AVX512BW) OR
the corresponding element of xmm3/m128 while
xmm3/m128
AVX10.1
shifting in 0s using writemask k1.
EVEX.256.66.0F38.W1 10 /r
B
V/V
(AVX512VL AND
Shift words in ymm2 right by amount specified in
VPSRLVW ymm1 {k1}{z}, ymm2,
AVX512BW) OR
the corresponding element of ymm3/m256 while
ymm3/m256
AVX10.1
shifting in 0s using writemask k1.
EVEX.512.66.0F38.W1 10 /r
B
V/V
AVX512BW
Shift words in zmm2 right by amount specified in
VPSRLVW zmm1 {k1}{z}, zmm2,
OR AVX10.1
the corresponding element of zmm3/m512 while
zmm3/m512
shifting in 0s using writemask k1.
EVEX.128.66.0F38.W0 45 /r
C
V/V
(AVX512VL AND
Shift doublewords in xmm2 right by amount
VPSRLVD xmm1 {k1}{z}, xmm2,
AVX512F) OR
specified in the corresponding element of
xmm3/m128/m32bcst
AVX10.1
xmm3/m128/m32bcst while shifting in 0s using
writemask k1.
EVEX.256.66.0F38.W0 45 /r
C
V/V
(AVX512VL AND
Shift doublewords in ymm2 right by amount
VPSRLVD ymm1 {k1}{z}, ymm2,
AVX512F) OR
specified in the corresponding element of
ymm3/m256/m32bcst
AVX10.1
ymm3/m256/m32bcst while shifting in 0s using
writemask k1.
EVEX.512.66.0F38.W0 45 /r
C
V/V
AVX512F
Shift doublewords in zmm2 right by amount
VPSRLVD zmm1 {k1}{z}, zmm2,
OR AVX10.1
specified in the corresponding element of
zmm3/m512/m32bcst
zmm3/m512/m32bcst while shifting in 0s using
writemask k1.
EVEX.128.66.0F38.W1 45 /r
C
V/V
(AVX512VL AND
Shift quadwords in xmm2 right by amount
VPSRLVQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
specified in the corresponding element of
xmm3/m128/m64bcst
AVX10.1
xmm3/m128/m64bcst while shifting in 0s using
writemask k1.
EVEX.256.66.0F38.W1 45 /r
C
V/V
(AVX512VL AND
Shift quadwords in ymm2 right by amount
VPSRLVQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
specified in the corresponding element of
ymm3/m256/m64bcst
AVX10.1
ymm3/m256/m64bcst while shifting in 0s using
writemask k1.
EVEX.512.66.0F38.W1 45 /r
C
V/V
AVX512F
Shift quadwords in zmm2 right by amount
VPSRLVQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
specified in the corresponding element of
zmm3/m512/m64bcst
zmm3/m512/m64bcst while shifting in 0s using
writemask k1.
VPSRLVW/VPSRLVD/VPSRLVQ-Variable Bit Shift Right Logical
Vol. 2C
5-646

Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Shifts the bits in the individual data elements (words, doublewords or quadword) in the first source operand to the
right by the count value of respective data elements in the second source operand. As the bits in the data elements
are shifted right, the empty high-order bits are cleared (set to 0).
The count values are specified individually in each data element of the second source operand. If the unsigned
integer value specified in the respective data element of the second source operand is greater than 15 (for word),
31 (for doublewords), or 63 (for a quadword), then the destination data element are written with 0.
VEX.128 encoded version: The destination and first source operands are XMM registers. The count operand can be
either an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination register
are zeroed.
VEX.256 encoded version: The destination and first source operands are YMM registers. The count operand can be
either an YMM register or a 256-bit memory. Bits (MAXVL-1:256) of the corresponding ZMM register are zeroed.
EVEX encoded VPSRLVD/Q: The destination and first source operands are ZMM/YMM/XMM registers. The count
operand can be either a ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512-bit vector broad-
casted from a 32/64-bit memory location. The destination is conditionally updated with writemask k1.
EVEX encoded VPSRLVW: The destination and first source operands are ZMM/YMM/XMM registers. The count
operand can be either a ZMM/YMM/XMM register, a 512/256/128-bit memory location. The destination is condition-
ally updated with writemask k1.
Operation
VPSRLVW (EVEX encoded version)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := ZeroExtend(SRC1[i+15:i] >> SRC2[i+15:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0;
VPSRLVW/VPSRLVD/VPSRLVQ-Variable Bit Shift Right Logical
Vol. 2C
5-647
VPSRLVD (VEX.128 version)
COUNT_0 := SRC2[31 : 0]
(* Repeat Each COUNT_i for the 2nd through 4th dwords of SRC2*)
COUNT_3 := SRC2[127 : 96];
IF COUNT_0 < 32 THEN
DEST[31:0] := ZeroExtend(SRC1[31:0] >> COUNT_0);
ELSE
DEST[31:0] := 0;
(* Repeat shift operation for 2nd through 4th dwords *)
IF COUNT_3 < 32 THEN
DEST[127:96] := ZeroExtend(SRC1[127:96] >> COUNT_3);
ELSE
DEST[127:96] := 0;
DEST[MAXVL-1:128] := 0;
VPSRLVD (VEX.256 version)
COUNT_0 := SRC2[31 : 0];
(* Repeat Each COUNT_i for the 2nd through 7th dwords of SRC2*)
COUNT_7 := SRC2[255 : 224];
IF COUNT_0 < 32 THEN
DEST[31:0] := ZeroExtend(SRC1[31:0] >> COUNT_0);
ELSE
DEST[31:0] := 0;
(* Repeat shift operation for 2nd through 7th dwords *)
IF COUNT_7 < 32 THEN
DEST[255:224] := ZeroExtend(SRC1[255:224] >> COUNT_7);
ELSE
DEST[255:224] := 0;
DEST[MAXVL-1:256] := 0;
VPSRLVD (EVEX encoded version)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[i+31:i] := ZeroExtend(SRC1[i+31:i] >> SRC2[31:0])
ELSE DEST[i+31:i] := ZeroExtend(SRC1[i+31:i] >> SRC2[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0;
VPSRLVW/VPSRLVD/VPSRLVQ-Variable Bit Shift Right Logical
Vol. 2C
5-648
VPSRLVQ (VEX.128 version)
COUNT_0 := SRC2[63 : 0];
COUNT_1 := SRC2[127 : 64];
IF COUNT_0 < 64 THEN
DEST[63:0] := ZeroExtend(SRC1[63:0] >> COUNT_0);
ELSE
DEST[63:0] := 0;
IF COUNT_1 < 64 THEN
DEST[127:64] := ZeroExtend(SRC1[127:64] >> COUNT_1);
ELSE
DEST[127:64] := 0;
DEST[MAXVL-1:128] := 0;
VPSRLVQ (VEX.256 version)
COUNT_0 := SRC2[63 : 0];
(* Repeat Each COUNT_i for the 2nd through 4th dwords of SRC2*)
COUNT_3 := SRC2[255 : 192];
IF COUNT_0 < 64 THEN
DEST[63:0] := ZeroExtend(SRC1[63:0] >> COUNT_0);
ELSE
DEST[63:0] := 0;
(* Repeat shift operation for 2nd through 4th dwords *)
IF COUNT_3 < 64 THEN
DEST[255:192] := ZeroExtend(SRC1[255:192] >> COUNT_3);
ELSE
DEST[255:192] := 0;
DEST[MAXVL-1:256] := 0;
VPSRLVQ (EVEX encoded version)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[i+63:i] := ZeroExtend(SRC1[i+63:i] >> SRC2[63:0])
ELSE DEST[i+63:i] := ZeroExtend(SRC1[i+63:i] >> SRC2[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0;
VPSRLVW/VPSRLVD/VPSRLVQ-Variable Bit Shift Right Logical
Vol. 2C
5-649
Intel C/C++ Compiler Intrinsic Equivalent
VPSRLVW __m512i _mm512_srlv_epi16(__m512i a, __m512i cnt);
VPSRLVW __m512i _mm512_mask_srlv_epi16(__m512i s, __mmask32 k, __m512i a, __m512i cnt);
VPSRLVW __m512i _mm512_maskz_srlv_epi16( __mmask32 k, __m512i a, __m512i cnt);
VPSRLVW __m256i _mm256_mask_srlv_epi16(__m256i s, __mmask16 k, __m256i a, __m256i cnt);
VPSRLVW __m256i _mm256_maskz_srlv_epi16( __mmask16 k, __m256i a, __m256i cnt);
VPSRLVW __m128i _mm_mask_srlv_epi16(__m128i s, __mmask8 k, __m128i a, __m128i cnt);
VPSRLVW __m128i _mm_maskz_srlv_epi16( __mmask8 k, __m128i a, __m128i cnt);
VPSRLVW __m256i _mm256_srlv_epi32 (__m256i m, __m256i count)
VPSRLVD __m512i _mm512_srlv_epi32(__m512i a, __m512i cnt);
VPSRLVD __m512i _mm512_mask_srlv_epi32(__m512i s, __mmask16 k, __m512i a, __m512i cnt);
VPSRLVD __m512i _mm512_maskz_srlv_epi32( __mmask16 k, __m512i a, __m512i cnt);
VPSRLVD __m256i _mm256_mask_srlv_epi32(__m256i s, __mmask8 k, __m256i a, __m256i cnt);
VPSRLVD __m256i _mm256_maskz_srlv_epi32( __mmask8 k, __m256i a, __m256i cnt);
VPSRLVD __m128i _mm_mask_srlv_epi32(__m128i s, __mmask8 k, __m128i a, __m128i cnt);
VPSRLVD __m128i _mm_maskz_srlv_epi32( __mmask8 k, __m128i a, __m128i cnt);
VPSRLVQ __m512i _mm512_srlv_epi64(__m512i a, __m512i cnt);
VPSRLVQ __m512i _mm512_mask_srlv_epi64(__m512i s, __mmask8 k, __m512i a, __m512i cnt);
VPSRLVQ __m512i _mm512_maskz_srlv_epi64( __mmask8 k, __m512i a, __m512i cnt);
VPSRLVQ __m256i _mm256_mask_srlv_epi64(__m256i s, __mmask8 k, __m256i a, __m256i cnt);
VPSRLVQ __m256i _mm256_maskz_srlv_epi64( __mmask8 k, __m256i a, __m256i cnt);
VPSRLVQ __m128i _mm_mask_srlv_epi64(__m128i s, __mmask8 k, __m128i a, __m128i cnt);
VPSRLVQ __m128i _mm_maskz_srlv_epi64( __mmask8 k, __m128i a, __m128i cnt);
VPSRLVQ __m256i _mm256_srlv_epi64 (__m256i m, __m256i count)
VPSRLVD __m128i _mm_srlv_epi32( __m128i a, __m128i cnt);
VPSRLVQ __m128i _mm_srlv_epi64( __m128i a, __m128i cnt);
SIMD Floating-Point Exceptions
None.
Other Exceptions
VEX-encoded instructions, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded VPSRLVD/Q, see Table 2-51, “Type E4 Class Exception Conditions.”
EVEX-encoded VPSRLVW, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPSRLVW/VPSRLVD/VPSRLVQ-Variable Bit Shift Right Logical
Vol. 2C
5-650
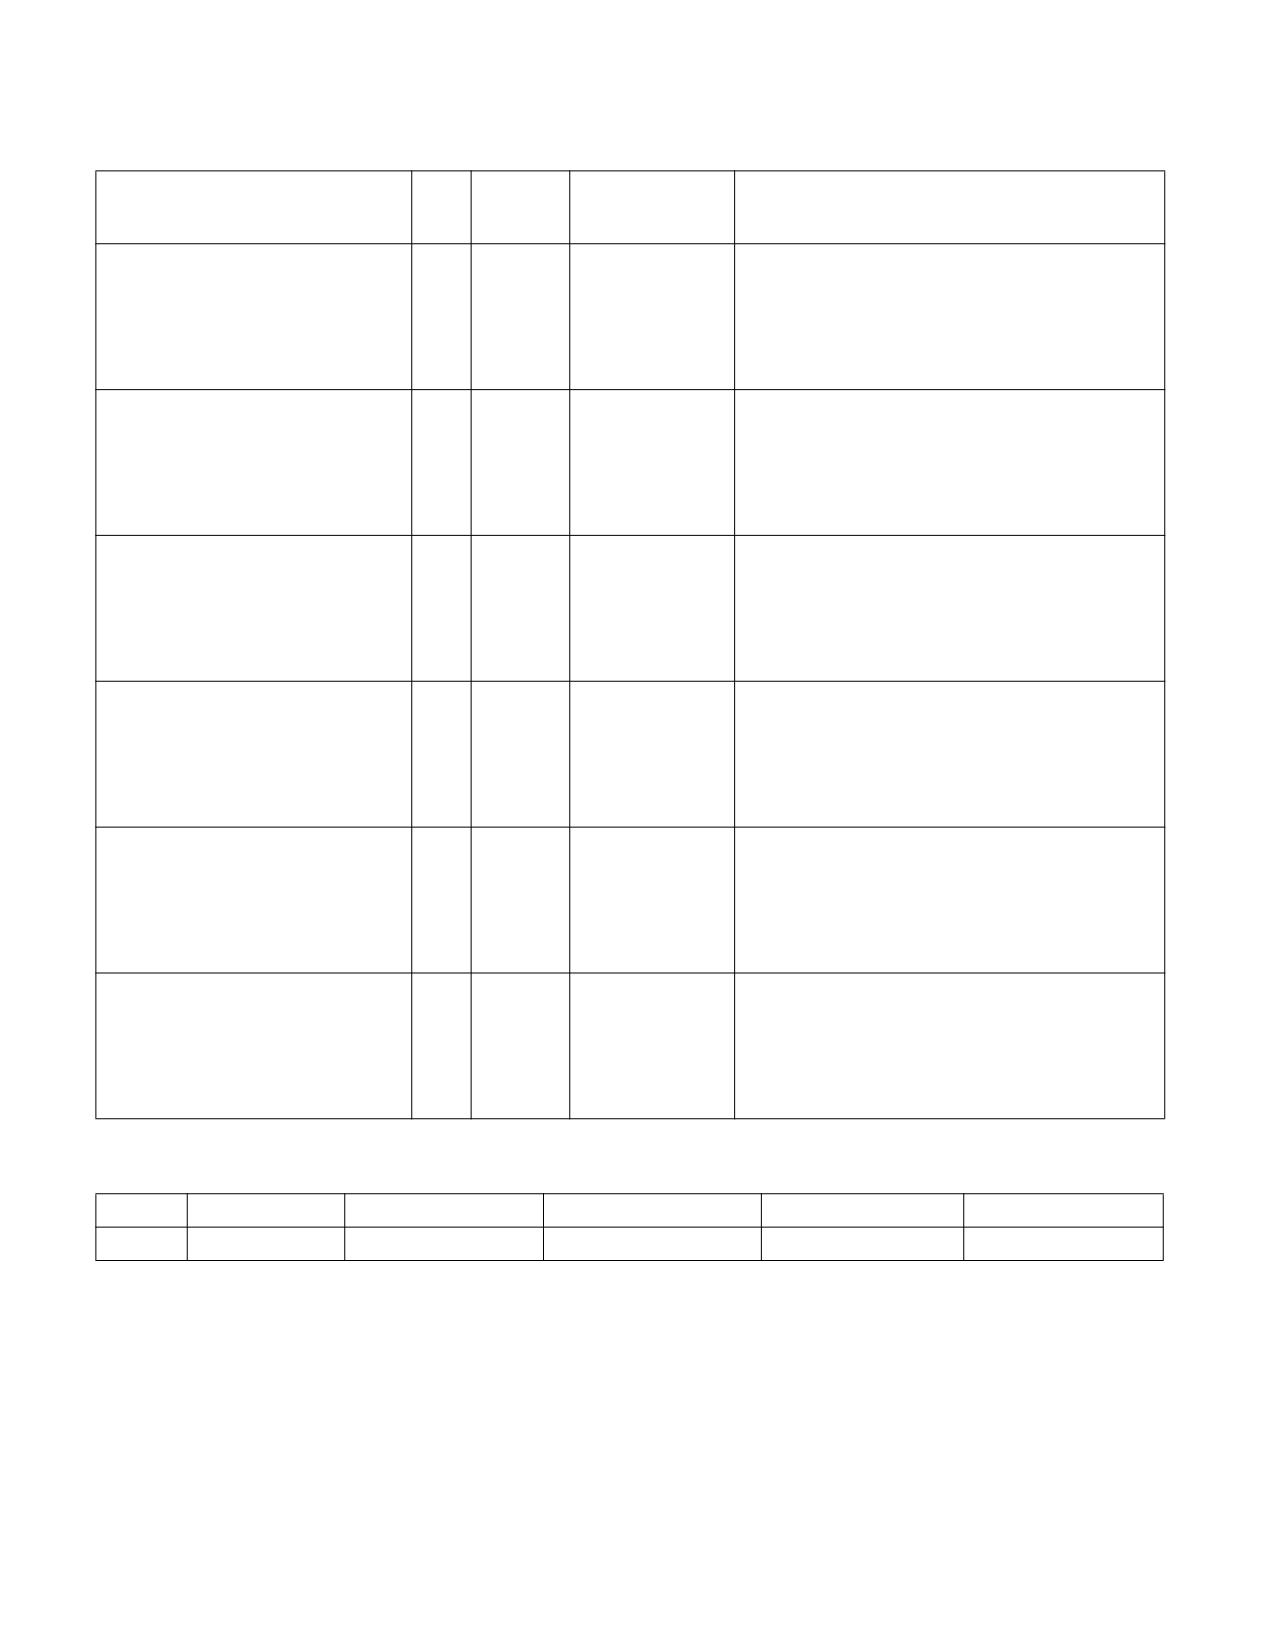
VPTERNLOGD/VPTERNLOGQ-Bitwise Ternary Logic
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 25 /r ib
A
V/V
(AVX512VL AND
Bitwise ternary logic taking xmm1, xmm2, and
VPTERNLOGD xmm1 {k1}{z}, xmm2,
AVX512F) OR
xmm3/m128/m32bcst as source operands and
xmm3/m128/m32bcst, imm8
AVX10.1
writing the result to xmm1 under writemask k1
with dword granularity. The immediate value
determines the specific binary function being
implemented.
EVEX.256.66.0F3A.W0 25 /r ib
A
V/V
(AVX512VL AND
Bitwise ternary logic taking ymm1, ymm2, and
VPTERNLOGD ymm1 {k1}{z}, ymm2,
AVX512F) OR
ymm3/m256/m32bcst as source operands and
ymm3/m256/m32bcst, imm8
AVX10.1
writing the result to ymm1 under writemask k1
with dword granularity. The immediate value
determines the specific binary function being
implemented.
EVEX.512.66.0F3A.W0 25 /r ib
A
V/V
AVX512F
Bitwise ternary logic taking zmm1, zmm2, and
VPTERNLOGD zmm1 {k1}{z}, zmm2,
OR AVX10.1
zmm3/m512/m32bcst as source operands and
zmm3/m512/m32bcst, imm8
writing the result to zmm1 under writemask k1
with dword granularity. The immediate value
determines the specific binary function being
implemented.
EVEX.128.66.0F3A.W1 25 /r ib
A
V/V
(AVX512VL AND
Bitwise ternary logic taking xmm1, xmm2, and
VPTERNLOGQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
xmm3/m128/m64bcst as source operands and
xmm3/m128/m64bcst, imm8
AVX10.1
writing the result to xmm1 under writemask k1
with qword granularity. The immediate value
determines the specific binary function being
implemented.
EVEX.256.66.0F3A.W1 25 /r ib
A
V/V
(AVX512VL AND
Bitwise ternary logic taking ymm1, ymm2, and
VPTERNLOGQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
ymm3/m256/m64bcst as source operands and
ymm3/m256/m64bcst, imm8
AVX10.1
writing the result to ymm1 under writemask k1
with qword granularity. The immediate value
determines the specific binary function being
implemented.
EVEX.512.66.0F3A.W1 25 /r ib
A
V/V
AVX512F
Bitwise ternary logic taking zmm1, zmm2, and
VPTERNLOGQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
zmm3/m512/m64bcst as source operands and
zmm3/m512/m64bcst, imm8
writing the result to zmm1 under writemask k1
with qword granularity. The immediate value
determines the specific binary function being
implemented.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
VPTERNLOGD/VPTERNLOGQ-Bitwise Ternary Logic
Vol. 2C
5-651
Description
VPTERNLOGD/Q takes three bit vectors of 512-bit length (in the first, second, and third operand) as input data to
form a set of 512 indices, each index is comprised of one bit from each input vector. The imm8 byte specifies a
boolean logic table producing a binary value for each 3-bit index value. The final 512-bit boolean result is written
to the destination operand (the first operand) using the writemask k1 with the granularity of doubleword element
or quadword element into the destination.
The destination operand is a ZMM (EVEX.512)/YMM (EVEX.256)/XMM (EVEX.128) register. The first source
operand is a ZMM/YMM/XMM register. The second source operand can be a ZMM/YMM/XMM register, a
512/256/128-bit memory location or a 512/256/128-bit vector broadcasted from a 32/64-bit memory location The
destination operand is a ZMM register conditionally updated with writemask k1.
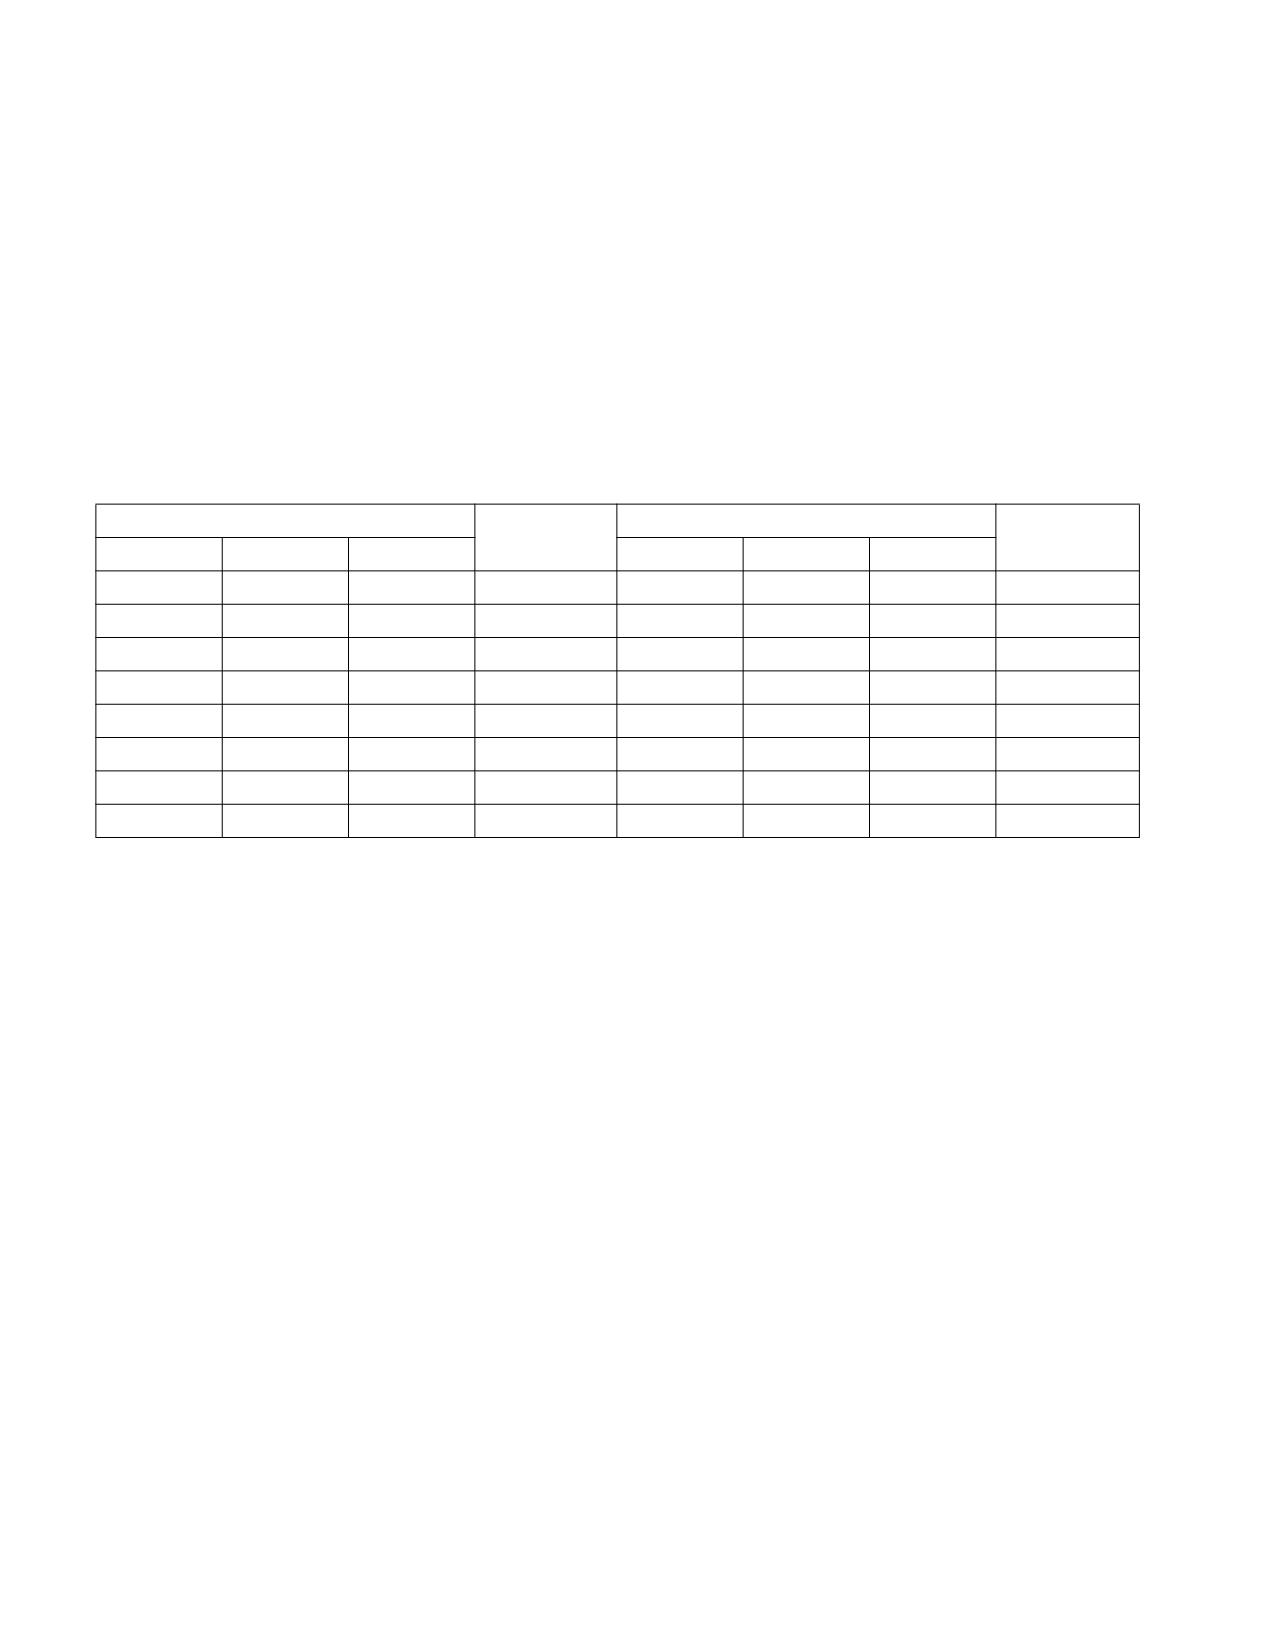
Table 5-20 shows two examples of Boolean functions specified by immediate values 0xE2 and 0xE4, with the look
up result listed in the fourth column following the three columns containing all possible values of the 3-bit index.
Table 5-20. Examples of VPTERNLOGD/Q Imm8 Boolean Function and Input Index Values
VPTERNLOGD reg1, reg2, src3, 0xE2
Bit Result with
VPTERNLOGD reg1, reg2, src3, 0xE4
Bit Result with
Imm8=0xE2
Imm8=0xE4
Bit(reg1)
Bit(reg2)
Bit(src3)
Bit(reg1)
Bit(reg2)
Bit(src3)
0
0
0
0
0
0
0
0
0
0
1
1
0
0
1
0
0
1
0
0
0
1
0
1
0
1
1
0
0
1
1
0
1
0
0
0
1
0
0
0
1
0
1
1
1
0
1
1
1
1
0
1
1
1
0
1
1
1
1
1
1
1
1
1
Specifying different values in imm8 will allow any arbitrary three-input Boolean functions to be implemented in
software using VPTERNLOGD/Q. Table 5-1 and Table 5-2 provide a mapping of all 256 possible imm8 values to
various Boolean expressions.
Operation
VPTERNLOGD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
FOR k := 0 TO 31
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[j][k] := imm[(DEST[i+k] << 2) + (SRC1[ i+k ] << 1) + SRC2[ k ]]
ELSE DEST[j][k] := imm[(DEST[i+k] << 2) + (SRC1[ i+k ] << 1) + SRC2[ i+k ]]
FI;
; table lookup of immediate bellow;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31+i:i] remains unchanged*
ELSE
; zeroing-masking
DEST[31+i:i] := 0
FI;
FI;
ENDFOR;
VPTERNLOGD/VPTERNLOGQ-Bitwise Ternary Logic
Vol. 2C
5-652
DEST[MAXVL-1:VL] := 0
VPTERNLOGQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
FOR k := 0 TO 63
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[j][k] := imm[(DEST[i+k] << 2) + (SRC1[ i+k ] << 1) + SRC2[ k ]]
ELSE DEST[j][k] := imm[(DEST[i+k] << 2) + (SRC1[ i+k ] << 1) + SRC2[ i+k ]]
FI;
; table lookup of immediate bellow;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63+i:i] remains unchanged*
ELSE
; zeroing-masking
DEST[63+i:i] := 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalents
VPTERNLOGD __m512i _mm512_ternarylogic_epi32(__m512i a, __m512i b, int imm);
VPTERNLOGD __m512i _mm512_mask_ternarylogic_epi32(__m512i s, __mmask16 m, __m512i a, __m512i b, int imm);
VPTERNLOGD __m512i _mm512_maskz_ternarylogic_epi32(__mmask m, __m512i a, __m512i b, int imm);
VPTERNLOGD __m256i _mm256_ternarylogic_epi32(__m256i a, __m256i b, int imm);
VPTERNLOGD __m256i _mm256_mask_ternarylogic_epi32(__m256i s, __mmask8 m, __m256i a, __m256i b, int imm);
VPTERNLOGD __m256i _mm256_maskz_ternarylogic_epi32( __mmask8 m, __m256i a, __m256i b, int imm);
VPTERNLOGD __m128i _mm_ternarylogic_epi32(__m128i a, __m128i b, int imm);
VPTERNLOGD __m128i _mm_mask_ternarylogic_epi32(__m128i s, __mmask8 m, __m128i a, __m128i b, int imm);
VPTERNLOGD __m128i _mm_maskz_ternarylogic_epi32( __mmask8 m, __m128i a, __m128i b, int imm);
VPTERNLOGQ __m512i _mm512_ternarylogic_epi64(__m512i a, __m512i b, int imm);
VPTERNLOGQ __m512i _mm512_mask_ternarylogic_epi64(__m512i s, __mmask8 m, __m512i a, __m512i b, int imm);
VPTERNLOGQ __m512i _mm512_maskz_ternarylogic_epi64( __mmask8 m, __m512i a, __m512i b, int imm);
VPTERNLOGQ __m256i _mm256_ternarylogic_epi64(__m256i a, __m256i b, int imm);
VPTERNLOGQ __m256i _mm256_mask_ternarylogic_epi64(__m256i s, __mmask8 m, __m256i a, __m256i b, int imm);
VPTERNLOGQ __m256i _mm256_maskz_ternarylogic_epi64( __mmask8 m, __m256i a, __m256i b, int imm);
VPTERNLOGQ __m128i _mm_ternarylogic_epi64(__m128i a, __m128i b, int imm);
VPTERNLOGQ __m128i _mm_mask_ternarylogic_epi64(__m128i s, __mmask8 m, __m128i a, __m128i b, int imm);
VPTERNLOGQ __m128i _mm_maskz_ternarylogic_epi64( __mmask8 m, __m128i a, __m128i b, int imm);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
VPTERNLOGD/VPTERNLOGQ-Bitwise Ternary Logic
Vol. 2C
5-653
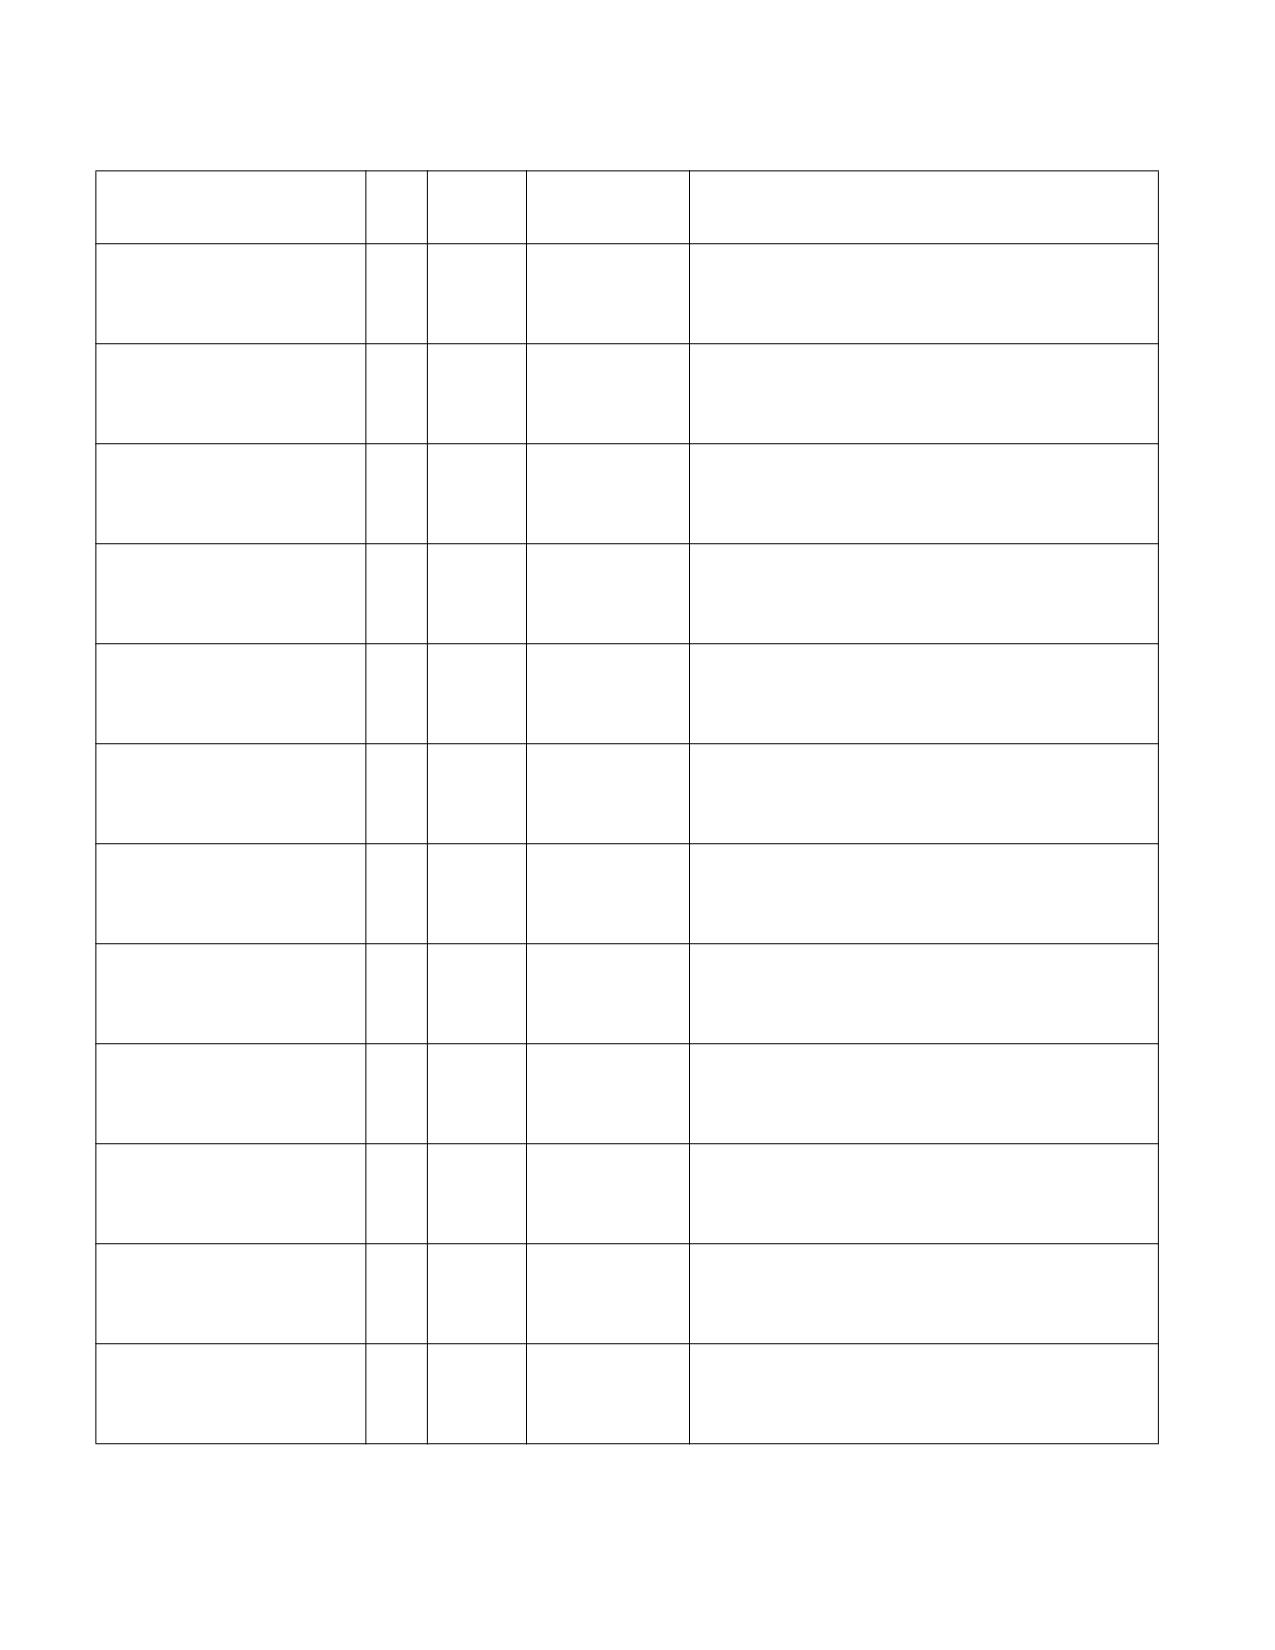
VPTESTMB/VPTESTMW/VPTESTMD/VPTESTMQ-Logical AND and Set Mask
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 26 /r
A
V/V
(AVX512VL AND
Bitwise AND of packed byte integers in xmm2 and
VPTESTMB k2 {k1}, xmm2,
AVX512BW) OR
xmm3/m128 and set mask k2 to reflect the zero/non-
xmm3/m128
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.256.66.0F38.W0 26 /r
A
V/V
(AVX512VL AND
Bitwise AND of packed byte integers in ymm2 and
VPTESTMB k2 {k1}, ymm2,
AVX512BW) OR
ymm3/m256 and set mask k2 to reflect the zero/non-
ymm3/m256
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.512.66.0F38.W0 26 /r
A
V/V
AVX512BW
Bitwise AND of packed byte integers in zmm2 and
VPTESTMB k2 {k1}, zmm2,
OR AVX10.1
zmm3/m512 and set mask k2 to reflect the zero/non-
zmm3/m512
zero status of each element of the result, under
writemask k1.
EVEX.128.66.0F38.W1 26 /r
A
V/V
(AVX512VL AND
Bitwise AND of packed word integers in xmm2 and
VPTESTMW k2 {k1}, xmm2,
AVX512BW) OR
xmm3/m128 and set mask k2 to reflect the zero/non-
xmm3/m128
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.256.66.0F38.W1 26 /r
A
V/V
(AVX512VL AND
Bitwise AND of packed word integers in ymm2 and
VPTESTMW k2 {k1}, ymm2,
AVX512BW) OR
ymm3/m256 and set mask k2 to reflect the zero/non-
ymm3/m256
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.512.66.0F38.W1 26 /r
A
V/V
AVX512BW
Bitwise AND of packed word integers in zmm2 and
VPTESTMW k2 {k1}, zmm2,
OR AVX10.1
zmm3/m512 and set mask k2 to reflect the zero/non-
zmm3/m512
zero status of each element of the result, under
writemask k1.
EVEX.128.66.0F38.W0 27 /r
B
V/V
(AVX512VL AND
Bitwise AND of packed doubleword integers in xmm2
VPTESTMD k2 {k1}, xmm2,
AVX512F) OR
and xmm3/m128/m32bcst and set mask k2 to reflect
xmm3/m128/m32bcst
AVX10.1
the zero/non-zero status of each element of the result,
under writemask k1.
EVEX.256.66.0F38.W0 27 /r
B
V/V
(AVX512VL AND
Bitwise AND of packed doubleword integers in ymm2
VPTESTMD k2 {k1}, ymm2,
AVX512F) OR
and ymm3/m256/m32bcst and set mask k2 to reflect
ymm3/m256/m32bcst
AVX10.1
the zero/non-zero status of each element of the result,
under writemask k1.
EVEX.512.66.0F38.W0 27 /r
B
V/V
AVX512F
Bitwise AND of packed doubleword integers in zmm2
VPTESTMD k2 {k1}, zmm2,
OR AVX10.1
and zmm3/m512/m32bcst and set mask k2 to reflect
zmm3/m512/m32bcst
the zero/non-zero status of each element of the result,
under writemask k1.
EVEX.128.66.0F38.W1 27 /r
B
V/V
(AVX512VL AND
Bitwise AND of packed quadword integers in xmm2 and
VPTESTMQ k2 {k1}, xmm2,
AVX512F) OR
xmm3/m128/m64bcst and set mask k2 to reflect the
xmm3/m128/m64bcst
AVX10.1
zero/non-zero status of each element of the result,
under writemask k1.
EVEX.256.66.0F38.W1 27 /r
B
V/V
(AVX512VL AND
Bitwise AND of packed quadword integers in ymm2 and
VPTESTMQ k2 {k1}, ymm2,
AVX512F) OR
ymm3/m256/m64bcst and set mask k2 to reflect the
ymm3/m256/m64bcst
AVX10.1
zero/non-zero status of each element of the result,
under writemask k1.
EVEX.512.66.0F38.W1 27 /r
B
V/V
AVX512F
Bitwise AND of packed quadword integers in zmm2 and
VPTESTMQ k2 {k1}, zmm2,
OR AVX10.1
zmm3/m512/m64bcst and set mask k2 to reflect the
zmm3/m512/m64bcst
zero/non-zero status of each element of the result,
under writemask k1.
VPTESTMB/VPTESTMW/VPTESTMD/VPTESTMQ-Logical AND and Set Mask
Vol. 2C
5-654

Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a bitwise logical AND operation on the first source operand (the second operand) and second source
operand (the third operand) and stores the result in the destination operand (the first operand) under the write-
mask. Each bit of the result is set to 1 if the bitwise AND of the corresponding elements of the first and second src
operands is non-zero; otherwise it is set to 0.
VPTESTMD/VPTESTMQ: The first source operand is a ZMM/YMM/XMM register. The second source operand can be a
ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512/256/128-bit vector broadcasted from a
32/64-bit memory location. The destination operand is a mask register updated under the writemask.
VPTESTMB/VPTESTMW: The first source operand is a ZMM/YMM/XMM register. The second source operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location. The destination operand is a mask register
updated under the writemask.
Operation
VPTESTMB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[j] := (SRC1[i+7:i] BITWISE AND SRC2[i+7:i] != 0)? 1 : 0;
ELSE
DEST[j] = 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPTESTMW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[j] := (SRC1[i+15:i] BITWISE AND SRC2[i+15:i] != 0)? 1 : 0;
ELSE
DEST[j] = 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPTESTMB/VPTESTMW/VPTESTMD/VPTESTMQ-Logical AND and Set Mask
Vol. 2C
5-655
VPTESTMD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[j] := (SRC1[i+31:i] BITWISE AND SRC2[31:0] != 0)? 1 : 0;
ELSE DEST[j] := (SRC1[i+31:i] BITWISE AND SRC2[i+31:i] != 0)? 1 : 0;
FI;
ELSE
DEST[j] := 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPTESTMQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[j] := (SRC1[i+63:i] BITWISE AND SRC2[63:0] != 0)? 1 : 0;
ELSE DEST[j] := (SRC1[i+63:i] BITWISE AND SRC2[i+63:i] != 0)? 1 : 0;
FI;
ELSE
DEST[j] := 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
Intel C/C++ Compiler Intrinsic Equivalents
VPTESTMB __mmask64 _mm512_test_epi8_mask( __m512i a, __m512i b);
VPTESTMB __mmask64 _mm512_mask_test_epi8_mask(__mmask64, __m512i a, __m512i b);
VPTESTMW __mmask32 _mm512_test_epi16_mask( __m512i a, __m512i b);
VPTESTMW __mmask32 _mm512_mask_test_epi16_mask(__mmask32, __m512i a, __m512i b);
VPTESTMD __mmask16 _mm512_test_epi32_mask( __m512i a, __m512i b);
VPTESTMD __mmask16 _mm512_mask_test_epi32_mask(__mmask16, __m512i a, __m512i b);
VPTESTMQ __mmask8 _mm512_test_epi64_mask(__m512i a, __m512i b);
VPTESTMQ __mmask8 _mm512_mask_test_epi64_mask(__mmask8, __m512i a, __m512i b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
VPTESTMD/Q: See Table 2-51, “Type E4 Class Exception Conditions.”
VPTESTMB/W: See Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPTESTMB/VPTESTMW/VPTESTMD/VPTESTMQ-Logical AND and Set Mask
Vol. 2C
5-656

VPTESTNMB/W/D/Q-Logical NAND and Set
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.F3.0F38.W0 26 /r
A
V/V
(AVX512VL AND
Bitwise NAND of packed byte integers in xmm2 and
VPTESTNMB k2 {k1}, xmm2,
AVX512BW) OR
xmm3/m128 and set mask k2 to reflect the zero/non-
xmm3/m128
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.256.F3.0F38.W0 26 /r
A
V/V
(AVX512VL AND
Bitwise NAND of packed byte integers in ymm2 and
VPTESTNMB k2 {k1}, ymm2,
AVX512BW) OR
ymm3/m256 and set mask k2 to reflect the zero/non-
ymm3/m256
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.512.F3.0F38.W0 26 /r
A
V/V
(AVX512F AND
Bitwise NAND of packed byte integers in zmm2 and
VPTESTNMB k2 {k1}, zmm2,
AVX512BW) OR
zmm3/m512 and set mask k2 to reflect the zero/non-
zmm3/m512
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.128.F3.0F38.W1 26 /r
A
V/V
(AVX512VL AND
Bitwise NAND of packed word integers in xmm2 and
VPTESTNMW k2 {k1}, xmm2,
AVX512BW) OR
xmm3/m128 and set mask k2 to reflect the zero/non-
xmm3/m128
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.256.F3.0F38.W1 26 /r
A
V/V
(AVX512VL AND
Bitwise NAND of packed word integers in ymm2 and
VPTESTNMW k2 {k1}, ymm2,
AVX512BW) OR
ymm3/m256 and set mask k2 to reflect the zero/non-
ymm3/m256
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.512.F3.0F38.W1 26 /r
A
V/V
(AVX512F AND
Bitwise NAND of packed word integers in zmm2 and
VPTESTNMW k2 {k1}, zmm2,
AVX512BW) OR
zmm3/m512 and set mask k2 to reflect the zero/non-
zmm3/m512
AVX10.1
zero status of each element of the result, under
writemask k1.
EVEX.128.F3.0F38.W0 27 /r
B
V/V
(AVX512VL AND
Bitwise NAND of packed doubleword integers in
VPTESTNMD k2 {k1}, xmm2,
AVX512F) OR
xmm2 and xmm3/m128/m32bcst and set mask k2 to
xmm3/m128/m32bcst
AVX10.1
reflect the zero/non-zero status of each element of
the result, under writemask k1.
EVEX.256.F3.0F38.W0 27 /r
B
V/V
(AVX512VL AND
Bitwise NAND of packed doubleword integers in
VPTESTNMD k2 {k1}, ymm2,
AVX512F) OR
ymm2 and ymm3/m256/m32bcst and set mask k2 to
ymm3/m256/m32bcst
AVX10.1
reflect the zero/non-zero status of each element of
the result, under writemask k1.
EVEX.512.F3.0F38.W0 27 /r
B
V/V
AVX512F
Bitwise NAND of packed doubleword integers in
VPTESTNMD k2 {k1}, zmm2,
OR AVX10.1
zmm2 and zmm3/m512/m32bcst and set mask k2 to
zmm3/m512/m32bcst
reflect the zero/non-zero status of each element of
the result, under writemask k1.
EVEX.128.F3.0F38.W1 27 /r
B
V/V
(AVX512VL AND
Bitwise NAND of packed quadword integers in xmm2
VPTESTNMQ k2 {k1}, xmm2,
AVX512F) OR
and xmm3/m128/m64bcst and set mask k2 to reflect
xmm3/m128/m64bcst
AVX10.1
the zero/non-zero status of each element of the
result, under writemask k1.
EVEX.256.F3.0F38.W1 27 /r
B
V/V
(AVX512VL AND
Bitwise NAND of packed quadword integers in ymm2
VPTESTNMQ k2 {k1}, ymm2,
AVX512F) OR
and ymm3/m256/m64bcst and set mask k2 to reflect
ymm3/m256/m64bcst
AVX10.1
the zero/non-zero status of each element of the
result, under writemask k1.
EVEX.512.F3.0F38.W1 27 /r
B
V/V
AVX512F
Bitwise NAND of packed quadword integers in zmm2
VPTESTNMQ k2 {k1}, zmm2,
OR AVX10.1
and zmm3/m512/m64bcst and set mask k2 to reflect
zmm3/m512/m64bcst
the zero/non-zero status of each element of the
result, under writemask k1.
VPTESTNMB/W/D/Q-Logical NAND and Set
Vol. 2C
5-657

Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a bitwise logical NAND operation on the byte/word/doubleword/quadword element of the first source
operand (the second operand) with the corresponding element of the second source operand (the third operand)
and stores the logical comparison result into each bit of the destination operand (the first operand) according to the
writemask k1. Each bit of the result is set to 1 if the bitwise AND of the corresponding elements of the first and
second src operands is zero; otherwise it is set to 0.
EVEX encoded VPTESTNMD/Q: The first source operand is a ZMM/YMM/XMM registers. The second source operand
can be a ZMM/YMM/XMM register, a 512/256/128-bit memory location, or a 512/256/128-bit vector broadcasted
from a 32/64-bit memory location. The destination is updated according to the writemask.
EVEX encoded VPTESTNMB/W: The first source operand is a ZMM/YMM/XMM registers. The second source operand
can be a ZMM/YMM/XMM register, a 512/256/128-bit memory location. The destination is updated according to the
writemask.
Operation
VPTESTNMB
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j*8
IF MaskBit(j) OR *no writemask*
THEN
DEST[j] := (SRC1[i+7:i] BITWISE AND SRC2[i+7:i] == 0)? 1 : 0
ELSE DEST[j] := 0; zeroing masking only
FI
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPTESTNMW
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j*16
IF MaskBit(j) OR *no writemask*
THEN
DEST[j] := (SRC1[i+15:i] BITWISE AND SRC2[i+15:i] == 0)? 1 : 0
ELSE DEST[j] := 0; zeroing masking only
FI
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPTESTNMB/W/D/Q-Logical NAND and Set
Vol. 2C
5-658
VPTESTNMD
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j*32
IF MaskBit(j) OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[i+31:i] := (SRC1[i+31:i] BITWISE AND SRC2[31:0] == 0)? 1 : 0
ELSE DEST[j] := (SRC1[i+31:i] BITWISE AND SRC2[i+31:i] == 0)? 1 : 0
FI
ELSE DEST[j] := 0; zeroing masking only
FI
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPTESTNMQ
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j*64
IF MaskBit(j) OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[j] := (SRC1[i+63:i] BITWISE AND SRC2[63:0] == 0)? 1 : 0;
ELSE DEST[j] := (SRC1[i+63:i] BITWISE AND SRC2[i+63:i] == 0)? 1 : 0;
FI;
ELSE DEST[j] := 0; zeroing masking only
FI
ENDFOR
DEST[MAX_KL-1:KL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPTESTNMB __mmask64 _mm512_testn_epi8_mask( __m512i a, __m512i b);
VPTESTNMB __mmask64 _mm512_mask_testn_epi8_mask(__mmask64, __m512i a, __m512i b);
VPTESTNMB __mmask32 _mm256_testn_epi8_mask(__m256i a, __m256i b);
VPTESTNMB __mmask32 _mm256_mask_testn_epi8_mask(__mmask32, __m256i a, __m256i b);
VPTESTNMB __mmask16 _mm_testn_epi8_mask(__m128i a, __m128i b);
VPTESTNMB __mmask16 _mm_mask_testn_epi8_mask(__mmask16, __m128i a, __m128i b);
VPTESTNMW __mmask32 _mm512_testn_epi16_mask( __m512i a, __m512i b);
VPTESTNMW __mmask32 _mm512_mask_testn_epi16_mask(__mmask32, __m512i a, __m512i b);
VPTESTNMW __mmask16 _mm256_testn_epi16_mask(__m256i a, __m256i b);
VPTESTNMW __mmask16 _mm256_mask_testn_epi16_mask(__mmask16, __m256i a, __m256i b);
VPTESTNMW __mmask8 _mm_testn_epi16_mask(__m128i a, __m128i b);
VPTESTNMW __mmask8 _mm_mask_testn_epi16_mask(__mmask8, __m128i a, __m128i b);
VPTESTNMD __mmask16 _mm512_testn_epi32_mask( __m512i a, __m512i b);
VPTESTNMD __mmask16 _mm512_mask_testn_epi32_mask(__mmask16, __m512i a, __m512i b);
VPTESTNMD __mmask8 _mm256_testn_epi32_mask(__m256i a, __m256i b);
VPTESTNMD __mmask8 _mm256_mask_testn_epi32_mask(__mmask8, __m256i a, __m256i b);
VPTESTNMD __mmask8 _mm_testn_epi32_mask(__m128i a, __m128i b);
VPTESTNMD __mmask8 _mm_mask_testn_epi32_mask(__mmask8, __m128i a, __m128i b);
VPTESTNMQ __mmask8 _mm512_testn_epi64_mask(__m512i a, __m512i b);
VPTESTNMQ __mmask8 _mm512_mask_testn_epi64_mask(__mmask8, __m512i a, __m512i b);
VPTESTNMQ __mmask8 _mm256_testn_epi64_mask(__m256i a, __m256i b);
VPTESTNMQ __mmask8 _mm256_mask_testn_epi64_mask(__mmask8, __m256i a, __m256i b);
VPTESTNMQ __mmask8 _mm_testn_epi64_mask(__m128i a, __m128i b);
VPTESTNMB/W/D/Q-Logical NAND and Set
Vol. 2C
5-659
VPTESTNMQ __mmask8 _mm_mask_testn_epi64_mask(__mmask8, __m128i a, __m128i b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
VPTESTNMD/VPTESTNMQ: See Table 2-51, “Type E4 Class Exception Conditions.”
VPTESTNMB/VPTESTNMW: See Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPTESTNMB/W/D/Q-Logical NAND and Set
Vol. 2C
5-660
VRANGEPD-Range Restriction Calculation for Packed Pairs of Float64 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W1 50 /r ib
A
V/V
(AVX512VL
Calculate two RANGE operation output value from 2
VRANGEPD xmm1 {k1}{z}, xmm2,
AND AVX512DQ)
pairs of double precision floating-point values in
xmm3/m128/m64bcst, imm8
OR AVX10.1
xmm2 and xmm3/m128/m32bcst, store the results
to xmm1 under the writemask k1. Imm8 specifies
the comparison and sign of the range operation.
EVEX.256.66.0F3A.W1 50 /r ib
A
V/V
(AVX512VL
Calculate four RANGE operation output value from
VRANGEPD ymm1 {k1}{z}, ymm2,
AND AVX512DQ)
4pairs of double precision floating-point values in
ymm3/m256/m64bcst, imm8
OR AVX10.1
ymm2 and ymm3/m256/m32bcst, store the results
to ymm1 under the writemask k1. Imm8 specifies
the comparison and sign of the range operation.
EVEX.512.66.0F3A.W1 50 /r ib
A
V/V
AVX512DQ
Calculate eight RANGE operation output value from
VRANGEPD zmm1 {k1}{z}, zmm2,
OR AVX10.1
8 pairs of double precision floating-point values in
zmm3/m512/m64bcst{sae}, imm8
zmm2 and zmm3/m512/m32bcst, store the results
to zmm1 under the writemask k1. Imm8 specifies
the comparison and sign of the range operation.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
This instruction calculates 2/4/8 range operation outputs from two sets of packed input double precision floating-
point values in the first source operand (the second operand) and the second source operand (the third operand).
The range outputs are written to the destination operand (the first operand) under the writemask k1.
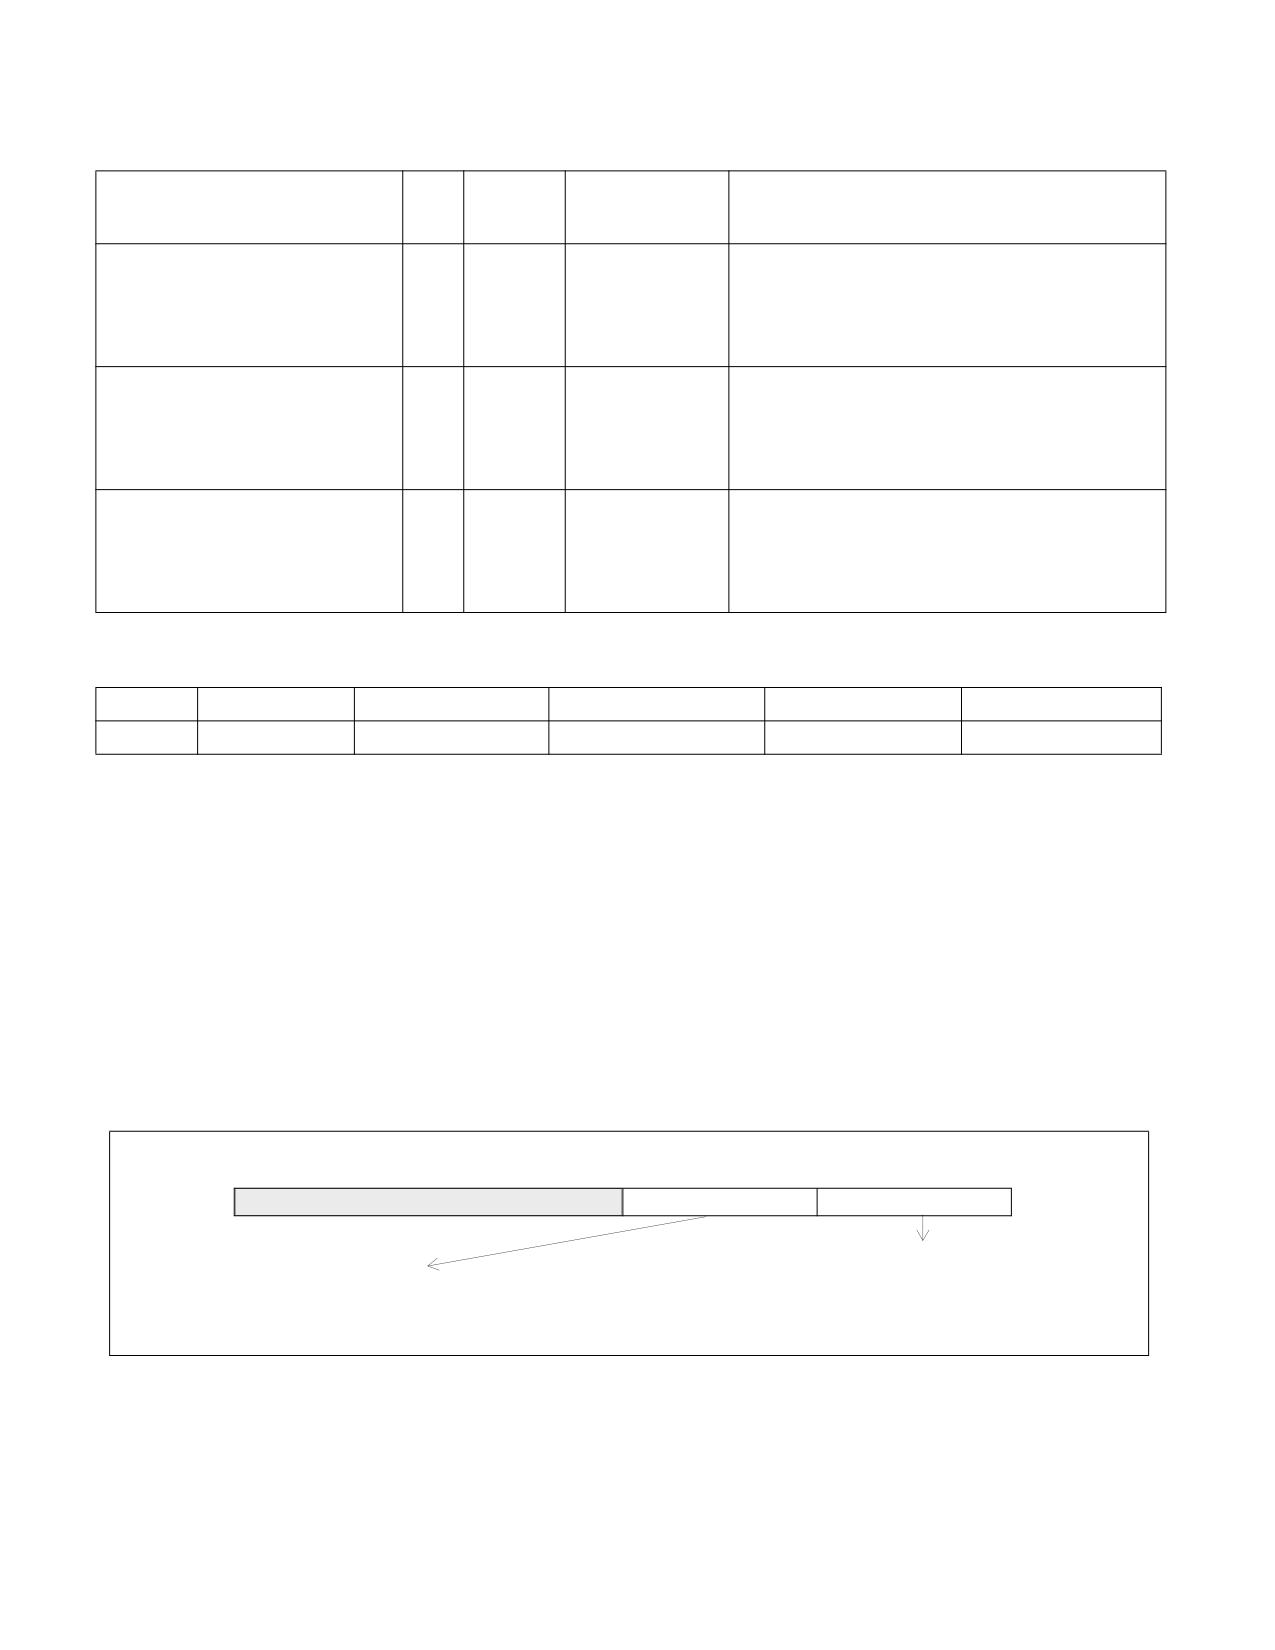
Bits7:4 of imm8 byte must be zero. The range operation output is performed in two parts, each configured by a
two-bit control field within imm8[3:0]:
• Imm8[1:0] specifies the initial comparison operation to be one of max, min, max absolute value or min
absolute value of the input value pair. Each comparison of two input values produces an intermediate result
that combines with the sign selection control (imm8[3:2]) to determine the final range operation output.
• Imm8[3:2] specifies the sign of the range operation output to be one of the following: from the first input
value, from the comparison result, set or clear.
The encodings of imm8[1:0] and imm8[3:2] are shown in Figure 5-27.
7
6
5
4
3
2
1
0
imm8
Must Be Zero
Sign Control (SC)
Compare Operation Select
Imm8[1:0] = 00b : Select Min value
Imm8[3:2] = 00b : Select sign(SRC1)
Imm8[1:0] = 01b : Select Max value
Imm8[3:2] = 01b : Select sign(Compare_Result)
Imm8[1:0] = 10b : Select Min-Abs value
Imm8[3:2] = 10b : Set sign to 0
Imm8[1:0] = 11b : Select Max-Abs value
Imm8[3:2] = 11b : Set sign to 1
Figure 5-27. Imm8 Controls for VRANGEPD/SD/PS/SS
VRANGEPD-Range Restriction Calculation for Packed Pairs of Float64 Values
Vol. 2C
5-661
When one or more of the input value is a NAN, the comparison operation may signal invalid exception (IE). Details
with one of more input value is NAN is listed in Table 5-21. If the comparison raises an IE, the sign select control
(imm8[3:2]) has no effect to the range operation output; this is indicated also in Table 5-21.
When both input values are zeros of opposite signs, the comparison operation of MIN/MAX in the range compare
operation is slightly different from the conceptually similar floating-point MIN/MAX operation that are found in the
instructions VMAXPD/VMINPD. The details of MIN/MAX/MIN_ABS/MAX_ABS operation for VRANGEPD/PS/SD/SS
for magnitude-0, opposite-signed input cases are listed in Table 5-22.
Additionally, non-zero, equal-magnitude with opposite-sign input values perform MIN_ABS or MAX_ABS compar-
ison operation with result listed in Table 5-23.
Table 5-21. Signaling of Comparison Operation of One or More NaN Input Values and Effect of Imm8[3:2]
Src1
Src2
Result
IE Signaling Due to Comparison
Imm8[3:2] Effect to Range Output
sNaN1
sNaN2
Quiet(sNaN1)
Yes
Ignored
sNaN1
qNaN2
Quiet(sNaN1)
Yes
Ignored
sNaN1
Norm2
Quiet(sNaN1)
Yes
Ignored
qNaN1
sNaN2
Quiet(sNaN2)
Yes
Ignored
qNaN1
qNaN2
qNaN1
No
Applicable
qNaN1
Norm2
Norm2
No
Applicable
Norm1
sNaN2
Quiet(sNaN2)
Yes
Ignored
Norm1
qNaN2
Norm1
No
Applicable
Table 5-22. Comparison Result for Opposite-Signed Zero Cases for MIN, MIN_ABS, and MAX, MAX_ABS
MIN and MIN_ABS
MAX and MAX_ABS
Src1
Src2
Result
Src1
Src2
Result
+0
-0
-0
+0
-0
+0
-0
+0
-0
-0
+0
+0
Table 5-23. Comparison Result of Equal-Magnitude Input Cases for MIN_ABS and MAX_ABS, (|a| = |b|, a>0, b<0)
MIN_ABS (|a| = |b|, a>0, b<0)
MAX_ABS (|a| = |b|, a>0, b<0)
Src1
Src2
Result
Src1
Src2
Result
a
b
b
a
b
a
b
a
b
b
a
a
Operation
RangeDP(SRC1[63:0], SRC2[63:0], CmpOpCtl[1:0], SignSelCtl[1:0])
{
// Check if SNAN and report IE, see also Table 5-21
IF (SRC1 = SNAN) THEN RETURN (QNAN(SRC1), set IE);
IF (SRC2 = SNAN) THEN RETURN (QNAN(SRC2), set IE);
Src1.exp := SRC1[62:52];
Src1.fraction := SRC1[51:0];
IF ((Src1.exp = 0 ) and (Src1.fraction != 0)) THEN// Src1 is a denormal number
IF DAZ THEN Src1.fraction := 0;
ELSE IF (SRC2 <> QNAN) Set DE; FI;
FI;
VRANGEPD-Range Restriction Calculation for Packed Pairs of Float64 Values
Vol. 2C
5-662
Src2.exp := SRC2[62:52];
Src2.fraction := SRC2[51:0];
IF ((Src2.exp = 0) and (Src2.fraction !=0 )) THEN// Src2 is a denormal number
IF DAZ THEN Src2.fraction := 0;
ELSE IF (SRC1 <> QNAN) Set DE; FI;
FI;
IF (SRC2 = QNAN) THEN{TMP[63:0] := SRC1[63:0]}
ELSE IF(SRC1 = QNAN) THEN{TMP[63:0] := SRC2[63:0]}
ELSE IF (Both SRC1, SRC2 are magnitude-0 and opposite-signed) TMP[63:0] := from Table 5-22
ELSE IF (Both SRC1, SRC2 are magnitude-equal and opposite-signed and CmpOpCtl[1:0] > 01) TMP[63:0] := from Table 5-23
ELSE
Case(CmpOpCtl[1:0])
00: TMP[63:0] := (SRC1[63:0] ≤ SRC2[63:0]) ? SRC1[63:0] : SRC2[63:0];
01: TMP[63:0] := (SRC1[63:0] ≤ SRC2[63:0]) ? SRC2[63:0] : SRC1[63:0];
10: TMP[63:0] := (ABS(SRC1[63:0]) ≤ ABS(SRC2[63:0])) ? SRC1[63:0] : SRC2[63:0];
11: TMP[63:0] := (ABS(SRC1[63:0]) ≤ ABS(SRC2[63:0])) ? SRC2[63:0] : SRC1[63:0];
ESAC;
FI;
Case(SignSelCtl[1:0])
00: dest := (SRC1[63] << 63) OR (TMP[62:0]);// Preserve Src1 sign bit
01: dest := TMP[63:0];// Preserve sign of compare result
10: dest := (0 << 63) OR (TMP[62:0]);// Zero out sign bit
11: dest := (1 << 63) OR (TMP[62:0]);// Set the sign bit
ESAC;
RETURN dest[63:0];
}
CmpOpCtl[1:0]= imm8[1:0];
SignSelCtl[1:0]=imm8[3:2];
VRANGEPD (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b == 1) AND (SRC2 *is memory*)
THEN DEST[i+63:i] := RangeDP (SRC1[i+63:i], SRC2[63:0], CmpOpCtl[1:0], SignSelCtl[1:0]);
ELSE DEST[i+63:i] := RangeDP (SRC1[i+63:i], SRC2[i+63:i], CmpOpCtl[1:0], SignSelCtl[1:0]);
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] = 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
The following example describes a common usage of this instruction for checking that the input operand is
bounded between ±1023.
VRANGEPD-Range Restriction Calculation for Packed Pairs of Float64 Values
Vol. 2C
5-663
VRANGEPD zmm_dst, zmm_src, zmm_1023, 02h;
Where:
zmm_dst is the destination operand.
zmm_src is the input operand to compare against ±1023 (this is SRC1).
zmm_1023 is the reference operand, contains the value of 1023 (and this is SRC2).
IMM=02(imm8[1:0]='10) selects the Min Absolute value operation with selection of SRC1.sign.
In case |zmm_src| < 1023 (i.e., SRC1 is smaller than 1023 in magnitude), then its value will be written into
zmm_dst. Otherwise, the value stored in zmm_dst will get the value of 1023 (received on zmm_1023, which is
SRC2).
However, the sign control (imm8[3:2]='00) instructs to select the sign of SRC1 received from zmm_src. So, even
in the case of |zmm_src| ≥ 1023, the selected sign of SRC1 is kept.
Thus, if zmm_src < -1023, the result of VRANGEPD will be the minimal value of -1023 while if zmm_src > +1023,
the result of VRANGE will be the maximal value of +1023.
Intel C/C++ Compiler Intrinsic Equivalent
VRANGEPD __m512d _mm512_range_pd ( __m512d a, __m512d b, int imm);
VRANGEPD __m512d _mm512_range_round_pd ( __m512d a, __m512d b, int imm, int sae);
VRANGEPD __m512d _mm512_mask_range_pd (__m512 ds, __mmask8 k, __m512d a, __m512d b, int imm);
VRANGEPD __m512d _mm512_mask_range_round_pd (__m512d s, __mmask8 k, __m512d a, __m512d b, int imm, int sae);
VRANGEPD __m512d _mm512_maskz_range_pd ( __mmask8 k, __m512d a, __m512d b, int imm);
VRANGEPD __m512d _mm512_maskz_range_round_pd ( __mmask8 k, __m512d a, __m512d b, int imm, int sae);
VRANGEPD __m256d _mm256_range_pd ( __m256d a, __m256d b, int imm);
VRANGEPD __m256d _mm256_mask_range_pd (__m256d s, __mmask8 k, __m256d a, __m256d b, int imm);
VRANGEPD __m256d _mm256_maskz_range_pd ( __mmask8 k, __m256d a, __m256d b, int imm);
VRANGEPD __m128d _mm_range_pd ( __m128 a, __m128d b, int imm);
VRANGEPD __m128d _mm_mask_range_pd (__m128 s, __mmask8 k, __m128d a, __m128d b, int imm);
VRANGEPD __m128d _mm_maskz_range_pd ( __mmask8 k, __m128d a, __m128d b, int imm);
SIMD Floating-Point Exceptions
Invalid, Denormal.
Other Exceptions
See Table 2-48, “Type E2 Class Exception Conditions.”
VRANGEPD-Range Restriction Calculation for Packed Pairs of Float64 Values
Vol. 2C
5-664
VRANGEPS-Range Restriction Calculation for Packed Pairs of Float32 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 50 /r ib
A
V/V
(AVX512VL
Calculate four RANGE operation output value from
VRANGEPS xmm1 {k1}{z}, xmm2,
AND AVX512DQ)
4 pairs of single-precision floating-point values in
xmm3/m128/m32bcst, imm8
OR AVX10.1
xmm2 and xmm3/m128/m32bcst, store the results
to xmm1 under the writemask k1. Imm8 specifies
the comparison and sign of the range operation.
EVEX.256.66.0F3A.W0 50 /r ib
A
V/V
(AVX512VL
Calculate eight RANGE operation output value from
VRANGEPS ymm1 {k1}{z}, ymm2,
AND AVX512DQ)
8 pairs of single-precision floating-point values in
ymm3/m256/m32bcst, imm8
OR AVX10.1
ymm2 and ymm3/m256/m32bcst, store the results
to ymm1 under the writemask k1. Imm8 specifies
the comparison and sign of the range operation.
EVEX.512.66.0F3A.W0 50 /r ib
A
V/V
AVX512DQ
Calculate 16 RANGE operation output value from
VRANGEPS zmm1 {k1}{z}, zmm2,
OR AVX10.1
16 pairs of single-precision floating-point values in
zmm3/m512/m32bcst{sae}, imm8
zmm2 and zmm3/m512/m32bcst, store the results
to zmm1 under the writemask k1. Imm8 specifies
the comparison and sign of the range operation.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
This instruction calculates 4/8/16 range operation outputs from two sets of packed input single precision floating-
point values in the first source operand (the second operand) and the second source operand (the third operand).
The range outputs are written to the destination operand (the first operand) under the writemask k1.
Bits7:4 of imm8 byte must be zero. The range operation output is performed in two parts, each configured by a
two-bit control field within imm8[3:0]:
• Imm8[1:0] specifies the initial comparison operation to be one of max, min, max absolute value or min
absolute value of the input value pair. Each comparison of two input values produces an intermediate result
that combines with the sign selection control (imm8[3:2]) to determine the final range operation output.
• Imm8[3:2] specifies the sign of the range operation output to be one of the following: from the first input
value, from the comparison result, set or clear.
The encodings of imm8[1:0] and imm8[3:2] are shown in Figure 5-27.
When one or more of the input value is a NAN, the comparison operation may signal invalid exception (IE). Details
with one of more input value is NAN is listed in Table 5-21. If the comparison raises an IE, the sign select control
(imm8[3:2]) has no effect to the range operation output; this is indicated also in Table 5-21.
When both input values are zeros of opposite signs, the comparison operation of MIN/MAX in the range compare
operation is slightly different from the conceptually similar floating-point MIN/MAX operation that are found in the
instructions VMAXPD/VMINPD. The details of MIN/MAX/MIN_ABS/MAX_ABS operation for VRANGEPD/PS/SD/SS
for magnitude-0, opposite-signed input cases are listed in Table 5-22.
Additionally, non-zero, equal-magnitude with opposite-sign input values perform MIN_ABS or MAX_ABS compar-
ison operation with result listed in Table 5-23.
VRANGEPS-Range Restriction Calculation for Packed Pairs of Float32 Values
Vol. 2C
5-665
Operation
RangeSP(SRC1[31:0], SRC2[31:0], CmpOpCtl[1:0], SignSelCtl[1:0])
{
// Check if SNAN and report IE, see also Table 5-21
IF (SRC1=SNAN) THEN RETURN (QNAN(SRC1), set IE);
IF (SRC2=SNAN) THEN RETURN (QNAN(SRC2), set IE);
Src1.exp := SRC1[30:23];
Src1.fraction := SRC1[22:0];
IF ((Src1.exp = 0 ) and (Src1.fraction != 0 )) THEN// Src1 is a denormal number
IF DAZ THEN Src1.fraction := 0;
ELSE IF (SRC2 <> QNAN) Set DE; FI;
FI;
Src2.exp := SRC2[30:23];
Src2.fraction := SRC2[22:0];
IF ((Src2.exp = 0 ) and (Src2.fraction != 0 )) THEN// Src2 is a denormal number
IF DAZ THEN Src2.fraction := 0;
ELSE IF (SRC1 <> QNAN) Set DE; FI;
FI;
IF (SRC2 = QNAN) THEN{TMP[31:0] := SRC1[31:0]}
ELSE IF(SRC1 = QNAN) THEN{TMP[31:0] := SRC2[31:0]}
ELSE IF (Both SRC1, SRC2 are magnitude-0 and opposite-signed) TMP[31:0] := from Table 5-22
ELSE IF (Both SRC1, SRC2 are magnitude-equal and opposite-signed and CmpOpCtl[1:0] > 01) TMP[31:0] := from Table 5-23
ELSE
Case(CmpOpCtl[1:0])
00: TMP[31:0] := (SRC1[31:0] ≤ SRC2[31:0]) ? SRC1[31:0] : SRC2[31:0];
01: TMP[31:0] := (SRC1[31:0] ≤ SRC2[31:0]) ? SRC2[31:0] : SRC1[31:0];
10: TMP[31:0] := (ABS(SRC1[31:0]) ≤ ABS(SRC2[31:0])) ? SRC1[31:0] : SRC2[31:0];
11: TMP[31:0] := (ABS(SRC1[31:0]) ≤ ABS(SRC2[31:0])) ? SRC2[31:0] : SRC1[31:0];
ESAC;
FI;
Case(SignSelCtl[1:0])
00: dest := (SRC1[31] << 31) OR (TMP[30:0]);// Preserve Src1 sign bit
01: dest := TMP[31:0];// Preserve sign of compare result
10: dest := (0 << 31) OR (TMP[30:0]);// Zero out sign bit
11: dest := (1 << 31) OR (TMP[30:0]);// Set the sign bit
ESAC;
RETURN dest[31:0];
}
CmpOpCtl[1:0]= imm8[1:0];
SignSelCtl[1:0]=imm8[3:2];
VRANGEPS
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b == 1) AND (SRC2 *is memory*)
THEN DEST[i+31:i] := RangeSP (SRC1[i+31:i], SRC2[31:0], CmpOpCtl[1:0], SignSelCtl[1:0]);
ELSE DEST[i+31:i] := RangeSP (SRC1[i+31:i], SRC2[i+31:i], CmpOpCtl[1:0], SignSelCtl[1:0]);
FI;
VRANGEPS-Range Restriction Calculation for Packed Pairs of Float32 Values
Vol. 2C
5-666
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] = 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
The following example describes a common usage of this instruction for checking that the input operand is
bounded between ±150.
VRANGEPS zmm_dst, zmm_src, zmm_150, 02h;
Where:
zmm_dst is the destination operand.
zmm_src is the input operand to compare against ±150.
zmm_150 is the reference operand, contains the value of 150.
IMM=02(imm8[1:0]=’10) selects the Min Absolute value operation with selection of src1.sign.
In case |zmm_src| < 150, then its value will be written into zmm_dst. Otherwise, the value stored in zmm_dst
will get the value of 150 (received on zmm_150).
However, the sign control (imm8[3:2]=’00) instructs to select the sign of SRC1 received from zmm_src. So, even
in the case of |zmm_src| ≥ 150, the selected sign of SRC1 is kept.
Thus, if zmm_src < -150, the result of VRANGEPS will be the minimal value of -150 while if zmm_src > +150,
the result of VRANGE will be the maximal value of +150.
Intel C/C++ Compiler Intrinsic Equivalent
VRANGEPS __m512 _mm512_range_ps ( __m512 a, __m512 b, int imm);
VRANGEPS __m512 _mm512_range_round_ps ( __m512 a, __m512 b, int imm, int sae);
VRANGEPS __m512 _mm512_mask_range_ps (__m512 s, __mmask16 k, __m512 a, __m512 b, int imm);
VRANGEPS __m512 _mm512_mask_range_round_ps (__m512 s, __mmask16 k, __m512 a, __m512 b, int imm, int sae);
VRANGEPS __m512 _mm512_maskz_range_ps ( __mmask16 k, __m512 a, __m512 b, int imm);
VRANGEPS __m512 _mm512_maskz_range_round_ps ( __mmask16 k, __m512 a, __m512 b, int imm, int sae);
VRANGEPS __m256 _mm256_range_ps ( __m256 a, __m256 b, int imm);
VRANGEPS __m256 _mm256_mask_range_ps (__m256 s, __mmask8 k, __m256 a, __m256 b, int imm);
VRANGEPS __m256 _mm256_maskz_range_ps ( __mmask8 k, __m256 a, __m256 b, int imm);
VRANGEPS __m128 _mm_range_ps ( __m128 a, __m128 b, int imm);
VRANGEPS __m128 _mm_mask_range_ps (__m128 s, __mmask8 k, __m128 a, __m128 b, int imm);
VRANGEPS __m128 _mm_maskz_range_ps ( __mmask8 k, __m128 a, __m128 b, int imm);
SIMD Floating-Point Exceptions
Invalid, Denormal.
Other Exceptions
See Table 2-48, “Type E2 Class Exception Conditions.”
VRANGEPS-Range Restriction Calculation for Packed Pairs of Float32 Values
Vol. 2C
5-667
VRANGESD-Range Restriction Calculation From a Pair of Scalar Float64 Values
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
bit Mode
Feature Flag
Support
EVEX.LLIG.66.0F3A.W1 51 /r
A
V/V
AVX512DQ
Calculate a RANGE operation output value from 2 double
VRANGESD xmm1 {k1}{z},
OR AVX10.1
precision floating-point values in xmm2 and xmm3/m64,
xmm2, xmm3/m64{sae}, imm8
store the output to xmm1 under writemask. Imm8
specifies the comparison and sign of the range operation.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
This instruction calculates a range operation output from two input double precision floating-point values in the low
qword element of the first source operand (the second operand) and second source operand (the third operand).
The range output is written to the low qword element of the destination operand (the first operand) under the
writemask k1.
Bits7:4 of imm8 byte must be zero. The range operation output is performed in two parts, each configured by a
two-bit control field within imm8[3:0]:
• Imm8[1:0] specifies the initial comparison operation to be one of max, min, max absolute value or min
absolute value of the input value pair. Each comparison of two input values produces an intermediate result
that combines with the sign selection control (imm8[3:2]) to determine the final range operation output.
• Imm8[3:2] specifies the sign of the range operation output to be one of the following: from the first input
value, from the comparison result, set or clear.
The encodings of imm8[1:0] and imm8[3:2] are shown in Figure 5-27.
Bits 128:63 of the destination operand are copied from the respective element of the first source operand.
When one or more of the input value is a NAN, the comparison operation may signal invalid exception (IE). Details
with one of more input value is NAN is listed in Table 5-21. If the comparison raises an IE, the sign select control
(imm8[3:2]) has no effect to the range operation output; this is indicated also in Table 5-21.
When both input values are zeros of opposite signs, the comparison operation of MIN/MAX in the range compare
operation is slightly different from the conceptually similar floating-point MIN/MAX operation that are found in the
instructions VMAXPD/VMINPD. The details of MIN/MAX/MIN_ABS/MAX_ABS operation for VRANGEPD/PS/SD/SS
for magnitude-0, opposite-signed input cases are listed in Table 5-22.
Additionally, non-zero, equal-magnitude with opposite-sign input values perform MIN_ABS or MAX_ABS compar-
ison operation with result listed in Table 5-23.
VRANGESD-Range Restriction Calculation From a Pair of Scalar Float64 Values
Vol. 2C
5-668
Operation
RangeDP(SRC1[63:0], SRC2[63:0], CmpOpCtl[1:0], SignSelCtl[1:0])
{
// Check if SNAN and report IE, see also Table 5-21
IF (SRC1 = SNAN) THEN RETURN (QNAN(SRC1), set IE);
IF (SRC2 = SNAN) THEN RETURN (QNAN(SRC2), set IE);
Src1.exp := SRC1[62:52];
Src1.fraction := SRC1[51:0];
IF ((Src1.exp = 0 ) and (Src1.fraction != 0)) THEN// Src1 is a denormal number
IF DAZ THEN Src1.fraction := 0;
ELSE IF (SRC2 <> QNAN) Set DE; FI;
FI;
Src2.exp := SRC2[62:52];
Src2.fraction := SRC2[51:0];
IF ((Src2.exp = 0) and (Src2.fraction !=0 )) THEN// Src2 is a denormal number
IF DAZ THEN Src2.fraction := 0;
ELSE IF (SRC1 <> QNAN) Set DE; FI;
FI;
IF (SRC2 = QNAN) THEN{TMP[63:0] := SRC1[63:0]}
ELSE IF(SRC1 = QNAN) THEN{TMP[63:0] := SRC2[63:0]}
ELSE IF (Both SRC1, SRC2 are magnitude-0 and opposite-signed) TMP[63:0] := from Table 5-22
ELSE IF (Both SRC1, SRC2 are magnitude-equal and opposite-signed and CmpOpCtl[1:0] > 01) TMP[63:0] := from Table 5-23
ELSE
Case(CmpOpCtl[1:0])
00: TMP[63:0] := (SRC1[63:0] ≤ SRC2[63:0]) ? SRC1[63:0] : SRC2[63:0];
01: TMP[63:0] := (SRC1[63:0] ≤ SRC2[63:0]) ? SRC2[63:0] : SRC1[63:0];
10: TMP[63:0] := (ABS(SRC1[63:0]) ≤ ABS(SRC2[63:0])) ? SRC1[63:0] : SRC2[63:0];
11: TMP[63:0] := (ABS(SRC1[63:0]) ≤ ABS(SRC2[63:0])) ? SRC2[63:0] : SRC1[63:0];
ESAC;
FI;
Case(SignSelCtl[1:0])
00: dest := (SRC1[63] << 63) OR (TMP[62:0]);// Preserve Src1 sign bit
01: dest := TMP[63:0];// Preserve sign of compare result
10: dest := (0 << 63) OR (TMP[62:0]);// Zero out sign bit
11: dest := (1 << 63) OR (TMP[62:0]);// Set the sign bit
ESAC;
RETURN dest[63:0];
}
CmpOpCtl[1:0]= imm8[1:0];
SignSelCtl[1:0]=imm8[3:2];
VRANGESD-Range Restriction Calculation From a Pair of Scalar Float64 Values
Vol. 2C
5-669
VRANGESD
IF k1[0] OR *no writemask*
THEN DEST[63:0] := RangeDP (SRC1[63:0], SRC2[63:0], CmpOpCtl[1:0], SignSelCtl[1:0]);
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
DEST[63:0] = 0
FI;
FI;
DEST[127:64] := SRC1[127:64]
DEST[MAXVL-1:128] := 0
The following example describes a common usage of this instruction for checking that the input operand is
bounded between ±1023.
VRANGESD xmm_dst, xmm_src, xmm_1023, 02h;
Where:
xmm_dst is the destination operand.
xmm_src is the input operand to compare against ±1023.
xmm_1023 is the reference operand, contains the value of 1023.
IMM=02(imm8[1:0]=’10) selects the Min Absolute value operation with selection of src1.sign.
In case |xmm_src| < 1023, then its value will be written into xmm_dst. Otherwise, the value stored in xmm_dst
will get the value of 1023 (received on xmm_1023).
However, the sign control (imm8[3:2]=’00) instructs to select the sign of SRC1 received from xmm_src. So, even
in the case of |xmm_src| ≥ 1023, the selected sign of SRC1 is kept.
Thus, if xmm_src < -1023, the result of VRANGEPD will be the minimal value of -1023while if xmm_src > +1023,
the result of VRANGE will be the maximal value of +1023.
Intel C/C++ Compiler Intrinsic Equivalent
VRANGESD __m128d _mm_range_sd ( __m128d a, __m128d b, int imm);
VRANGESD __m128d _mm_range_round_sd ( __m128d a, __m128d b, int imm, int sae);
VRANGESD __m128d _mm_mask_range_sd (__m128d s, __mmask8 k, __m128d a, __m128d b, int imm);
VRANGESD __m128d _mm_mask_range_round_sd (__m128d s, __mmask8 k, __m128d a, __m128d b, int imm, int sae);
VRANGESD __m128d _mm_maskz_range_sd ( __mmask8 k, __m128d a, __m128d b, int imm);
VRANGESD __m128d _mm_maskz_range_round_sd ( __mmask8 k, __m128d a, __m128d b, int imm, int sae);
SIMD Floating-Point Exceptions
Invalid, Denormal.
Other Exceptions
See Table 2-49, “Type E3 Class Exception Conditions.”
VRANGESD-Range Restriction Calculation From a Pair of Scalar Float64 Values
Vol. 2C
5-670
VRANGESS-Range Restriction Calculation From a Pair of Scalar Float32 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.LLIG.66.0F3A.W0 51 /r
A
V/V
AVX512DQ
Calculate a RANGE operation output value from 2
VRANGESS xmm1 {k1}{z},
OR AVX10.1
single-precision floating-point values in xmm2 and
xmm2, xmm3/m32{sae}, imm8
xmm3/m32, store the output to xmm1 under
writemask. Imm8 specifies the comparison and sign of
the range operation.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
This instruction calculates a range operation output from two input single precision floating-point values in the low
dword element of the first source operand (the second operand) and second source operand (the third operand).
The range output is written to the low dword element of the destination operand (the first operand) under the
writemask k1.
Bits7:4 of imm8 byte must be zero. The range operation output is performed in two parts, each configured by a
two-bit control field within imm8[3:0]:
• Imm8[1:0] specifies the initial comparison operation to be one of max, min, max absolute value or min
absolute value of the input value pair. Each comparison of two input values produces an intermediate result
that combines with the sign selection control (imm8[3:2]) to determine the final range operation output.
• Imm8[3:2] specifies the sign of the range operation output to be one of the following: from the first input
value, from the comparison result, set or clear.
The encodings of imm8[1:0] and imm8[3:2] are shown in Figure 5-27.
Bits 128:31 of the destination operand are copied from the respective elements of the first source operand.
When one or more of the input value is a NAN, the comparison operation may signal invalid exception (IE). Details
with one of more input value is NAN is listed in Table 5-21. If the comparison raises an IE, the sign select control
(imm8[3:2]) has no effect to the range operation output; this is indicated also in Table 5-21.
When both input values are zeros of opposite signs, the comparison operation of MIN/MAX in the range compare
operation is slightly different from the conceptually similar floating-point MIN/MAX operation that are found in the
instructions VMAXPD/VMINPD. The details of MIN/MAX/MIN_ABS/MAX_ABS operation for VRANGEPD/PS/SD/SS
for magnitude-0, opposite-signed input cases are listed in Table 5-22.
Additionally, non-zero, equal-magnitude with opposite-sign input values perform MIN_ABS or MAX_ABS compar-
ison operation with result listed in Table 5-23.
VRANGESS-Range Restriction Calculation From a Pair of Scalar Float32 Values
Vol. 2C
5-671
Operation
RangeSP(SRC1[31:0], SRC2[31:0], CmpOpCtl[1:0], SignSelCtl[1:0])
{
// Check if SNAN and report IE, see also Table 5-21
IF (SRC1=SNAN) THEN RETURN (QNAN(SRC1), set IE);
IF (SRC2=SNAN) THEN RETURN (QNAN(SRC2), set IE);
Src1.exp := SRC1[30:23];
Src1.fraction := SRC1[22:0];
IF ((Src1.exp = 0 ) and (Src1.fraction != 0 )) THEN// Src1 is a denormal number
IF DAZ THEN Src1.fraction := 0;
ELSE IF (SRC2 <> QNAN) Set DE; FI;
FI;
Src2.exp := SRC2[30:23];
Src2.fraction := SRC2[22:0];
IF ((Src2.exp = 0 ) and (Src2.fraction != 0 )) THEN// Src2 is a denormal number
IF DAZ THEN Src2.fraction := 0;
ELSE IF (SRC1 <> QNAN) Set DE; FI;
FI;
IF (SRC2 = QNAN) THEN{TMP[31:0] := SRC1[31:0]}
ELSE IF(SRC1 = QNAN) THEN{TMP[31:0] := SRC2[31:0]}
ELSE IF (Both SRC1, SRC2 are magnitude-0 and opposite-signed) TMP[31:0] := from Table 5-22
ELSE IF (Both SRC1, SRC2 are magnitude-equal and opposite-signed and CmpOpCtl[1:0] > 01) TMP[31:0] := from Table 5-23
ELSE
Case(CmpOpCtl[1:0])
00: TMP[31:0] := (SRC1[31:0] ≤ SRC2[31:0]) ? SRC1[31:0] : SRC2[31:0];
01: TMP[31:0] := (SRC1[31:0] ≤ SRC2[31:0]) ? SRC2[31:0] : SRC1[31:0];
10: TMP[31:0] := (ABS(SRC1[31:0]) ≤ ABS(SRC2[31:0])) ? SRC1[31:0] : SRC2[31:0];
11: TMP[31:0] := (ABS(SRC1[31:0]) ≤ ABS(SRC2[31:0])) ? SRC2[31:0] : SRC1[31:0];
ESAC;
FI;
Case(SignSelCtl[1:0])
00: dest := (SRC1[31] << 31) OR (TMP[30:0]);// Preserve Src1 sign bit
01: dest := TMP[31:0];// Preserve sign of compare result
10: dest := (0 << 31) OR (TMP[30:0]);// Zero out sign bit
11: dest := (1 << 31) OR (TMP[30:0]);// Set the sign bit
ESAC;
RETURN dest[31:0];
}
CmpOpCtl[1:0]= imm8[1:0];
SignSelCtl[1:0]=imm8[3:2];
VRANGESS-Range Restriction Calculation From a Pair of Scalar Float32 Values
Vol. 2C
5-672
VRANGESS
IF k1[0] OR *no writemask*
THEN DEST[31:0] := RangeSP (SRC1[31:0], SRC2[31:0], CmpOpCtl[1:0], SignSelCtl[1:0]);
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
DEST[31:0] = 0
FI;
FI;
DEST[127:32] := SRC1[127:32]
DEST[MAXVL-1:128] := 0
The following example describes a common usage of this instruction for checking that the input operand is
bounded between ±150.
VRANGESS zmm_dst, zmm_src, zmm_150, 02h;
Where:
xmm_dst is the destination operand.
xmm_src is the input operand to compare against ±150.
xmm_150 is the reference operand, contains the value of 150.
IMM=02(imm8[1:0]=’10) selects the Min Absolute value operation with selection of src1.sign.
In case |xmm_src| < 150, then its value will be written into zmm_dst. Otherwise, the value stored in xmm_dst
will get the value of 150 (received on zmm_150).
However, the sign control (imm8[3:2]=’00) instructs to select the sign of SRC1 received from xmm_src. So, even
in the case of |xmm_src| ≥ 150, the selected sign of SRC1 is kept.
Thus, if xmm_src < -150, the result of VRANGESS will be the minimal value of -150 while if xmm_src > +150,
the result of VRANGE will be the maximal value of +150.
Intel C/C++ Compiler Intrinsic Equivalent
VRANGESS __m128 _mm_range_ss ( __m128 a, __m128 b, int imm);
VRANGESS __m128 _mm_range_round_ss ( __m128 a, __m128 b, int imm, int sae);
VRANGESS __m128 _mm_mask_range_ss (__m128 s, __mmask8 k, __m128 a, __m128 b, int imm);
VRANGESS __m128 _mm_mask_range_round_ss (__m128 s, __mmask8 k, __m128 a, __m128 b, int imm, int sae);
VRANGESS __m128 _mm_maskz_range_ss ( __mmask8 k, __m128 a, __m128 b, int imm);
VRANGESS __m128 _mm_maskz_range_round_ss ( __mmask8 k, __m128 a, __m128 b, int imm, int sae);
SIMD Floating-Point Exceptions
Invalid, Denormal.
Other Exceptions
See Table 2-49, “Type E3 Class Exception Conditions.”
VRANGESS-Range Restriction Calculation From a Pair of Scalar Float32 Values
Vol. 2C
5-673
VRCP14PD-Compute Approximate Reciprocals of Packed Float64 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W1 4C /r
A
V/V
(AVX512VL AND
Computes the approximate reciprocals of the packed
VRCP14PD xmm1 {k1}{z},
AVX512F) OR
double precision floating-point values in
xmm2/m128/m64bcst
AVX10.1
xmm2/m128/m64bcst and stores the results in xmm1.
Under writemask.
EVEX.256.66.0F38.W1 4C /r
A
V/V
(AVX512VL AND
Computes the approximate reciprocals of the packed
VRCP14PD ymm1 {k1}{z},
AVX512F) OR
double precision floating-point values in
ymm2/m256/m64bcst
AVX10.1
ymm2/m256/m64bcst and stores the results in ymm1.
Under writemask.
EVEX.512.66.0F38.W1 4C /r
A
V/V
AVX512F
Computes the approximate reciprocals of the packed
VRCP14PD zmm1 {k1}{z},
OR AVX10.1
double precision floating-point values in
zmm2/m512/m64bcst
zmm2/m512/m64bcst and stores the results in zmm1.
Under writemask.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
This instruction performs a SIMD computation of the approximate reciprocals of eight/four/two packed double
precision floating-point values in the source operand (the second operand) and stores the packed double precision
floating-point results in the destination operand. The maximum relative error for this approximation is less than 2-
14.
The source operand can be a ZMM register, a 512-bit memory location, or a 512-bit vector broadcasted from a 64-
bit memory location. The destination operand is a ZMM register conditionally updated according to the writemask.
The VRCP14PD instruction is not affected by the rounding control bits in the MXCSR register. When a source value
is a 0.0, an ∞ with the sign of the source value is returned. A denormal source value will be treated as zero only in
case of DAZ bit set in MXCSR. Otherwise it is treated correctly (i.e., not as a 0.0). Underflow results are flushed to
zero only in case of FTZ bit set in MXCSR. Otherwise it will be treated correctly (i.e., correct underflow result is
written) with the sign of the operand. When a source value is a SNaN or QNaN, the SNaN is converted to a QNaN
or the source QNaN is returned.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
MXCSR exception flags are not affected by this instruction and floating-point exceptions are not reported.
Table 5-24. VRCP14PD/VRCP14SD Special Cases
Input value
Result value
Comments
0 ≤ X ≤ 2-1024
INF
Very small denormal
-2-1024 ≤ X ≤ -0
-INF
Very small denormal
X > 21022
Underflow
Up to 18 bits of fractions are returned*
X < -21022
-Underflow
Up to 18 bits of fractions are returned*
X = 2-n
2n
X = -2-n
-2n
* in this case the mantissa is shifted right by one or two bits
VRCP14PD-Compute Approximate Reciprocals of Packed Float64 Values
Vol. 2C
5-674
A numerically exact implementation of VRCP14xx can be found at https://software.intel.com/en-us/articles/refer-
ence-implementations-for-IA-approximation-instructions-vrcp14-vrsqrt14-vrcp28-vrsqrt28-vexp2.
Operation
VRCP14PD ((EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC *is memory*)
THEN DEST[i+63:i] := APPROXIMATE(1.0/SRC[63:0]);
ELSE DEST[i+63:i] := APPROXIMATE(1.0/SRC[i+63:i]);
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VRCP14PD __m512d _mm512_rcp14_pd( __m512d a);
VRCP14PD __m512d _mm512_mask_rcp14_pd(__m512d s, __mmask8 k, __m512d a);
VRCP14PD __m512d _mm512_maskz_rcp14_pd( __mmask8 k, __m512d a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
VRCP14PD-Compute Approximate Reciprocals of Packed Float64 Values
Vol. 2C
5-675
VRCP14PS-Compute Approximate Reciprocals of Packed Float32 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 4C /r
A
V/V
(AVX512VL AND
Computes the approximate reciprocals of the packed
VRCP14PS xmm1 {k1}{z},
AVX512F) OR
single-precision floating-point values in
xmm2/m128/m32bcst
AVX10.1
xmm2/m128/m32bcst and stores the results in xmm1.
Under writemask.
EVEX.256.66.0F38.W0 4C /r
A
V/V
(AVX512VL AND
Computes the approximate reciprocals of the packed
VRCP14PS ymm1 {k1}{z},
AVX512F) OR
single-precision floating-point values in
ymm2/m256/m32bcst
AVX10.1
ymm2/m256/m32bcst and stores the results in ymm1.
Under writemask.
EVEX.512.66.0F38.W0 4C /r
A
V/V
AVX512F
Computes the approximate reciprocals of the packed
VRCP14PS zmm1 {k1}{z},
OR AVX10.1
single-precision floating-point values in
zmm2/m512/m32bcst
zmm2/m512/m32bcst and stores the results in zmm1.
Under writemask.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
This instruction performs a SIMD computation of the approximate reciprocals of the packed single precision
floating-point values in the source operand (the second operand) and stores the packed single precision floating-
point results in the destination operand (the first operand). The maximum relative error for this approximation is
less than 2-14.
The source operand can be a ZMM register, a 512-bit memory location or a 512-bit vector broadcasted from a 32-
bit memory location. The destination operand is a ZMM register conditionally updated according to the writemask.
The VRCP14PS instruction is not affected by the rounding control bits in the MXCSR register. When a source value
is a 0.0, an ∞ with the sign of the source value is returned. A denormal source value will be treated as zero only in
case of DAZ bit set in MXCSR. Otherwise it is treated correctly (i.e., not as a 0.0). Underflow results are flushed to
zero only in case of FTZ bit set in MXCSR. Otherwise it will be treated correctly (i.e., correct underflow result is
written) with the sign of the operand. When a source value is a SNaN or QNaN, the SNaN is converted to a QNaN
or the source QNaN is returned.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
MXCSR exception flags are not affected by this instruction and floating-point exceptions are not reported.
Table 5-25. VRCP14PS/VRCP14SS Special Cases
Input value
Result value
Comments
0 ≤ X ≤ 2-128
INF
Very small denormal
-2-128 ≤ X ≤ -0
-INF
Very small denormal
X > 2126
Underflow
Up to 18 bits of fractions are returned1
X < -2126
-Underflow
Up to 18 bits of fractions are returned1
X = 2-n
2n
X = -2-n
-2n
NOTES:
1. In this case, the mantissa is shifted right by one or two bits.
VRCP14PS-Compute Approximate Reciprocals of Packed Float32 Values
Vol. 2C
5-676
A numerically exact implementation of VRCP14xx can be found at:
vrsqrt14-vrcp28-vrsqrt28-vexp2.
Operation
VRCP14PS (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC *is memory*)
THEN DEST[i+31:i] := APPROXIMATE(1.0/SRC[31:0]);
ELSE DEST[i+31:i] := APPROXIMATE(1.0/SRC[i+31:i]);
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VRCP14PS __m512 _mm512_rcp14_ps( __m512 a);
VRCP14PS __m512 _mm512_mask_rcp14_ps(__m512 s, __mmask16 k, __m512 a);
VRCP14PS __m512 _mm512_maskz_rcp14_ps( __mmask16 k, __m512 a);
VRCP14PS __m256 _mm256_rcp14_ps( __m256 a);
VRCP14PS __m256 _mm512_mask_rcp14_ps(__m256 s, __mmask8 k, __m256 a);
VRCP14PS __m256 _mm512_maskz_rcp14_ps( __mmask8 k, __m256 a);
VRCP14PS __m128 _mm_rcp14_ps( __m128 a);
VRCP14PS __m128 _mm_mask_rcp14_ps(__m128 s, __mmask8 k, __m128 a);
VRCP14PS __m128 _mm_maskz_rcp14_ps( __mmask8 k, __m128 a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
VRCP14PS-Compute Approximate Reciprocals of Packed Float32 Values
Vol. 2C
5-677
VRCP14SD-Compute Approximate Reciprocal of Scalar Float64 Value
Opcode/
Op
64/32
CPUID Feature
Description
Instruction
/ En
bit Mode
Flag
Support
EVEX.LLIG.66.0F38.W1 4D /r
A
V/V
AVX512F
Computes the approximate reciprocal of the scalar
VRCP14SD xmm1 {k1}{z}, xmm2,
OR AVX10.1
double precision floating-point value in xmm3/m64 and
xmm3/m64
stores the result in xmm1 using writemask k1. Also,
upper double precision floating-point value (bits[127:64])
from xmm2 is copied to xmm1[127:64].
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
This instruction performs a SIMD computation of the approximate reciprocal of the low double precision floating-
point value in the second source operand (the third operand) stores the result in the low quadword element of the
destination operand (the first operand) according to the writemask k1. Bits (127:64) of the XMM register destina-
tion are copied from corresponding bits in the first source operand (the second operand). The maximum relative
error for this approximation is less than 2-14. The source operand can be an XMM register or a 64-bit memory loca-
tion. The destination operand is an XMM register.
The VRCP14SD instruction is not affected by the rounding control bits in the MXCSR register. When a source value
is a 0.0, an ∞ with the sign of the source value is returned. A denormal source value will be treated as zero only in
case of DAZ bit set in MXCSR. Otherwise it is treated correctly (i.e., not as a 0.0). Underflow results are flushed to
zero only in case of FTZ bit set in MXCSR. Otherwise it will be treated correctly (i.e., correct underflow result is
written) with the sign of the operand. When a source value is a SNaN or QNaN, the SNaN is converted to a QNaN
or the source QNaN is returned. See Table 5-24 for special-case input values.
MXCSR exception flags are not affected by this instruction and floating-point exceptions are not reported.
A numerically exact implementation of VRCP14xx can be found at:
vrsqrt14-vrcp28-vrsqrt28-vexp2.
Operation
VRCP14SD (EVEX version)
IF k1[0] OR *no writemask*
THEN DEST[63:0] := APPROXIMATE(1.0/SRC2[63:0]);
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
DEST[63:0] := 0
FI;
FI;
DEST[127:64] := SRC1[127:64]
DEST[MAXVL-1:128] := 0
VRCP14SD-Compute Approximate Reciprocal of Scalar Float64 Value
Vol. 2C
5-678
Intel C/C++ Compiler Intrinsic Equivalent
VRCP14SD __m128d _mm_rcp14_sd( __m128d a, __m128d b);
VRCP14SD __m128d _mm_mask_rcp14_sd(__m128d s, __mmask8 k, __m128d a, __m128d b);
VRCP14SD __m128d _mm_maskz_rcp14_sd( __mmask8 k, __m128d a, __m128d b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-53, “Type E5 Class Exception Conditions.”
VRCP14SD-Compute Approximate Reciprocal of Scalar Float64 Value
Vol. 2C
5-679
VRCP14SS-Compute Approximate Reciprocal of Scalar Float32 Value
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
bit Mode
Feature Flag
Support
EVEX.LLIG.66.0F38.W0 4D /r
A
V/V
AVX512F
Computes the approximate reciprocal of the scalar
VRCP14SS xmm1 {k1}{z}, xmm2,
OR AVX10.1
single-precision floating-point value in xmm3/m32 and
xmm3/m32
stores the results in xmm1 using writemask k1. Also,
upper double precision floating-point value
(bits[127:32]) from xmm2 is copied to xmm1[127:32].
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
This instruction performs a SIMD computation of the approximate reciprocal of the low single precision floating-
point value in the second source operand (the third operand) and stores the result in the low quadword element of
the destination operand (the first operand) according to the writemask k1. Bits (127:32) of the XMM register desti-
nation are copied from corresponding bits in the first source operand (the second operand). The maximum relative
error for this approximation is less than 2-14. The source operand can be an XMM register or a 32-bit memory loca-
tion. The destination operand is an XMM register.
The VRCP14SS instruction is not affected by the rounding control bits in the MXCSR register. When a source value
is a 0.0, an ∞ with the sign of the source value is returned. A denormal source value will be treated as zero only in
case of DAZ bit set in MXCSR. Otherwise it is treated correctly (i.e., not as a 0.0). Underflow results are flushed to
zero only in case of FTZ bit set in MXCSR. Otherwise it will be treated correctly (i.e., correct underflow result is
written) with the sign of the operand. When a source value is a SNaN or QNaN, the SNaN is converted to a QNaN
or the source QNaN is returned. See Table 5-25 for special-case input values.
MXCSR exception flags are not affected by this instruction and floating-point exceptions are not reported.
A numerically exact implementation of VRCP14xx can be found at https://software.intel.com/en-us/articles/refer-
ence-implementations-for-IA-approximation-instructions-vrcp14-vrsqrt14-vrcp28-vrsqrt28-vexp2.
Operation
VRCP14SS (EVEX version)
IF k1[0] OR *no writemask*
THEN DEST[31:0] := APPROXIMATE(1.0/SRC2[31:0]);
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
DEST[31:0] := 0
FI;
FI;
DEST[127:32] := SRC1[127:32]
DEST[MAXVL-1:128] := 0
VRCP14SS-Compute Approximate Reciprocal of Scalar Float32 Value
Vol. 2C
5-680
Intel C/C++ Compiler Intrinsic Equivalent
VRCP14SS __m128 _mm_rcp14_ss( __m128 a, __m128 b);
VRCP14SS __m128 _mm_mask_rcp14_ss(__m128 s, __mmask8 k, __m128 a, __m128 b);
VRCP14SS __m128 _mm_maskz_rcp14_ss( __mmask8 k, __m128 a, __m128 b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-53, “Type E5 Class Exception Conditions.”
VRCP14SS-Compute Approximate Reciprocal of Scalar Float32 Value
Vol. 2C
5-681
VRCPPH-Compute Reciprocals of Packed FP16 Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.MAP6.W0 4C /r
A
V/V
(AVX512_FP16
Compute the approximate reciprocals of packed
VRCPPH xmm1{k1}{z},
AND AVX512VL)
FP16 values in xmm2/m128/m16bcst and store
xmm2/m128/m16bcst
OR AVX10.1
the result in xmm1 subject to writemask k1.
EVEX.256.66.MAP6.W0 4C /r
A
V/V
(AVX512_FP16
Compute the approximate reciprocals of packed
VRCPPH ymm1{k1}{z},
AND AVX512VL)
FP16 values in ymm2/m256/m16bcst and store
ymm2/m256/m16bcst
OR AVX10.1
the result in ymm1 subject to writemask k1.
EVEX.512.66.MAP6.W0 4C /r
A
V/V
AVX512_FP16
Compute the approximate reciprocals of packed
VRCPPH zmm1{k1}{z},
OR AVX10.1
FP16 values in zmm2/m512/m16bcst and store
zmm2/m512/m16bcst
the result in zmm1 subject to writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
This instruction performs a SIMD computation of the approximate reciprocals of 8/16/32 packed FP16 values in the
source operand (the second operand) and stores the packed FP16 results in the destination operand. The maximum
relative error for this approximation is less than 2-11 + 2-14.
For special cases, see Table 5-26.
Table 5-26. VRCPPH/VRCPSH Special Cases
Input Value
Result Value
Comments
0 ≤ X ≤ 2-16
INF
Very small denormal
−2-16 ≤ X ≤ -0
-INF
Very small denormal
X > +∞
+0
X < -∞
-0
X = 2-n
2n
X = -2-n
-2n
VRCPPH-Compute Reciprocals of Packed FP16 Values
Vol. 2C
5-682
Operation
VRCPPH dest{k1}, src
VL = 128, 256 or 512
KL := VL/16
FOR i := 0 to KL-1:
IF k1[i] or *no writemask*:
IF SRC is memory and (EVEX.b = 1):
tsrc := src.fp16[0]
ELSE:
tsrc := src.fp16[i]
DEST.fp16[i] := APPROXIMATE(1.0 / tsrc)
ELSE IF *zeroing*:
DEST.fp16[i] := 0
//else DEST.fp16[i] remains unchanged
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VRCPPH __m128h _mm_mask_rcp_ph (__m128h src, __mmask8 k, __m128h a);
VRCPPH __m128h _mm_maskz_rcp_ph (__mmask8 k, __m128h a);
VRCPPH __m128h _mm_rcp_ph (__m128h a);
VRCPPH __m256h _mm256_mask_rcp_ph (__m256h src, __mmask16 k, __m256h a);
VRCPPH __m256h _mm256_maskz_rcp_ph (__mmask16 k, __m256h a);
VRCPPH __m256h _mm256_rcp_ph (__m256h a);
VRCPPH __m512h _mm512_mask_rcp_ph (__m512h src, __mmask32 k, __m512h a);
VRCPPH __m512h _mm512_maskz_rcp_ph (__mmask32 k, __m512h a);
VRCPPH __m512h _mm512_rcp_ph (__m512h a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VRCPPH-Compute Reciprocals of Packed FP16 Values
Vol. 2C
5-683
VRCPSH-Compute Reciprocal of Scalar FP16 Value
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.LLIG.66.MAP6.W0 4D /r
A
V/V
AVX512_FP16
Compute the approximate reciprocal of the low
VRCPSH xmm1{k1}{z}, xmm2,
OR AVX10.1
FP16 value in xmm3/m16 and store the result in
xmm3/m16
xmm1 subject to writemask k1. Bits 127:16 from
xmm2 are copied to xmm1[127:16].
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Scalar
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
This instruction performs a SIMD computation of the approximate reciprocal of the low FP16 value in the second
source operand (the third operand) and stores the result in the low word element of the destination operand (the
first operand) according to the writemask k1. Bits 127:16 of the XMM register destination are copied from corre-
sponding bits in the first source operand (the second operand). The maximum relative error for this approximation
is less than 2-11 + 2-14.
Bits 127:16 of the destination operand are copied from the corresponding bits of the first source operand. Bits
MAXVL-1:128 of the destination operand are zeroed. The low FP16 element of the destination is updated according
to the writemask.
For special cases, see Table 5-26.
Operation
VRCPSH dest{k1}, src1, src2
IF k1[0] or *no writemask*:
DEST.fp16[0] := APPROXIMATE(1.0 / src2.fp16[0])
ELSE IF *zeroing*:
DEST.fp16[0] := 0
//else DEST.fp16[0] remains unchanged
DEST[127:16] := src1[127:16]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VRCPSH __m128h _mm_mask_rcp_sh (__m128h src, __mmask8 k, __m128h a, __m128h b);
VRCPSH __m128h _mm_maskz_rcp_sh (__mmask8 k, __m128h a, __m128h b);
VRCPSH __m128h _mm_rcp_sh (__m128h a, __m128h b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
EVEX-encoded instruction, see Table 2-60, “Type E10 Class Exception Conditions.”
VRCPSH-Compute Reciprocal of Scalar FP16 Value
Vol. 2C
5-684
VREDUCEPD-Perform Reduction Transformation on Packed Float64 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W1 56 /r ib
A
V/V
(AVX512VL
Perform reduction transformation on packed double
VREDUCEPD xmm1 {k1}{z},
AND AVX512DQ)
precision floating-point values in
xmm2/m128/m64bcst, imm8
OR AVX10.1
xmm2/m128/m32bcst by subtracting a number of
fraction bits specified by the imm8 field. Stores the
result in xmm1 register under writemask k1.
EVEX.256.66.0F3A.W1 56 /r ib
A
V/V
(AVX512VL
Perform reduction transformation on packed double
VREDUCEPD ymm1 {k1}{z},
AND AVX512DQ)
precision floating-point values in
ymm2/m256/m64bcst, imm8
OR AVX10.1
ymm2/m256/m32bcst by subtracting a number of
fraction bits specified by the imm8 field. Stores the
result in ymm1 register under writemask k1.
EVEX.512.66.0F3A.W1 56 /r ib
A
V/V
AVX512DQ
Perform reduction transformation on double precision
VREDUCEPD zmm1 {k1}{z},
OR AVX10.1
floating-point values in zmm2/m512/m32bcst by
zmm2/m512/m64bcst{sae},
subtracting a number of fraction bits specified by the
imm8
imm8 field. Stores the result in zmm1 register under
writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8
N/A
Description
Perform reduction transformation of the packed binary encoded double precision floating-point values in the source
operand (the second operand) and store the reduced results in binary floating-point format to the destination
operand (the first operand) under the writemask k1.
The reduction transformation subtracts the integer part and the leading M fractional bits from the binary floating-
point source value, where M is a unsigned integer specified by imm8[7:4], see Figure 5-28. Specifically, the reduc-
tion transformation can be expressed as:
dest = src - (ROUND(2M*src))*2-M;
where “Round()” treats “src”, “2M”, and their product as binary floating-point numbers with normalized signifi-
cand and biased exponents.
The magnitude of the reduced result can be expressed by considering src= 2p*man2,
where ‘man2’ is the normalized significand and ‘p’ is the unbiased exponent
Then if RC = RNE: 0<=|Reduced Result|<=2p-M-1
Then if RC ≠ RNE: 0<=|Reduced Result|<2p-M
This instruction might end up with a precision exception set. However, in case of SPE set (i.e., Suppress Precision
Exception, which is imm8[3]=1), no precision exception is reported.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
VREDUCEPD-Perform Reduction Transformation on Packed Float64 Values
Vol. 2C
5-685
7
6
5
4
3
2
1
0
imm8
Fixed point length
SPE
RS
Round Control Override
Suppress Precision Exception: Imm8[3]
Imm8[1:0] = 00b : Round nearest even
Imm8[3] = 0b : Use MXCSR exception mask
Round Select: Imm8[2]
Imm8[7:4] : Number of fixed points to subtract
Imm8[1:0] = 01b : Round down
Imm8[3] = 1b : Suppress
Imm8[2] = 0b : Use Imm8[1:0]
Imm8[1:0] = 10b : Round up
Imm8[2] = 1b : Use MXCSR
Imm8[1:0] = 11b : Truncate
Figure 5-28. Imm8 Controls for VREDUCEPD/SD/PS/SS
Handling of special case of input values are listed in Table 5-27.
Table 5-27. VREDUCEPD/SD/PS/SS Special Cases
Round Mode
Returned value
|Src1| < 2-M-1
RNE
Src1
RPI, Src1 > 0
Round (Src1-2-M) *
RPI, Src1 ≤ 0
Src1
RNI, Src1 ≥ 0
Src1
|Src1| < 2-M
RNI, Src1 < 0
Round (Src1+2-M) *
NOT RNI
+0.0
Src1 = ±0, or
Dest = ±0 (Src1!=INF)
RNI
-0.0
Src1 = ±INF
any
+0.0
Src1= ±NAN
n/a
QNaN(Src1)
* Round control = (imm8.MS1)? MXCSR.RC: imm8.RC
Operation
ReduceArgumentDP(SRC[63:0], imm8[7:0])
{
// Check for NaN
IF (SRC [63:0] = NAN) THEN
RETURN (Convert SRC[63:0] to QNaN); FI;
M := imm8[7:4]; // Number of fraction bits of the normalized significand to be subtracted
RC := imm8[1:0];// Round Control for ROUND() operation
RC source := imm[2];
SPE := imm[3];// Suppress Precision Exception
TMP[63:0] := 2-M *{ROUND(2M*SRC[63:0], SPE, RC_source, RC)}; // ROUND() treats SRC and 2M as standard binary FP values
TMP[63:0] := SRC[63:0] - TMP[63:0]; // subtraction under the same RC,SPE controls
RETURN TMP[63:0]; // binary encoded FP with biased exponent and normalized significand
}
VREDUCEPD-Perform Reduction Transformation on Packed Float64 Values
Vol. 2C
5-686
VREDUCEPD
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b == 1) AND (SRC *is memory*)
THEN DEST[i+63:i] := ReduceArgumentDP(SRC[63:0], imm8[7:0]);
ELSE DEST[i+63:i] := ReduceArgumentDP(SRC[i+63:i], imm8[7:0]);
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] = 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VREDUCEPD __m512d _mm512_mask_reduce_pd( __m512d a, int imm, int sae)
VREDUCEPD __m512d _mm512_mask_reduce_pd(__m512d s, __mmask8 k, __m512d a, int imm, int sae)
VREDUCEPD __m512d _mm512_maskz_reduce_pd(__mmask8 k, __m512d a, int imm, int sae)
VREDUCEPD __m256d _mm256_mask_reduce_pd( __m256d a, int imm)
VREDUCEPD __m256d _mm256_mask_reduce_pd(__m256d s, __mmask8 k, __m256d a, int imm)
VREDUCEPD __m256d _mm256_maskz_reduce_pd(__mmask8 k, __m256d a, int imm)
VREDUCEPD __m128d _mm_mask_reduce_pd( __m128d a, int imm)
VREDUCEPD __m128d _mm_mask_reduce_pd(__m128d s, __mmask8 k, __m128d a, int imm)
VREDUCEPD __m128d _mm_maskz_reduce_pd(__mmask8 k, __m128d a, int imm)
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
See Table 2-48, “Type E2 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B.
VREDUCEPD-Perform Reduction Transformation on Packed Float64 Values
Vol. 2C
5-687
VREDUCEPH-Perform Reduction Transformation on Packed FP16 Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.NP.0F3A.W0 56 /r /ib
A
V/V
(AVX512_FP16
Perform reduction transformation on packed
VREDUCEPH xmm1{k1}{z},
AND AVX512VL)
FP16 values in xmm2/m128/m16bcst by
xmm2/m128/m16bcst, imm8
OR AVX10.1
subtracting a number of fraction bits specified by
the imm8 field. Store the result in xmm1 subject
to writemask k1.
EVEX.256.NP.0F3A.W0 56 /r /ib
A
V/V
(AVX512_FP16
Perform reduction transformation on packed
VREDUCEPH ymm1{k1}{z},
AND AVX512VL)
FP16 values in ymm2/m256/m16bcst by
ymm2/m256/m16bcst, imm8
OR AVX10.1
subtracting a number of fraction bits specified by
the imm8 field. Store the result in ymm1 subject
to writemask k1.
EVEX.512.NP.0F3A.W0 56 /r /ib
A
V/V
AVX512_FP16
Perform reduction transformation on packed
VREDUCEPH zmm1{k1}{z},
OR AVX10.1
FP16 values in zmm2/m512/m16bcst by
zmm2/m512/m16bcst {sae}, imm8
subtracting a number of fraction bits specified by
the imm8 field. Store the result in zmm1 subject
to writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8 (r)
N/A
Description
This instruction performs a reduction transformation of the packed binary encoded FP16 values in the source
operand (the second operand) and store the reduced results in binary FP format to the destination operand (the
first operand) under the writemask k1.
The reduction transformation subtracts the integer part and the leading M fractional bits from the binary FP source
value, where M is a unsigned integer specified by imm8[7:4]. Specifically, the reduction transformation can be
expressed as:
dest = src - (ROUND(2M * src)) * 2-M
where ROUND() treats src, 2M, and their product as binary FP numbers with normalized significand and biased
exponents.
The magnitude of the reduced result can be expressed by considering src = 2p * man2, where ‘man2’ is the normal-
ized significand and ‘p’ is the unbiased exponent.
Then if RC=RNE: 0 ≤ |ReducedResult| ≤ 2-M-1.
Then if RC ≠ RNE: 0 ≤ |ReducedResult| < 2-M.
This instruction might end up with a precision exception set. However, in case of SPE set (i.e., Suppress Precision
Exception, which is imm8[3]=1), no precision exception is reported.
This instruction may generate tiny non-zero result. If it does so, it does not report underflow exception, even if
underflow exceptions are unmasked (UM flag in MXCSR register is 0).
For special cases, see Table 5-28.
VREDUCEPH-Perform Reduction Transformation on Packed FP16 Values
Vol. 2C
5-688
Table 5-28. VREDUCEPH/VREDUCESH Special Cases
Input value
Round Mode
Returned Value
|Src1| < 2-M-1
RNE
Src1
RU, Src1 > 0
Round(Src1 - 2-M)1
RU, Src1 ≤ 0
Src1
|Src1| < 2-M
RD, Src1 ≥ 0
Src1
RD, Src1 < 0
Round(Src1 + 2-M)
NOT RD
+0.0
Src1 = ±0 or
Dest = ±0 (Src1 ≠ ∞)
RD
-0.0
Src1 = ±∞
Any
+0.0
Src1 = ±NAN
Any
QNaN (Src1)
NOTES:
1. The Round(.) function uses rounding controls specified by (imm8[2]? MXCSR.RC: imm8[1:0]).
Operation
def reduce_fp16(src, imm8):
nan := (src.exp = 0x1F) and (src.fraction != 0)
if nan:
return QNAN(src)
m := imm8[7:4]
rc := imm8[1:0]
rc_source := imm8[2]
spe := imm[3] // suppress precision exception
tmp := 2^(-m) * ROUND(2^m * src, spe, rc_source, rc)
tmp := src - tmp // using same RC, SPE controls
return tmp
VREDUCEPH dest{k1}, src, imm8
VL = 128, 256 or 512
KL := VL/16
FOR i := 0 to KL-1:
IF k1[i] or *no writemask*:
IF SRC is memory and (EVEX.b = 1):
tsrc := src.fp16[0]
ELSE:
tsrc := src.fp16[i]
DEST.fp16[i] := reduce_fp16(tsrc, imm8)
ELSE IF *zeroing*:
DEST.fp16[i] := 0
//else DEST.fp16[i] remains unchanged
DEST[MAXVL-1:VL] := 0
VREDUCEPH-Perform Reduction Transformation on Packed FP16 Values
Vol. 2C
5-689
Intel C/C++ Compiler Intrinsic Equivalent
VREDUCEPH __m128h _mm_mask_reduce_ph (__m128h src, __mmask8 k, __m128h a, int imm8);
VREDUCEPH __m128h _mm_maskz_reduce_ph (__mmask8 k, __m128h a, int imm8);
VREDUCEPH __m128h _mm_reduce_ph (__m128h a, int imm8);
VREDUCEPH __m256h _mm256_mask_reduce_ph (__m256h src, __mmask16 k, __m256h a, int imm8);
VREDUCEPH __m256h _mm256_maskz_reduce_ph (__mmask16 k, __m256h a, int imm8);
VREDUCEPH __m256h _mm256_reduce_ph (__m256h a, int imm8);
VREDUCEPH __m512h _mm512_mask_reduce_ph (__m512h src, __mmask32 k, __m512h a, int imm8);
VREDUCEPH __m512h _mm512_maskz_reduce_ph (__mmask32 k, __m512h a, int imm8);
VREDUCEPH __m512h _mm512_reduce_ph (__m512h a, int imm8);
VREDUCEPH __m512h _mm512_mask_reduce_round_ph (__m512h src, __mmask32 k, __m512h a, int imm8, const int sae);
VREDUCEPH __m512h _mm512_maskz_reduce_round_ph (__mmask32 k, __m512h a, int imm8, const int sae);
VREDUCEPH __m512h _mm512_reduce_round_ph (__m512h a, int imm8, const int sae);
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
EVEX-encoded instruction, see Table 2-48, “Type E2 Class Exception Conditions.”
VREDUCEPH-Perform Reduction Transformation on Packed FP16 Values
Vol. 2C
5-690
VREDUCEPS-Perform Reduction Transformation on Packed Float32 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 56 /r ib
A
V/V
(AVX512VL
Perform reduction transformation on packed single-
VREDUCEPS xmm1 {k1}{z},
AND AVX512DQ)
precision floating-point values in
xmm2/m128/m32bcst, imm8
OR AVX10.1
xmm2/m128/m32bcst by subtracting a number of
fraction bits specified by the imm8 field. Stores the
result in xmm1 register under writemask k1.
EVEX.256.66.0F3A.W0 56 /r ib
A
V/V
(AVX512VL
Perform reduction transformation on packed single-
VREDUCEPS ymm1 {k1}{z},
AND AVX512DQ)
precision floating-point values in
ymm2/m256/m32bcst, imm8
OR AVX10.1
ymm2/m256/m32bcst by subtracting a number of
fraction bits specified by the imm8 field. Stores the
result in ymm1 register under writemask k1.
EVEX.512.66.0F3A.W0 56 /r ib
A
V/V
AVX512DQ
Perform reduction transformation on packed single-
VREDUCEPS zmm1 {k1}{z},
OR AVX10.1
precision floating-point values in
zmm2/m512/m32bcst{sae},
zmm2/m512/m32bcst by subtracting a number of
imm8
fraction bits specified by the imm8 field. Stores the
result in zmm1 register under writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8
N/A
Description
Perform reduction transformation of the packed binary encoded single precision floating-point values in the source
operand (the second operand) and store the reduced results in binary floating-point format to the destination
operand (the first operand) under the writemask k1.
The reduction transformation subtracts the integer part and the leading M fractional bits from the binary floating-
point source value, where M is a unsigned integer specified by imm8[7:4], see Figure 5-28. Specifically, the reduc-
tion transformation can be expressed as:
dest = src - (ROUND(2M*src))*2-M;
where “Round()” treats “src”, “2M”, and their product as binary floating-point numbers with normalized signifi-
cand and biased exponents.
The magnitude of the reduced result can be expressed by considering src= 2p*man2,
where ‘man2’ is the normalized significand and ‘p’ is the unbiased exponent
Then if RC = RNE: 0<=|Reduced Result|<=2p-M-1
Then if RC ≠ RNE: 0<=|Reduced Result|<2p-M
This instruction might end up with a precision exception set. However, in case of SPE set (i.e., Suppress Precision
Exception, which is imm8[3]=1), no precision exception is reported.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Handling of special case of input values are listed in Table 5-27.
VREDUCEPS-Perform Reduction Transformation on Packed Float32 Values
Vol. 2C
5-691
Operation
ReduceArgumentSP(SRC[31:0], imm8[7:0])
{
// Check for NaN
IF (SRC [31:0] = NAN) THEN
RETURN (Convert SRC[31:0] to QNaN); FI
M := imm8[7:4]; // Number of fraction bits of the normalized significand to be subtracted
RC := imm8[1:0];// Round Control for ROUND() operation
RC source := imm[2];
SPE := imm[3];// Suppress Precision Exception
TMP[31:0] := 2-M *{ROUND(2M*SRC[31:0], SPE, RC_source, RC)}; // ROUND() treats SRC and 2M as standard binary FP values
TMP[31:0] := SRC[31:0] - TMP[31:0]; // subtraction under the same RC,SPE controls
RETURN TMP[31:0]; // binary encoded FP with biased exponent and normalized significand
}
VREDUCEPS
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b == 1) AND (SRC *is memory*)
THEN DEST[i+31:i] := ReduceArgumentSP(SRC[31:0], imm8[7:0]);
ELSE DEST[i+31:i] := ReduceArgumentSP(SRC[i+31:i], imm8[7:0]);
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] = 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VREDUCEPS __m512 _mm512_mask_reduce_ps( __m512 a, int imm, int sae)
VREDUCEPS __m512 _mm512_mask_reduce_ps(__m512 s, __mmask16 k, __m512 a, int imm, int sae)
VREDUCEPS __m512 _mm512_maskz_reduce_ps(__mmask16 k, __m512 a, int imm, int sae)
VREDUCEPS __m256 _mm256_mask_reduce_ps( __m256 a, int imm)
VREDUCEPS __m256 _mm256_mask_reduce_ps(__m256 s, __mmask8 k, __m256 a, int imm)
VREDUCEPS __m256 _mm256_maskz_reduce_ps(__mmask8 k, __m256 a, int imm)
VREDUCEPS __m128 _mm_mask_reduce_ps( __m128 a, int imm)
VREDUCEPS __m128 _mm_mask_reduce_ps(__m128 s, __mmask8 k, __m128 a, int imm)
VREDUCEPS __m128 _mm_maskz_reduce_ps(__mmask8 k, __m128 a, int imm)
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
See Table 2-48, “Type E2 Class Exception Conditions”; additionally:
#UD
If EVEX.vvvv != 1111B.
VREDUCEPS-Perform Reduction Transformation on Packed Float32 Values
Vol. 2C
5-692
VREDUCESD-Perform a Reduction Transformation on a Scalar Float64 Value
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
EVEX.LLIG.66.0F3A.W1 57
A
V/V
AVX512DQ
Perform a reduction transformation on a scalar double
VREDUCESD xmm1 {k1}{z},
OR AVX10.1
precision floating-point value in xmm3/m64 by
xmm2, xmm3/m64{sae},
subtracting a number of fraction bits specified by the
imm8/r
imm8 field. Also, upper double precision floating-point
value (bits[127:64]) from xmm2 are copied to
xmm1[127:64]. Stores the result in xmm1 register.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Perform a reduction transformation of the binary encoded double precision floating-point value in the low qword
element of the second source operand (the third operand) and store the reduced result in binary floating-point
format to the low qword element of the destination operand (the first operand) under the writemask k1. Bits
127:64 of the destination operand are copied from respective qword elements of the first source operand (the
second operand).
The reduction transformation subtracts the integer part and the leading M fractional bits from the binary floating-
point source value, where M is a unsigned integer specified by imm8[7:4], see Figure 5-28. Specifically, the reduc-
tion transformation can be expressed as:
dest = src - (ROUND(2M*src))*2-M;
where “Round()” treats “src”, “2M”, and their product as binary floating-point numbers with normalized signifi-
cand and biased exponents.
The magnitude of the reduced result can be expressed by considering src= 2p*man2,
where ‘man2’ is the normalized significand and ‘p’ is the unbiased exponent
Then if RC = RNE: 0<=|Reduced Result|<=2p-M-1
Then if RC ≠ RNE: 0<=|Reduced Result|<2p-M
This instruction might end up with a precision exception set. However, in case of SPE set (i.e., Suppress Precision
Exception, which is imm8[3]=1), no precision exception is reported.
The operation is write masked.
Handling of special case of input values are listed in Table 5-27.
VREDUCESD-Perform a Reduction Transformation on a Scalar Float64 Value
Vol. 2C
5-693
Operation
ReduceArgumentDP(SRC[63:0], imm8[7:0])
{
// Check for NaN
IF (SRC [63:0] = NAN) THEN
RETURN (Convert SRC[63:0] to QNaN); FI;
M := imm8[7:4]; // Number of fraction bits of the normalized significand to be subtracted
RC := imm8[1:0];// Round Control for ROUND() operation
RC source := imm[2];
SPE := imm[3];// Suppress Precision Exception
TMP[63:0] := 2-M *{ROUND(2M*SRC[63:0], SPE, RC_source, RC)}; // ROUND() treats SRC and 2M as standard binary FP values
TMP[63:0] := SRC[63:0] - TMP[63:0]; // subtraction under the same RC,SPE controls
RETURN TMP[63:0]; // binary encoded FP with biased exponent and normalized significand
}
VREDUCESD
IF k1[0] or *no writemask*
THEN
DEST[63:0] := ReduceArgumentDP(SRC2[63:0], imm8[7:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] = 0
FI;
FI;
DEST[127:64] := SRC1[127:64]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VREDUCESD __m128d _mm_mask_reduce_sd( __m128d a, __m128d b, int imm, int sae)
VREDUCESD __m128d _mm_mask_reduce_sd(__m128d s, __mmask16 k, __m128d a, __m128d b, int imm, int sae)
VREDUCESD __m128d _mm_maskz_reduce_sd(__mmask16 k, __m128d a, __m128d b, int imm, int sae)
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
See Table 2-49, “Type E3 Class Exception Conditions.”
VREDUCESD-Perform a Reduction Transformation on a Scalar Float64 Value
Vol. 2C
5-694
VREDUCESH-Perform Reduction Transformation on Scalar FP16 Value
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.LLIG.NP.0F3A.W0 57 /r /ib
A
V/V
AVX512_FP16
Perform a reduction transformation on the low
VREDUCESH xmm1{k1}{z}, xmm2,
OR AVX10.1
binary encoded FP16 value in xmm3/m16 by
xmm3/m16 {sae}, imm8
subtracting a number of fraction bits specified by
the imm8 field. Store the result in xmm1 subject
to writemask k1. Bits 127:16 from xmm2 are
copied to xmm1[127:16].
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Scalar
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8 (r)
Description
This instruction performs a reduction transformation of the low binary encoded FP16 value in the source operand
(the second operand) and store the reduced result in binary FP format to the low element of the destination
operand (the first operand) under the writemask k1. For further details see the description of VREDUCEPH.
Bits 127:16 of the destination operand are copied from the corresponding bits of the first source operand. Bits
MAXVL-1:128 of the destination operand are zeroed. The low FP16 element of the destination is updated according
to the writemask.
This instruction might end up with a precision exception set. However, in case of SPE set (i.e., Suppress Precision
Exception, which is imm8[3]=1), no precision exception is reported.
This instruction may generate tiny non-zero result. If it does so, it does not report underflow exception, even if
underflow exceptions are unmasked (UM flag in MXCSR register is 0).
For special cases, see Table 5-28.
Operation
VREDUCESH dest{k1}, src, imm8
IF k1[0] or *no writemask*:
dest.fp16[0] := reduce_fp16(src2.fp16[0], imm8)
// see VREDUCEPH
ELSE IF *zeroing*:
dest.fp16[0] := 0
//else dest.fp16[0] remains unchanged
DEST[127:16] := src1[127:16]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VREDUCESH __m128h _mm_mask_reduce_round_sh (__m128h src, __mmask8 k, __m128h a, __m128h b, int imm8, const int sae);
VREDUCESH __m128h _mm_maskz_reduce_round_sh (__mmask8 k, __m128h a, __m128h b, int imm8, const int sae);
VREDUCESH __m128h _mm_reduce_round_sh (__m128h a, __m128h b, int imm8, const int sae);
VREDUCESH __m128h _mm_mask_reduce_sh (__m128h src, __mmask8 k, __m128h a, __m128h b, int imm8);
VREDUCESH __m128h _mm_maskz_reduce_sh (__mmask8 k, __m128h a, __m128h b, int imm8);
VREDUCESH __m128h _mm_reduce_sh (__m128h a, __m128h b, int imm8);
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
VREDUCESH-Perform Reduction Transformation on Scalar FP16 Value
Vol. 2C
5-695
Other Exceptions
EVEX-encoded instructions, see Table 2-49, “Type E3 Class Exception Conditions.”
VREDUCESH-Perform Reduction Transformation on Scalar FP16 Value
Vol. 2C
5-696
VREDUCESS-Perform a Reduction Transformation on a Scalar Float32 Value
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.LLIG.66.0F3A.W0 57 /r /ib
A
V/V
AVX512DQ
Perform a reduction transformation on a scalar single-
VREDUCESS xmm1 {k1}{z},
OR AVX10.1
precision floating-point value in xmm3/m32 by
xmm2, xmm3/m32{sae}, imm8
subtracting a number of fraction bits specified by the
imm8 field. Also, upper single-precision floating-point
values (bits[127:32]) from xmm2 are copied to
xmm1[127:32]. Stores the result in xmm1 register.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Perform a reduction transformation of the binary encoded single precision floating-point value in the low dword
element of the second source operand (the third operand) and store the reduced result in binary floating-point
format to the low dword element of the destination operand (the first operand) under the writemask k1. Bits
127:32 of the destination operand are copied from respective dword elements of the first source operand (the
second operand).
The reduction transformation subtracts the integer part and the leading M fractional bits from the binary floating-
point source value, where M is a unsigned integer specified by imm8[7:4], see Figure 5-28. Specifically, the reduc-
tion transformation can be expressed as:
dest = src - (ROUND(2M*src))*2-M;
where “Round()” treats “src”, “2M”, and their product as binary floating-point numbers with normalized signifi-
cand and biased exponents.
The magnitude of the reduced result can be expressed by considering src= 2p*man2,
where ‘man2’ is the normalized significand and ‘p’ is the unbiased exponent
Then if RC = RNE: 0<=|Reduced Result|<=2p-M-1
Then if RC ≠ RNE: 0<=|Reduced Result|<2p-M
This instruction might end up with a precision exception set. However, in case of SPE set (i.e., Suppress Precision
Exception, which is imm8[3]=1), no precision exception is reported.
Handling of special case of input values are listed in Table 5-27.
VREDUCESS-Perform a Reduction Transformation on a Scalar Float32 Value
Vol. 2C
5-697
Operation
ReduceArgumentSP(SRC[31:0], imm8[7:0])
{
// Check for NaN
IF (SRC [31:0] = NAN) THEN
RETURN (Convert SRC[31:0] to QNaN); FI
M := imm8[7:4]; // Number of fraction bits of the normalized significand to be subtracted
RC := imm8[1:0];// Round Control for ROUND() operation
RC source := imm[2];
SPE := imm[3];// Suppress Precision Exception
TMP[31:0] := 2-M *{ROUND(2M*SRC[31:0], SPE, RC_source, RC)}; // ROUND() treats SRC and 2M as standard binary FP values
TMP[31:0] := SRC[31:0] - TMP[31:0]; // subtraction under the same RC,SPE controls
RETURN TMP[31:0]; // binary encoded FP with biased exponent and normalized significand
}
VREDUCESS
IF k1[0] or *no writemask*
THEN
DEST[31:0] := ReduceArgumentSP(SRC2[31:0], imm8[7:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] = 0
FI;
FI;
DEST[127:32] := SRC1[127:32]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VREDUCESS __m128 _mm_mask_reduce_ss( __m128 a, __m128 b, int imm, int sae)
VREDUCESS __m128 _mm_mask_reduce_ss(__m128 s, __mmask16 k, __m128 a, __m128 b, int imm, int sae)
VREDUCESS __m128 _mm_maskz_reduce_ss(__mmask16 k, __m128 a, __m128 b, int imm, int sae)
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
See Table 2-49, “Type E3 Class Exception Conditions.”
VREDUCESS-Perform a Reduction Transformation on a Scalar Float32 Value
Vol. 2C
5-698

VRNDSCALEPD-Round Packed Float64 Values to Include a Given Number of Fraction Bits
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W1 09 /r ib
A
V/V
(AVX512VL
Rounds packed double precision floating-point values
VRNDSCALEPD xmm1 {k1}{z},
AND AVX512F)
in xmm2/m128/m64bcst to a number of fraction bits
xmm2/m128/m64bcst, imm8
OR AVX10.1
specified by the imm8 field. Stores the result in xmm1
register. Under writemask.
EVEX.256.66.0F3A.W1 09 /r ib
A
V/V
(AVX512VL
Rounds packed double precision floating-point values
VRNDSCALEPD ymm1 {k1}{z},
AND AVX512F)
in ymm2/m256/m64bcst to a number of fraction bits
ymm2/m256/m64bcst, imm8
OR AVX10.1
specified by the imm8 field. Stores the result in ymm1
register. Under writemask.
EVEX.512.66.0F3A.W1 09 /r ib
A
V/V
AVX512F
Rounds packed double precision floating-point values
VRNDSCALEPD zmm1 {k1}{z},
OR AVX10.1
in zmm2/m512/m64bcst to a number of fraction bits
zmm2/m512/m64bcst{sae}, imm8
specified by the imm8 field. Stores the result in zmm1
register using writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8
N/A
Description
Round the double precision floating-point values in the source operand by the rounding mode specified in the
immediate operand (see Figure 5-29) and places the result in the destination operand.
The destination operand (the first operand) is a ZMM/YMM/XMM register conditionally updated according to the
writemask. The source operand (the second operand) can be a ZMM/YMM/XMM register, a 512/256/128-bit
memory location, or a 512/256/128-bit vector broadcasted from a 64-bit memory location.
The rounding process rounds the input to an integral value, plus number bits of fraction that are specified by
imm8[7:4] (to be included in the result) and returns the result as a double precision floating-point value.
It should be noticed that no overflow is induced while executing this instruction (although the source is scaled by
the imm8[7:4] value).
The immediate operand also specifies control fields for the rounding operation, three bit fields are defined and
shown in the “Immediate Control Description” figure below. Bit 3 of the immediate byte controls the processor
behavior for a precision exception, bit 2 selects the source of rounding mode control. Bits 1:0 specify a non-sticky
rounding-mode value (immediate control table below lists the encoded values for rounding-mode field).
The Precision Floating-Point Exception is signaled according to the immediate operand. If any source operand is an
SNaN then it will be converted to a QNaN. If DAZ is set to ‘1 then denormals will be converted to zero before
rounding.
The sign of the result of this instruction is preserved, including the sign of zero.
The formula of the operation on each data element for VRNDSCALEPD is
ROUND(x) = 2-M*Round_to_INT(x*2M, round_ctrl),
round_ctrl = imm[3:0];
M=imm[7:4];
The operation of x*2M is computed as if the exponent range is unlimited (i.e., no overflow ever occurs).
VRNDSCALEPD-Round Packed Float64 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-699
VRNDSCALEPD is a more general form of the VEX-encoded VROUNDPD instruction. In VROUNDPD, the formula of
the operation on each element is
ROUND(x) = Round_to_INT(x, round_ctrl),
round_ctrl = imm[3:0];
Note: EVEX.vvvv is reserved and must be 1111b, otherwise instructions will #UD.
7
6
5
4
3
2
1
0
imm8
Fixed point length
SPE
RS
Round Control Override
Suppress Precision Exception: Imm8[3]
Imm8[1:0] = 00b : Round nearest even
Imm8[3] = 0b : Use MXCSR exception mask
Round Select: Imm8[2]
Imm8[7:4] : Number of fixed points to preserve
Imm8[1:0] = 01b : Round down
Imm8[3] = 1b : Suppress
Imm8[2] = 0b : Use Imm8[1:0]
Imm8[1:0] = 10b : Round up
Imm8[2] = 1b : Use MXCSR
Imm8[1:0] = 11b : Truncate
Figure 5-29. Imm8 Controls for VRNDSCALEPD/SD/PS/SS
Handling of special case of input values are listed in Table 5-29.
Table 5-29. VRNDSCALEPD/SD/PS/SS Special Cases
Returned value
Src1=±inf
Src1
Src1=±NAN
Src1 converted to QNAN
Src1=±0
Src1
Operation
RoundToIntegerDP(SRC[63:0], imm8[7:0]) {
if (imm8[2] = 1)
rounding_direction := MXCSR:RC
; get round control from MXCSR
else
rounding_direction := imm8[1:0]
; get round control from imm8[1:0]
FI
M := imm8[7:4]
; get the scaling factor
case (rounding_direction)
00: TMP[63:0] := round_to_nearest_even_integer(2M*SRC[63:0])
01: TMP[63:0] := round_to_equal_or_smaller_integer(2M*SRC[63:0])
10: TMP[63:0] := round_to_equal_or_larger_integer(2M*SRC[63:0])
11: TMP[63:0] := round_to_nearest_smallest_magnitude_integer(2M*SRC[63:0])
ESAC
Dest[63:0] := 2-M* TMP[63:0]
; scale down back to 2-M
if (imm8[3] = 0) Then
; check SPE
if (SRC[63:0] != Dest[63:0]) Then
; check precision lost
set_precision()
; set #PE
FI;
FI;
VRNDSCALEPD-Round Packed Float64 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-700
return(Dest[63:0])
}
VRNDSCALEPD (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF *src is a memory operand*
THEN TMP_SRC := BROADCAST64(SRC, VL, k1)
ELSE TMP_SRC := SRC
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := RoundToIntegerDP((TMP_SRC[i+63:i], imm8[7:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VRNDSCALEPD __m512d _mm512_roundscale_pd( __m512d a, int imm);
VRNDSCALEPD __m512d _mm512_roundscale_round_pd( __m512d a, int imm, int sae);
VRNDSCALEPD __m512d _mm512_mask_roundscale_pd(__m512d s, __mmask8 k, __m512d a, int imm);
VRNDSCALEPD __m512d _mm512_mask_roundscale_round_pd(__m512d s, __mmask8 k, __m512d a, int imm, int sae);
VRNDSCALEPD __m512d _mm512_maskz_roundscale_pd( __mmask8 k, __m512d a, int imm);
VRNDSCALEPD __m512d _mm512_maskz_roundscale_round_pd( __mmask8 k, __m512d a, int imm, int sae);
VRNDSCALEPD __m256d _mm256_roundscale_pd( __m256d a, int imm);
VRNDSCALEPD __m256d _mm256_mask_roundscale_pd(__m256d s, __mmask8 k, __m256d a, int imm);
VRNDSCALEPD __m256d _mm256_maskz_roundscale_pd( __mmask8 k, __m256d a, int imm);
VRNDSCALEPD __m128d _mm_roundscale_pd( __m128d a, int imm);
VRNDSCALEPD __m128d _mm_mask_roundscale_pd(__m128d s, __mmask8 k, __m128d a, int imm);
VRNDSCALEPD __m128d _mm_maskz_roundscale_pd( __mmask8 k, __m128d a, int imm);
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
See Table 2-48, “Type E2 Class Exception Conditions.”
VRNDSCALEPD-Round Packed Float64 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-701

VRNDSCALEPH-Round Packed FP16 Values to Include a Given Number of Fraction Bits
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.NP.0F3A.W0 08 /r /ib
A
V/V
(AVX512_FP16
Round packed FP16 values in
VRNDSCALEPH xmm1{k1}{z},
AND AVX512VL)
xmm2/m128/m16bcst to a number of fraction
xmm2/m128/m16bcst, imm8
OR AVX10.1
bits specified by the imm8 field. Store the result
in xmm1 subject to writemask k1.
EVEX.256.NP.0F3A.W0 08 /r /ib
A
V/V
(AVX512_FP16
Round packed FP16 values in
VRNDSCALEPH ymm1{k1}{z},
AND AVX512VL)
ymm2/m256/m16bcst to a number of fraction
ymm2/m256/m16bcst, imm8
OR AVX10.1
bits specified by the imm8 field. Store the result
in ymm1 subject to writemask k1.
EVEX.512.NP.0F3A.W0 08 /r /ib
A
V/V
AVX512_FP16
Round packed FP16 values in
VRNDSCALEPH zmm1{k1}{z},
OR AVX10.1
zmm2/m512/m16bcst to a number of fraction
zmm2/m512/m16bcst {sae}, imm8
bits specified by the imm8 field. Store the result
in zmm1 subject to writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8 (r)
N/A
Description
This instruction rounds the FP16 values in the source operand by the rounding mode specified in the immediate
operand (see Table 5-30) and places the result in the destination operand. The destination operand is conditionally
updated according to the writemask.
The rounding process rounds the input to an integral value, plus number bits of fraction that are specified by
imm8[7:4] (to be included in the result), and returns the result as an FP16 value.
Note that no overflow is induced while executing this instruction (although the source is scaled by the imm8[7:4]
value).
The immediate operand also specifies control fields for the rounding operation. Three bit fields are defined and
shown in Table 5-30, “Imm8 Controls for VRNDSCALEPH/VRNDSCALESH.” Bit 3 of the immediate byte controls the
processor behavior for a precision exception, bit 2 selects the source of rounding mode control, and bits 1:0 specify
a non-sticky rounding-mode value.
The Precision Floating-Point Exception is signaled according to the immediate operand. If any source operand is an
SNaN then it will be converted to a QNaN.
The sign of the result of this instruction is preserved, including the sign of zero. Special cases are described in Table
5-31.
The formula of the operation on each data element for VRNDSCALEPH is
ROUND(x) = 2-M *Round_to_INT(x * 2M, round_ctrl),
round_ctrl = imm[3:0];
M=imm[7:4];
The operation of x * 2M is computed as if the exponent range is unlimited (i.e., no overflow ever occurs).
If this instruction encoding’s SPE bit (bit 3) in the immediate operand is 1, VRNDSCALEPH can set MXCSR.UE
without MXCSR.PE.
EVEX.vvvv is reserved and must be 1111b, otherwise instructions will #UD.
VRNDSCALEPH-Round Packed FP16 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-702

Table 5-30. Imm8 Controls for VRNDSCALEPH/VRNDSCALESH
Imm8 Bits
Description
imm8[7:4]
Number of fixed points to preserve.
imm8[3]
Suppress Precision Exception (SPE)
0b00: Implies use of MXCSR exception mask.
0b01: Implies suppress.
imm8[2]
Round Select (RS)
0b00: Implies use of imm8[1:0].
0b01: Implies use of MXCSR.
imm8[1:0]
Round Control Override:
0b00: Round nearest even.
0b01: Round down.
0b10: Round up.
0b11: Truncate.
Table 5-31. VRNDSCALEPH/VRNDSCALESH Special Cases
Input Value
Returned Value
Src1 = ±∞
Src1
Src1 = ±NaN
Src1 converted to QNaN
Src1 = ±0
Src1
Operation
def round_fp16_to_integer(src, imm8):
if imm8[2] = 1:
rounding_direction := MXCSR.RC
else:
rounding_direction := imm8[1:0]
m := imm8[7:4] // scaling factor
tsrc1 := 2^m * src
if rounding_direction = 0b00:
tmp := round_to_nearest_even_integer(trc1)
else if rounding_direction = 0b01:
tmp := round_to_equal_or_smaller_integer(trc1)
else if rounding_direction = 0b10:
tmp := round_to_equal_or_larger_integer(trc1)
else if rounding_direction = 0b11:
tmp := round_to_smallest_magnitude_integer(trc1)
dst := 2^(-m) * tmp
if imm8[3]==0: // check SPE
if src != dst:
MXCSR.PE := 1
return dst
VRNDSCALEPH-Round Packed FP16 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-703
VRNDSCALEPH dest{k1}, src, imm8
VL = 128, 256 or 512
KL := VL/16
FOR i := 0 to KL-1:
IF k1[i] or *no writemask*:
IF SRC is memory and (EVEX.b = 1):
tsrc := src.fp16[0]
ELSE:
tsrc := src.fp16[i]
DEST.fp16[i] := round_fp16_to_integer(tsrc, imm8)
ELSE IF *zeroing*:
DEST.fp16[i] := 0
//else DEST.fp16[i] remains unchanged
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VRNDSCALEPH __m128h _mm_mask_roundscale_ph (__m128h src, __mmask8 k, __m128h a, int imm8);
VRNDSCALEPH __m128h _mm_maskz_roundscale_ph (__mmask8 k, __m128h a, int imm8);
VRNDSCALEPH __m128h _mm_roundscale_ph (__m128h a, int imm8);
VRNDSCALEPH __m256h _mm256_mask_roundscale_ph (__m256h src, __mmask16 k, __m256h a, int imm8);
VRNDSCALEPH __m256h _mm256_maskz_roundscale_ph (__mmask16 k, __m256h a, int imm8);
VRNDSCALEPH __m256h _mm256_roundscale_ph (__m256h a, int imm8);
VRNDSCALEPH __m512h _mm512_mask_roundscale_ph (__m512h src, __mmask32 k, __m512h a, int imm8);
VRNDSCALEPH __m512h _mm512_maskz_roundscale_ph (__mmask32 k, __m512h a, int imm8);
VRNDSCALEPH __m512h _mm512_roundscale_ph (__m512h a, int imm8);
VRNDSCALEPH __m512h _mm512_mask_roundscale_round_ph (__m512h src, __mmask32 k, __m512h a, int imm8, const int sae);
VRNDSCALEPH __m512h _mm512_maskz_roundscale_round_ph (__mmask32 k, __m512h a, int imm8, const int sae);
VRNDSCALEPH __m512h _mm512_roundscale_round_ph (__m512h a, int imm8, const int sae);
SIMD Floating-Point Exceptions
Invalid, Underflow, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
EVEX-encoded instruction, see Table 2-48, “Type E2 Class Exception Conditions.”
VRNDSCALEPH-Round Packed FP16 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-704

VRNDSCALEPS-Round Packed Float32 Values to Include a Given Number of Fraction Bits
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 08 /r ib
A
V/V
(AVX512VL
Rounds packed single-precision floating-point values
VRNDSCALEPS xmm1 {k1}{z},
AND AVX512F)
in xmm2/m128/m32bcst to a number of fraction bits
xmm2/m128/m32bcst, imm8
OR AVX10.1
specified by the imm8 field. Stores the result in xmm1
register. Under writemask.
EVEX.256.66.0F3A.W0 08 /r ib
A
V/V
(AVX512VL
Rounds packed single-precision floating-point values
VRNDSCALEPS ymm1 {k1}{z},
AND AVX512F)
in ymm2/m256/m32bcst to a number of fraction bits
ymm2/m256/m32bcst, imm8
OR AVX10.1
specified by the imm8 field. Stores the result in ymm1
register. Under writemask.
EVEX.512.66.0F3A.W0 08 /r ib
A
V/V
AVX512F
Rounds packed single-precision floating-point values
VRNDSCALEPS zmm1 {k1}{z},
OR AVX10.1
in zmm2/m512/m32bcst to a number of fraction bits
zmm2/m512/m32bcst{sae}, imm8
specified by the imm8 field. Stores the result in zmm1
register using writemask.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8
N/A
Description
Round the single precision floating-point values in the source operand by the rounding mode specified in the imme-
diate operand (see Figure 5-29) and places the result in the destination operand.
The destination operand (the first operand) is a ZMM register conditionally updated according to the writemask.
The source operand (the second operand) can be a ZMM register, a 512-bit memory location, or a 512-bit vector
broadcasted from a 32-bit memory location.
The rounding process rounds the input to an integral value, plus number bits of fraction that are specified by
imm8[7:4] (to be included in the result) and returns the result as a single precision floating-point value.
It should be noticed that no overflow is induced while executing this instruction (although the source is scaled by
the imm8[7:4] value).
The immediate operand also specifies control fields for the rounding operation, three bit fields are defined and
shown in the “Immediate Control Description” figure below. Bit 3 of the immediate byte controls the processor
behavior for a precision exception, bit 2 selects the source of rounding mode control. Bits 1:0 specify a non-sticky
rounding-mode value (immediate control table below lists the encoded values for rounding-mode field).
The Precision Floating-Point Exception is signaled according to the immediate operand. If any source operand is an
SNaN then it will be converted to a QNaN. If DAZ is set to ‘1 then denormals will be converted to zero before
rounding.
The sign of the result of this instruction is preserved, including the sign of zero.
The formula of the operation on each data element for VRNDSCALEPS is
ROUND(x) = 2-M*Round_to_INT(x*2M, round_ctrl),
round_ctrl = imm[3:0];
M=imm[7:4];
The operation of x*2M is computed as if the exponent range is unlimited (i.e., no overflow ever occurs).
VRNDSCALEPS is a more general form of the VEX-encoded VROUNDPS instruction. In VROUNDPS, the formula of
the operation on each element is
ROUND(x) = Round_to_INT(x, round_ctrl),
round_ctrl = imm[3:0];
VRNDSCALEPS-Round Packed Float32 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-705
Note: EVEX.vvvv is reserved and must be 1111b, otherwise instructions will #UD.
Handling of special case of input values are listed in Table 5-29.
Operation
RoundToIntegerSP(SRC[31:0], imm8[7:0]) {
if (imm8[2] = 1)
rounding_direction := MXCSR:RC
; get round control from MXCSR
else
rounding_direction := imm8[1:0]
; get round control from imm8[1:0]
FI
M := imm8[7:4]
; get the scaling factor
case (rounding_direction)
00: TMP[31:0] := round_to_nearest_even_integer(2M*SRC[31:0])
01: TMP[31:0] := round_to_equal_or_smaller_integer(2M*SRC[31:0])
10: TMP[31:0] := round_to_equal_or_larger_integer(2M*SRC[31:0])
11: TMP[31:0] := round_to_nearest_smallest_magnitude_integer(2M*SRC[31:0])
ESAC;
Dest[31:0] := 2-M* TMP[31:0]
; scale down back to 2-M
if (imm8[3] = 0) Then
; check SPE
if (SRC[31:0] != Dest[31:0]) Then
; check precision lost
set_precision()
; set #PE
FI;
FI;
return(Dest[31:0])
}
VRNDSCALEPS (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF *src is a memory operand*
THEN TMP_SRC := BROADCAST32(SRC, VL, k1)
ELSE TMP_SRC := SRC
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := RoundToIntegerSP(TMP_SRC[i+31:i]), imm8[7:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI;
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
VRNDSCALEPS-Round Packed Float32 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-706
Intel C/C++ Compiler Intrinsic Equivalent
VRNDSCALEPS __m512 _mm512_roundscale_ps( __m512 a, int imm);
VRNDSCALEPS __m512 _mm512_roundscale_round_ps( __m512 a, int imm, int sae);
VRNDSCALEPS __m512 _mm512_mask_roundscale_ps(__m512 s, __mmask16 k, __m512 a, int imm);
VRNDSCALEPS __m512 _mm512_mask_roundscale_round_ps(__m512 s, __mmask16 k, __m512 a, int imm, int sae);
VRNDSCALEPS __m512 _mm512_maskz_roundscale_ps( __mmask16 k, __m512 a, int imm);
VRNDSCALEPS __m512 _mm512_maskz_roundscale_round_ps( __mmask16 k, __m512 a, int imm, int sae);
VRNDSCALEPS __m256 _mm256_roundscale_ps( __m256 a, int imm);
VRNDSCALEPS __m256 _mm256_mask_roundscale_ps(__m256 s, __mmask8 k, __m256 a, int imm);
VRNDSCALEPS __m256 _mm256_maskz_roundscale_ps( __mmask8 k, __m256 a, int imm);
VRNDSCALEPS __m128 _mm_roundscale_ps( __m256 a, int imm);
VRNDSCALEPS __m128 _mm_mask_roundscale_ps(__m128 s, __mmask8 k, __m128 a, int imm);
VRNDSCALEPS __m128 _mm_maskz_roundscale_ps( __mmask8 k, __m128 a, int imm);
SIMD Floating-Point Exceptions
Invalid, Precision.
If SPE is enabled, precision exception is not reported (regardless of MXCSR exception mask).
Other Exceptions
See Table 2-48, “Type E2 Class Exception Conditions.”
VRNDSCALEPS-Round Packed Float32 Values to Include a Given Number of Fraction Bits
Vol. 2C
5-707