Intel 64 and IA-32 Architectures. Software Developer’s Manual (2026) - page 37

VMULSH-Multiply Scalar FP16 Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.LLIG.F3.MAP5.W0 59 /r
A
V/V
AVX512_FP16
Multiply the low FP16 value in xmm3/m16 by low
VMULSH xmm1{k1}{z}, xmm2,
OR AVX10.1
FP16 value in xmm2, and store the result in
xmm3/m16 {er}
xmm1 subject to writemask k1. Bits 127:16 of
xmm2 are copied to xmm1[127:16].
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Scalar
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
This instruction multiplies the low FP16 value from the source operands and stores the FP16 result in the destina-
tion operand. Bits 127:16 of the destination operand are copied from the corresponding bits of the first source
operand. Bits MAXVL-1:128 of the destination operand are zeroed. The low FP16 element of the destination is
updated according to the writemask.
Operation
VMULSH (EVEX encoded versions)
IF EVEX.b = 1 and SRC2 is a register:
SET_RM(EVEX.RC)
ELSE
SET_RM(MXCSR.RC)
IF k1[0] OR *no writemask*:
DEST.fp16[0] := SRC1.fp16[0] * SRC2.fp16[0]
ELSE IF *zeroing*:
DEST.fp16[0] := 0
// else dest.fp16[0] remains unchanged
DEST[127:16] := SRC1[127:16]
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VMULSH __m128h _mm_mask_mul_round_sh (__m128h src, __mmask8 k, __m128h a, __m128h b, int rounding);
VMULSH __m128h _mm_maskz_mul_round_sh (__mmask8 k, __m128h a, __m128h b, int rounding);
VMULSH __m128h _mm_mul_round_sh (__m128h a, __m128h b, int rounding);
VMULSH __m128h _mm_mask_mul_sh (__m128h src, __mmask8 k, __m128h a, __m128h b);
VMULSH __m128h _mm_maskz_mul_sh (__mmask8 k, __m128h a, __m128h b);
VMULSH __m128h _mm_mul_sh (__m128h a, __m128h b);
SIMD Floating-Point Exceptions
Invalid, Underflow, Overflow, Precision, Denormal.
Other Exceptions
EVEX-encoded instructions, see Table 2-49, “Type E3 Class Exception Conditions.”
VMULSH-Multiply Scalar FP16 Values
Vol. 2C
5-432

VP2INTERSECTD/VP2INTERSECTQ-Compute Intersection Between DWORDS/QUADWORDS to a
Pair of Mask Registers
Opcode/
Op/
64/32
CPUID Feature Flag
Description
Instruction
En
bit Mode
Support
EVEX.NDS.128.F2.0F38.W0 68 /r
A
V/V
AVX512VL
Store, in an even/odd pair of mask registers,
VP2INTERSECTD k1+1, xmm2,
AVX512_VP2INTERSECT
the indicators of the locations of value
xmm3/m128/m32bcst
matches between dwords in
xmm3/m128/m32bcst and xmm2.
EVEX.NDS.256.F2.0F38.W0 68 /r
A
V/V
AVX512VL
Store, in an even/odd pair of mask registers,
VP2INTERSECTD k1+1, ymm2,
AVX512_VP2INTERSECT
the indicators of the locations of value
ymm3/m256/m32bcst
matches between dwords in
ymm3/m256/m32bcst and ymm2.
EVEX.NDS.512.F2.0F38.W0 68 /r
A
V/V
AVX512F
Store, in an even/odd pair of mask registers,
VP2INTERSECTD k1+1, zmm2,
AVX512_VP2INTERSECT
the indicators of the locations of value
zmm3/m512/m32bcst
matches between dwords in
zmm3/m512/m32bcst and zmm2.
EVEX.NDS.128.F2.0F38.W1 68 /r
A
V/V
AVX512VL
Store, in an even/odd pair of mask registers,
VP2INTERSECTQ k1+1, xmm2,
AVX512_VP2INTERSECT
the indicators of the locations of value
xmm3/m128/m64bcst
matches between quadwords in
xmm3/m128/m64bcst and xmm2.
EVEX.NDS.256.F2.0F38.W1 68 /r
A
V/V
AVX512VL
Store, in an even/odd pair of mask registers,
VP2INTERSECTQ k1+1, ymm2,
AVX512_VP2INTERSECT
the indicators of the locations of value
ymm3/m256/m64bcst
matches between quadwords in
ymm3/m256/m64bcst and ymm2.
EVEX.NDS.512.F2.0F38.W1 68 /r
A
V/V
AVX512F
Store, in an even/odd pair of mask registers,
VP2INTERSECTQ k1+1, zmm2,
AVX512_VP2INTERSECT
the indicators of the locations of value
zmm3/m512/m64bcst
matches between quadwords in
zmm3/m512/m64bcst and zmm2.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
This instruction writes an even/odd pair of mask registers. The mask register destination indicated in the
MODRM.REG field is used to form the basis of the register pair. The low bit of that field is masked off (set to zero)
to create the first register of the pair.
EVEX.aaa and EVEX.z must be zero.
VP2INTERSECTD/VP2INTERSECTQ-Compute Intersection Between DWORDS/QUADWORDS to a Pair of Mask Registers
Vol. 2C
5-433
Operation
VP2INTERSECTD destmask, src1, src2
(KL, VL) = (4, 128), (8, 256), (16, 512)
// dest_mask_reg_id is the register id specified in the instruction for destmask
dest_base := dest_mask_reg_id & ~1
// maskregs[ ] is an array representing the mask registers
maskregs[dest_base+0][MAX_KL-1:0] := 0
maskregs[dest_base+1][MAX_KL-1:0] := 0
FOR i := 0 to KL-1:
FOR j := 0 to KL-1:
match := (src1.dword[i] == src2.dword[j])
maskregs[dest_base+0].bit[i] |= match
maskregs[dest_base+1].bit[j] |= match
VP2INTERSECTQ destmask, src1, src2
(KL, VL) = (2, 128), (4, 256), (8, 512)
// dest_mask_reg_id is the register id specified in the instruction for destmask
dest_base := dest_mask_reg_id & ~1
// maskregs[ ] is an array representing the mask registers
maskregs[dest_base+0][MAX_KL-1:0] := 0
maskregs[dest_base+1][MAX_KL-1:0] := 0
FOR i = 0 to KL-1:
FOR j = 0 to KL-1:
match := (src1.qword[i] == src2.qword[j])
maskregs[dest_base+0].bit[i] |= match
maskregs[dest_base+1].bit[j] |= match
Intel C/C++ Compiler Intrinsic Equivalent
VP2INTERSECTD void _mm_2intersect_epi32(__m128i, __m128i, __mmask8 *, __mmask8 *);
VP2INTERSECTD void _mm256_2intersect_epi32(__m256i, __m256i, __mmask8 *, __mmask8 *);
VP2INTERSECTD void _mm512_2intersect_epi32(__m512i, __m512i, __mmask16 *, __mmask16 *);
VP2INTERSECTQ void _mm_2intersect_epi64(__m128i, __m128i, __mmask8 *, __mmask8 *);
VP2INTERSECTQ void _mm256_2intersect_epi64(__m256i, __m256i, __mmask8 *, __mmask8 *);
VP2INTERSECTQ void _mm512_2intersect_epi64(__m512i, __m512i, __mmask8 *, __mmask8 *);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-52, “Type E4NF Class Exception Conditions.”
VP2INTERSECTD/VP2INTERSECTQ-Compute Intersection Between DWORDS/QUADWORDS to a Pair of Mask Registers
Vol. 2C
5-434

VPBLENDD-Blend Packed Dwords
Opcode/
Op/
64/32
CPUID
Description
Instruction
En
-bit
Feature
Mode
Flag
VEX.128.66.0F3A.W0 02 /r ib
RVMI
V/V
AVX2
Select dwords from xmm2 and xmm3/m128 from
VPBLENDD xmm1, xmm2, xmm3/m128, imm8
mask specified in imm8 and store the values into
xmm1.
VEX.256.66.0F3A.W0 02 /r ib
RVMI
V/V
AVX2
Select dwords from ymm2 and ymm3/m256 from
VPBLENDD ymm1, ymm2, ymm3/m256, imm8
mask specified in imm8 and store the values into
ymm1.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RVMI
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Dword elements from the source operand (second operand) are conditionally written to the destination operand
(first operand) depending on bits in the immediate operand (third operand). The immediate bits (bits 7:0) form a
mask that determines whether the corresponding dword in the destination is copied from the source. If a bit in the
mask, corresponding to a dword, is “1”, then the dword is copied, else the dword is unchanged.
VEX.128 encoded version: The second source operand can be an XMM register or a 128-bit memory location. The
first source and destination operands are XMM registers. Bits (MAXVL-1:128) of the corresponding YMM register
are zeroed.
VEX.256 encoded version: The first source operand is a YMM register. The second source operand is a YMM register
or a 256-bit memory location. The destination operand is a YMM register.
Operation
VPBLENDD (VEX.256 encoded version)
IF (imm8[0] == 1) THEN DEST[31:0] := SRC2[31:0]
ELSE DEST[31:0] := SRC1[31:0]
IF (imm8[1] == 1) THEN DEST[63:32] := SRC2[63:32]
ELSE DEST[63:32] := SRC1[63:32]
IF (imm8[2] == 1) THEN DEST[95:64] := SRC2[95:64]
ELSE DEST[95:64] := SRC1[95:64]
IF (imm8[3] == 1) THEN DEST[127:96] := SRC2[127:96]
ELSE DEST[127:96] := SRC1[127:96]
IF (imm8[4] == 1) THEN DEST[159:128] := SRC2[159:128]
ELSE DEST[159:128] := SRC1[159:128]
IF (imm8[5] == 1) THEN DEST[191:160] := SRC2[191:160]
ELSE DEST[191:160] := SRC1[191:160]
IF (imm8[6] == 1) THEN DEST[223:192] := SRC2[223:192]
ELSE DEST[223:192] := SRC1[223:192]
IF (imm8[7] == 1) THEN DEST[255:224] := SRC2[255:224]
ELSE DEST[255:224] := SRC1[255:224]
VPBLENDD-Blend Packed Dwords
Vol. 2C
5-435
VPBLENDD (VEX.128 encoded version)
IF (imm8[0] == 1) THEN DEST[31:0] := SRC2[31:0]
ELSE DEST[31:0] := SRC1[31:0]
IF (imm8[1] == 1) THEN DEST[63:32] := SRC2[63:32]
ELSE DEST[63:32] := SRC1[63:32]
IF (imm8[2] == 1) THEN DEST[95:64] := SRC2[95:64]
ELSE DEST[95:64] := SRC1[95:64]
IF (imm8[3] == 1) THEN DEST[127:96] := SRC2[127:96]
ELSE DEST[127:96] := SRC1[127:96]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPBLENDD:
__m128i _mm_blend_epi32 (__m128i v1, __m128i v2, const int mask)
VPBLENDD:
__m256i _mm256_blend_epi32 (__m256i v1, __m256i v2, const int mask)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-21, “Type 4 Class Exception Conditions.”
Additionally:
#UD
If VEX.W = 1.
VPBLENDD-Blend Packed Dwords
Vol. 2C
5-436

VPBLENDMB/VPBLENDMW-Blend Byte/Word Vectors Using an Opmask Control
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 66 /r
A
V/V
(AVX512VL AND
Blend byte integer vector xmm2 and byte vector
VPBLENDMB xmm1 {k1}{z},
AVX512BW) OR
xmm3/m128 and store the result in xmm1, under
xmm2, xmm3/m128
AVX10.1
control mask.
EVEX.256.66.0F38.W0 66 /r
A
V/V
(AVX512VL AND
Blend byte integer vector ymm2 and byte vector
VPBLENDMB ymm1 {k1}{z},
AVX512BW) OR
ymm3/m256 and store the result in ymm1, under
ymm2, ymm3/m256
AVX10.1
control mask.
EVEX.512.66.0F38.W0 66 /r
A
V/V
AVX512BW
Blend byte integer vector zmm2 and byte vector
VPBLENDMB zmm1 {k1}{z},
OR AVX10.1
zmm3/m512 and store the result in zmm1, under
zmm2, zmm3/m512
control mask.
EVEX.128.66.0F38.W1 66 /r
A
V/V
(AVX512VL AND
Blend word integer vector xmm2 and word vector
VPBLENDMW xmm1 {k1}{z},
AVX512BW) OR
xmm3/m128 and store the result in xmm1, under
xmm2, xmm3/m128
AVX10.1
control mask.
EVEX.256.66.0F38.W1 66 /r
A
V/V
(AVX512VL AND
Blend word integer vector ymm2 and word vector
VPBLENDMW ymm1 {k1}{z},
AVX512BW) OR
ymm3/m256 and store the result in ymm1, under
ymm2, ymm3/m256
AVX10.1
control mask.
EVEX.512.66.0F38.W1 66 /r
A
V/V
AVX512BW
Blend word integer vector zmm2 and word vector
VPBLENDMW zmm1 {k1}{z},
OR AVX10.1
zmm3/m512 and store the result in zmm1, under
zmm2, zmm3/m512
control mask.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs an element-by-element blending of byte/word elements between the first source operand byte vector
register and the second source operand byte vector from memory or register, using the instruction mask as
selector. The result is written into the destination byte vector register.
The destination and first source operands are ZMM/YMM/XMM registers. The second source operand can be a
ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512/256/128-bit memory location.
The mask is not used as a writemask for this instruction. Instead, the mask is used as an element selector: every
element of the destination is conditionally selected between first source or second source using the value of the
related mask bit (0 for first source, 1 for second source).
VPBLENDMB/VPBLENDMW-Blend Byte/Word Vectors Using an Opmask Control
Vol. 2C
5-437
Operation
VPBLENDMB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[i+7:i] := SRC2[i+7:i]
ELSE
IF *merging-masking*
; merging-masking
THEN DEST[i+7:i] := SRC1[i+7:i]
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI;
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0;
VPBLENDMW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SRC2[i+15:i]
ELSE
IF *merging-masking*
; merging-masking
THEN DEST[i+15:i] := SRC1[i+15:i]
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI;
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPBLENDMB __m512i _mm512_mask_blend_epi8(__mmask64 m, __m512i a, __m512i b);
VPBLENDMB __m256i _mm256_mask_blend_epi8(__mmask32 m, __m256i a, __m256i b);
VPBLENDMB __m128i _mm_mask_blend_epi8(__mmask16 m, __m128i a, __m128i b);
VPBLENDMW __m512i _mm512_mask_blend_epi16(__mmask32 m, __m512i a, __m512i b);
VPBLENDMW __m256i _mm256_mask_blend_epi16(__mmask16 m, __m256i a, __m256i b);
VPBLENDMW __m128i _mm_mask_blend_epi16(__mmask8 m, __m128i a, __m128i b);
SIMD Floating-Point Exceptions
None
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
VPBLENDMB/VPBLENDMW-Blend Byte/Word Vectors Using an Opmask Control
Vol. 2C
5-438

VPBLENDMD/VPBLENDMQ-Blend Int32/Int64 Vectors Using an OpMask Control
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 64 /r
A
V/V
(AVX512VL AND
Blend doubleword integer vector xmm2 and
VPBLENDMD xmm1 {k1}{z},
AVX512F) OR
doubleword vector xmm3/m128/m32bcst and
xmm2, xmm3/m128/m32bcst
AVX10.1
store the result in xmm1, under control mask.
EVEX.256.66.0F38.W0 64 /r
A
V/V
(AVX512VL AND
Blend doubleword integer vector ymm2 and
VPBLENDMD ymm1 {k1}{z}, ymm2,
AVX512F) OR
doubleword vector ymm3/m256/m32bcst and
ymm3/m256/m32bcst
AVX10.1
store the result in ymm1, under control mask.
EVEX.512.66.0F38.W0 64 /r
A
V/V
AVX512F
Blend doubleword integer vector zmm2 and
VPBLENDMD zmm1 {k1}{z}, zmm2,
OR AVX10.1
doubleword vector zmm3/m512/m32bcst and
zmm3/m512/m32bcst
store the result in zmm1, under control mask.
EVEX.128.66.0F38.W1 64 /r
A
V/V
(AVX512VL AND
Blend quadword integer vector xmm2 and
VPBLENDMQ xmm1 {k1}{z},
AVX512F) OR
quadword vector xmm3/m128/m64bcst and store
xmm2, xmm3/m128/m64bcst
AVX10.1
the result in xmm1, under control mask.
EVEX.256.66.0F38.W1 64 /r
A
V/V
(AVX512VL AND
Blend quadword integer vector ymm2 and
VPBLENDMQ ymm1 {k1}{z},
AVX512F) OR
quadword vector ymm3/m256/m64bcst and store
ymm2, ymm3/m256/m64bcst
AVX10.1
the result in ymm1, under control mask.
EVEX.512.66.0F38.W1 64 /r
A
V/V
AVX512F
Blend quadword integer vector zmm2 and
VPBLENDMQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
quadword vector zmm3/m512/m64bcst and store
zmm3/m512/m64bcst
the result in zmm1, under control mask.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs an element-by-element blending of dword/qword elements between the first source operand (the second
operand) and the elements of the second source operand (the third operand) using an opmask register as select
control. The blended result is written into the destination.
The destination and first source operands are ZMM/YMM/XMM registers. The second source operand can be a
ZMM/YMM/XMM register; a 512/256/128-bit memory location; or a 512/256/128-bit vector with 16/8/4 identical
values broadcast from a 32-bit memory location (VPBLENDMD) or 8/4/2 identical values broadcast from a 64-bit
memory location (VPBLENDMQ).
The opmask register is not used as a writemask for this instruction. Instead, the mask is used as an element
selector: every element of the destination is conditionally selected between first source or second source using the
value of the related mask bit (0 for the first source operand, 1 for the second source operand).
If EVEX.z is set, the elements with corresponding mask bit value of 0 in the destination operand are zeroed.
VPBLENDMD/VPBLENDMQ-Blend Int32/Int64 Vectors Using an OpMask Control
Vol. 2C
5-439
Operation
VPBLENDMD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no controlmask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
DEST[i+31:i] := SRC2[31:0]
ELSE
DEST[i+31:i] := SRC2[i+31:i]
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN DEST[i+31:i] := SRC1[i+31:i]
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI;
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0;
VPBLENDMQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no controlmask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
DEST[i+63i] := SRC2[63:0]
ELSE
DEST[i+63:i] := SRC2[i+63:i]
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN DEST[i+63:i] := SRC1[i+63:i]
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI;
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBLENDMD/VPBLENDMQ-Blend Int32/Int64 Vectors Using an OpMask Control
Vol. 2C
5-440
Intel C/C++ Compiler Intrinsic Equivalent
VPBLENDMD __m512i _mm512_mask_blend_epi32(__mmask16 k, __m512i a, __m512i b);
VPBLENDMD __m256i _mm256_mask_blend_epi32(__mmask8 m, __m256i a, __m256i b);
VPBLENDMD __m128i _mm_mask_blend_epi32(__mmask8 m, __m128i a, __m128i b);
VPBLENDMQ __m512i _mm512_mask_blend_epi64(__mmask8 k, __m512i a, __m512i b);
VPBLENDMQ __m256i _mm256_mask_blend_epi64(__mmask8 m, __m256i a, __m256i b);
VPBLENDMQ __m128i _mm_mask_blend_epi64(__mmask8 m, __m128i a, __m128i b);
SIMD Floating-Point Exceptions
None
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
VPBLENDMD/VPBLENDMQ-Blend Int32/Int64 Vectors Using an OpMask Control
Vol. 2C
5-441

VPBROADCAST-Load Integer and Broadcast
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 78 /r
A
V/V
AVX2
Broadcast a byte integer in the source
VPBROADCASTB xmm1, xmm2/m8
operand to sixteen locations in xmm1.
VEX.256.66.0F38.W0 78 /r
A
V/V
AVX2
Broadcast a byte integer in the source
VPBROADCASTB ymm1, xmm2/m8
operand to thirty-two locations in ymm1.
EVEX.128.66.0F38.W0 78 /r
B
V/V
(AVX512VL AND
Broadcast a byte integer in the source
VPBROADCASTB xmm1{k1}{z}, xmm2/m8
AVX512BW) OR
operand to locations in xmm1 subject to
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 78 /r
B
V/V
(AVX512VL AND
Broadcast a byte integer in the source
VPBROADCASTB ymm1{k1}{z}, xmm2/m8
AVX512BW) OR
operand to locations in ymm1 subject to
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 78 /r
B
V/V
AVX512BW
Broadcast a byte integer in the source
VPBROADCASTB zmm1{k1}{z}, xmm2/m8
OR AVX10.1
operand to 64 locations in zmm1 subject to
writemask k1.
VEX.128.66.0F38.W0 79 /r
A
V/V
AVX2
Broadcast a word integer in the source
VPBROADCASTW xmm1, xmm2/m16
operand to eight locations in xmm1.
VEX.256.66.0F38.W0 79 /r
A
V/V
AVX2
Broadcast a word integer in the source
VPBROADCASTW ymm1, xmm2/m16
operand to sixteen locations in ymm1.
EVEX.128.66.0F38.W0 79 /r
B
V/V
(AVX512VL AND
Broadcast a word integer in the source
VPBROADCASTW xmm1{k1}{z}, xmm2/m16
AVX512BW) OR
operand to locations in xmm1 subject to
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 79 /r
B
V/V
(AVX512VL AND
Broadcast a word integer in the source
VPBROADCASTW ymm1{k1}{z}, xmm2/m16
AVX512BW) OR
operand to locations in ymm1 subject to
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 79 /r
B
V/V
AVX512BW
Broadcast a word integer in the source
VPBROADCASTW zmm1{k1}{z}, xmm2/m16
OR AVX10.1
operand to 32 locations in zmm1 subject to
writemask k1.
VEX.128.66.0F38.W0 58 /r
A
V/V
AVX2
Broadcast a dword integer in the source
VPBROADCASTD xmm1, xmm2/m32
operand to four locations in xmm1.
VEX.256.66.0F38.W0 58 /r
A
V/V
AVX2
Broadcast a dword integer in the source
VPBROADCASTD ymm1, xmm2/m32
operand to eight locations in ymm1.
EVEX.128.66.0F38.W0 58 /r
B
V/V
(AVX512VL AND
Broadcast a dword integer in the source
VPBROADCASTD xmm1 {k1}{z}, xmm2/m32
AVX512F) OR
operand to locations in xmm1 subject to
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 58 /r
B
V/V
(AVX512VL AND
Broadcast a dword integer in the source
VPBROADCASTD ymm1 {k1}{z}, xmm2/m32
AVX512F) OR
operand to locations in ymm1 subject to
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 58 /r
B
V/V
AVX512F
Broadcast a dword integer in the source
VPBROADCASTD zmm1 {k1}{z}, xmm2/m32
OR AVX10.1
operand to locations in zmm1 subject to
writemask k1.
VEX.128.66.0F38.W0 59 /r
A
V/V
AVX2
Broadcast a qword element in source
VPBROADCASTQ xmm1, xmm2/m64
operand to two locations in xmm1.
VEX.256.66.0F38.W0 59 /r
A
V/V
AVX2
Broadcast a qword element in source
VPBROADCASTQ ymm1, xmm2/m64
operand to four locations in ymm1.
EVEX.128.66.0F38.W1 59 /r
B
V/V
(AVX512VL AND
Broadcast a qword element in source
VPBROADCASTQ xmm1 {k1}{z}, xmm2/m64
AVX512F) OR
operand to locations in xmm1 subject to
AVX10.1
writemask k1.
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-442

Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.256.66.0F38.W1 59 /r
B
V/V
(AVX512VL AND
Broadcast a qword element in source
VPBROADCASTQ ymm1 {k1}{z}, xmm2/m64
AVX512F) OR
operand to locations in ymm1 subject to
AVX10.1
writemask k1.
EVEX.512.66.0F38.W1 59 /r
B
V/V
AVX512F
Broadcast a qword element in source
VPBROADCASTQ zmm1 {k1}{z}, xmm2/m64
OR AVX10.1
operand to locations in zmm1 subject to
writemask k1.
EVEX.128.66.0F38.W0 59 /r
C
V/V
(AVX512VL AND
Broadcast two dword elements in source
VBROADCASTI32x2 xmm1 {k1}{z},
AVX512DQ) OR
operand to locations in xmm1 subject to
xmm2/m64
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 59 /r
C
V/V
(AVX512VL AND
Broadcast two dword elements in source
VBROADCASTI32x2 ymm1 {k1}{z},
AVX512DQ) OR
operand to locations in ymm1 subject to
xmm2/m64
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 59 /r
C
V/V
AVX512DQ
Broadcast two dword elements in source
VBROADCASTI32x2 zmm1 {k1}{z},
OR AVX10.1
operand to locations in zmm1 subject to
xmm2/m64
writemask k1.
VEX.256.66.0F38.W0 5A /r
A
V/V
AVX2
Broadcast 128 bits of integer data in mem
VBROADCASTI128 ymm1, m128
to low and high 128-bits in ymm1.
EVEX.256.66.0F38.W0 5A /r
D
V/V
(AVX512VL AND
Broadcast 128 bits of 4 doubleword integer
VBROADCASTI32X4 ymm1 {k1}{z}, m128
AVX512F) OR
data in mem to locations in ymm1 using
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 5A /r
D
V/V
AVX512F
Broadcast 128 bits of 4 doubleword integer
VBROADCASTI32X4 zmm1 {k1}{z}, m128
OR AVX10.1
data in mem to locations in zmm1 using
writemask k1.
EVEX.256.66.0F38.W1 5A /r
C
V/V
(AVX512VL AND
Broadcast 128 bits of 2 quadword integer
VBROADCASTI64X2 ymm1 {k1}{z}, m128
AVX512DQ) OR
data in mem to locations in ymm1 using
AVX10.1
writemask k1.
EVEX.512.66.0F38.W1 5A /r
C
V/V
AVX512DQ
Broadcast 128 bits of 2 quadword integer
VBROADCASTI64X2 zmm1 {k1}{z}, m128
OR AVX10.1
data in mem to locations in zmm1 using
writemask k1.
EVEX.512.66.0F38.W0 5B /r
E
V/V
AVX512DQ
Broadcast 256 bits of 8 doubleword integer
VBROADCASTI32X8 zmm1 {k1}{z}, m256
OR AVX10.1
data in mem to locations in zmm1 using
writemask k1.
EVEX.512.66.0F38.W1 5B /r
D
V/V
AVX512F
Broadcast 256 bits of 4 quadword integer
VBROADCASTI64X4 zmm1 {k1}{z}, m256
OR AVX10.1
data in mem to locations in zmm1 using
writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
Tuple1 Scalar
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
C
Tuple2
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Tuple4
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
E
Tuple8
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Load integer data from the source operand (the second operand) and broadcast to all elements of the destination
operand (the first operand).
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-443
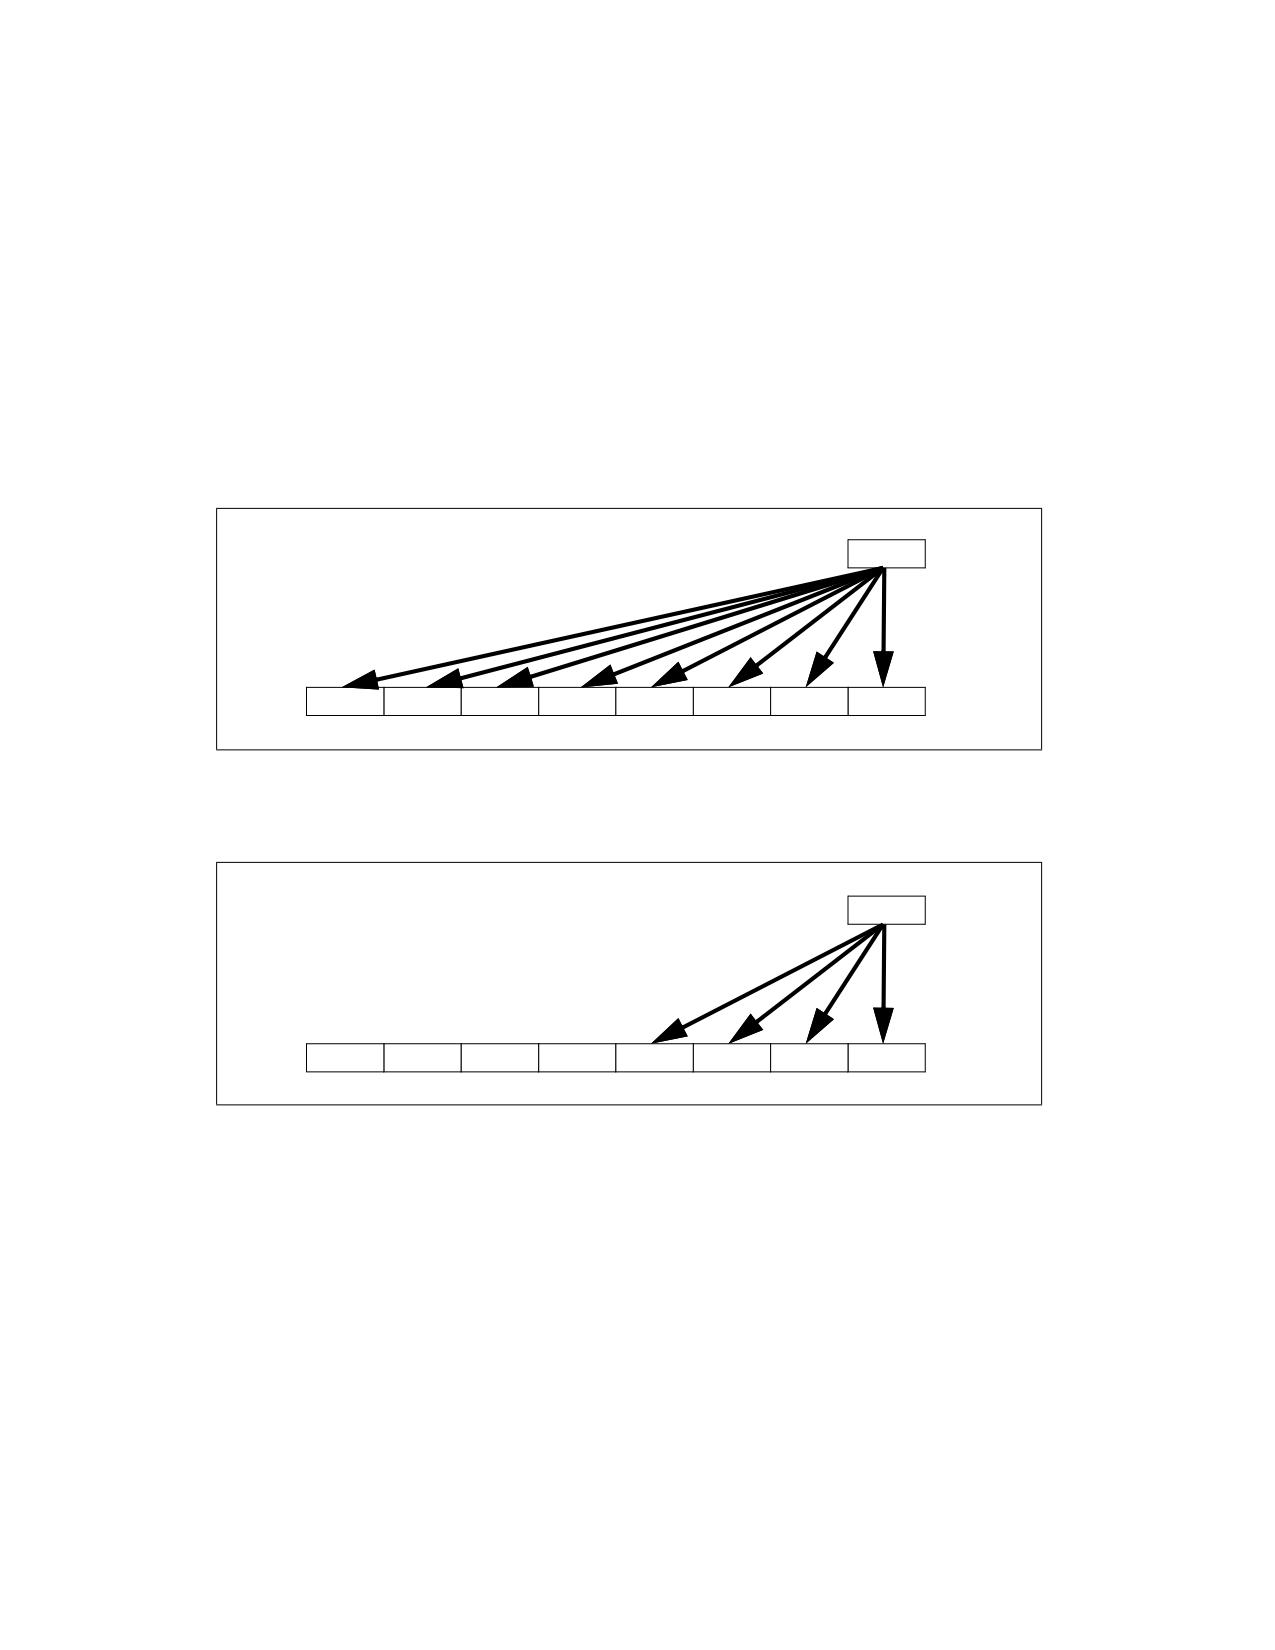
VEX256-encoded VPBROADCASTB/W/D/Q: The source operand is 8-bit, 16-bit, 32-bit, 64-bit memory location or
the low 8-bit, 16-bit 32-bit, 64-bit data in an XMM register. The destination operand is a YMM register. VPBROAD-
CASTI128 support the source operand of 128-bit memory location. Register source encodings for VPBROADCAS-
TI128 is reserved and will #UD. Bits (MAXVL-1:256) of the destination register are zeroed.
EVEX-encoded VPBROADCASTD/Q: The source operand is a 32-bit, 64-bit memory location or the low 32-bit, 64-
bit data in an XMM register. The destination operand is a ZMM/YMM/XMM register and updated according to the
writemask k1.
VPBROADCASTI32X4 and VPBROADCASTI64X4: The destination operand is a ZMM register and updated according
to the writemask k1. The source operand is 128-bit or 256-bit memory location. Register source encodings for
VBROADCASTI32X4 and VBROADCASTI64X4 are reserved and will #UD.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
If VPBROADCASTI128 is encoded with VEX.L= 0, an attempt to execute the instruction encoded with VEX.L= 0 will
cause an #UD exception.
m32
X0
DEST
X0
X0
X0
X0
X0
X0
X0
X0
Figure 5-16. VPBROADCASTD Operation (VEX.256 encoded version)
m32
X0
DEST
0
0
0
0
X0
X0
X0
X0
Figure 5-17. VPBROADCASTD Operation (128-bit version)
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-444
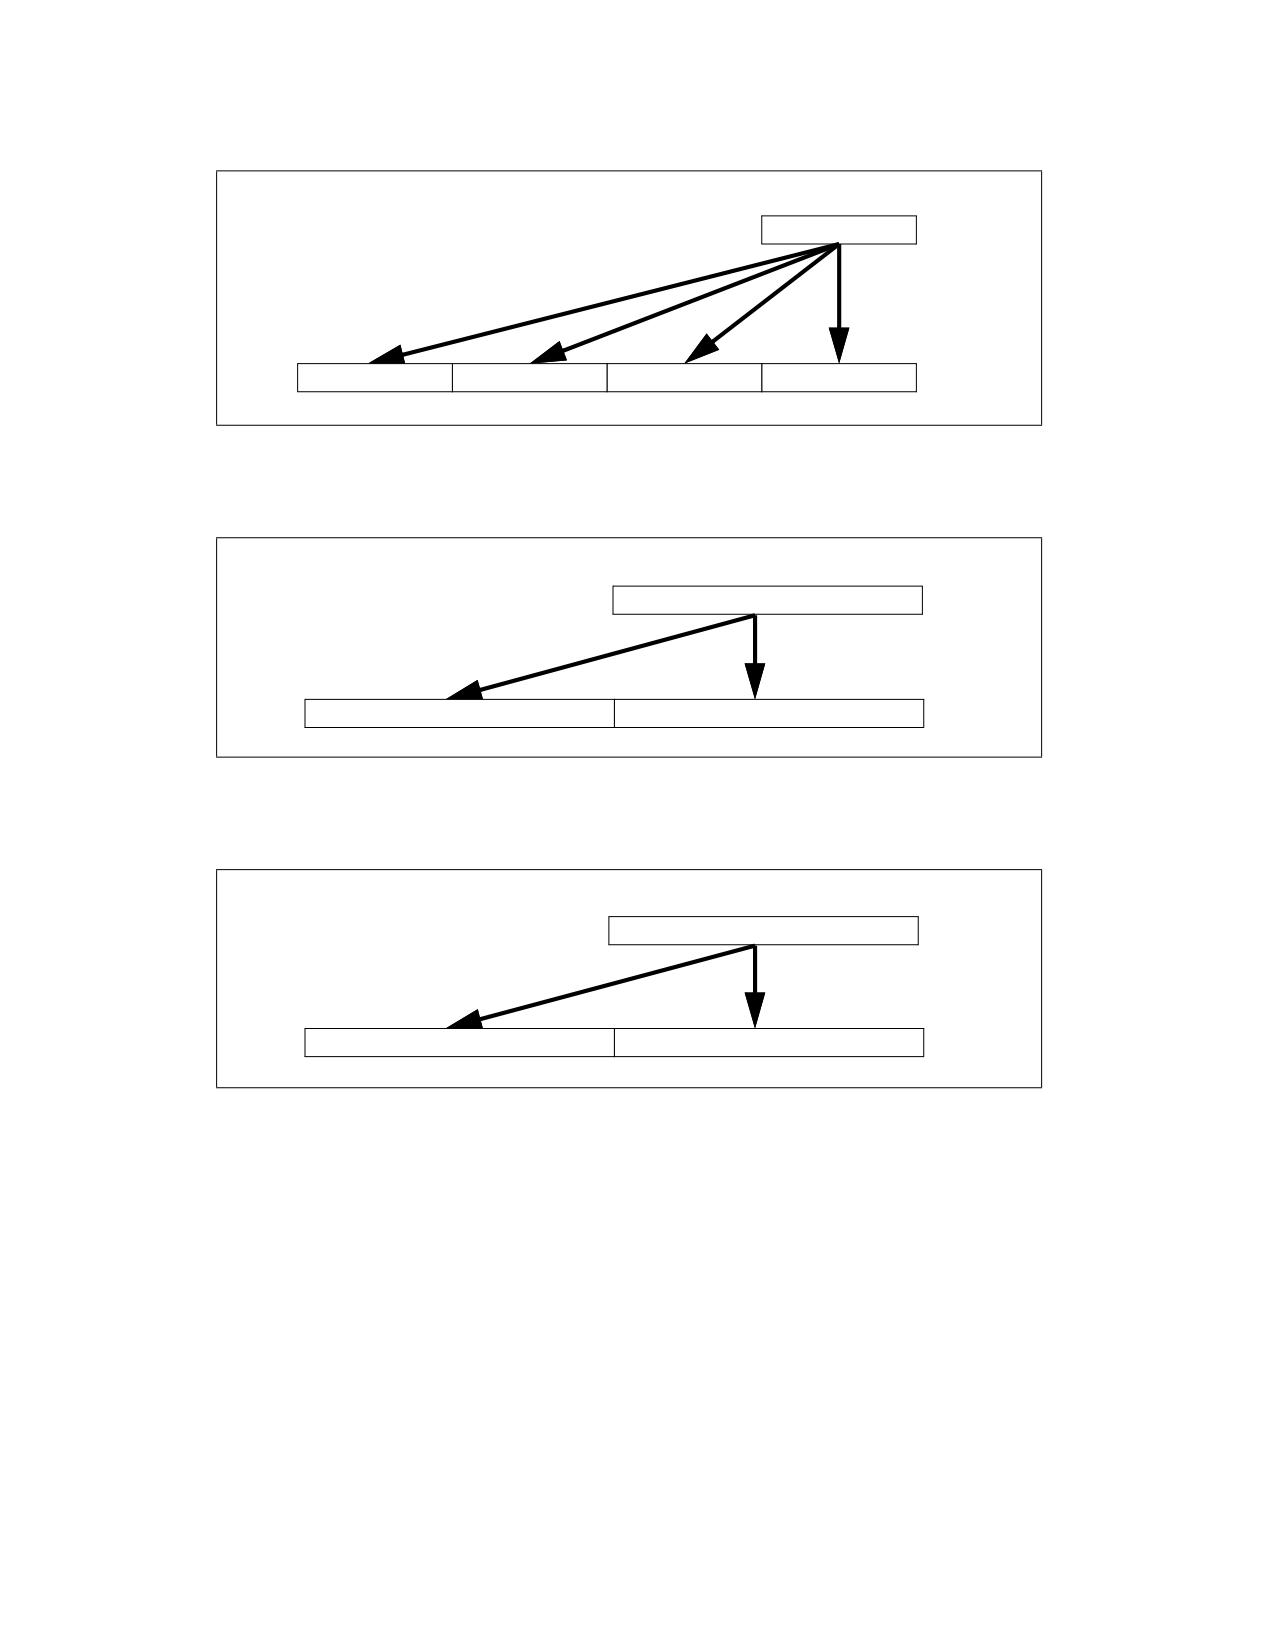
m64
X0
DEST
X0
X0
X0
X0
Figure 5-18. VPBROADCASTQ Operation (256-bit version)
m128
X0
DEST
X0
X0
Figure 5-19. VBROADCASTI128 Operation (256-bit version)
m256
X0
DEST
X0
X0
Figure 5-20. VBROADCASTI256 Operation (512-bit version)
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-445
Operation
VPBROADCASTB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[i+7:i] := SRC[7:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SRC[15:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTD (128 bit version)
temp := SRC[31:0]
DEST[31:0] := temp
DEST[63:32] := temp
DEST[95:64] := temp
DEST[127:96] := temp
DEST[MAXVL-1:128] := 0
VPBROADCASTD (VEX.256 encoded version)
temp := SRC[31:0]
DEST[31:0] := temp
DEST[63:32] := temp
DEST[95:64] := temp
DEST[127:96] := temp
DEST[159:128] := temp
DEST[191:160] := temp
DEST[223:192] := temp
DEST[255:224] := temp
DEST[MAXVL-1:256] := 0
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-446
VPBROADCASTD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[31:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTQ (VEX.256 encoded version)
temp := SRC[63:0]
DEST[63:0] := temp
DEST[127:64] := temp
DEST[191:128] := temp
DEST[255:192] := temp
DEST[MAXVL-1:256] := 0
VPBROADCASTQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[63:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VBROADCASTI32x2 (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
n := (j mod 2) * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[n+31:n]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-447
DEST[MAXVL-1:VL] := 0
VBROADCASTI128 (VEX.256 encoded version)
temp := SRC[127:0]
DEST[127:0] := temp
DEST[255:128] := temp
DEST[MAXVL-1:256] := 0
VBROADCASTI32X4 (EVEX encoded versions)
(KL, VL) = (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j* 32
n := (j modulo 4) * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[n+31:n]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VBROADCASTI64X2 (EVEX encoded versions)
(KL, VL) = (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 64
n := (j modulo 2) * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[n+63:n]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] = 0
FI
FI;
ENDFOR;
VBROADCASTI32X8 (EVEX.U1.512 encoded version)
FOR j := 0 TO 15
i := j * 32
n := (j modulo 8) * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[n+31:n]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-448
ENDFOR
DEST[MAXVL-1:VL] := 0
VBROADCASTI64X4 (EVEX.512 encoded version)
FOR j := 0 TO 7
i := j * 64
n := (j modulo 4) * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[n+63:n]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPBROADCASTB __m512i _mm512_broadcastb_epi8( __m128i a);
VPBROADCASTB __m512i _mm512_mask_broadcastb_epi8(__m512i s, __mmask64 k, __m128i a);
VPBROADCASTB __m512i _mm512_maskz_broadcastb_epi8( __mmask64 k, __m128i a);
VPBROADCASTB __m256i _mm256_broadcastb_epi8(__m128i a);
VPBROADCASTB __m256i _mm256_mask_broadcastb_epi8(__m256i s, __mmask32 k, __m128i a);
VPBROADCASTB __m256i _mm256_maskz_broadcastb_epi8( __mmask32 k, __m128i a);
VPBROADCASTB __m128i _mm_mask_broadcastb_epi8(__m128i s, __mmask16 k, __m128i a);
VPBROADCASTB __m128i _mm_maskz_broadcastb_epi8( __mmask16 k, __m128i a);
VPBROADCASTB __m128i _mm_broadcastb_epi8(__m128i a);
VPBROADCASTD __m512i _mm512_broadcastd_epi32( __m128i a);
VPBROADCASTD __m512i _mm512_mask_broadcastd_epi32(__m512i s, __mmask16 k, __m128i a);
VPBROADCASTD __m512i _mm512_maskz_broadcastd_epi32( __mmask16 k, __m128i a);
VPBROADCASTD __m256i _mm256_broadcastd_epi32( __m128i a);
VPBROADCASTD __m256i _mm256_mask_broadcastd_epi32(__m256i s, __mmask8 k, __m128i a);
VPBROADCASTD __m256i _mm256_maskz_broadcastd_epi32( __mmask8 k, __m128i a);
VPBROADCASTD __m128i _mm_broadcastd_epi32(__m128i a);
VPBROADCASTD __m128i _mm_mask_broadcastd_epi32(__m128i s, __mmask8 k, __m128i a);
VPBROADCASTD __m128i _mm_maskz_broadcastd_epi32( __mmask8 k, __m128i a);
VPBROADCASTQ __m512i _mm512_broadcastq_epi64( __m128i a);
VPBROADCASTQ __m512i _mm512_mask_broadcastq_epi64(__m512i s, __mmask8 k, __m128i a);
VPBROADCASTQ __m512i _mm512_maskz_broadcastq_epi64( __mmask8 k, __m128i a);
VPBROADCASTQ __m256i _mm256_broadcastq_epi64(__m128i a);
VPBROADCASTQ __m256i _mm256_mask_broadcastq_epi64(__m256i s, __mmask8 k, __m128i a);
VPBROADCASTQ __m256i _mm256_maskz_broadcastq_epi64( __mmask8 k, __m128i a);
VPBROADCASTQ __m128i _mm_broadcastq_epi64(__m128i a);
VPBROADCASTQ __m128i _mm_mask_broadcastq_epi64(__m128i s, __mmask8 k, __m128i a);
VPBROADCASTQ __m128i _mm_maskz_broadcastq_epi64( __mmask8 k, __m128i a);
VPBROADCASTW __m512i _mm512_broadcastw_epi16(__m128i a);
VPBROADCASTW __m512i _mm512_mask_broadcastw_epi16(__m512i s, __mmask32 k, __m128i a);
VPBROADCASTW __m512i _mm512_maskz_broadcastw_epi16( __mmask32 k, __m128i a);
VPBROADCASTW __m256i _mm256_broadcastw_epi16(__m128i a);
VPBROADCASTW __m256i _mm256_mask_broadcastw_epi16(__m256i s, __mmask16 k, __m128i a);
VPBROADCASTW __m256i _mm256_maskz_broadcastw_epi16( __mmask16 k, __m128i a);
VPBROADCASTW __m128i _mm_broadcastw_epi16(__m128i a);
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-449
VPBROADCASTW __m128i _mm_mask_broadcastw_epi16(__m128i s, __mmask8 k, __m128i a);
VPBROADCASTW __m128i _mm_maskz_broadcastw_epi16( __mmask8 k, __m128i a);
VBROADCASTI32x2 __m512i _mm512_broadcast_i32x2( __m128i a);
VBROADCASTI32x2 __m512i _mm512_mask_broadcast_i32x2(__m512i s, __mmask16 k, __m128i a);
VBROADCASTI32x2 __m512i _mm512_maskz_broadcast_i32x2( __mmask16 k, __m128i a);
VBROADCASTI32x2 __m256i _mm256_broadcast_i32x2( __m128i a);
VBROADCASTI32x2 __m256i _mm256_mask_broadcast_i32x2(__m256i s, __mmask8 k, __m128i a);
VBROADCASTI32x2 __m256i _mm256_maskz_broadcast_i32x2( __mmask8 k, __m128i a);
VBROADCASTI32x2 __m128i _mm_broadcast_i32x2(__m128i a);
VBROADCASTI32x2 __m128i _mm_mask_broadcast_i32x2(__m128i s, __mmask8 k, __m128i a);
VBROADCASTI32x2 __m128i _mm_maskz_broadcast_i32x2( __mmask8 k, __m128i a);
VBROADCASTI32x4 __m512i _mm512_broadcast_i32x4( __m128i a);
VBROADCASTI32x4 __m512i _mm512_mask_broadcast_i32x4(__m512i s, __mmask16 k, __m128i a);
VBROADCASTI32x4 __m512i _mm512_maskz_broadcast_i32x4( __mmask16 k, __m128i a);
VBROADCASTI32x4 __m256i _mm256_broadcast_i32x4( __m128i a);
VBROADCASTI32x4 __m256i _mm256_mask_broadcast_i32x4(__m256i s, __mmask8 k, __m128i a);
VBROADCASTI32x4 __m256i _mm256_maskz_broadcast_i32x4( __mmask8 k, __m128i a);
VBROADCASTI32x8 __m512i _mm512_broadcast_i32x8( __m256i a);
VBROADCASTI32x8 __m512i _mm512_mask_broadcast_i32x8(__m512i s, __mmask16 k, __m256i a);
VBROADCASTI32x8 __m512i _mm512_maskz_broadcast_i32x8( __mmask16 k, __m256i a);
VBROADCASTI64x2 __m512i _mm512_broadcast_i64x2( __m128i a);
VBROADCASTI64x2 __m512i _mm512_mask_broadcast_i64x2(__m512i s, __mmask8 k, __m128i a);
VBROADCASTI64x2 __m512i _mm512_maskz_broadcast_i64x2( __mmask8 k, __m128i a);
VBROADCASTI64x2 __m256i _mm256_broadcast_i64x2( __m128i a);
VBROADCASTI64x2 __m256i _mm256_mask_broadcast_i64x2(__m256i s, __mmask8 k, __m128i a);
VBROADCASTI64x2 __m256i _mm256_maskz_broadcast_i64x2( __mmask8 k, __m128i a);
VBROADCASTI64x4 __m512i _mm512_broadcast_i64x4( __m256i a);
VBROADCASTI64x4 __m512i _mm512_mask_broadcast_i64x4(__m512i s, __mmask8 k, __m256i a);
VBROADCASTI64x4 __m512i _mm512_maskz_broadcast_i64x4( __mmask8 k, __m256i a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
EVEX-encoded instructions, see Table 2-23, “Type 6 Class Exception Conditions.”
EVEX-encoded instructions, syntax with reg/mem operand, see Table 2-55, “Type E6 Class Exception Conditions.”
Additionally:
#UD
If VEX.L = 0 for VPBROADCASTQ, VPBROADCASTI128.
If EVEX.L’L = 0 for VBROADCASTI32X4/VBROADCASTI64X2.
If EVEX.L’L < 10b for VBROADCASTI32X8/VBROADCASTI64X4.
VPBROADCAST-Load Integer and Broadcast
Vol. 2C
5-450

VPBROADCASTB/W/D/Q-Load With Broadcast Integer Data From General Purpose Register
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit
Flag
Mode
Support
EVEX.128.66.0F38.W0 7A /r
A
V/V
(AVX512VL AND
Broadcast an 8-bit value from a GPR to all bytes in
VPBROADCASTB xmm1 {k1}{z}, reg
AVX512BW) OR
the 128-bit destination subject to writemask k1.
AVX10.1
EVEX.256.66.0F38.W0 7A /r
A
V/V
(AVX512VL AND
Broadcast an 8-bit value from a GPR to all bytes in
VPBROADCASTB ymm1 {k1}{z}, reg
AVX512BW) OR
the 256-bit destination subject to writemask k1.
AVX10.1
EVEX.512.66.0F38.W0 7A /r
A
V/V
AVX512BW
Broadcast an 8-bit value from a GPR to all bytes in
VPBROADCASTB zmm1 {k1}{z}, reg
OR AVX10.1
the 512-bit destination subject to writemask k1.
EVEX.128.66.0F38.W0 7B /r
A
V/V
(AVX512VL AND
Broadcast a 16-bit value from a GPR to all words in
VPBROADCASTW xmm1 {k1}{z}, reg
AVX512BW) OR
the 128-bit destination subject to writemask k1.
AVX10.1
EVEX.256.66.0F38.W0 7B /r
A
V/V
(AVX512VL AND
Broadcast a 16-bit value from a GPR to all words in
VPBROADCASTW ymm1 {k1}{z}, reg
AVX512BW) OR
the 256-bit destination subject to writemask k1.
AVX10.1
EVEX.512.66.0F38.W0 7B /r
A
V/V
AVX512BW
Broadcast a 16-bit value from a GPR to all words in
VPBROADCASTW zmm1 {k1}{z}, reg
OR AVX10.1
the 512-bit destination subject to writemask k1.
EVEX.128.66.0F38.W0 7C /r
A
V/V
(AVX512VL AND
Broadcast a 32-bit value from a GPR to all
VPBROADCASTD xmm1 {k1}{z}, r32
AVX512F) OR
doublewords in the 128-bit destination subject to
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 7C /r
A
V/V
(AVX512VL AND
Broadcast a 32-bit value from a GPR to all
VPBROADCASTD ymm1 {k1}{z}, r32
AVX512F) OR
doublewords in the 256-bit destination subject to
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 7C /r
A
V/V
AVX512F
Broadcast a 32-bit value from a GPR to all
VPBROADCASTD zmm1 {k1}{z}, r32
OR AVX10.1
doublewords in the 512-bit destination subject to
writemask k1.
EVEX.128.66.0F38.W1 7C /r
A
V/N.E.1
(AVX512VL AND
Broadcast a 64-bit value from a GPR to all
VPBROADCASTQ xmm1 {k1}{z}, r64
AVX512F) OR
quadwords in the 128-bit destination subject to
AVX10.1
writemask k1.
EVEX.256.66.0F38.W1 7C /r
A
V/N.E.1
(AVX512VL AND
Broadcast a 64-bit value from a GPR to all
VPBROADCASTQ ymm1 {k1}{z}, r64
AVX512F) OR
quadwords in the 256-bit destination subject to
AVX10.1
writemask k1.
EVEX.512.66.0F38.W1 7C /r
A
V/N.E.1
AVX512F
Broadcast a 64-bit value from a GPR to all
VPBROADCASTQ zmm1 {k1}{z}, r64
OR AVX10.1
quadwords in the 512-bit destination subject to
writemask k1.
NOTES:
1. EVEX.W in non-64 bit is ignored; the instruction behaves as if the W0 version is used.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
VPBROADCASTB/W/D/Q-Load With Broadcast Integer Data From General Purpose Register
Vol. 2C
5-451
Description
Broadcasts a 8-bit, 16-bit, 32-bit or 64-bit value from a general-purpose register (the second operand) to all the
locations in the destination vector register (the first operand) using the writemask k1.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Operation
VPBROADCASTB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[i+7:i] := SRC[7:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SRC[15:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[31:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTB/W/D/Q-Load With Broadcast Integer Data From General Purpose Register
Vol. 2C
5-452
VPBROADCASTQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[63:0]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPBROADCASTB __m512i _mm512_mask_set1_epi8(__m512i s, __mmask64 k, int a);
VPBROADCASTB __m512i _mm512_maskz_set1_epi8( __mmask64 k, int a);
VPBROADCASTB __m256i _mm256_mask_set1_epi8(__m256i s, __mmask32 k, int a);
VPBROADCASTB __m256i _mm256_maskz_set1_epi8( __mmask32 k, int a);
VPBROADCASTB __m128i _mm_mask_set1_epi8(__m128i s, __mmask16 k, int a);
VPBROADCASTB __m128i _mm_maskz_set1_epi8( __mmask16 k, int a);
VPBROADCASTD __m512i _mm512_mask_set1_epi32(__m512i s, __mmask16 k, int a);
VPBROADCASTD __m512i _mm512_maskz_set1_epi32( __mmask16 k, int a);
VPBROADCASTD __m256i _mm256_mask_set1_epi32(__m256i s, __mmask8 k, int a);
VPBROADCASTD __m256i _mm256_maskz_set1_epi32( __mmask8 k, int a);
VPBROADCASTD __m128i _mm_mask_set1_epi32(__m128i s, __mmask8 k, int a);
VPBROADCASTD __m128i _mm_maskz_set1_epi32( __mmask8 k, int a);
VPBROADCASTQ __m512i _mm512_mask_set1_epi64(__m512i s, __mmask8 k, __int64 a);
VPBROADCASTQ __m512i _mm512_maskz_set1_epi64( __mmask8 k, __int64 a);
VPBROADCASTQ __m256i _mm256_mask_set1_epi64(__m256i s, __mmask8 k, __int64 a);
VPBROADCASTQ __m256i _mm256_maskz_set1_epi64( __mmask8 k, __int64 a);
VPBROADCASTQ __m128i _mm_mask_set1_epi64(__m128i s, __mmask8 k, __int64 a);
VPBROADCASTQ __m128i _mm_maskz_set1_epi64( __mmask8 k, __int64 a);
VPBROADCASTW __m512i _mm512_mask_set1_epi16(__m512i s, __mmask32 k, int a);
VPBROADCASTW __m512i _mm512_maskz_set1_epi16( __mmask32 k, int a);
VPBROADCASTW __m256i _mm256_mask_set1_epi16(__m256i s, __mmask16 k, int a);
VPBROADCASTW __m256i _mm256_maskz_set1_epi16( __mmask16 k, int a);
VPBROADCASTW __m128i _mm_mask_set1_epi16(__m128i s, __mmask8 k, int a);
VPBROADCASTW __m128i _mm_maskz_set1_epi16( __mmask8 k, int a);
Exceptions
EVEX-encoded instructions, see Table 2-57, “Type E7NM Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B.
VPBROADCASTB/W/D/Q-Load With Broadcast Integer Data From General Purpose Register
Vol. 2C
5-453

VPBROADCASTM-Broadcast Mask to Vector Register
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.F3.0F38.W1 2A /r
RM
V/V
(AVX512VL AND
Broadcast low byte value in k1 to two locations in
VPBROADCASTMB2Q xmm1, k1
AVX512CD) OR
xmm1.
AVX10.1
EVEX.256.F3.0F38.W1 2A /r
RM
V/V
(AVX512VL AND
Broadcast low byte value in k1 to four locations in
VPBROADCASTMB2Q ymm1, k1
AVX512CD) OR
ymm1.
AVX10.1
EVEX.512.F3.0F38.W1 2A /r
RM
V/V
AVX512CD
Broadcast low byte value in k1 to eight locations in
VPBROADCASTMB2Q zmm1, k1
OR AVX10.1
zmm1.
EVEX.128.F3.0F38.W0 3A /r
RM
V/V
(AVX512VL AND
Broadcast low word value in k1 to four locations in
VPBROADCASTMW2D xmm1, k1
AVX512CD) OR
xmm1.
AVX10.1
EVEX.256.F3.0F38.W0 3A /r
RM
V/V
(AVX512VL AND
Broadcast low word value in k1 to eight locations
VPBROADCASTMW2D ymm1, k1
AVX512CD) OR
in ymm1.
AVX10.1
EVEX.512.F3.0F38.W0 3A /r
RM
V/V
AVX512CD
Broadcast low word value in k1 to sixteen
VPBROADCASTMW2D zmm1, k1
OR AVX10.1
locations in zmm1.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Broadcasts the zero-extended 64/32 bit value of the low byte/word of the source operand (the second operand) to
each 64/32 bit element of the destination operand (the first operand). The source operand is an opmask register.
The destination operand is a ZMM register (EVEX.512), YMM register (EVEX.256), or XMM register (EVEX.128).
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Operation
VPBROADCASTMB2Q
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j*64
DEST[i+63:i] := ZeroExtend(SRC[7:0])
ENDFOR
DEST[MAXVL-1:VL] := 0
VPBROADCASTM-Broadcast Mask to Vector Register
Vol. 2C
5-454
VPBROADCASTMW2D
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j*32
DEST[i+31:i] := ZeroExtend(SRC[15:0])
ENDFOR
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPBROADCASTMB2Q __m512i _mm512_broadcastmb_epi64( __mmask8);
VPBROADCASTMW2D __m512i _mm512_broadcastmw_epi32( __mmask16);
VPBROADCASTMB2Q __m256i _mm256_broadcastmb_epi64( __mmask8);
VPBROADCASTMW2D __m256i _mm256_broadcastmw_epi32( __mmask8);
VPBROADCASTMB2Q __m128i _mm_broadcastmb_epi64( __mmask8);
VPBROADCASTMW2D __m128i _mm_broadcastmw_epi32( __mmask8);
SIMD Floating-Point Exceptions
None
Other Exceptions
EVEX-encoded instruction, see Table 2-56, “Type E6NF Class Exception Conditions.”
VPBROADCASTM-Broadcast Mask to Vector Register
Vol. 2C
5-455

VPCMPB/VPCMPUB-Compare Packed Byte Values Into Mask
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 3F /r ib
A
V/V
(AVX512VL AND
Compare packed signed byte values in xmm3/m128
VPCMPB k1 {k2}, xmm2,
AVX512BW) OR
and xmm2 using bits 2:0 of imm8 as a comparison
xmm3/m128, imm8
AVX10.1
predicate with writemask k2 and leave the result in
mask register k1.
EVEX.256.66.0F3A.W0 3F /r ib
A
V/V
(AVX512VL AND
Compare packed signed byte values in ymm3/m256
VPCMPB k1 {k2}, ymm2,
AVX512BW) OR
and ymm2 using bits 2:0 of imm8 as a comparison
ymm3/m256, imm8
AVX10.1
predicate with writemask k2 and leave the result in
mask register k1.
EVEX.512.66.0F3A.W0 3F /r ib
A
V/V
AVX512BW
Compare packed signed byte values in zmm3/m512
VPCMPB k1 {k2}, zmm2,
OR AVX10.1
and zmm2 using bits 2:0 of imm8 as a comparison
zmm3/m512, imm8
predicate with writemask k2 and leave the result in
mask register k1.
EVEX.128.66.0F3A.W0 3E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned byte values in
VPCMPUB k1 {k2}, xmm2,
AVX512BW) OR
xmm3/m128 and xmm2 using bits 2:0 of imm8 as a
xmm3/m128, imm8
AVX10.1
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.256.66.0F3A.W0 3E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned byte values in
VPCMPUB k1 {k2}, ymm2,
AVX512BW) OR
ymm3/m256 and ymm2 using bits 2:0 of imm8 as a
ymm3/m256, imm8
AVX10.1
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.512.66.0F3A.W0 3E /r ib
A
V/V
AVX512BW
Compare packed unsigned byte values in
VPCMPUB k1 {k2}, zmm2,
OR AVX10.1
zmm3/m512 and zmm2 using bits 2:0 of imm8 as a
zmm3/m512, imm8
comparison predicate with writemask k2 and leave
the result in mask register k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed byte values in the second source operand and the first source operand and
returns the results of the comparison to the mask destination operand. The comparison predicate operand (imme-
diate byte) specifies the type of comparison performed on each pair of packed values in the two source operands.
The result of each comparison is a single mask bit result of 1 (comparison true) or 0 (comparison false).
VPCMPB performs a comparison between pairs of signed byte values.
VPCMPUB performs a comparison between pairs of unsigned byte values.
The first source operand (second operand) is a ZMM/YMM/XMM register. The second source operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location. The destination operand (first operand) is a mask
register k1. Up to 64/32/16 comparisons are performed with results written to the destination operand under the
writemask k2.
VPCMPB/VPCMPUB-Compare Packed Byte Values Into Mask
Vol. 2C
5-456

The comparison predicate operand is an 8-bit immediate: bits 2:0 define the type of comparison to be performed.
Bits 3 through 7 of the immediate are reserved. Compiler can implement the pseudo-op mnemonic listed in Table
5-19.
:
Table 5-19. Pseudo-Op and VPCMP* Implementation
Pseudo-Op
PCMPM Implementation
VPCMPEQ* reg1, reg2, reg3
VPCMP* reg1, reg2, reg3, 0
VPCMPLT* reg1, reg2, reg3
VPCMP*reg1, reg2, reg3, 1
VPCMPLE* reg1, reg2, reg3
VPCMP* reg1, reg2, reg3, 2
VPCMPNEQ* reg1, reg2, reg3
VPCMP* reg1, reg2, reg3, 4
VPPCMPNLT* reg1, reg2, reg3
VPCMP* reg1, reg2, reg3, 5
VPCMPNLE* reg1, reg2, reg3
VPCMP* reg1, reg2, reg3, 6
Operation
CASE (COMPARISON PREDICATE) OF
0: OP := EQ;
1: OP := LT;
2: OP := LE;
3: OP := FALSE;
4: OP := NEQ;
5: OP := NLT;
6: OP := NLE;
7: OP := TRUE;
ESAC;
VPCMPB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k2[j] OR *no writemask*
THEN
CMP := SRC1[i+7:i] OP SRC2[i+7:i];
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] = 0
; zeroing-masking onlyFI;
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPB/VPCMPUB-Compare Packed Byte Values Into Mask
Vol. 2C
5-457
VPCMPUB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k2[j] OR *no writemask*
THEN
CMP := SRC1[i+7:i] OP SRC2[i+7:i];
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] = 0
; zeroing-masking onlyFI;
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPCMPB __mmask64 _mm512_cmp_epi8_mask( __m512i a, __m512i b, int cmp);
VPCMPB __mmask64 _mm512_mask_cmp_epi8_mask( __mmask64 m, __m512i a, __m512i b, int cmp);
VPCMPB __mmask32 _mm256_cmp_epi8_mask( __m256i a, __m256i b, int cmp);
VPCMPB __mmask32 _mm256_mask_cmp_epi8_mask( __mmask32 m, __m256i a, __m256i b, int cmp);
VPCMPB __mmask16 _mm_cmp_epi8_mask( __m128i a, __m128i b, int cmp);
VPCMPB __mmask16 _mm_mask_cmp_epi8_mask( __mmask16 m, __m128i a, __m128i b, int cmp);
VPCMPB __mmask64 _mm512_cmp[eq|ge|gt|le|lt|neq]_epi8_mask( __m512i a, __m512i b);
VPCMPB __mmask64 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epi8_mask( __mmask64 m, __m512i a, __m512i b);
VPCMPB __mmask32 _mm256_cmp[eq|ge|gt|le|lt|neq]_epi8_mask( __m256i a, __m256i b);
VPCMPB __mmask32 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epi8_mask( __mmask32 m, __m256i a, __m256i b);
VPCMPB __mmask16 _mm_cmp[eq|ge|gt|le|lt|neq]_epi8_mask( __m128i a, __m128i b);
VPCMPB __mmask16 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epi8_mask( __mmask16 m, __m128i a, __m128i b);
VPCMPUB __mmask64 _mm512_cmp_epu8_mask( __m512i a, __m512i b, int cmp);
VPCMPUB __mmask64 _mm512_mask_cmp_epu8_mask( __mmask64 m, __m512i a, __m512i b, int cmp);
VPCMPUB __mmask32 _mm256_cmp_epu8_mask( __m256i a, __m256i b, int cmp);
VPCMPUB __mmask32 _mm256_mask_cmp_epu8_mask( __mmask32 m, __m256i a, __m256i b, int cmp);
VPCMPUB __mmask16 _mm_cmp_epu8_mask( __m128i a, __m128i b, int cmp);
VPCMPUB __mmask16 _mm_mask_cmp_epu8_mask( __mmask16 m, __m128i a, __m128i b, int cmp);
VPCMPUB __mmask64 _mm512_cmp[eq|ge|gt|le|lt|neq]_epu8_mask( __m512i a, __m512i b, int cmp);
VPCMPUB __mmask64 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epu8_mask( __mmask64 m, __m512i a, __m512i b, int cmp);
VPCMPUB __mmask32 _mm256_cmp[eq|ge|gt|le|lt|neq]_epu8_mask( __m256i a, __m256i b, int cmp);
VPCMPUB __mmask32 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epu8_mask( __mmask32 m, __m256i a, __m256i b, int cmp);
VPCMPUB __mmask16 _mm_cmp[eq|ge|gt|le|lt|neq]_epu8_mask( __m128i a, __m128i b, int cmp);
VPCMPUB __mmask16 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epu8_mask( __mmask16 m, __m128i a, __m128i b, int cmp);
SIMD Floating-Point Exceptions
None
Other Exceptions
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPCMPB/VPCMPUB-Compare Packed Byte Values Into Mask
Vol. 2C
5-458

VPCMPD/VPCMPUD-Compare Packed Integer Values Into Mask
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 1F /r ib
A
V/V
(AVX512VL AND
Compare packed signed doubleword integer values in
VPCMPD k1 {k2}, xmm2,
AVX512F) OR
xmm3/m128/m32bcst and xmm2 using bits 2:0 of
xmm3/m128/m32bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.256.66.0F3A.W0 1F /r ib
A
V/V
(AVX512VL AND
Compare packed signed doubleword integer values in
VPCMPD k1 {k2}, ymm2,
AVX512F) OR
ymm3/m256/m32bcst and ymm2 using bits 2:0 of
ymm3/m256/m32bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.512.66.0F3A.W0 1F /r ib
A
V/V
AVX512F
Compare packed signed doubleword integer values in
VPCMPD k1 {k2}, zmm2,
OR AVX10.1
zmm2 and zmm3/m512/m32bcst using bits 2:0 of
zmm3/m512/m32bcst, imm8
imm8 as a comparison predicate. The comparison
results are written to the destination k1 under
writemask k2.
EVEX.128.66.0F3A.W0 1E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned doubleword integer values
VPCMPUD k1 {k2}, xmm2,
AVX512F) OR
in xmm3/m128/m32bcst and xmm2 using bits 2:0 of
xmm3/m128/m32bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.256.66.0F3A.W0 1E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned doubleword integer values
VPCMPUD k1 {k2}, ymm2,
AVX512F) OR
in ymm3/m256/m32bcst and ymm2 using bits 2:0 of
ymm3/m256/m32bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.512.66.0F3A.W0 1E /r ib
A
V/V
AVX512F
Compare packed unsigned doubleword integer values
VPCMPUD k1 {k2}, zmm2,
OR AVX10.1
in zmm2 and zmm3/m512/m32bcst using bits 2:0 of
zmm3/m512/m32bcst, imm8
imm8 as a comparison predicate. The comparison
results are written to the destination k1 under
writemask k2.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Performs a SIMD compare of the packed integer values in the second source operand and the first source operand
and returns the results of the comparison to the mask destination operand. The comparison predicate operand
(immediate byte) specifies the type of comparison performed on each pair of packed values in the two source oper-
ands. The result of each comparison is a single mask bit result of 1 (comparison true) or 0 (comparison false).
VPCMPD/VPCMPUD performs a comparison between pairs of signed/unsigned doubleword integer values.
The first source operand (second operand) is a ZMM/YMM/XMM register. The second source operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location or a 512-bit vector broadcasted from a 32-bit
memory location. The destination operand (first operand) is a mask register k1. Up to 16/8/4 comparisons are
performed with results written to the destination operand under the writemask k2.
The comparison predicate operand is an 8-bit immediate: bits 2:0 define the type of comparison to be performed.
Bits 3 through 7 of the immediate are reserved. Compiler can implement the pseudo-op mnemonic listed in Table
5-19.
Operation
CASE (COMPARISON PREDICATE) OF
0: OP := EQ;
VPCMPD/VPCMPUD-Compare Packed Integer Values Into Mask
Vol. 2C
5-459
1: OP := LT;
2: OP := LE;
3: OP := FALSE;
4: OP := NEQ;
5: OP := NLT;
6: OP := NLE;
7: OP := TRUE;
ESAC;
VPCMPD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k2[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN CMP := SRC1[i+31:i] OP SRC2[31:0];
ELSE CMP := SRC1[i+31:i] OP SRC2[i+31:i];
FI;
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] := 0
; zeroing-masking onlyFI;
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPUD (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k2[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN CMP := SRC1[i+31:i] OP SRC2[31:0];
ELSE CMP := SRC1[i+31:i] OP SRC2[i+31:i];
FI;
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] := 0
; zeroing-masking onlyFI;
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPD/VPCMPUD-Compare Packed Integer Values Into Mask
Vol. 2C
5-460
Intel C/C++ Compiler Intrinsic Equivalent
VPCMPD __mmask16 _mm512_cmp_epi32_mask( __m512i a, __m512i b, int imm);
VPCMPD __mmask16 _mm512_mask_cmp_epi32_mask(__mmask16 k, __m512i a, __m512i b, int imm);
VPCMPD __mmask16 _mm512_cmp[eq|ge|gt|le|lt|neq]_epi32_mask( __m512i a, __m512i b);
VPCMPD __mmask16 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epi32_mask(__mmask16 k, __m512i a, __m512i b);
VPCMPUD __mmask16 _mm512_cmp_epu32_mask( __m512i a, __m512i b, int imm);
VPCMPUD __mmask16 _mm512_mask_cmp_epu32_mask(__mmask16 k, __m512i a, __m512i b, int imm);
VPCMPUD __mmask16 _mm512_cmp[eq|ge|gt|le|lt|neq]_epu32_mask( __m512i a, __m512i b);
VPCMPUD __mmask16 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epu32_mask(__mmask16 k, __m512i a, __m512i b);
VPCMPD __mmask8 _mm256_cmp_epi32_mask( __m256i a, __m256i b, int imm);
VPCMPD __mmask8 _mm256_mask_cmp_epi32_mask(__mmask8 k, __m256i a, __m256i b, int imm);
VPCMPD __mmask8 _mm256_cmp[eq|ge|gt|le|lt|neq]_epi32_mask( __m256i a, __m256i b);
VPCMPD __mmask8 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epi32_mask(__mmask8 k, __m256i a, __m256i b);
VPCMPUD __mmask8 _mm256_cmp_epu32_mask( __m256i a, __m256i b, int imm);
VPCMPUD __mmask8 _mm256_mask_cmp_epu32_mask(__mmask8 k, __m256i a, __m256i b, int imm);
VPCMPUD __mmask8 _mm256_cmp[eq|ge|gt|le|lt|neq]_epu32_mask( __m256i a, __m256i b);
VPCMPUD __mmask8 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epu32_mask(__mmask8 k, __m256i a, __m256i b);
VPCMPD __mmask8 _mm_cmp_epi32_mask( __m128i a, __m128i b, int imm);
VPCMPD __mmask8 _mm_mask_cmp_epi32_mask(__mmask8 k, __m128i a, __m128i b, int imm);
VPCMPD __mmask8 _mm_cmp[eq|ge|gt|le|lt|neq]_epi32_mask( __m128i a, __m128i b);
VPCMPD __mmask8 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epi32_mask(__mmask8 k, __m128i a, __m128i b);
VPCMPUD __mmask8 _mm_cmp_epu32_mask( __m128i a, __m128i b, int imm);
VPCMPUD __mmask8 _mm_mask_cmp_epu32_mask(__mmask8 k, __m128i a, __m128i b, int imm);
VPCMPUD __mmask8 _mm_cmp[eq|ge|gt|le|lt|neq]_epu32_mask( __m128i a, __m128i b);
VPCMPUD __mmask8 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epu32_mask(__mmask8 k, __m128i a, __m128i b);
SIMD Floating-Point Exceptions
None
Other Exceptions
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPCMPD/VPCMPUD-Compare Packed Integer Values Into Mask
Vol. 2C
5-461

VPCMPQ/VPCMPUQ-Compare Packed Integer Values Into Mask
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W1 1F /r ib
A
V/V
(AVX512VL AND
Compare packed signed quadword integer values in
VPCMPQ k1 {k2}, xmm2,
AVX512F) OR
xmm3/m128/m64bcst and xmm2 using bits 2:0 of
xmm3/m128/m64bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.256.66.0F3A.W1 1F /r ib
A
V/V
(AVX512VL AND
Compare packed signed quadword integer values in
VPCMPQ k1 {k2}, ymm2,
AVX512F) OR
ymm3/m256/m64bcst and ymm2 using bits 2:0 of
ymm3/m256/m64bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.512.66.0F3A.W1 1F /r ib
A
V/V
AVX512F
Compare packed signed quadword integer values in
VPCMPQ k1 {k2}, zmm2,
OR AVX10.1
zmm3/m512/m64bcst and zmm2 using bits 2:0 of
zmm3/m512/m64bcst, imm8
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.128.66.0F3A.W1 1E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned quadword integer values
VPCMPUQ k1 {k2}, xmm2,
AVX512F) OR
in xmm3/m128/m64bcst and xmm2 using bits 2:0 of
xmm3/m128/m64bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.256.66.0F3A.W1 1E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned quadword integer values
VPCMPUQ k1 {k2}, ymm2,
AVX512F) OR
in ymm3/m256/m64bcst and ymm2 using bits 2:0 of
ymm3/m256/m64bcst, imm8
AVX10.1
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
EVEX.512.66.0F3A.W1 1E /r ib
A
V/V
AVX512F
Compare packed unsigned quadword integer values
VPCMPUQ k1 {k2}, zmm2,
OR AVX10.1
in zmm3/m512/m64bcst and zmm2 using bits 2:0 of
zmm3/m512/m64bcst, imm8
imm8 as a comparison predicate with writemask k2
and leave the result in mask register k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Performs a SIMD compare of the packed integer values in the second source operand and the first source operand
and returns the results of the comparison to the mask destination operand. The comparison predicate operand
(immediate byte) specifies the type of comparison performed on each pair of packed values in the two source oper-
ands. The result of each comparison is a single mask bit result of 1 (comparison true) or 0 (comparison false).
VPCMPQ/VPCMPUQ performs a comparison between pairs of signed/unsigned quadword integer values.
The first source operand (second operand) is a ZMM/YMM/XMM register. The second source operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location or a 512-bit vector broadcasted from a 64-bit
memory location. The destination operand (first operand) is a mask register k1. Up to 8/4/2 comparisons are
performed with results written to the destination operand under the writemask k2.
The comparison predicate operand is an 8-bit immediate: bits 2:0 define the type of comparison to be performed.
Bits 3 through 7 of the immediate are reserved. Compiler can implement the pseudo-op mnemonic listed in Table
5-19.
VPCMPQ/VPCMPUQ-Compare Packed Integer Values Into Mask
Vol. 2C
5-462
Operation
CASE (COMPARISON PREDICATE) OF
0: OP := EQ;
1: OP := LT;
2: OP := LE;
3: OP := FALSE;
4: OP := NEQ;
5: OP := NLT;
6: OP := NLE;
7: OP := TRUE;
ESAC;
VPCMPQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k2[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN CMP := SRC1[i+63:i] OP SRC2[63:0];
ELSE CMP := SRC1[i+63:i] OP SRC2[i+63:i];
FI;
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] := 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPUQ (EVEX encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k2[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN CMP := SRC1[i+63:i] OP SRC2[63:0];
ELSE CMP := SRC1[i+63:i] OP SRC2[i+63:i];
FI;
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] := 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPQ/VPCMPUQ-Compare Packed Integer Values Into Mask
Vol. 2C
5-463
Intel C/C++ Compiler Intrinsic Equivalent
VPCMPQ __mmask8 _mm512_cmp_epi64_mask( __m512i a, __m512i b, int imm);
VPCMPQ __mmask8 _mm512_mask_cmp_epi64_mask(__mmask8 k, __m512i a, __m512i b, int imm);
VPCMPQ __mmask8 _mm512_cmp[eq|ge|gt|le|lt|neq]_epi64_mask( __m512i a, __m512i b);
VPCMPQ __mmask8 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epi64_mask(__mmask8 k, __m512i a, __m512i b);
VPCMPUQ __mmask8 _mm512_cmp_epu64_mask( __m512i a, __m512i b, int imm);
VPCMPUQ __mmask8 _mm512_mask_cmp_epu64_mask(__mmask8 k, __m512i a, __m512i b, int imm);
VPCMPUQ __mmask8 _mm512_cmp[eq|ge|gt|le|lt|neq]_epu64_mask( __m512i a, __m512i b);
VPCMPUQ __mmask8 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epu64_mask(__mmask8 k, __m512i a, __m512i b);
VPCMPQ __mmask8 _mm256_cmp_epi64_mask( __m256i a, __m256i b, int imm);
VPCMPQ __mmask8 _mm256_mask_cmp_epi64_mask(__mmask8 k, __m256i a, __m256i b, int imm);
VPCMPQ __mmask8 _mm256_cmp[eq|ge|gt|le|lt|neq]_epi64_mask( __m256i a, __m256i b);
VPCMPQ __mmask8 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epi64_mask(__mmask8 k, __m256i a, __m256i b);
VPCMPUQ __mmask8 _mm256_cmp_epu64_mask( __m256i a, __m256i b, int imm);
VPCMPUQ __mmask8 _mm256_mask_cmp_epu64_mask(__mmask8 k, __m256i a, __m256i b, int imm);
VPCMPUQ __mmask8 _mm256_cmp[eq|ge|gt|le|lt|neq]_epu64_mask( __m256i a, __m256i b);
VPCMPUQ __mmask8 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epu64_mask(__mmask8 k, __m256i a, __m256i b);
VPCMPQ __mmask8 _mm_cmp_epi64_mask( __m128i a, __m128i b, int imm);
VPCMPQ __mmask8 _mm_mask_cmp_epi64_mask(__mmask8 k, __m128i a, __m128i b, int imm);
VPCMPQ __mmask8 _mm_cmp[eq|ge|gt|le|lt|neq]_epi64_mask( __m128i a, __m128i b);
VPCMPQ __mmask8 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epi64_mask(__mmask8 k, __m128i a, __m128i b);
VPCMPUQ __mmask8 _mm_cmp_epu64_mask( __m128i a, __m128i b, int imm);
VPCMPUQ __mmask8 _mm_mask_cmp_epu64_mask(__mmask8 k, __m128i a, __m128i b, int imm);
VPCMPUQ __mmask8 _mm_cmp[eq|ge|gt|le|lt|neq]_epu64_mask( __m128i a, __m128i b);
VPCMPUQ __mmask8 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epu64_mask(__mmask8 k, __m128i a, __m128i b);
SIMD Floating-Point Exceptions
None
Other Exceptions
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPCMPQ/VPCMPUQ-Compare Packed Integer Values Into Mask
Vol. 2C
5-464

VPCMPW/VPCMPUW-Compare Packed Word Values Into Mask
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F3A.W1 3F /r ib
A
V/V
(AVX512VL AND
Compare packed signed word integers in
VPCMPW k1 {k2}, xmm2,
AVX512BW) OR
xmm3/m128 and xmm2 using bits 2:0 of imm8 as a
xmm3/m128, imm8
AVX10.1
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.256.66.0F3A.W1 3F /r ib
A
V/V
(AVX512VL AND
Compare packed signed word integers in
VPCMPW k1 {k2}, ymm2,
AVX512BW) OR
ymm3/m256 and ymm2 using bits 2:0 of imm8 as a
ymm3/m256, imm8
AVX10.1
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.512.66.0F3A.W1 3F /r ib
A
V/V
AVX512BW
Compare packed signed word integers in
VPCMPW k1 {k2}, zmm2,
OR AVX10.1
zmm3/m512 and zmm2 using bits 2:0 of imm8 as a
zmm3/m512, imm8
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.128.66.0F3A.W1 3E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned word integers in
VPCMPUW k1 {k2}, xmm2,
AVX512BW) OR
xmm3/m128 and xmm2 using bits 2:0 of imm8 as a
xmm3/m128, imm8
AVX10.1
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.256.66.0F3A.W1 3E /r ib
A
V/V
(AVX512VL AND
Compare packed unsigned word integers in
VPCMPUW k1 {k2}, ymm2,
AVX512BW) OR
ymm3/m256 and ymm2 using bits 2:0 of imm8 as a
ymm3/m256, imm8
AVX10.1
comparison predicate with writemask k2 and leave
the result in mask register k1.
EVEX.512.66.0F3A.W1 3E /r ib
A
V/V
AVX512BW
Compare packed unsigned word integers in
VPCMPUW k1 {k2}, zmm2,
OR AVX10.1
zmm3/m512 and zmm2 using bits 2:0 of imm8 as a
zmm3/m512, imm8
comparison predicate with writemask k2 and leave
the result in mask register k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed integer word in the second source operand and the first source operand
and returns the results of the comparison to the mask destination operand. The comparison predicate operand
(immediate byte) specifies the type of comparison performed on each pair of packed values in the two source oper-
ands. The result of each comparison is a single mask bit result of 1 (comparison true) or 0 (comparison false).
VPCMPW performs a comparison between pairs of signed word values.
VPCMPUW performs a comparison between pairs of unsigned word values.
The first source operand (second operand) is a ZMM/YMM/XMM register. The second source operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location. The destination operand (first operand) is a mask
register k1. Up to 32/16/8 comparisons are performed with results written to the destination operand under the
writemask k2.
The comparison predicate operand is an 8-bit immediate: bits 2:0 define the type of comparison to be performed.
Bits 3 through 7 of the immediate are reserved. Compiler can implement the pseudo-op mnemonic listed in Table
5-19.
VPCMPW/VPCMPUW-Compare Packed Word Values Into Mask
Vol. 2C
5-465
Operation
CASE (COMPARISON PREDICATE) OF
0: OP := EQ;
1: OP := LT;
2: OP := LE;
3: OP := FALSE;
4: OP := NEQ;
5: OP := NLT;
6: OP := NLE;
7: OP := TRUE;
ESAC;
VPCMPW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k2[j] OR *no writemask*
THEN
ICMP := SRC1[i+15:i] OP SRC2[i+15:i];
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] = 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPUW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k2[j] OR *no writemask*
THEN
CMP := SRC1[i+15:i] OP SRC2[i+15:i];
IF CMP = TRUE
THEN DEST[j] := 1;
ELSE DEST[j] := 0; FI;
ELSE
DEST[j] = 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
VPCMPW/VPCMPUW-Compare Packed Word Values Into Mask
Vol. 2C
5-466
Intel C/C++ Compiler Intrinsic Equivalent
VPCMPW __mmask32 _mm512_cmp_epi16_mask( __m512i a, __m512i b, int cmp);
VPCMPW __mmask32 _mm512_mask_cmp_epi16_mask( __mmask32 m, __m512i a, __m512i b, int cmp);
VPCMPW __mmask16 _mm256_cmp_epi16_mask( __m256i a, __m256i b, int cmp);
VPCMPW __mmask16 _mm256_mask_cmp_epi16_mask( __mmask16 m, __m256i a, __m256i b, int cmp);
VPCMPW __mmask8 _mm_cmp_epi16_mask( __m128i a, __m128i b, int cmp);
VPCMPW __mmask8 _mm_mask_cmp_epi16_mask( __mmask8 m, __m128i a, __m128i b, int cmp);
VPCMPW __mmask32 _mm512_cmp[eq|ge|gt|le|lt|neq]_epi16_mask( __m512i a, __m512i b);
VPCMPW __mmask32 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epi16_mask( __mmask32 m, __m512i a, __m512i b);
VPCMPW __mmask16 _mm256_cmp[eq|ge|gt|le|lt|neq]_epi16_mask( __m256i a, __m256i b);
VPCMPW __mmask16 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epi16_mask( __mmask16 m, __m256i a, __m256i b);
VPCMPW __mmask8 _mm_cmp[eq|ge|gt|le|lt|neq]_epi16_mask( __m128i a, __m128i b);
VPCMPW __mmask8 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epi16_mask( __mmask8 m, __m128i a, __m128i b);
VPCMPUW __mmask32 _mm512_cmp_epu16_mask( __m512i a, __m512i b, int cmp);
VPCMPUW __mmask32 _mm512_mask_cmp_epu16_mask( __mmask32 m, __m512i a, __m512i b, int cmp);
VPCMPUW __mmask16 _mm256_cmp_epu16_mask( __m256i a, __m256i b, int cmp);
VPCMPUW __mmask16 _mm256_mask_cmp_epu16_mask( __mmask16 m, __m256i a, __m256i b, int cmp);
VPCMPUW __mmask8 _mm_cmp_epu16_mask( __m128i a, __m128i b, int cmp);
VPCMPUW __mmask8 _mm_mask_cmp_epu16_mask( __mmask8 m, __m128i a, __m128i b, int cmp);
VPCMPUW __mmask32 _mm512_cmp[eq|ge|gt|le|lt|neq]_epu16_mask( __m512i a, __m512i b, int cmp);
VPCMPUW __mmask32 _mm512_mask_cmp[eq|ge|gt|le|lt|neq]_epu16_mask( __mmask32 m, __m512i a, __m512i b, int cmp);
VPCMPUW __mmask16 _mm256_cmp[eq|ge|gt|le|lt|neq]_epu16_mask( __m256i a, __m256i b, int cmp);
VPCMPUW __mmask16 _mm256_mask_cmp[eq|ge|gt|le|lt|neq]_epu16_mask( __mmask16 m, __m256i a, __m256i b, int cmp);
VPCMPUW __mmask8 _mm_cmp[eq|ge|gt|le|lt|neq]_epu16_mask( __m128i a, __m128i b, int cmp);
VPCMPUW __mmask8 _mm_mask_cmp[eq|ge|gt|le|lt|neq]_epu16_mask( __mmask8 m, __m128i a, __m128i b, int cmp);
SIMD Floating-Point Exceptions
None
Other Exceptions
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPCMPW/VPCMPUW-Compare Packed Word Values Into Mask
Vol. 2C
5-467

VPCOMPRESSB/VCOMPRESSW-Store Sparse Packed Byte/Word Integer Values Into Dense
Memory/Register
Opcode/
Op/
64/32
CPUID Feature Flag
Description
Instruction
En
bit Mode
Support
EVEX.128.66.0F38.W0 63 /r
A
V/V
(AVX512_VBMI2 AND
Compress up to 128 bits of packed byte
VPCOMPRESSB m128{k1}, xmm1
AVX512VL) OR
values from xmm1 to m128 with
AVX10.1
writemask k1.
EVEX.128.66.0F38.W0 63 /r
B
V/V
(AVX512_VBMI2 AND
Compress up to 128 bits of packed byte
VPCOMPRESSB xmm1{k1}{z}, xmm2
AVX512VL) OR
values from xmm2 to xmm1 with
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 63 /r
A
V/V
(AVX512_VBMI2 AND
Compress up to 256 bits of packed byte
VPCOMPRESSB m256{k1}, ymm1
AVX512VL) OR
values from ymm1 to m256 with
AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 63 /r
B
V/V
(AVX512_VBMI2 AND
Compress up to 256 bits of packed byte
VPCOMPRESSB ymm1{k1}{z}, ymm2
AVX512VL) OR
values from ymm2 to ymm1 with
AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 63 /r
A
V/V
AVX512_VBMI2
Compress up to 512 bits of packed byte
VPCOMPRESSB m512{k1}, zmm1
OR AVX10.1
values from zmm1 to m512 with writemask
k1.
EVEX.512.66.0F38.W0 63 /r
B
V/V
AVX512_VBMI2
Compress up to 512 bits of packed byte
VPCOMPRESSB zmm1{k1}{z}, zmm2
OR AVX10.1
values from zmm2 to zmm1 with
writemask k1.
EVEX.128.66.0F38.W1 63 /r
A
V/V
(AVX512_VBMI2 AND
Compress up to 128 bits of packed word
VPCOMPRESSW m128{k1}, xmm1
AVX512VL) OR
values from xmm1 to m128 with
AVX10.1
writemask k1.
EVEX.128.66.0F38.W1 63 /r
B
V/V
(AVX512_VBMI2 AND
Compress up to 128 bits of packed word
VPCOMPRESSW xmm1{k1}{z}, xmm2
AVX512VL) OR
values from xmm2 to xmm1 with
AVX10.1
writemask k1.
EVEX.256.66.0F38.W1 63 /r
A
V/V
(AVX512_VBMI2 AND
Compress up to 256 bits of packed word
VPCOMPRESSW m256{k1}, ymm1
AVX512VL) OR
values from ymm1 to m256 with
AVX10.1
writemask k1.
EVEX.256.66.0F38.W1 63 /r
B
V/V
(AVX512_VBMI2 AND
Compress up to 256 bits of packed word
VPCOMPRESSW ymm1{k1}{z}, ymm2
AVX512VL) OR
values from ymm2 to ymm1 with
AVX10.1
writemask k1.
EVEX.512.66.0F38.W1 63 /r
A
V/V
AVX512_VBMI2
Compress up to 512 bits of packed word
VPCOMPRESSW m512{k1}, zmm1
OR AVX10.1
values from zmm1 to m512 with writemask
k1.
EVEX.512.66.0F38.W1 63 /r
B
V/V
AVX512_VBMI2
Compress up to 512 bits of packed word
VPCOMPRESSW zmm1{k1}{z}, zmm2
OR AVX10.1
values from zmm2 to zmm1 with
writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
B
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Compress (stores) up to 64 byte values or 32 word values from the source operand (second operand) to the desti-
nation operand (first operand), based on the active elements determined by the writemask operand. Note:
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
VPCOMPRESSB/VCOMPRESSW-Store Sparse Packed Byte/Word Integer Values Into Dense Memory/Register
Vol. 2C
5-468
Moves up to 512 bits of packed byte values from the source operand (second operand) to the destination operand
(first operand). This instruction is used to store partial contents of a vector register into a byte vector or single
memory location using the active elements in operand writemask.
Memory destination version: Only the contiguous vector is written to the destination memory location. EVEX.z
must be zero.
Register destination version: If the vector length of the contiguous vector is less than that of the input vector in the
source operand, the upper bits of the destination register are unmodified if EVEX.z is not set, otherwise the upper
bits are zeroed.
This instruction supports memory fault suppression.
Note that the compressed displacement assumes a pre-scaling (N) corresponding to the size of one single element
instead of the size of the full vector.
Operation
VPCOMPRESSB store form
(KL, VL) = (16, 128), (32, 256), (64, 512)
k := 0
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
DEST.byte[k] := SRC.byte[j]
k := k +1
VPCOMPRESSB reg-reg form
(KL, VL) = (16, 128), (32, 256), (64, 512)
k := 0
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
DEST.byte[k] := SRC.byte[j]
k := k + 1
IF *merging-masking*:
*DEST[VL-1:k*8] remains unchanged*
ELSE DEST[VL-1:k*8] := 0
DEST[MAX_VL-1:VL] := 0
VPCOMPRESSW store form
(KL, VL) = (8, 128), (16, 256), (32, 512)
k := 0
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
DEST.word[k] := SRC.word[j]
k := k + 1
VPCOMPRESSB/VCOMPRESSW-Store Sparse Packed Byte/Word Integer Values Into Dense Memory/Register
Vol. 2C
5-469
VPCOMPRESSW reg-reg form
(KL, VL) = (8, 128), (16, 256), (32, 512)
k := 0
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
DEST.word[k] := SRC.word[j]
k := k + 1
IF *merging-masking*:
*DEST[VL-1:k*16] remains unchanged*
ELSE DEST[VL-1:k*16] := 0
DEST[MAX_VL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPCOMPRESSB __m128i _mm_mask_compress_epi8(__m128i, __mmask16, __m128i);
VPCOMPRESSB __m128i _mm_maskz_compress_epi8(__mmask16, __m128i);
VPCOMPRESSB __m256i _mm256_mask_compress_epi8(__m256i, __mmask32, __m256i);
VPCOMPRESSB __m256i _mm256_maskz_compress_epi8(__mmask32, __m256i);
VPCOMPRESSB __m512i _mm512_mask_compress_epi8(__m512i, __mmask64, __m512i);
VPCOMPRESSB __m512i _mm512_maskz_compress_epi8(__mmask64, __m512i);
VPCOMPRESSB void _mm_mask_compressstoreu_epi8(void*, __mmask16, __m128i);
VPCOMPRESSB void _mm256_mask_compressstoreu_epi8(void*, __mmask32, __m256i);
VPCOMPRESSB void _mm512_mask_compressstoreu_epi8(void*, __mmask64, __m512i);
VPCOMPRESSW __m128i _mm_mask_compress_epi16(__m128i, __mmask8, __m128i);
VPCOMPRESSW __m128i _mm_maskz_compress_epi16(__mmask8, __m128i);
VPCOMPRESSW __m256i _mm256_mask_compress_epi16(__m256i, __mmask16, __m256i);
VPCOMPRESSW __m256i _mm256_maskz_compress_epi16(__mmask16, __m256i);
VPCOMPRESSW __m512i _mm512_mask_compress_epi16(__m512i, __mmask32, __m512i);
VPCOMPRESSW __m512i _mm512_maskz_compress_epi16(__mmask32, __m512i);
VPCOMPRESSW void _mm_mask_compressstoreu_epi16(void*, __mmask8, __m128i);
VPCOMPRESSW void _mm256_mask_compressstoreu_epi16(void*, __mmask16, __m256i);
VPCOMPRESSW void _mm512_mask_compressstoreu_epi16(void*, __mmask32, __m512i);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
VPCOMPRESSB/VCOMPRESSW-Store Sparse Packed Byte/Word Integer Values Into Dense Memory/Register
Vol. 2C
5-470

VPCOMPRESSD-Store Sparse Packed Doubleword Integer Values Into Dense Memory/Register
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 8B /r
A
V/V
(AVX512VL AND
Compress packed doubleword integer
VPCOMPRESSD xmm1/m128 {k1}{z}, xmm2
AVX512F) OR
values from xmm2 to xmm1/m128 using
AVX10.1
control mask k1.
EVEX.256.66.0F38.W0 8B /r
A
V/V
(AVX512VL AND
Compress packed doubleword integer
VPCOMPRESSD ymm1/m256 {k1}{z}, ymm2
AVX512F) OR
values from ymm2 to ymm1/m256 using
AVX10.1
control mask k1.
EVEX.512.66.0F38.W0 8B /r
A
V/V
AVX512F
Compress packed doubleword integer
VPCOMPRESSD zmm1/m512 {k1}{z}, zmm2
OR AVX10.1
values from zmm2 to zmm1/m512 using
control mask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Compress (store) up to 16/8/4 doubleword integer values from the source operand (second operand) to the desti-
nation operand (first operand). The source operand is a ZMM/YMM/XMM register, the destination operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location.
The opmask register k1 selects the active elements (partial vector or possibly non-contiguous if less than 16 active
elements) from the source operand to compress into a contiguous vector. The contiguous vector is written to the
destination starting from the low element of the destination operand.
Memory destination version: Only the contiguous vector is written to the destination memory location. EVEX.z
must be zero.
Register destination version: If the vector length of the contiguous vector is less than that of the input vector in the
source operand, the upper bits of the destination register are unmodified if EVEX.z is not set, otherwise the upper
bits are zeroed.
Note: EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Note that the compressed displacement assumes a pre-scaling (N) corresponding to the size of one single element
instead of the size of the full vector.
VPCOMPRESSD-Store Sparse Packed Doubleword Integer Values Into Dense Memory/Register
Vol. 2C
5-471
Operation
VPCOMPRESSD (EVEX encoded versions) store form
(KL, VL) = (4, 128), (8, 256), (16, 512)
SIZE := 32
k := 0
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no controlmask*
THEN
DEST[k+SIZE-1:k] := SRC[i+31:i]
k := k + SIZE
FI;
ENDFOR;
VPCOMPRESSD (EVEX encoded versions) reg-reg form
(KL, VL) = (4, 128), (8, 256), (16, 512)
SIZE := 32
k := 0
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no controlmask*
THEN
DEST[k+SIZE-1:k] := SRC[i+31:i]
k := k + SIZE
FI;
ENDFOR
IF *merging-masking*
THEN *DEST[VL-1:k] remains unchanged*
ELSE DEST[VL-1:k] := 0
FI
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPCOMPRESSD __m512i _mm512_mask_compress_epi32(__m512i s, __mmask16 c, __m512i a);
VPCOMPRESSD __m512i _mm512_maskz_compress_epi32( __mmask16 c, __m512i a);
VPCOMPRESSD void _mm512_mask_compressstoreu_epi32(void * a, __mmask16 c, __m512i s);
VPCOMPRESSD __m256i _mm256_mask_compress_epi32(__m256i s, __mmask8 c, __m256i a);
VPCOMPRESSD __m256i _mm256_maskz_compress_epi32( __mmask8 c, __m256i a);
VPCOMPRESSD void _mm256_mask_compressstoreu_epi32(void * a, __mmask8 c, __m256i s);
VPCOMPRESSD __m128i _mm_mask_compress_epi32(__m128i s, __mmask8 c, __m128i a);
VPCOMPRESSD __m128i _mm_maskz_compress_epi32( __mmask8 c, __m128i a);
VPCOMPRESSD void _mm_mask_compressstoreu_epi32(void * a, __mmask8 c, __m128i s);
SIMD Floating-Point Exceptions
None.
Other Exceptions
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPCOMPRESSD-Store Sparse Packed Doubleword Integer Values Into Dense Memory/Register
Vol. 2C
5-472

VPCOMPRESSQ-Store Sparse Packed Quadword Integer Values Into Dense Memory/Register
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W1 8B /r
A
V/V
(AVX512VL AND
Compress packed quadword integer values
VPCOMPRESSQ xmm1/m128 {k1}{z}, xmm2
AVX512F) OR
from xmm2 to xmm1/m128 using control
AVX10.1
mask k1.
EVEX.256.66.0F38.W1 8B /r
A
V/V
(AVX512VL AND
Compress packed quadword integer values
VPCOMPRESSQ ymm1/m256 {k1}{z}, ymm2
AVX512F) OR
from ymm2 to ymm1/m256 using control
AVX10.1
mask k1.
EVEX.512.66.0F38.W1 8B /r
A
V/V
AVX512F
Compress packed quadword integer values
VPCOMPRESSQ zmm1/m512 {k1}{z}, zmm2
OR AVX10.1
from zmm2 to zmm1/m512 using control
mask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Compress (stores) up to 8/4/2 quadword integer values from the source operand (second operand) to the destina-
tion operand (first operand). The source operand is a ZMM/YMM/XMM register, the destination operand can be a
ZMM/YMM/XMM register or a 512/256/128-bit memory location.
The opmask register k1 selects the active elements (partial vector or possibly non-contiguous if less than 8 active
elements) from the source operand to compress into a contiguous vector. The contiguous vector is written to the
destination starting from the low element of the destination operand.
Memory destination version: Only the contiguous vector is written to the destination memory location. EVEX.z
must be zero.
Register destination version: If the vector length of the contiguous vector is less than that of the input vector in the
source operand, the upper bits of the destination register are unmodified if EVEX.z is not set, otherwise the upper
bits are zeroed.
Note: EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Note that the compressed displacement assumes a pre-scaling (N) corresponding to the size of one single element
instead of the size of the full vector.
VPCOMPRESSQ-Store Sparse Packed Quadword Integer Values Into Dense Memory/Register
Vol. 2C
5-473
Operation
VPCOMPRESSQ (EVEX encoded versions) store form
(KL, VL) = (2, 128), (4, 256), (8, 512)
SIZE := 64
k := 0
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no controlmask*
THEN
DEST[k+SIZE-1:k] := SRC[i+63:i]
k := k + SIZE
FI;
ENFOR
VPCOMPRESSQ (EVEX encoded versions) reg-reg form
(KL, VL) = (2, 128), (4, 256), (8, 512)
SIZE := 64
k := 0
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no controlmask*
THEN
DEST[k+SIZE-1:k] := SRC[i+63:i]
k := k + SIZE
FI;
ENDFOR
IF *merging-masking*
THEN *DEST[VL-1:k] remains unchanged*
ELSE DEST[VL-1:k] := 0
FI
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPCOMPRESSQ __m512i _mm512_mask_compress_epi64(__m512i s, __mmask8 c, __m512i a);
VPCOMPRESSQ __m512i _mm512_maskz_compress_epi64( __mmask8 c, __m512i a);
VPCOMPRESSQ void _mm512_mask_compressstoreu_epi64(void * a, __mmask8 c, __m512i s);
VPCOMPRESSQ __m256i _mm256_mask_compress_epi64(__m256i s, __mmask8 c, __m256i a);
VPCOMPRESSQ __m256i _mm256_maskz_compress_epi64( __mmask8 c, __m256i a);
VPCOMPRESSQ void _mm256_mask_compressstoreu_epi64(void * a, __mmask8 c, __m256i s);
VPCOMPRESSQ __m128i _mm_mask_compress_epi64(__m128i s, __mmask8 c, __m128i a);
VPCOMPRESSQ __m128i _mm_maskz_compress_epi64( __mmask8 c, __m128i a);
VPCOMPRESSQ void _mm_mask_compressstoreu_epi64(void * a, __mmask8 c, __m128i s);
SIMD Floating-Point Exceptions
None.
Other Exceptions
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
VPCOMPRESSQ-Store Sparse Packed Quadword Integer Values Into Dense Memory/Register
Vol. 2C
5-474

VPCONFLICTD/Q-Detect Conflicts Within a Vector of Packed Dword/Qword Values Into Dense
Memory/ Register
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 C4 /r
A
V/V
(AVX512VL AND
Detect duplicate double-word values in
VPCONFLICTD xmm1 {k1}{z},
AVX512CD) OR
xmm2/m128/m32bcst using writemask k1.
xmm2/m128/m32bcst
AVX10.1
EVEX.256.66.0F38.W0 C4 /r
A
V/V
(AVX512VL AND
Detect duplicate double-word values in
VPCONFLICTD ymm1 {k1}{z},
AVX512CD) OR
ymm2/m256/m32bcst using writemask k1.
ymm2/m256/m32bcst
AVX10.1
EVEX.512.66.0F38.W0 C4 /r
A
V/V
AVX512CD
Detect duplicate double-word values in
VPCONFLICTD zmm1 {k1}{z},
OR AVX10.1
zmm2/m512/m32bcst using writemask k1.
zmm2/m512/m32bcst
EVEX.128.66.0F38.W1 C4 /r
A
V/V
(AVX512VL AND
Detect duplicate quad-word values in
VPCONFLICTQ xmm1 {k1}{z},
AVX512CD) OR
xmm2/m128/m64bcst using writemask k1.
xmm2/m128/m64bcst
AVX10.1
EVEX.256.66.0F38.W1 C4 /r
A
V/V
(AVX512VL AND
Detect duplicate quad-word values in
VPCONFLICTQ ymm1 {k1}{z},
AVX512CD) OR
ymm2/m256/m64bcst using writemask k1.
ymm2/m256/m64bcst
AVX10.1
EVEX.512.66.0F38.W1 C4 /r
A
V/V
AVX512CD
Detect duplicate quad-word values in
VPCONFLICTQ zmm1 {k1}{z},
OR AVX10.1
zmm2/m512/m64bcst using writemask k1.
zmm2/m512/m64bcst
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Test each dword/qword element of the source operand (the second operand) for equality with all other elements in
the source operand closer to the least significant element. Each element’s comparison results form a bit vector,
which is then zero extended and written to the destination according to the writemask.
EVEX.512 encoded version: The source operand is a ZMM register, a 512-bit memory location, or a 512-bit vector
broadcasted from a 32/64-bit memory location. The destination operand is a ZMM register, conditionally updated
using writemask k1.
EVEX.256 encoded version: The source operand is a YMM register, a 256-bit memory location, or a 256-bit vector
broadcasted from a 32/64-bit memory location. The destination operand is a YMM register, conditionally updated
using writemask k1.
EVEX.128 encoded version: The source operand is a XMM register, a 128-bit memory location, or a 128-bit vector
broadcasted from a 32/64-bit memory location. The destination operand is a XMM register, conditionally updated
using writemask k1.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
VPCONFLICTD/Q-Detect Conflicts Within a Vector of Packed Dword/Qword Values Into Dense Memory/ Register
Vol. 2C
5-475
Operation
VPCONFLICTD
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j*32
IF MaskBit(j) OR *no writemask* THEN
FOR k := 0 TO j-1
m := k*32
IF ((SRC[i+31:i] = SRC[m+31:m])) THEN
DEST[i+k] := 1
ELSE
DEST[i+k] := 0
FI
ENDFOR
DEST[i+31:i+j] := 0
ELSE
IF *merging-masking* THEN
*DEST[i+31:i] remains unchanged*
ELSE
DEST[i+31:i] := 0
FI
FI
ENDFOR
DEST[MAXVL-1:VL] := 0
VPCONFLICTQ
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j*64
IF MaskBit(j) OR *no writemask* THEN
FOR k := 0 TO j-1
m := k*64
IF ((SRC[i+63:i] = SRC[m+63:m])) THEN
DEST[i+k] := 1
ELSE
DEST[i+k] := 0
FI
ENDFOR
DEST[i+63:i+j] := 0
ELSE
IF *merging-masking* THEN
*DEST[i+63:i] remains unchanged*
ELSE
DEST[i+63:i] := 0
FI
FI
ENDFOR
DEST[MAXVL-1:VL] := 0
VPCONFLICTD/Q-Detect Conflicts Within a Vector of Packed Dword/Qword Values Into Dense Memory/ Register
Vol. 2C
5-476
Intel C/C++ Compiler Intrinsic Equivalent
VPCONFLICTD __m512i _mm512_conflict_epi32( __m512i a);
VPCONFLICTD __m512i _mm512_mask_conflict_epi32(__m512i s, __mmask16 m, __m512i a);
VPCONFLICTD __m512i _mm512_maskz_conflict_epi32(__mmask16 m, __m512i a);
VPCONFLICTQ __m512i _mm512_conflict_epi64( __m512i a);
VPCONFLICTQ __m512i _mm512_mask_conflict_epi64(__m512i s, __mmask8 m, __m512i a);
VPCONFLICTQ __m512i _mm512_maskz_conflict_epi64(__mmask8 m, __m512i a);
VPCONFLICTD __m256i _mm256_conflict_epi32( __m256i a);
VPCONFLICTD __m256i _mm256_mask_conflict_epi32(__m256i s, __mmask8 m, __m256i a);
VPCONFLICTD __m256i _mm256_maskz_conflict_epi32(__mmask8 m, __m256i a);
VPCONFLICTQ __m256i _mm256_conflict_epi64( __m256i a);
VPCONFLICTQ __m256i _mm256_mask_conflict_epi64(__m256i s, __mmask8 m, __m256i a);
VPCONFLICTQ __m256i _mm256_maskz_conflict_epi64(__mmask8 m, __m256i a);
VPCONFLICTD __m128i _mm_conflict_epi32( __m128i a);
VPCONFLICTD __m128i _mm_mask_conflict_epi32(__m128i s, __mmask8 m, __m128i a);
VPCONFLICTD __m128i _mm_maskz_conflict_epi32(__mmask8 m, __m128i a);
VPCONFLICTQ __m128i _mm_conflict_epi64( __m128i a);
VPCONFLICTQ __m128i _mm_mask_conflict_epi64(__m128i s, __mmask8 m, __m128i a);
VPCONFLICTQ __m128i _mm_maskz_conflict_epi64(__mmask8 m, __m128i a);
SIMD Floating-Point Exceptions
None
Other Exceptions
EVEX-encoded instruction, see Table 2-52, “Type E4NF Class Exception Conditions.”
VPCONFLICTD/Q-Detect Conflicts Within a Vector of Packed Dword/Qword Values Into Dense Memory/ Register
Vol. 2C
5-477

VPDPB[SU,UU,SS]D[,S]-Multiply and Add Unsigned and Signed Bytes With and Without
Saturation
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.F2.0F38.W0 50 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of signed bytes in
xmm3/m128 with corresponding signed bytes
VPDPBSSD xmm1, xmm2,
of xmm2, summing those products and adding
xmm3/m128
them to the doubleword result in xmm1.
VEX.256.F2.0F38.W0 50 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of signed bytes in
ymm3/m256 with corresponding signed bytes
VPDPBSSD ymm1, ymm2,
of ymm2, summing those products and adding
ymm3/m256
them to the doubleword result in ymm1.
VEX.128.F2.0F38.W0 51 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of signed bytes in
xmm3/m128 with corresponding signed bytes
VPDPBSSDS xmm1, xmm2,
of xmm2, summing those products and adding
xmm3/m128
them to the doubleword result, with signed
saturation in xmm1.
VEX.256.F2.0F38.W0 51 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of signed bytes in
ymm3/m256 with corresponding signed bytes
VPDPBSSDS ymm1, ymm2,
of ymm2, summing those products and adding
ymm3/m256
them to the doubleword result, with signed
saturation in ymm1.
VEX.128.F3.0F38.W0 50 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
xmm3/m128 with corresponding signed bytes
VPDPBSUD xmm1, xmm2,
of xmm2, summing those products and adding
xmm3/m128
them to doubleword result in xmm1.
VEX.256.F3.0F38.W0 50 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
ymm3/m256 with corresponding signed bytes
VPDPBSUD ymm1, ymm2,
of ymm2, summing those products and adding
ymm3/m256
them to doubleword result in ymm1.
VEX.128.F3.0F38.W0 51 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
xmm3/m128 with corresponding signed bytes
VPDPBSUDS xmm1, xmm2,
of xmm2, summing those products and adding
xmm3/m128
them to doubleword result, with signed
saturation in xmm1.
VEX.256.F3.0F38.W0 51 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
ymm3/m256 with corresponding signed bytes
VPDPBSUDS ymm1, ymm2,
of ymm2, summing those products and adding
ymm3/m256
them to doubleword result, with signed
saturation in ymm1.
VEX.128.NP.0F38.W0 50 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
xmm3/m128 with corresponding unsigned
VPDPBUUD xmm1, xmm2,
bytes of xmm2, summing those products and
xmm3/m128
adding them to doubleword result in xmm1.
VEX.256.NP.0F38.W0 50 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
ymm3/m256 with corresponding unsigned
VPDPBUUD ymm1, ymm2,
bytes of ymm2, summing those products and
ymm3/m256
adding them to doubleword result in ymm1.
VPDPB[SU,UU,SS]D[,S]-Multiply and Add Unsigned and Signed Bytes With and Without Saturation
Vol. 2C
5-478

Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.NP.0F38.W0 51 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
xmm3/m128 with corresponding unsigned
VPDPBUUDS xmm1, xmm2,
bytes of xmm2, summing those products and
xmm3/m128
adding them to the doubleword result, with
unsigned saturation in xmm1.
VEX.256.NP.0F38.W0 51 /r
A
V/V
AVX_VNNI_INT8
Multiply groups of 4 pairs of unsigned bytes in
ymm3/m256 with corresponding unsigned
VPDPBUUDS ymm1, ymm2,
bytes of ymm2, summing those products and
ymm3/m256
adding them to the doubleword result, with
unsigned saturation in ymm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual bytes of the first source operand by the corresponding bytes of the second source operand,
producing intermediate word results. The word results are then summed and accumulated in the destination dword
element size operand.
For unsigned saturation, when an individual result value is beyond the range of an unsigned doubleword (that is,
greater than FFFFF_FFFFH), the saturated unsigned doubleword integer value of FFFF_FFFFH is stored in the
doubleword destination.
For signed saturation, when an individual result is beyond the range of a signed doubleword integer (that is,
greater than 7FFF_FFFFH or less than 8000_0000H), the saturated value of 7FFF_FFFFH or 8000_0000H, respec-
tively, is written to the destination operand.
Operation
VPDPB[SU,UU,SS]D[,S] dest, src1, src2 (VEX encoded version)
VL = (128, 256)
KL = VL/32
ORIGDEST := DEST
FOR i := 0 TO KL-1:
IF *src1 is signed*:
src1extend := SIGN_EXTEND // SU, SS
ELSE:
src1extend := ZERO_EXTEND // UU
IF *src2 is signed*:
src2extend := SIGN_EXTEND // SS
ELSE:
src2extend := ZERO_EXTEND // UU, SU
p1word := src1extend(SRC1.byte[4*i+0]) * src2extend(SRC2.byte[4*i+0])
p2word := src1extend(SRC1.byte[4*i+1]) * src2extend(SRC2.byte[4*i+1])
p3word := src1extend(SRC1.byte[4*i+2]) * src2extend(SRC2.byte[4*i+2])
p4word := src1extend(SRC1.byte[4*i+3]) * src2extend(SRC2.byte[4*i+3])
IF *saturating*:
VPDPB[SU,UU,SS]D[,S]-Multiply and Add Unsigned and Signed Bytes With and Without Saturation
Vol. 2C
5-479
IF *UU instruction version*:
DEST.dword[i] := UNSIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1word + p2word + p3word + p4word)
ELSE:
DEST.dword[i] := SIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1word + p2word + p3word + p4word)
ELSE:
DEST.dword[i] := ORIGDEST.dword[i] + p1word + p2word + p3word + p4word
DEST[MAXVL-1:VL] := 0
Flags Affected
None.
Intel C/C++ Compiler Intrinsic Equivalent
VPDPBSSD __m128i _mm_dpbssd_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPBSSD __m256i _mm256_dpbssd_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPBSSDS __m128i _mm_dpbssds_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPBSSDS __m256i _mm256_dpbssds_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPBSUD __m128i _mm_dpbsud_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPBSUD __m256i _mm256_dpbsud_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPBSUDS __m128i _mm_dpbsuds_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPBSUDS __m256i _mm256_dpbsuds_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPBUUD __m128i _mm_dpbuud_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPBUUD __m256i _mm256_dpbuud_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPBUUDS __m128i _mm_dpbuuds_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPBUUDS __m256i _mm256_dpbuuds_epi32 (__m256i __W, __m256i __A, __m256i __B);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-21, “Type 4 Class Exception Conditions.”
VPDPB[SU,UU,SS]D[,S]-Multiply and Add Unsigned and Signed Bytes With and Without Saturation
Vol. 2C
5-480

VPDPBUSD-Multiply and Add Unsigned and Signed Bytes
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 50 /r
A
V/V
AVX_VNNI
Multiply groups of 4 pairs of signed bytes in
VPDPBUSD xmm1, xmm2,
xmm3/m128 with corresponding unsigned bytes of
xmm3/m128
xmm2, summing those products and adding them
to doubleword result in xmm1.
VEX.256.66.0F38.W0 50 /r
A
V/V
AVX_VNNI
Multiply groups of 4 pairs of signed bytes in
VPDPBUSD ymm1, ymm2,
ymm3/m256 with corresponding unsigned bytes of
ymm3/m256
ymm2, summing those products and adding them
to doubleword result in ymm1.
EVEX.128.66.0F38.W0 50 /r
B
V/V
(AVX512_VNNI
Multiply groups of 4 pairs of signed bytes in
VPDPBUSD xmm1{k1}{z}, xmm2,
AND AVX512VL)
xmm3/m128/m32bcst with corresponding
xmm3/m128/m32bcst
OR AVX10.1
unsigned bytes of xmm2, summing those products
and adding them to doubleword result in xmm1
under writemask k1.
EVEX.256.66.0F38.W0 50 /r
B
V/V
(AVX512_VNNI
Multiply groups of 4 pairs of signed bytes in
VPDPBUSD ymm1{k1}{z}, ymm2,
AND AVX512VL)
ymm3/m256/m32bcst with corresponding
ymm3/m256/m32bcst
OR AVX10.1
unsigned bytes of ymm2, summing those products
and adding them to doubleword result in ymm1
under writemask k1.
EVEX.512.66.0F38.W0 50 /r
B
V/V
AVX512_VNNI
Multiply groups of 4 pairs of signed bytes in
VPDPBUSD zmm1{k1}{z}, zmm2,
OR AVX10.1
zmm3/m512/m32bcst with corresponding
zmm3/m512/m32bcst
unsigned bytes of zmm2, summing those products
and adding them to doubleword result in zmm1
under writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual unsigned bytes of the first source operand by the corresponding signed bytes of the second
source operand, producing intermediate signed word results. The word results are then summed and accumulated
in the destination dword element size operand.
This instruction supports memory fault suppression.
VPDPBUSD-Multiply and Add Unsigned and Signed Bytes
Vol. 2C
5-481
Operation
VPDPBUSD dest, src1, src2 (VEX encoded versions)
VL=(128, 256)
KL=VL/32
ORIGDEST := DEST
FOR i := 0 TO KL-1:
// Extending to 16b
// src1extend := ZERO_EXTEND
// src2extend := SIGN_EXTEND
p1word := src1extend(SRC1.byte[4*i+0]) * src2extend(SRC2.byte[4*i+0])
p2word := src1extend(SRC1.byte[4*i+1]) * src2extend(SRC2.byte[4*i+1])
p3word := src1extend(SRC1.byte[4*i+2]) * src2extend(SRC2.byte[4*i+2])
p4word := src1extend(SRC1.byte[4*i+3]) * src2extend(SRC2.byte[4*i+3])
DEST.dword[i] := ORIGDEST.dword[i] + p1word + p2word + p3word + p4word
DEST[MAX_VL-1:VL] := 0
VPDPBUSD dest, src1, src2 (EVEX encoded versions)
(KL,VL)=(4,128), (8,256), (16,512)
ORIGDEST := DEST
FOR i := 0 TO KL-1:
IF k1[i] or *no writemask*:
// Byte elements of SRC1 are zero-extended to 16b and
// byte elements of SRC2 are sign extended to 16b before multiplication.
IF SRC2 is memory and EVEX.b == 1:
t := SRC2.dword[0]
ELSE:
t := SRC2.dword[i]
p1word := ZERO_EXTEND(SRC1.byte[4*i]) * SIGN_EXTEND(t.byte[0])
p2word := ZERO_EXTEND(SRC1.byte[4*i+1]) * SIGN_EXTEND(t.byte[1])
p3word := ZERO_EXTEND(SRC1.byte[4*i+2]) * SIGN_EXTEND(t.byte[2])
p4word := ZERO_EXTEND(SRC1.byte[4*i+3]) * SIGN_EXTEND(t.byte[3])
DEST.dword[i] := ORIGDEST.dword[i] + p1word + p2word + p3word + p4word
ELSE IF *zeroing*:
DEST.dword[i] := 0
ELSE:
// Merge masking, dest element unchanged
DEST.dword[i] := ORIGDEST.dword[i]
DEST[MAX_VL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPDPBUSD __m128i _mm_dpbusd_avx_epi32(__m128i, __m128i, __m128i);
VPDPBUSD __m128i _mm_dpbusd_epi32(__m128i, __m128i, __m128i);
VPDPBUSD __m128i _mm_mask_dpbusd_epi32(__m128i, __mmask8, __m128i, __m128i);
VPDPBUSD __m128i _mm_maskz_dpbusd_epi32(__mmask8, __m128i, __m128i, __m128i);
VPDPBUSD __m256i _mm256_dpbusd_avx_epi32(__m256i, __m256i, __m256i);
VPDPBUSD __m256i _mm256_dpbusd_epi32(__m256i, __m256i, __m256i);
VPDPBUSD __m256i _mm256_mask_dpbusd_epi32(__m256i, __mmask8, __m256i, __m256i);
VPDPBUSD __m256i _mm256_maskz_dpbusd_epi32(__mmask8, __m256i, __m256i, __m256i);
VPDPBUSD __m512i _mm512_dpbusd_epi32(__m512i, __m512i, __m512i);
VPDPBUSD __m512i _mm512_mask_dpbusd_epi32(__m512i, __mmask16, __m512i, __m512i);
VPDPBUSD __m512i _mm512_maskz_dpbusd_epi32(__mmask16, __m512i, __m512i, __m512i);
VPDPBUSD-Multiply and Add Unsigned and Signed Bytes
Vol. 2C
5-482
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPDPBUSD-Multiply and Add Unsigned and Signed Bytes
Vol. 2C
5-483

VPDPBUSDS-Multiply and Add Unsigned and Signed Bytes With Saturation
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 51 /r
A
V/V
AVX_VNNI
Multiply groups of 4 pairs signed bytes in
VPDPBUSDS xmm1, xmm2,
xmm3/m128 with corresponding unsigned
xmm3/m128
bytes of xmm2, summing those products and
adding them to doubleword result, with signed
saturation in xmm1.
VEX.256.66.0F38.W0 51 /r
A
V/V
AVX_VNNI
Multiply groups of 4 pairs signed bytes in
VPDPBUSDS ymm1, ymm2,
ymm3/m256 with corresponding unsigned
ymm3/m256
bytes of ymm2, summing those products and
adding them to doubleword result, with signed
saturation in ymm1.
EVEX.128.66.0F38.W0 51 /r
B
V/V
(AVX512_VNNI
Multiply groups of 4 pairs signed bytes in
VPDPBUSDS xmm1{k1}{z}, xmm2,
AND AVX512VL)
xmm3/m128/m32bcst with corresponding
xmm3/m128/m32bcst
OR AVX10.1
unsigned bytes of xmm2, summing those
products and adding them to doubleword
result, with signed saturation in xmm1, under
writemask k1.
EVEX.256.66.0F38.W0 51 /r
B
V/V
(AVX512_VNNI
Multiply groups of 4 pairs signed bytes in
VPDPBUSDS ymm1{k1}{z}, ymm2,
AND AVX512VL)
ymm3/m256/m32bcst with corresponding
ymm3/m256/m32bcst
OR AVX10.1
unsigned bytes of ymm2, summing those
products and adding them to doubleword
result, with signed saturation in ymm1, under
writemask k1.
EVEX.512.66.0F38.W0 51 /r
B
V/V
AVX512_VNNI
Multiply groups of 4 pairs signed bytes in
VPDPBUSDS zmm1{k1}{z}, zmm2,
OR AVX10.1
zmm3/m512/m32bcst with corresponding
zmm3/m512/m32bcst
unsigned bytes of zmm2, summing those
products and adding them to doubleword
result, with signed saturation in zmm1, under
writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual unsigned bytes of the first source operand by the corresponding signed bytes of the second
source operand, producing intermediate signed word results. The word results are then summed and accumulated
in the destination dword element size operand. If the intermediate sum overflows a 32b signed number the result
is saturated to either 0x7FFF_FFFF for positive numbers of 0x8000_0000 for negative numbers.
This instruction supports memory fault suppression.
VPDPBUSDS-Multiply and Add Unsigned and Signed Bytes With Saturation
Vol. 2C
5-484
Operation
VPDPBUSDS dest, src1, src2 (VEX encoded versions)
VL=(128, 256)
KL=VL/32
ORIGDEST := DEST
FOR i := 0 TO KL-1:
// Extending to 16b
// src1extend := ZERO_EXTEND
// src2extend := SIGN_EXTEND
p1word := src1extend(SRC1.byte[4*i+0]) * src2extend(SRC2.byte[4*i+0])
p2word := src1extend(SRC1.byte[4*i+1]) * src2extend(SRC2.byte[4*i+1])
p3word := src1extend(SRC1.byte[4*i+2]) * src2extend(SRC2.byte[4*i+2])
p4word := src1extend(SRC1.byte[4*i+3]) * src2extend(SRC2.byte[4*i+3])
DEST.dword[i] := SIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1word + p2word + p3word + p4word)
DEST[MAX_VL-1:VL] := 0
VPDPBUSDS dest, src1, src2 (EVEX encoded versions)
(KL,VL)=(4,128), (8,256), (16,512)
ORIGDEST := DEST
FOR i := 0 TO KL-1:
IF k1[i] or *no writemask*:
// Byte elements of SRC1 are zero-extended to 16b and
// byte elements of SRC2 are sign extended to 16b before multiplication.
IF SRC2 is memory and EVEX.b == 1:
t := SRC2.dword[0]
ELSE:
t := SRC2.dword[i]
p1word := ZERO_EXTEND(SRC1.byte[4*i]) * SIGN_EXTEND(t.byte[0])
p2word := ZERO_EXTEND(SRC1.byte[4*i+1]) * SIGN_EXTEND(t.byte[1])
p3word := ZERO_EXTEND(SRC1.byte[4*i+2]) * SIGN_EXTEND(t.byte[2])
p4word := ZERO_EXTEND(SRC1.byte[4*i+3]) *SIGN_EXTEND(t.byte[3])
DEST.dword[i] := SIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1word + p2word + p3word + p4word)
ELSE IF *zeroing*:
DEST.dword[i] := 0
ELSE:
// Merge masking, dest element unchanged
DEST.dword[i] := ORIGDEST.dword[i]
DEST[MAX_VL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPDPBUSDS __m128i _mm_dpbusds_avx_epi32(__m128i, __m128i, __m128i);
VPDPBUSDS __m128i _mm_dpbusds_epi32(__m128i, __m128i, __m128i);
VPDPBUSDS __m128i _mm_mask_dpbusds_epi32(__m128i, __mmask8, __m128i, __m128i);
VPDPBUSDS __m128i _mm_maskz_dpbusds_epi32(__mmask8, __m128i, __m128i, __m128i);
VPDPBUSDS __m256i _mm256_dpbusds_avx_epi32(__m256i, __m256i, __m256i);
VPDPBUSDS __m256i _mm256_dpbusds_epi32(__m256i, __m256i, __m256i);
VPDPBUSDS __m256i _mm256_mask_dpbusds_epi32(__m256i, __mmask8, __m256i, __m256i);
VPDPBUSDS __m256i _mm256_maskz_dpbusds_epi32(__mmask8, __m256i, __m256i, __m256i);
VPDPBUSDS __m512i _mm512_dpbusds_epi32(__m512i, __m512i, __m512i);
VPDPBUSDS __m512i _mm512_mask_dpbusds_epi32(__m512i, __mmask16, __m512i, __m512i);
VPDPBUSDS __m512i _mm512_maskz_dpbusds_epi32(__mmask16, __m512i, __m512i, __m512i);
VPDPBUSDS-Multiply and Add Unsigned and Signed Bytes With Saturation
Vol. 2C
5-485
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPDPBUSDS-Multiply and Add Unsigned and Signed Bytes With Saturation
Vol. 2C
5-486

VPDPWSSD-Multiply and Add Signed Word Integers
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 52 /r
A
V/V
AVX_VNNI
Multiply groups of 2 pairs signed words in
VPDPWSSD xmm1, xmm2,
xmm3/m128 with corresponding signed words
xmm3/m128
of xmm2, summing those products and adding
them to doubleword result in xmm1.
VEX.256.66.0F38.W0 52 /r
A
V/V
AVX_VNNI
Multiply groups of 2 pairs signed words in
VPDPWSSD ymm1, ymm2,
ymm3/m256 with corresponding signed words
ymm3/m256
of ymm2, summing those products and adding
them to doubleword result in ymm1.
EVEX.128.66.0F38.W0 52 /r
B
V/V
(AVX512_VNNI
Multiply groups of 2 pairs signed words in
VPDPWSSD xmm1{k1}{z}, xmm2,
AND AVX512VL)
xmm3/m128/m32bcst with corresponding
xmm3/m128/m32bcst
OR AVX10.1
signed words of xmm2, summing those
products and adding them to doubleword result
in xmm1, under writemask k1.
EVEX.256.66.0F38.W0 52 /r
B
V/V
(AVX512_VNNI
Multiply groups of 2 pairs signed words in
VPDPWSSD ymm1{k1}{z}, ymm2,
AND AVX512VL)
ymm3/m256/m32bcst with corresponding
ymm3/m256/m32bcst
OR AVX10.1
signed words of ymm2, summing those
products and adding them to doubleword result
in ymm1, under writemask k1.
EVEX.512.66.0F38.W0 52 /r
B
V/V
AVX512_VNNI
Multiply groups of 2 pairs signed words in
VPDPWSSD zmm1{k1}{z}, zmm2,
OR AVX10.1
zmm3/m512/m32bcst with corresponding
zmm3/m512/m32bcst
signed words of zmm2, summing those
products and adding them to doubleword result
in zmm1, under writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual signed words of the first source operand by the corresponding signed words of the second
source operand, producing intermediate signed, doubleword results. The adjacent doubleword results are then
summed and accumulated in the destination operand.
This instruction supports memory fault suppression.
VPDPWSSD-Multiply and Add Signed Word Integers
Vol. 2C
5-487
Operation
VPDPWSSD dest, src1, src2 (VEX encoded versions)
VL=(128, 256)
KL=VL/32
ORIGDEST := DEST
FOR i := 0 TO KL-1:
p1dword := SIGN_EXTEND(SRC1.word[2*i+0]) * SIGN_EXTEND(SRC2.word[2*i+0] )
p2dword := SIGN_EXTEND(SRC1.word[2*i+1]) * SIGN_EXTEND(SRC2.word[2*i+1] )
DEST.dword[i] := ORIGDEST.dword[i] + p1dword + p2dword
DEST[MAX_VL-1:VL] := 0
VPDPWSSD dest, src1, src2 (EVEX encoded versions)
(KL,VL)=(4,128), (8,256), (16,512)
ORIGDEST := DEST
FOR i := 0 TO KL-1:
IF k1[i] or *no writemask*:
IF SRC2 is memory and EVEX.b == 1:
t := SRC2.dword[0]
ELSE:
t := SRC2.dword[i]
p1dword := SIGN_EXTEND(SRC1.word[2*i]) * SIGN_EXTEND(t.word[0])
p2dword := SIGN_EXTEND(SRC1.word[2*i+1]) * SIGN_EXTEND(t.word[1])
DEST.dword[i] := ORIGDEST.dword[i] + p1dword + p2dword
ELSE IF *zeroing*:
DEST.dword[i] := 0
ELSE:
// Merge masking, dest element unchanged
DEST.dword[i] := ORIGDEST.dword[i]
DEST[MAX_VL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPDPWSSD __m128i _mm_dpwssd_avx_epi32(__m128i, __m128i, __m128i);
VPDPWSSD __m128i _mm_dpwssd_epi32(__m128i, __m128i, __m128i);
VPDPWSSD __m128i _mm_mask_dpwssd_epi32(__m128i, __mmask8, __m128i, __m128i);
VPDPWSSD __m128i _mm_maskz_dpwssd_epi32(__mmask8, __m128i, __m128i, __m128i);
VPDPWSSD __m256i _mm256_dpwssd_avx_epi32(__m256i, __m256i, __m256i);
VPDPWSSD __m256i _mm256_dpwssd_epi32(__m256i, __m256i, __m256i);
VPDPWSSD __m256i _mm256_mask_dpwssd_epi32(__m256i, __mmask8, __m256i, __m256i);
VPDPWSSD __m256i _mm256_maskz_dpwssd_epi32(__mmask8, __m256i, __m256i, __m256i);
VPDPWSSD __m512i _mm512_dpwssd_epi32(__m512i, __m512i, __m512i);
VPDPWSSD __m512i _mm512_mask_dpwssd_epi32(__m512i, __mmask16, __m512i, __m512i);
VPDPWSSD __m512i _mm512_maskz_dpwssd_epi32(__mmask16, __m512i, __m512i, __m512i);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPDPWSSD-Multiply and Add Signed Word Integers
Vol. 2C
5-488

VPDPWSSDS-Multiply and Add Signed Word Integers With Saturation
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.66.0F38.W0 53 /r
A
V/V
AVX_VNNI
Multiply groups of 2 pairs of signed words in
VPDPWSSDS xmm1, xmm2,
xmm3/m128 with corresponding signed words
xmm3/m128
of xmm2, summing those products and adding
them to doubleword result in xmm1, with
signed saturation.
VEX.256.66.0F38.W0 53 /r
A
V/V
AVX_VNNI
Multiply groups of 2 pairs of signed words in
VPDPWSSDS ymm1, ymm2,
ymm3/m256 with corresponding signed words
ymm3/m256
of ymm2, summing those products and adding
them to doubleword result in ymm1, with
signed saturation.
EVEX.128.66.0F38.W0 53 /r
B
V/V
(AVX512_VNNI
Multiply groups of 2 pairs of signed words in
VPDPWSSDS xmm1{k1}{z}, xmm2,
AND AVX512VL)
xmm3/m128/m32bcst with corresponding
xmm3/m128/m32bcst
OR AVX10.1
signed words of xmm2, summing those
products and adding them to doubleword result
in xmm1, with signed saturation, under
writemask k1.
EVEX.256.66.0F38.W0 53 /r
B
V/V
(AVX512_VNNI
Multiply groups of 2 pairs of signed words in
VPDPWSSDS ymm1{k1}{z}, ymm2,
AND AVX512VL)
ymm3/m256/m32bcst with corresponding
ymm3/m256/m32bcst
OR AVX10.1
signed words of ymm2, summing those
products and adding them to doubleword result
in ymm1, with signed saturation, under
writemask k1.
EVEX.512.66.0F38.W0 53 /r
B
V/V
AVX512_VNNI
Multiply groups of 2 pairs of signed words in
VPDPWSSDS zmm1{k1}{z}, zmm2,
OR AVX10.1
zmm3/m512/m32bcst with corresponding
zmm3/m512/m32bcst
signed words of zmm2, summing those
products and adding them to doubleword result
in zmm1, with signed saturation, under
writemask k1.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual signed words of the first source operand by the corresponding signed words of the second
source operand, producing intermediate signed, doubleword results. The adjacent doubleword results are then
summed and accumulated in the destination operand. If the intermediate sum overflows a 32b signed number, the
result is saturated to either 0x7FFF_FFFF for positive numbers of 0x8000_0000 for negative numbers.
This instruction supports memory fault suppression.
VPDPWSSDS-Multiply and Add Signed Word Integers With Saturation
Vol. 2C
5-489
Operation
VPDPWSSDS dest, src1, src2 (VEX encoded versions)
VL=(128, 256)
KL=VL/32
ORIGDEST := DEST
FOR i := 0 TO KL-1:
p1dword := SIGN_EXTEND(SRC1.word[2*i+0]) * SIGN_EXTEND(SRC2.word[2*i+0])
p2dword := SIGN_EXTEND(SRC1.word[2*i+1]) * SIGN_EXTEND(SRC2.word[2*i+1])
DEST.dword[i] := SIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1dword + p2dword)
DEST[MAX_VL-1:VL] := 0
VPDPWSSDS dest, src1, src2 (EVEX encoded versions)
(KL,VL)=(4,128), (8,256), (16,512)
ORIGDEST := DEST
FOR i := 0 TO KL-1:
IF k1[i] or *no writemask*:
IF SRC2 is memory and EVEX.b == 1:
t := SRC2.dword[0]
ELSE:
t := SRC2.dword[i]
p1dword := SIGN_EXTEND(SRC1.word[2*i]) * SIGN_EXTEND(t.word[0])
p2dword := SIGN_EXTEND(SRC1.word[2*i+1]) * SIGN_EXTEND(t.word[1])
DEST.dword[i] := SIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1dword + p2dword)
ELSE IF *zeroing*:
DEST.dword[i] := 0
ELSE:
// Merge masking, dest element unchanged
DEST.dword[i] := ORIGDEST.dword[i]
DEST[MAX_VL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPDPWSSDS __m128i _mm_dpwssds_avx_epi32(__m128i, __m128i, __m128i);
VPDPWSSDS __m128i _mm_dpwssds_epi32(__m128i, __m128i, __m128i);
VPDPWSSDS __m128i _mm_mask_dpwssd_epi32(__m128i, __mmask8, __m128i, __m128i);
VPDPWSSDS __m128i _mm_maskz_dpwssd_epi32(__mmask8, __m128i, __m128i, __m128i);
VPDPWSSDS __m256i _mm256_dpwssds_avx_epi32(__m256i, __m256i, __m256i);
VPDPWSSDS __m256i _mm256_dpwssd_epi32(__m256i, __m256i, __m256i);
VPDPWSSDS __m256i _mm256_mask_dpwssd_epi32(__m256i, __mmask8, __m256i, __m256i);
VPDPWSSDS __m256i _mm256_maskz_dpwssd_epi32(__mmask8, __m256i, __m256i, __m256i);
VPDPWSSDS __m512i _mm512_dpwssd_epi32(__m512i, __m512i, __m512i);
VPDPWSSDS __m512i _mm512_mask_dpwssd_epi32(__m512i, __mmask16, __m512i, __m512i);
VPDPWSSDS __m512i _mm512_maskz_dpwssd_epi32(__mmask16, __m512i, __m512i, __m512i);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
VPDPWSSDS-Multiply and Add Signed Word Integers With Saturation
Vol. 2C
5-490

VPDPW[SU,US,UU]D[,S]-Multiply and Add Unsigned and Signed Words With and Without
Saturation
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.F3.0F38.W0 D2 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
xmm3/m128 with corresponding signed words
VPDPWSUD xmm1, xmm2,
of xmm2, summing those products and adding
xmm3/m128
them to the doubleword result in xmm1.
VEX.256.F3.0F38.W0 D2 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
ymm3/m256 with corresponding signed words
VPDPWSUD ymm1, ymm2,
of ymm2, summing those products and adding
ymm3/m256
them to the doubleword result in ymm1.
VEX.128.F3.0F38.W0 D3 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
xmm3/m128 with corresponding signed words
VPDPWSUDS xmm1, xmm2,
of xmm2, summing those products and adding
xmm3/m128
them to the doubleword result, with signed
saturation in xmm1.
VEX.256.F3.0F38.W0 D3 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
ymm3/m256 with corresponding signed words
VPDPWSUDS ymm1, ymm2,
of ymm2, summing those products and adding
ymm3/m256
them to the doubleword result, with signed
saturation in ymm1.
VEX.128.66.0F38.W0 D2 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of signed words in
xmm3/m128 with corresponding unsigned
VPDPWUSD xmm1, xmm2,
words of xmm2, summing those products and
xmm3/m128
adding them to doubleword result in xmm1.
VEX.256.66.0F38.W0 D2 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of signed words in
ymm3/m256 with corresponding unsigned
VPDPWUSD ymm1, ymm2,
words of ymm2, summing those products and
ymm3/m256
adding them to doubleword result in ymm1.
VEX.128.66.0F38.W0 D3 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of signed words in
xmm3/m128 with corresponding unsigned
VPDPWUSDS xmm1, xmm2,
words of xmm2, summing those products and
xmm3/m128
adding them to doubleword result, with signed
saturation in xmm1.
VEX.256.66.0F38.W0 D3 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of signed words in
ymm3/m256 with corresponding unsigned
VPDPWUSDS ymm1, ymm2,
words of ymm2, summing those products and
ymm3/m256
adding them to doubleword result, with signed
saturation in ymm1.
VEX.128.NP.0F38.W0 D2 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
xmm3/m128 with corresponding unsigned
VPDPWUUD xmm1, xmm2,
words of xmm2, summing those products and
xmm3/m128
adding them to doubleword result in xmm1.
VEX.256.NP.0F38.W0 D2 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
ymm3/m256 with corresponding unsigned
VPDPWUUD ymm1, ymm2,
words of ymm2, summing those products and
ymm3/m256
adding them to doubleword result in ymm1.
VPDPW[SU,US,UU]D[,S]-Multiply and Add Unsigned and Signed Words With and Without Saturation
Vol. 2C
5-491

Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.128.NP.0F38.W0 D3 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
xmm3/m128 with corresponding unsigned
VPDPWUUDS xmm1, xmm2,
words of xmm2, summing those products and
xmm3/m128
adding them to the doubleword result, with
unsigned saturation in xmm1.
VEX.256.NP.0F38.W0 D3 /r
A
V/V
AVX_VNNI_INT16
Multiply groups of 2 pairs of unsigned words in
ymm3/m256 with corresponding unsigned
VPDPWUUDS ymm1, ymm2,
words of ymm2, summing those products and
ymm3/m256
adding them to the doubleword result, with
unsigned saturation in ymm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual words of the first source operand by the corresponding words of the second source
operand, producing intermediate dword results. The dword results are then summed and accumulated in the desti-
nation dword element size operand.
For unsigned saturation, when an individual result value is beyond the range of an unsigned doubleword (that is,
greater than FFFF_FFFFH), the saturated unsigned doubleword integer value of FFFF_FFFFH is stored in the double-
word destination.
For signed saturation, when an individual result is beyond the range of a signed doubleword integer (that is,
greater than 7FFF_FFFFH or less than 8000_0000H), the saturated value of 7FFF_FFFFH or 8000_0000H, respec-
tively, is written to the destination operand.
The EVEX version of VPDPWSSD[,S] was previously introduced with AVX512_VNNI. The VEX version of
VPDPWSSD[,S] was previously introduced with AVX_VNNI.
Operation
VPDPW[UU,SU,US]D[,S] dest, src1, src2 (VEX encoded version)
VL = (128, 256)
KL = VL/32
ORIGDEST := DEST
IF *src1 is signed*:
// SU
src1extend := SIGN_EXTEND
ELSE:
// UU, US
src1extend := ZERO_EXTEND
IF *src2 is signed*:
// US
src2extend := SIGN_EXTEND
ELSE:
// UU, SU
src2extend := ZERO_EXTEND
FOR i := 0 TO KL-1:
p1dword := src1extend(SRC1.word[2*i+0]) * src2extend(SRC2.word[2*i+0])
p2dword := src1extend(SRC1.word[2*i+1]) * src2extend(SRC2.word[2*i+1])
IF *saturating version*:
IF *UU instruction version*:
VPDPW[SU,US,UU]D[,S]-Multiply and Add Unsigned and Signed Words With and Without Saturation
Vol. 2C
5-492
DEST.dword[i] := UNSIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1dword + p2dword)
ELSE:
DEST.dword[i] := SIGNED_DWORD_SATURATE(ORIGDEST.dword[i] + p1dword + p2dword)
ELSE:
DEST.dword[i] := ORIGDEST.dword[i] + p1dword + p2dword
DEST[MAX_VL-1:VL] := 0
Flags Affected
None.
Intel C/C++ Compiler Intrinsic Equivalent
VPDPWSUD __m128i _mm_dpwsud_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPWSUD __m256i _mm256_dpwsud_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPWSUDS __m128i _mm_dpwsuds_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPWSUDS __m256i _mm256_dpwsuds_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPWUSD __m128i _mm_dpwusd_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPWUSD __m256i _mm256_dpwusd_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPWUSDS __m128i _mm_dpwusds_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPWUSDS __m256i _mm256_dpwusds_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPWUUD __m128i _mm_dpwuud_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPWUUD __m256i _mm256_dpwuud_epi32 (__m256i __W, __m256i __A, __m256i __B);
VPDPWUUDS __m128i _mm_dpwuuds_epi32 (__m128i __W, __m128i __A, __m128i __B);
VPDPWUUDS __m256i _mm256_dpwuuds_epi32 (__m256i __W, __m256i __A, __m256i __B);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-21, “Type 4 Class Exception Conditions.”
VPDPW[SU,US,UU]D[,S]-Multiply and Add Unsigned and Signed Words With and Without Saturation
Vol. 2C
5-493
VPERM2F128-Permute Floating-Point Values
Opcode/
Op/
64/32
CPUID
Description
Instruction
En
bit Mode
Feature
Support
Flag
VEX.256.66.0F3A.W0 06 /r ib
RV
V/V
AVX
Permute 128-bit floating-point fields in
VPERM2F128 ymm1, ymm2, ymm3/m256, imm8
MI
ymm2 and ymm3/mem using controls from
imm8 and store result in ymm1.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RVMI
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Permute 128 bit floating-point-containing fields from the first source operand (second operand) and second source
operand (third operand) using bits in the 8-bit immediate and store results in the destination operand (first
operand). The first source operand is a YMM register, the second source operand is a YMM register or a 256-bit
memory location, and the destination operand is a YMM register.
SRC2
Y1
Y0
SRC1
X1
X0
DEST
X0, X1, Y0, or Y1
X0, X1, Y0, or Y1
Figure 5-21. VPERM2F128 Operation
Imm8[1:0] select the source for the first destination 128-bit field, imm8[5:4] select the source for the second
destination field. If imm8[3] is set, the low 128-bit field is zeroed. If imm8[7] is set, the high 128-bit field is zeroed.
VEX.L must be 1, otherwise the instruction will #UD.
VPERM2F128-Permute Floating-Point Values
Vol. 2C
5-494
Operation
VPERM2F128
CASE IMM8[1:0] of
0: DEST[127:0] := SRC1[127:0]
1: DEST[127:0] := SRC1[255:128]
2: DEST[127:0] := SRC2[127:0]
3: DEST[127:0] := SRC2[255:128]
ESAC
CASE IMM8[5:4] of
0: DEST[255:128] := SRC1[127:0]
1: DEST[255:128] := SRC1[255:128]
2: DEST[255:128] := SRC2[127:0]
3: DEST[255:128] := SRC2[255:128]
ESAC
IF (imm8[3])
DEST[127:0] := 0
FI
IF (imm8[7])
DEST[MAXVL-1:128] := 0
FI
Intel C/C++ Compiler Intrinsic Equivalent
VPERM2F128:
__m256 _mm256_permute2f128_ps (__m256 a, __m256 b, int control)
VPERM2F128:
__m256d _mm256_permute2f128_pd (__m256d a, __m256d b, int control)
VPERM2F128:
__m256i _mm256_permute2f128_si256 (__m256i a, __m256i b, int control)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-23, “Type 6 Class Exception Conditions.”
Additionally:
#UD
If VEX.L = 0
If VEX.W = 1.
VPERM2F128-Permute Floating-Point Values
Vol. 2C
5-495
VPERM2I128-Permute Integer Values
Opcode/
Op/
64/32
CPUID
Description
Instruction
En
-bit
Feature
Mode
Flag
VEX.256.66.0F3A.W0 46 /r ib
RVMI
V/V
AVX2
Permute 128-bit integer data in ymm2 and
VPERM2I128 ymm1, ymm2, ymm3/m256, imm8
ymm3/mem using controls from imm8 and
store result in ymm1.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RVMI
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Permute 128 bit integer data from the first source operand (second operand) and second source operand (third
operand) using bits in the 8-bit immediate and store results in the destination operand (first operand). The first
source operand is a YMM register, the second source operand is a YMM register or a 256-bit memory location, and
the destination operand is a YMM register.
SRC2
Y1
Y0
SRC1
X1
X0
DEST
X0, X1, Y0, or Y1
X0, X1, Y0, or Y1
Figure 5-22. VPERM2I128 Operation
Imm8[1:0] select the source for the first destination 128-bit field, imm8[5:4] select the source for the second
destination field. If imm8[3] is set, the low 128-bit field is zeroed. If imm8[7] is set, the high 128-bit field is zeroed.
VEX.L must be 1, otherwise the instruction will #UD.
VPERM2I128-Permute Integer Values
Vol. 2C
5-496
Operation
VPERM2I128
CASE IMM8[1:0] of
0: DEST[127:0] := SRC1[127:0]
1: DEST[127:0] := SRC1[255:128]
2: DEST[127:0] := SRC2[127:0]
3: DEST[127:0] := SRC2[255:128]
ESAC
CASE IMM8[5:4] of
0: DEST[255:128] := SRC1[127:0]
1: DEST[255:128] := SRC1[255:128]
2: DEST[255:128] := SRC2[127:0]
3: DEST[255:128] := SRC2[255:128]
ESAC
IF (imm8[3])
DEST[127:0] := 0
FI
IF (imm8[7])
DEST[255:128] := 0
FI
Intel C/C++ Compiler Intrinsic Equivalent
VPERM2I128: __m256i _mm256_permute2x128_si256 (__m256i a, __m256i b, int control)
SIMD Floating-Point Exceptions
None
Other Exceptions
See Table 2-23, “Type 6 Class Exception Conditions.”
Additionally:
#UD
If VEX.L = 0,
If VEX.W = 1.
VPERM2I128-Permute Integer Values
Vol. 2C
5-497

VPERMB-Permute Packed Bytes Elements
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
EVEX.128.66.0F38.W0 8D /r
A
V/V
(AVX512VL AND
Permute bytes in xmm3/m128 using byte indexes
VPERMB xmm1 {k1}{z}, xmm2,
AVX512_VBMI)
in xmm2 and store the result in xmm1 using
xmm3/m128
OR AVX10.1
writemask k1.
EVEX.256.66.0F38.W0 8D /r
A
V/V
AVX512VL
Permute bytes in ymm3/m256 using byte indexes
VPERMB ymm1 {k1}{z}, ymm2,
AVX512_VBMI)
in ymm2 and store the result in ymm1 using
ymm3/m256
OR AVX10.1
writemask k1.
EVEX.512.66.0F38.W0 8D /r
A
V/V
AVX512_VBMI
Permute bytes in zmm3/m512 using byte indexes
VPERMB zmm1 {k1}{z}, zmm2,
OR AVX10.1
in zmm2 and store the result in zmm1 using
zmm3/m512
writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Copies bytes from the second source operand (the third operand) to the destination operand (the first operand)
according to the byte indices in the first source operand (the second operand). Note that this instruction permits a
byte in the source operand to be copied to more than one location in the destination operand.
Only the low 6(EVEX.512)/5(EVEX.256)/4(EVEX.128) bits of each byte index is used to select the location of the
source byte from the second source operand.
The first source operand is a ZMM/YMM/XMM register. The second source operand can be a ZMM/YMM/XMM reg-
ister, a 512/256/128-bit memory location. The destination operand is a ZMM/YMM/XMM register updated at byte
granularity by the writemask k1.
Operation
VPERMB (EVEX encoded versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
IF VL = 128:
n := 3;
ELSE IF VL = 256:
n := 4;
ELSE IF VL = 512:
n := 5;
FI;
FOR j := 0 TO KL-1:
id := SRC1[j*8 + n : j*8] ; // location of the source byte
IF k1[j] OR *no writemask* THEN
DEST[j*8 + 7: j*8] := SRC2[id*8 +7: id*8];
ELSE IF zeroing-masking THEN
DEST[j*8 + 7: j*8] := 0;
*ELSE
DEST[j*8 + 7: j*8] remains unchanged*
FI
ENDFOR
DEST[MAX_VL-1:VL] := 0;
VPERMB-Permute Packed Bytes Elements
Vol. 2C
5-498
Intel C/C++ Compiler Intrinsic Equivalent
VPERMB __m512i _mm512_permutexvar_epi8( __m512i idx, __m512i a);
VPERMB __m512i _mm512_mask_permutexvar_epi8(__m512i s, __mmask64 k, __m512i idx, __m512i a);
VPERMB __m512i _mm512_maskz_permutexvar_epi8( __mmask64 k, __m512i idx, __m512i a);
VPERMB __m256i _mm256_permutexvar_epi8( __m256i idx, __m256i a);
VPERMB __m256i _mm256_mask_permutexvar_epi8(__m256i s, __mmask32 k, __m256i idx, __m256i a);
VPERMB __m256i _mm256_maskz_permutexvar_epi8( __mmask32 k, __m256i idx, __m256i a);
VPERMB __m128i _mm_permutexvar_epi8( __m128i idx, __m128i a);
VPERMB __m128i _mm_mask_permutexvar_epi8(__m128i s, __mmask16 k, __m128i idx, __m128i a);
VPERMB __m128i _mm_maskz_permutexvar_epi8( __mmask16 k, __m128i idx, __m128i a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Exceptions Type E4NF.nb in Table 2-52, “Type E4NF Class Exception Conditions.”
VPERMB-Permute Packed Bytes Elements
Vol. 2C
5-499

VPERMD/VPERMW-Permute Packed Doubleword/Word Elements
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
bit Mode
Flag
Support
VEX.256.66.0F38.W0 36 /r
A
V/V
AVX2
Permute doublewords in ymm3/m256 using
VPERMD ymm1, ymm2, ymm3/m256
indices in ymm2 and store the result in ymm1.
EVEX.256.66.0F38.W0 36 /r
B
V/V
(AVX512VL AND
Permute doublewords in ymm3/m256/m32bcst
VPERMD ymm1 {k1}{z}, ymm2,
AVX512F) OR
using indexes in ymm2 and store the result in
ymm3/m256/m32bcst
AVX10.1
ymm1 using writemask k1.
EVEX.512.66.0F38.W0 36 /r
B
V/V
AVX512F
Permute doublewords in zmm3/m512/m32bcst
VPERMD zmm1 {k1}{z}, zmm2,
OR AVX10.1
using indices in zmm2 and store the result in
zmm3/m512/m32bcst
zmm1 using writemask k1.
EVEX.128.66.0F38.W1 8D /r
C
V/V
(AVX512VL AND
Permute word integers in xmm3/m128 using
VPERMW xmm1 {k1}{z}, xmm2,
AVX512BW) OR
indexes in xmm2 and store the result in xmm1
xmm3/m128
AVX10.1
using writemask k1.
EVEX.256.66.0F38.W1 8D /r
C
V/V
(AVX512VL AND
Permute word integers in ymm3/m256 using
VPERMW ymm1 {k1}{z}, ymm2,
AVX512BW) OR
indexes in ymm2 and store the result in ymm1
ymm3/m256
AVX10.1
using writemask k1.
EVEX.512.66.0F38.W1 8D /r
C
V/V
AVX512BW
Permute word integers in zmm3/m512 using
VPERMW zmm1 {k1}{z}, zmm2,
OR AVX10.1
indexes in zmm2 and store the result in zmm1
zmm3/m512
using writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Copies doublewords (or words) from the second source operand (the third operand) to the destination operand
(the first operand) according to the indices in the first source operand (the second operand). Note that this instruc-
tion permits a doubleword (word) in the source operand to be copied to more than one location in the destination
operand.
VEX.256 encoded VPERMD: The first and second operands are YMM registers, the third operand can be a YMM
register or memory location. Bits (MAXVL-1:256) of the corresponding destination register are zeroed.
EVEX encoded VPERMD: The first and second operands are ZMM/YMM registers, the third operand can be a
ZMM/YMM register, a 512/256-bit memory location or a 512/256-bit vector broadcasted from a 32-bit memory
location. The elements in the destination are updated using the writemask k1.
VPERMW: first and second operands are ZMM/YMM/XMM registers, the third operand can be a ZMM/YMM/XMM
register, or a 512/256/128-bit memory location. The destination is updated using the writemask k1.
EVEX.128 encoded versions: Bits (MAXVL-1:128) of the corresponding ZMM register are zeroed.
VPERMD/VPERMW-Permute Packed Doubleword/Word Elements
Vol. 2C
5-500
Operation
VPERMD (EVEX encoded versions)
(KL, VL) = (8, 256), (16, 512)
IF VL = 256 THEN n := 2; FI;
IF VL = 512 THEN n := 3; FI;
FOR j := 0 TO KL-1
i := j * 32
id := 32*SRC1[i+n:i]
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN DEST[i+31:i] := SRC2[31:0];
ELSE DEST[i+31:i] := SRC2[id+31:id];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPERMD (VEX.256 encoded version)
DEST[31:0] := (SRC2[255:0] >> (SRC1[2:0] * 32))[31:0];
DEST[63:32] := (SRC2[255:0] >> (SRC1[34:32] * 32))[31:0];
DEST[95:64] := (SRC2[255:0] >> (SRC1[66:64] * 32))[31:0];
DEST[127:96] := (SRC2[255:0] >> (SRC1[98:96] * 32))[31:0];
DEST[159:128] := (SRC2[255:0] >> (SRC1[130:128] * 32))[31:0];
DEST[191:160] := (SRC2[255:0] >> (SRC1[162:160] * 32))[31:0];
DEST[223:192] := (SRC2[255:0] >> (SRC1[194:192] * 32))[31:0];
DEST[255:224] := (SRC2[255:0] >> (SRC1[226:224] * 32))[31:0];
DEST[MAXVL-1:256] := 0
VPERMW (EVEX encoded versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
IF VL = 128 THEN n := 2; FI;
IF VL = 256 THEN n := 3; FI;
IF VL = 512 THEN n := 4; FI;
FOR j := 0 TO KL-1
i := j * 16
id := 16*SRC1[i+n:i]
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SRC2[id+15:id]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPERMD/VPERMW-Permute Packed Doubleword/Word Elements
Vol. 2C
5-501