Intel 64 and IA-32 Architectures. Software Developer’s Manual (2026) - page 35
// else dest.fp16[j] remains unchanged
DEST[MAXVL-1:VL] := 0:
VFMSUBADD213PH DEST, SRC2, SRC3 (EVEX encoded versions) when src3 operand is a register
VL = 128, 256 or 512
KL := VL/16
IF (VL = 512) AND (EVEX.b = 1):
SET_RM(EVEX.RC)
ELSE
SET_RM(MXCSR.RC)
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
IF *j is even*:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j]*DEST.fp16[j] + SRC3.fp16[j])
ELSE
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j]*DEST.fp16[j] - SRC3.fp16[j])
ELSE IF *zeroing*:
DEST.fp16[j] := 0
// else dest.fp16[j] remains unchanged
DEST[MAXVL-1:VL] := 0
VFMSUBADD213PH DEST, SRC2, SRC3 (EVEX encoded versions) when src3 operand is a memory source
VL = 128, 256 or 512
KL := VL/16
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
IF EVEX.b = 1:
t3 := SRC3.fp16[0]
ELSE:
t3 := SRC3.fp16[j]
IF *j is even*:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j] * DEST.fp16[j] + t3 )
ELSE:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j] * DEST.fp16[j] - t3 )
ELSE IF *zeroing*:
DEST.fp16[j] := 0
// else dest.fp16[j] remains unchanged
DEST[MAXVL-1:VL] := 0:
VFMSUBADD132PH/VFMSUBADD213PH/VFMSUBADD231PH-Fused Multiply-Alternating Subtract/Add of Packed FP16 Values
Vol. 2C
5-294
VFMSUBADD231PH DEST, SRC2, SRC3 (EVEX encoded versions) when src3 operand is a register
VL = 128, 256 or 512
KL := VL/16
IF (VL = 512) AND (EVEX.b = 1):
SET_RM(EVEX.RC)
ELSE
SET_RM(MXCSR.RC)
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
IF *j is even:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j]*SRC3.fp16[j] + DEST.fp16[j])
ELSE:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j]*SRC3.fp16[j] - DEST.fp16[j])
ELSE IF *zeroing*:
DEST.fp16[j] := 0
// else dest.fp16[j] remains unchanged
DEST[MAXVL-1:VL] := 0
VFMSUBADD231PH DEST, SRC2, SRC3 (EVEX encoded versions) when src3 operand is a memory source
VL = 128, 256 or 512
KL := VL/16
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
IF EVEX.b = 1:
t3 := SRC3.fp16[0]
ELSE:
t3 := SRC3.fp16[j]
IF *j is even*:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j] * t3 + DEST.fp16[j] )
ELSE:
DEST.fp16[j] := RoundFPControl(SRC2.fp16[j] * t3 - DEST.fp16[j] )
ELSE IF *zeroing*:
DEST.fp16[j] := 0
// else dest.fp16[j] remains unchanged
DEST[MAXVL-1:VL] := 0
VFMSUBADD132PH/VFMSUBADD213PH/VFMSUBADD231PH-Fused Multiply-Alternating Subtract/Add of Packed FP16 Values
Vol. 2C
5-295
Intel C/C++ Compiler Intrinsic Equivalent
VFMSUBADD132PH, VFMSUBADD213PH, and VFMSUBADD231PH:
__m128h _mm_fmsubadd_ph (__m128h a, __m128h b, __m128h c);
__m128h _mm_mask_fmsubadd_ph (__m128h a, __mmask8 k, __m128h b, __m128h c);
__m128h _mm_mask3_fmsubadd_ph (__m128h a, __m128h b, __m128h c, __mmask8 k);
__m128h _mm_maskz_fmsubadd_ph (__mmask8 k, __m128h a, __m128h b, __m128h c);
__m256h _mm256_fmsubadd_ph (__m256h a, __m256h b, __m256h c);
__m256h _mm256_mask_fmsubadd_ph (__m256h a, __mmask16 k, __m256h b, __m256h c);
__m256h _mm256_mask3_fmsubadd_ph (__m256h a, __m256h b, __m256h c, __mmask16 k);
__m256h _mm256_maskz_fmsubadd_ph (__mmask16 k, __m256h a, __m256h b, __m256h c);
__m512h _mm512_fmsubadd_ph (__m512h a, __m512h b, __m512h c);
__m512h _mm512_mask_fmsubadd_ph (__m512h a, __mmask32 k, __m512h b, __m512h c);
__m512h _mm512_mask3_fmsubadd_ph (__m512h a, __m512h b, __m512h c, __mmask32 k);
__m512h _mm512_maskz_fmsubadd_ph (__mmask32 k, __m512h a, __m512h b, __m512h c);
__m512h _mm512_fmsubadd_round_ph (__m512h a, __m512h b, __m512h c, const int rounding);
__m512h _mm512_mask_fmsubadd_round_ph (__m512h a, __mmask32 k, __m512h b, __m512h c, const int rounding);
__m512h _mm512_mask3_fmsubadd_round_ph (__m512h a, __m512h b, __m512h c, __mmask32 k, const int rounding);
__m512h _mm512_maskz_fmsubadd_round_ph (__mmask32 k, __m512h a, __m512h b, __m512h c, const int rounding);
SIMD Floating-Point Exceptions
Invalid, Underflow, Overflow, Precision, Denormal.
Other Exceptions
EVEX-encoded instructions, see Table 2-48, “Type E2 Class Exception Conditions.”
VFMSUBADD132PH/VFMSUBADD213PH/VFMSUBADD231PH-Fused Multiply-Alternating Subtract/Add of Packed FP16 Values
Vol. 2C
5-296

VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating
Subtract/Add of Packed Single Precision Floating-Point Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
VEX.128.66.0F38.W0 97 /r
A
V/V
FMA
Multiply packed single precision floating-point
VFMSUBADD132PS xmm1, xmm2,
values from xmm1 and xmm3/mem, subtract/add
xmm3/m128
elements in xmm2 and put result in xmm1.
VEX.128.66.0F38.W0 A7 /r
A
V/V
FMA
Multiply packed single precision floating-point
VFMSUBADD213PS xmm1, xmm2,
values from xmm1 and xmm2, subtract/add
xmm3/m128
elements in xmm3/mem and put result in xmm1.
VEX.128.66.0F38.W0 B7 /r
A
V/V
FMA
Multiply packed single precision floating-point
VFMSUBADD231PS xmm1, xmm2,
values from xmm2 and xmm3/mem, subtract/add
xmm3/m128
elements in xmm1 and put result in xmm1.
VEX.256.66.0F38.W0 97 /r
A
V/V
FMA
Multiply packed single precision floating-point
VFMSUBADD132PS ymm1, ymm2,
values from ymm1 and ymm3/mem, subtract/add
ymm3/m256
elements in ymm2 and put result in ymm1.
VEX.256.66.0F38.W0 A7 /r
A
V/V
FMA
Multiply packed single precision floating-point
VFMSUBADD213PS ymm1, ymm2,
values from ymm1 and ymm2, subtract/add
ymm3/m256
elements in ymm3/mem and put result in ymm1.
VEX.256.66.0F38.W0 B7 /r
A
V/V
FMA
Multiply packed single precision floating-point
VFMSUBADD231PS ymm1, ymm2,
values from ymm2 and ymm3/mem, subtract/add
ymm3/m256
elements in ymm1 and put result in ymm1.
EVEX.128.66.0F38.W0 97 /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point
VFMSUBADD132PS xmm1 {k1}{z},
AVX512F) OR
values from xmm1 and xmm3/m128/m32bcst,
xmm2, xmm3/m128/m32bcst
AVX10.1
subtract/add elements in xmm2 and put result in
xmm1 subject to writemask k1.
EVEX.128.66.0F38.W0 A7 /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point
VFMSUBADD213PS xmm1 {k1}{z},
AVX512F) OR
values from xmm1 and xmm2, subtract/add
xmm2, xmm3/m128/m32bcst
AVX10.1
elements in xmm3/m128/m32bcst and put result
in xmm1 subject to writemask k1.
EVEX.128.66.0F38.W0 B7 /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point
VFMSUBADD231PS xmm1 {k1}{z},
AVX512F) OR
values from xmm2 and xmm3/m128/m32bcst,
xmm2, xmm3/m128/m32bcst
AVX10.1
subtract/add elements in xmm1 and put result in
xmm1 subject to writemask k1.
EVEX.256.66.0F38.W0 97 /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point
VFMSUBADD132PS ymm1 {k1}{z},
AVX512F) OR
values from ymm1 and ymm3/m256/m32bcst,
ymm2, ymm3/m256/m32bcst
AVX10.1
subtract/add elements in ymm2 and put result in
ymm1 subject to writemask k1.
EVEX.256.66.0F38.W0 A7 /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point
VFMSUBADD213PS ymm1 {k1}{z},
AVX512F) OR
values from ymm1 and ymm2, subtract/add
ymm2, ymm3/m256/m32bcst
AVX10.1
elements in ymm3/m256/m32bcst and put result
in ymm1 subject to writemask k1.
EVEX.256.66.0F38.W0 B7 /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point
VFMSUBADD231PS ymm1 {k1}{z},
AVX512F) OR
values from ymm2 and ymm3/m256/m32bcst,
ymm2, ymm3/m256/m32bcst
AVX10.1
subtract/add elements in ymm1 and put result in
ymm1 subject to writemask k1.
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-297

Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.512.66.0F38.W0 97 /r
B
V/V
AVX512F
Multiply packed single precision floating-point
VFMSUBADD132PS zmm1 {k1}{z},
OR AVX10.1
values from zmm1 and zmm3/m512/m32bcst,
zmm2, zmm3/m512/m32bcst{er}
subtract/add elements in zmm2 and put result in
zmm1 subject to writemask k1.
EVEX.512.66.0F38.W0 A7 /r
B
V/V
AVX512F
Multiply packed single precision floating-point
VFMSUBADD213PS zmm1 {k1}{z},
OR AVX10.1
values from zmm1 and zmm2, subtract/add
zmm2, zmm3/m512/m32bcst{er}
elements in zmm3/m512/m32bcst and put result
in zmm1 subject to writemask k1.
EVEX.512.66.0F38.W0 B7 /r
B
V/V
AVX512F
Multiply packed single precision floating-point
VFMSUBADD231PS zmm1 {k1}{z},
OR AVX10.1
values from zmm2 and zmm3/m512/m32bcst,
zmm2, zmm3/m512/m32bcst{er}
subtract/add elements in zmm1 and put result in
zmm1 subject to writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFMSUBADD132PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the first
source operand to the corresponding packed single precision floating-point values in the third source operand.
From the infinite precision intermediate result, subtracts the odd single precision floating-point elements and adds
the even single precision floating-point values in the second source operand, performs rounding and stores the
resulting packed single precision floating-point values to the destination operand (first source operand).
VFMSUBADD213PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the
second source operand to the corresponding packed single precision floating-point values in the first source
operand. From the infinite precision intermediate result, subtracts the odd single precision floating-point elements
and adds the even single precision floating-point values in the third source operand, performs rounding and stores
the resulting packed single precision floating-point values to the destination operand (first source operand).
VFMSUBADD231PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the
second source operand to the corresponding packed single precision floating-point values in the third source
operand. From the infinite precision intermediate result, subtracts the odd single precision floating-point elements
and adds the even single precision floating-point values in the first source operand, performs rounding and stores
the resulting packed single precision floating-point values to the destination operand (first source operand).
EVEX encoded versions: The destination operand (also first source operand) and the second source operand are
ZMM/YMM/XMM register. The third source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory loca-
tion or a 512/256/128-bit vector broadcasted from a 32-bit memory location. The destination operand is condition-
ally updated with write mask k1.
VEX.256 encoded version: The destination operand (also first source operand) is a YMM register and encoded in
reg_field. The second source operand is a YMM register and encoded in VEX.vvvv. The third source operand is a
YMM register or a 256-bit memory location and encoded in rm_field.
VEX.128 encoded version: The destination operand (also first source operand) is a XMM register and encoded in
reg_field. The second source operand is a XMM register and encoded in VEX.vvvv. The third source operand is a
XMM register or a 128-bit memory location and encoded in rm_field. The upper 128 bits of the YMM destination
register are zeroed.
Compiler tools may optionally support a complementary mnemonic for each instruction mnemonic listed in the
opcode/instruction column of the summary table. The behavior of the complementary mnemonic in situations
involving NANs are governed by the definition of the instruction mnemonic defined in the opcode/instruction
column.
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-298
Operation
In the operations below, “*” and “+” symbols represent multiplication and addition with infinite precision inputs and outputs (no
rounding).
VFMSUBADD132PS DEST, SRC2, SRC3
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM -1{
n := 64*i;
DEST[n+31:n] := RoundFPControl_MXCSR(DEST[n+31:n]*SRC3[n+31:n] + SRC2[n+31:n])
DEST[n+63:n+32] := RoundFPControl_MXCSR(DEST[n+63:n+32]*SRC3[n+63:n+32] -SRC2[n+63:n+32])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFMSUBADD213PS DEST, SRC2, SRC3
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM -1{
n := 64*i;
DEST[n+31:n] := RoundFPControl_MXCSR(SRC2[n+31:n]*DEST[n+31:n] +SRC3[n+31:n])
DEST[n+63:n+32] := RoundFPControl_MXCSR(SRC2[n+63:n+32]*DEST[n+63:n+32] -SRC3[n+63:n+32])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFMSUBADD231PS DEST, SRC2, SRC3
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM -1{
n := 64*i;
DEST[n+31:n] := RoundFPControl_MXCSR(SRC2[n+31:n]*SRC3[n+31:n] + DEST[n+31:n])
DEST[n+63:n+32] := RoundFPControl_MXCSR(SRC2[n+63:n+32]*SRC3[n+63:n+32] -DEST[n+63:n+32])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-299
VFMSUBADD132PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF j *is even*
THEN DEST[i+31:i] :=
RoundFPControl(DEST[i+31:i]*SRC3[i+31:i] + SRC2[i+31:i])
ELSE DEST[i+31:i] :=
RoundFPControl(DEST[i+31:i]*SRC3[i+31:i] - SRC2[i+31:i])
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFMSUBADD132PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF j *is even*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(DEST[i+31:i]*SRC3[31:0] + SRC2[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(DEST[i+31:i]*SRC3[i+31:i] + SRC2[i+31:i])
FI;
ELSE
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(DEST[i+31:i]*SRC3[31:0] - SRC2[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(DEST[i+31:i]*SRC3[i+31:i] - SRC2[i+31:i])
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-300
FI;
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFMSUBADD213PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF j *is even*
THEN DEST[i+31:i] :=
RoundFPControl(SRC2[i+31:i]*DEST[i+31:i] + SRC3[i+31:i])
ELSE DEST[i+31:i] :=
RoundFPControl(SRC2[i+31:i]*DEST[i+31:i] - SRC3[i+31:i])
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFMSUBADD213PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF j *is even*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*DEST[i+31:i] + SRC3[31:0])
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-301
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*DEST[i+31:i] + SRC3[i+31:i])
FI;
ELSE
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*DEST[i+31:i] - SRC3[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*DEST[i+31:i] - SRC3[31:0])
FI;
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFMSUBADD231PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF j *is even*
THEN DEST[i+31:i] :=
RoundFPControl(SRC2[i+31:i]*SRC3[i+31:i] + DEST[i+31:i])
ELSE DEST[i+31:i] :=
RoundFPControl(SRC2[i+31:i]*SRC3[i+31:i] - DEST[i+31:i])
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFMSUBADD231PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-302
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF j *is even*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*SRC3[31:0] + DEST[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*SRC3[i+31:i] + DEST[i+31:i])
FI;
ELSE
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*SRC3[31:0] - DEST[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(SRC2[i+31:i]*SRC3[i+31:i] - DEST[i+31:i])
FI;
FI
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFMSUBADDxxxPS __m512 _mm512_fmsubadd_ps(__m512 a, __m512 b, __m512 c);
VFMSUBADDxxxPS __m512 _mm512_fmsubadd_round_ps(__m512 a, __m512 b, __m512 c, int r);
VFMSUBADDxxxPS __m512 _mm512_mask_fmsubadd_ps(__m512 a, __mmask16 k, __m512 b, __m512 c);
VFMSUBADDxxxPS __m512 _mm512_maskz_fmsubadd_ps(__mmask16 k, __m512 a, __m512 b, __m512 c);
VFMSUBADDxxxPS __m512 _mm512_mask3_fmsubadd_ps(__m512 a, __m512 b, __m512 c, __mmask16 k);
VFMSUBADDxxxPS __m512 _mm512_mask_fmsubadd_round_ps(__m512 a, __mmask16 k, __m512 b, __m512 c, int r);
VFMSUBADDxxxPS __m512 _mm512_maskz_fmsubadd_round_ps(__mmask16 k, __m512 a, __m512 b, __m512 c, int r);
VFMSUBADDxxxPS __m512 _mm512_mask3_fmsubadd_round_ps(__m512 a, __m512 b, __m512 c, __mmask16 k, int r);
VFMSUBADDxxxPS __m256 _mm256_mask_fmsubadd_ps(__m256 a, __mmask8 k, __m256 b, __m256 c);
VFMSUBADDxxxPS __m256 _mm256_maskz_fmsubadd_ps(__mmask8 k, __m256 a, __m256 b, __m256 c);
VFMSUBADDxxxPS __m256 _mm256_mask3_fmsubadd_ps(__m256 a, __m256 b, __m256 c, __mmask8 k);
VFMSUBADDxxxPS __m128 _mm_mask_fmsubadd_ps(__m128 a, __mmask8 k, __m128 b, __m128 c);
VFMSUBADDxxxPS __m128 _mm_maskz_fmsubadd_ps(__mmask8 k, __m128 a, __m128 b, __m128 c);
VFMSUBADDxxxPS __m128 _mm_mask3_fmsubadd_ps(__m128 a, __m128 b, __m128 c, __mmask8 k);
VFMSUBADDxxxPS __m128 _mm_fmsubadd_ps (__m128 a, __m128 b, __m128 c);
VFMSUBADDxxxPS __m256 _mm256_fmsubadd_ps (__m256 a, __m256 b, __m256 c);
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-303
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-19, “Type 2 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-48, “Type E2 Class Exception Conditions.”
VFMSUBADD132PS/VFMSUBADD213PS/VFMSUBADD231PS-Fused Multiply-Alternating Subtract/Add of Packed Single Precision
Vol. 2C
5-304
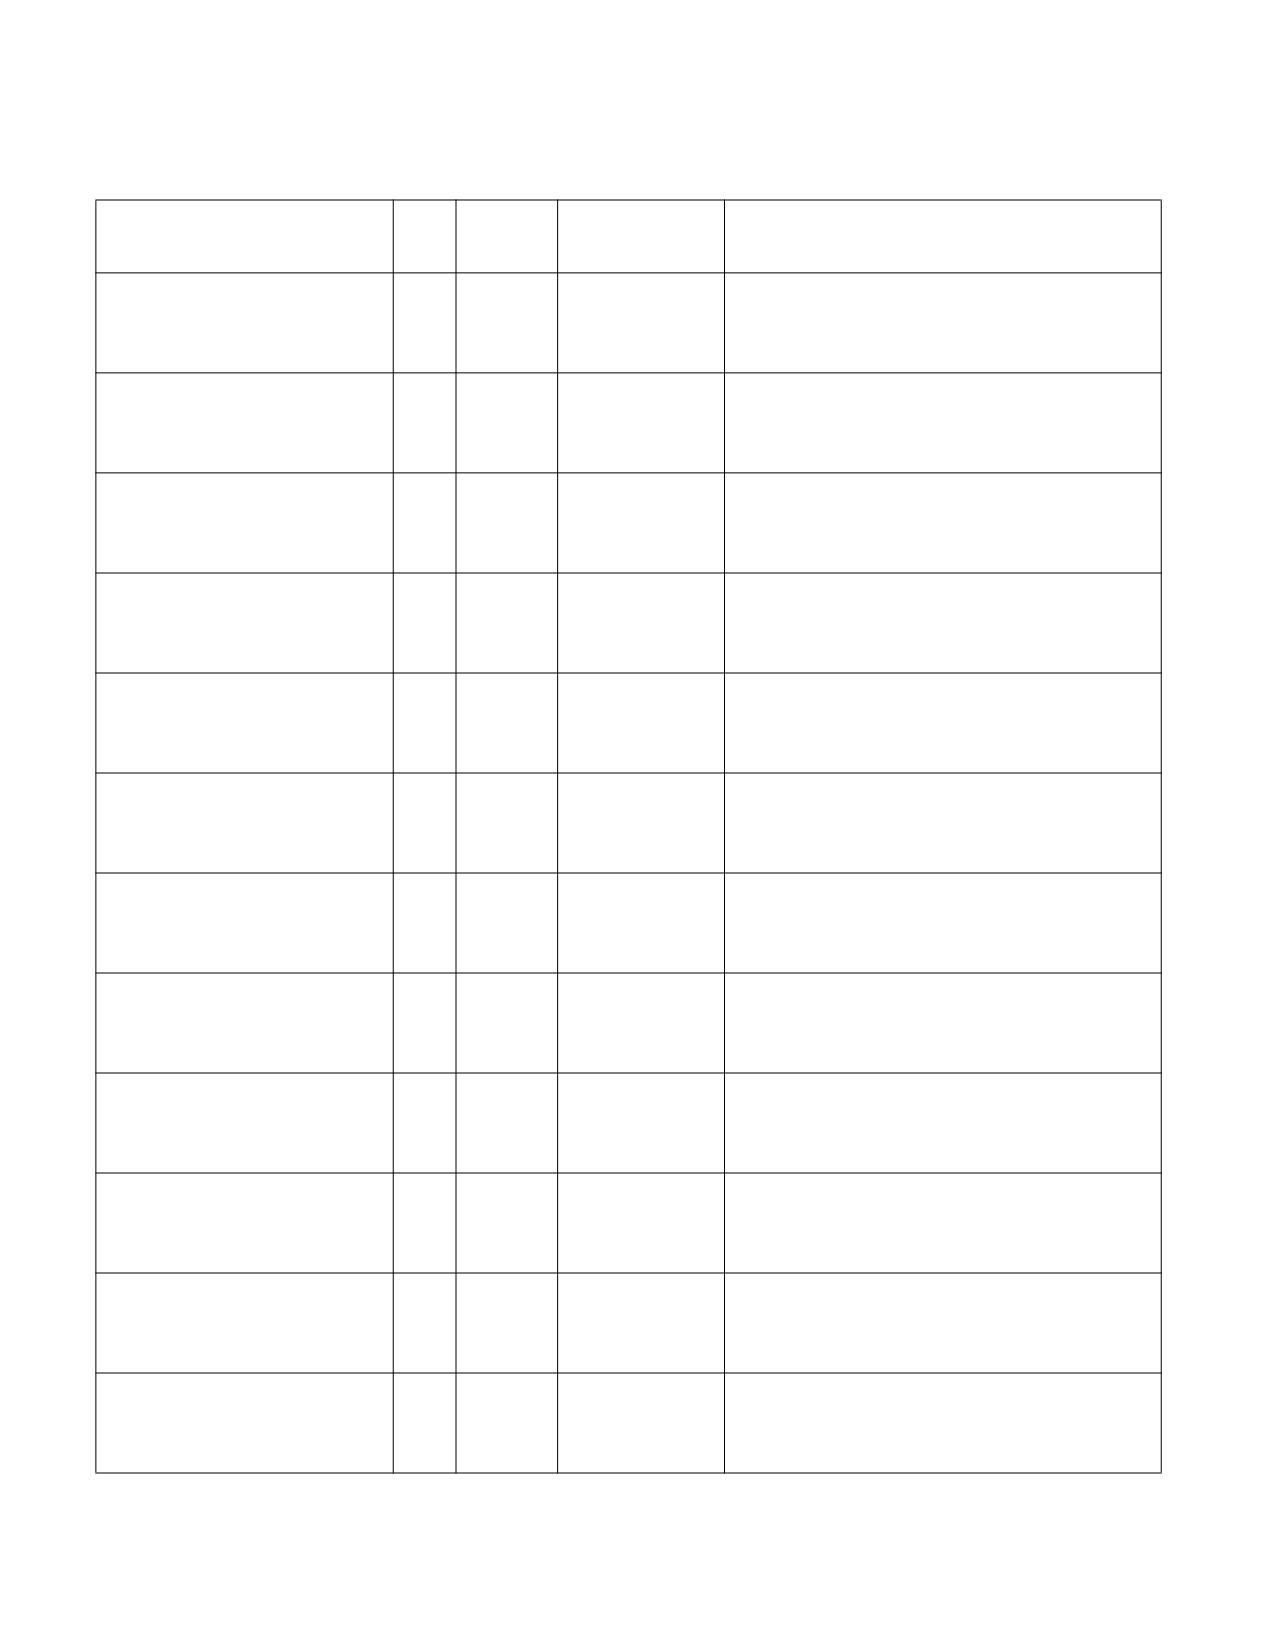
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed
Double Precision Floating-Point Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
VEX.128.66.0F38.W1 9C /r
A
V/V
FMA
Multiply packed double precision floating-point
VFNMADD132PD xmm1, xmm2,
values from xmm1 and xmm3/mem, negate the
xmm3/m128
multiplication result and add to xmm2 and put result
in xmm1.
VEX.128.66.0F38.W1 AC /r
A
V/V
FMA
Multiply packed double precision floating-point
VFNMADD213PD xmm1, xmm2,
values from xmm1 and xmm2, negate the
xmm3/m128
multiplication result and add to xmm3/mem and put
result in xmm1.
VEX.128.66.0F38.W1 BC /r
A
V/V
FMA
Multiply packed double precision floating-point
VFNMADD231PD xmm1, xmm2,
values from xmm2 and xmm3/mem, negate the
xmm3/m128
multiplication result and add to xmm1 and put result
in xmm1.
VEX.256.66.0F38.W1 9C /r
A
V/V
FMA
Multiply packed double precision floating-point
VFNMADD132PD ymm1, ymm2,
values from ymm1 and ymm3/mem, negate the
ymm3/m256
multiplication result and add to ymm2 and put result
in ymm1.
VEX.256.66.0F38.W1 AC /r
A
V/V
FMA
Multiply packed double precision floating-point
VFNMADD213PD ymm1, ymm2,
values from ymm1 and ymm2, negate the
ymm3/m256
multiplication result and add to ymm3/mem and put
result in ymm1.
VEX.256.66.0F38.W1 BC /r
A
V/V
FMA
Multiply packed double precision floating-point
VFNMADD231PD ymm1, ymm2,
values from ymm2 and ymm3/mem, negate the
ymm3/m256
multiplication result and add to ymm1 and put result
in ymm1.
EVEX.128.66.0F38.W1 9C /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point
VFNMADD132PD xmm0 {k1}{z},
AVX512F) OR
values from xmm1 and xmm3/m128/m64bcst,
xmm1, xmm2/m128/m64bcst
AVX10.1
negate the multiplication result and add to xmm2
and put result in xmm1.
EVEX.128.66.0F38.W1 AC /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point
VFNMADD213PD xmm1 {k1}{z},
AVX512F) OR
values from xmm1 and xmm2, negate the
xmm2, xmm3/m128/m64bcst
AVX10.1
multiplication result and add to
xmm3/m128/m64bcst and put result in xmm1.
EVEX.128.66.0F38.W1 BC /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point
VFNMADD231PD xmm1 {k1}{z},
AVX512F) OR
values from xmm2 and xmm3/m128/m64bcst,
xmm2, xmm3/m128/m64bcst
AVX10.1
negate the multiplication result and add to xmm1
and put result in xmm1.
EVEX.256.66.0F38.W1 9C /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point
VFNMADD132PD ymm1 {k1}{z},
AVX512F) OR
values from ymm1 and ymm3/m256/m64bcst,
ymm2, ymm3/m256/m64bcst
AVX10.1
negate the multiplication result and add to ymm2
and put result in ymm1.
EVEX.256.66.0F38.W1 AC /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point
VFNMADD213PD ymm1 {k1}{z},
AVX512F) OR
values from ymm1 and ymm2, negate the
ymm2, ymm3/m256/m64bcst
AVX10.1
multiplication result and add to
ymm3/m256/m64bcst and put result in ymm1.
EVEX.256.66.0F38.W1 BC /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point
VFNMADD231PD ymm1 {k1}{z},
AVX512F) OR
values from ymm2 and ymm3/m256/m64bcst,
ymm2, ymm3/m256/m64bcst
AVX10.1
negate the multiplication result and add to ymm1
and put result in ymm1.
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-305
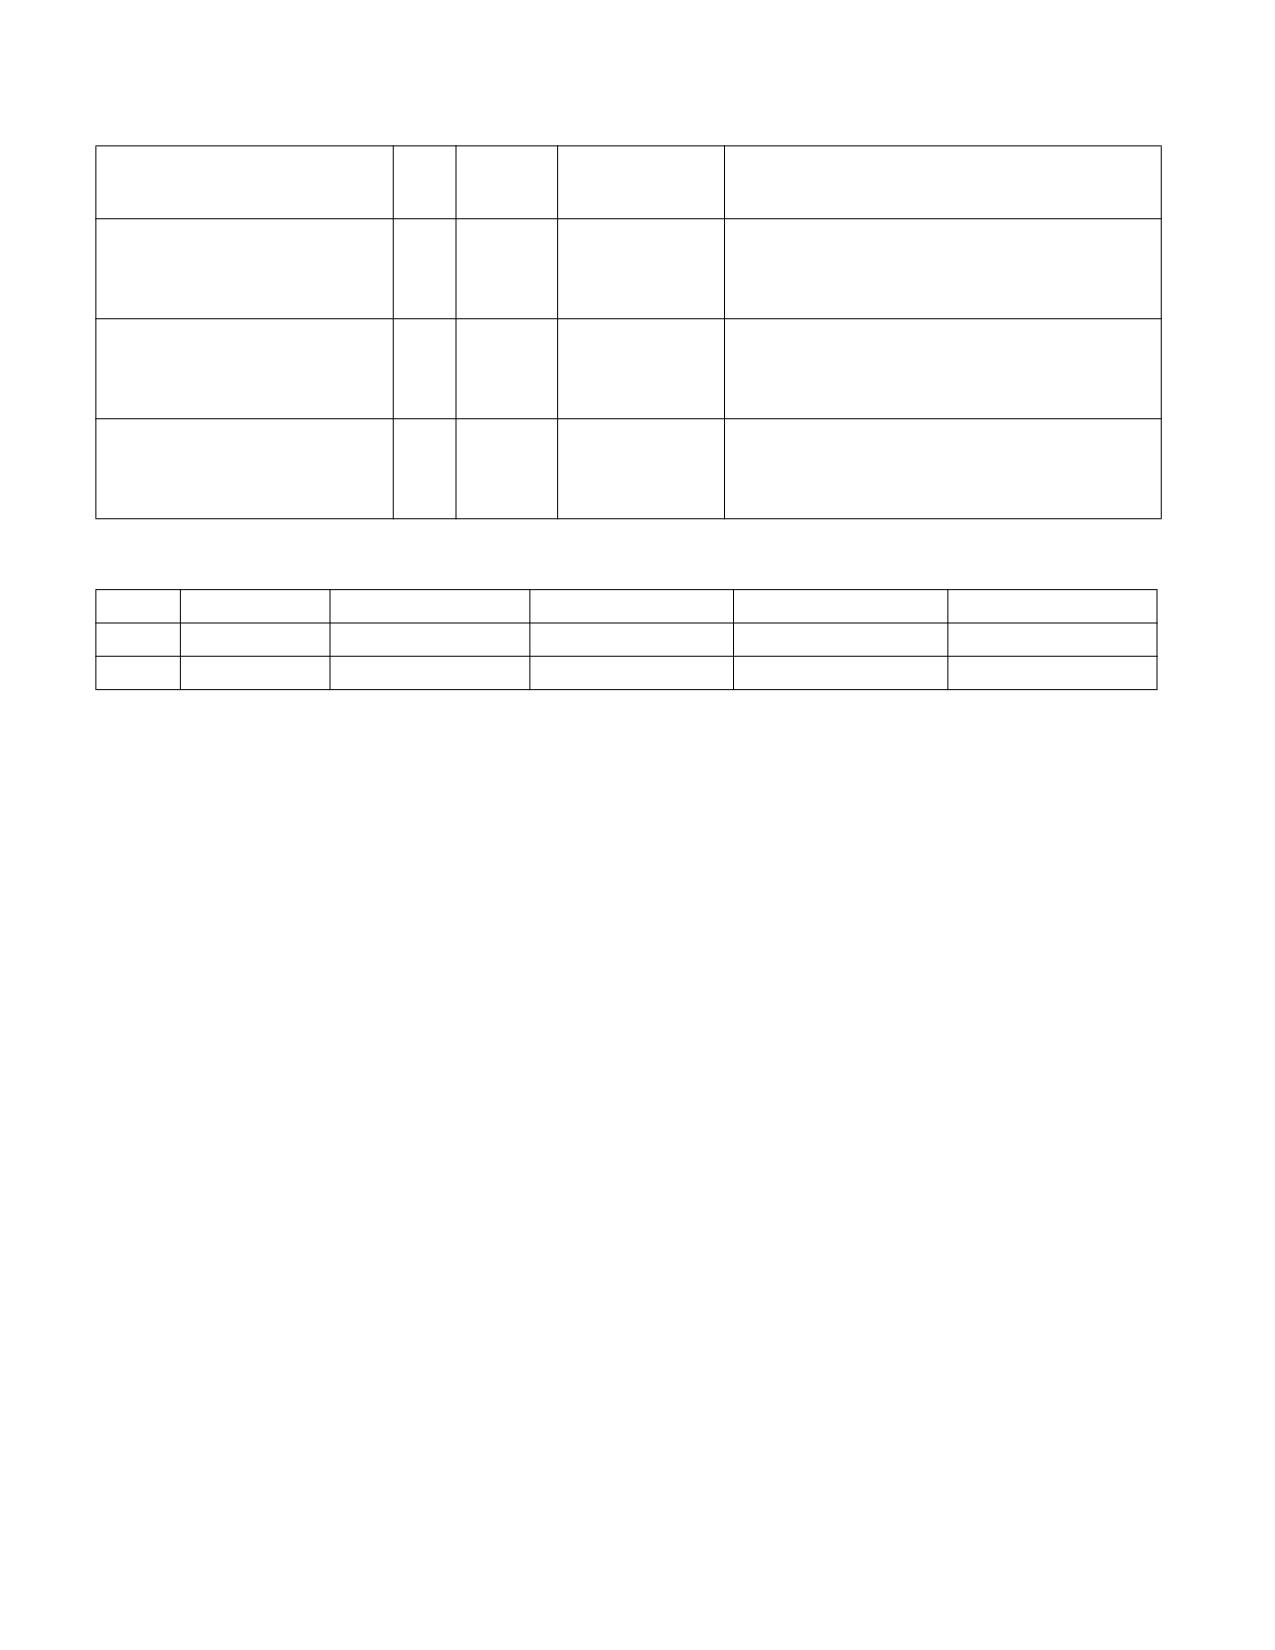
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.512.66.0F38.W1 9C /r
B
V/V
AVX512F
Multiply packed double precision floating-point
VFNMADD132PD zmm1 {k1}{z},
OR AVX10.1
values from zmm1 and zmm3/m512/m64bcst,
zmm2, zmm3/m512/m64bcst{er}
negate the multiplication result and add to zmm2
and put result in zmm1.
EVEX.512.66.0F38.W1 AC /r
B
V/V
AVX512F
Multiply packed double precision floating-point
VFNMADD213PD zmm1 {k1}{z},
OR AVX10.1
values from zmm1 and zmm2, negate the
zmm2, zmm3/m512/m64bcst{er}
multiplication result and add to
zmm3/m512/m64bcst and put result in zmm1.
EVEX.512.66.0F38.W1 BC /r
B
V/V
AVX512F
Multiply packed double precision floating-point
VFNMADD231PD zmm1 {k1}{z},
OR AVX10.1
values from zmm2 and zmm3/m512/m64bcst,
zmm2, zmm3/m512/m64bcst{er}
negate the multiplication result and add to zmm1
and put result in zmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMADD132PD: Multiplies the two, four or eight packed double precision floating-point values from the first
source operand to the two, four or eight packed double precision floating-point values in the third source operand,
adds the negated infinite precision intermediate result to the two, four or eight packed double precision floating-
point values in the second source operand, performs rounding and stores the resulting two, four or eight packed
double precision floating-point values to the destination operand (first source operand).
VFNMADD213PD: Multiplies the two, four or eight packed double precision floating-point values from the second
source operand to the two, four or eight packed double precision floating-point values in the first source operand,
adds the negated infinite precision intermediate result to the two, four or eight packed double precision floating-
point values in the third source operand, performs rounding and stores the resulting two, four or eight packed
double precision floating-point values to the destination operand (first source operand).
VFNMADD231PD: Multiplies the two, four or eight packed double precision floating-point values from the second
source to the two, four or eight packed double precision floating-point values in the third source operand, the
negated infinite precision intermediate result to the two, four or eight packed double precision floating-point values
in the first source operand, performs rounding and stores the resulting two, four or eight packed double precision
floating-point values to the destination operand (first source operand).
EVEX encoded versions: The destination operand (also first source operand) and the second source operand are
ZMM/YMM/XMM register. The third source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory loca-
tion or a 512/256/128-bit vector broadcasted from a 64-bit memory location. The destination operand is condition-
ally updated with write mask k1.
VEX.256 encoded version: The destination operand (also first source operand) is a YMM register and encoded in
reg_field. The second source operand is a YMM register and encoded in VEX.vvvv. The third source operand is a
YMM register or a 256-bit memory location and encoded in rm_field.
VEX.128 encoded version: The destination operand (also first source operand) is a XMM register and encoded in
reg_field. The second source operand is a XMM register and encoded in VEX.vvvv. The third source operand is a
XMM register or a 128-bit memory location and encoded in rm_field. The upper 128 bits of the YMM destination
register are zeroed.
Operation
In the operations below, “*” and “-” symbols represent multiplication and subtraction with infinite precision inputs and outputs (no
rounding).
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-306
VFNMADD132PD DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 64*i;
DEST[n+63:n] := RoundFPControl_MXCSR(-(DEST[n+63:n]*SRC3[n+63:n]) + SRC2[n+63:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMADD213PD DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 64*i;
DEST[n+63:n] := RoundFPControl_MXCSR(-(SRC2[n+63:n]*DEST[n+63:n]) + SRC3[n+63:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMADD231PD DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 64*i;
DEST[n+63:n] := RoundFPControl_MXCSR(-(SRC2[n+63:n]*SRC3[n+63:n]) + DEST[n+63:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-307
VFNMADD132PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] :=
RoundFPControl(-(DEST[i+63:i]*SRC3[i+63:i]) + SRC2[i+63:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(DEST[i+63:i]*SRC3[63:0]) + SRC2[i+63:i])
ELSE
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(DEST[i+63:i]*SRC3[i+63:i]) + SRC2[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-308
VFNMADD213PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] :=
RoundFPControl(-(SRC2[i+63:i]*DEST[i+63:i]) + SRC3[i+63:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD213PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*DEST[i+63:i]) + SRC3[63:0])
ELSE
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*DEST[i+63:i]) + SRC3[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-309
VFNMADD231PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] :=
RoundFPControl(-(SRC2[i+63:i]*SRC3[i+63:i]) + DEST[i+63:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD231PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*SRC3[63:0]) + DEST[i+63:i])
ELSE
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*SRC3[i+63:i]) + DEST[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-310
Intel C/C++ Compiler Intrinsic Equivalent
VFNMADDxxxPD __m512d _mm512_fnmadd_pd(__m512d a, __m512d b, __m512d c);
VFNMADDxxxPD __m512d _mm512_fnmadd_round_pd(__m512d a, __m512d b, __m512d c, int r);
VFNMADDxxxPD __m512d _mm512_mask_fnmadd_pd(__m512d a, __mmask8 k, __m512d b, __m512d c);
VFNMADDxxxPD __m512d _mm512_maskz_fnmadd_pd(__mmask8 k, __m512d a, __m512d b, __m512d c);
VFNMADDxxxPD __m512d _mm512_mask3_fnmadd_pd(__m512d a, __m512d b, __m512d c, __mmask8 k);
VFNMADDxxxPD __m512d _mm512_mask_fnmadd_round_pd(__m512d a, __mmask8 k, __m512d b, __m512d c, int r);
VFNMADDxxxPD __m512d _mm512_maskz_fnmadd_round_pd(__mmask8 k, __m512d a, __m512d b, __m512d c, int r);
VFNMADDxxxPD __m512d _mm512_mask3_fnmadd_round_pd(__m512d a, __m512d b, __m512d c, __mmask8 k, int r);
VFNMADDxxxPD __m256d _mm256_mask_fnmadd_pd(__m256d a, __mmask8 k, __m256d b, __m256d c);
VFNMADDxxxPD __m256d _mm256_maskz_fnmadd_pd(__mmask8 k, __m256d a, __m256d b, __m256d c);
VFNMADDxxxPD __m256d _mm256_mask3_fnmadd_pd(__m256d a, __m256d b, __m256d c, __mmask8 k);
VFNMADDxxxPD __m128d _mm_mask_fnmadd_pd(__m128d a, __mmask8 k, __m128d b, __m128d c);
VFNMADDxxxPD __m128d _mm_maskz_fnmadd_pd(__mmask8 k, __m128d a, __m128d b, __m128d c);
VFNMADDxxxPD __m128d _mm_mask3_fnmadd_pd(__m128d a, __m128d b, __m128d c, __mmask8 k);
VFNMADDxxxPD __m128d _mm_fnmadd_pd (__m128d a, __m128d b, __m128d c);
VFNMADDxxxPD __m256d _mm256_fnmadd_pd (__m256d a, __m256d b, __m256d c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-19, “Type 2 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-48, “Type E2 Class Exception Conditions.”
VFNMADD132PD/VFNMADD213PD/VFNMADD231PD-Fused Negative Multiply-Add of Packed Double Precision Floating-Point Values
Vol. 2C
5-311
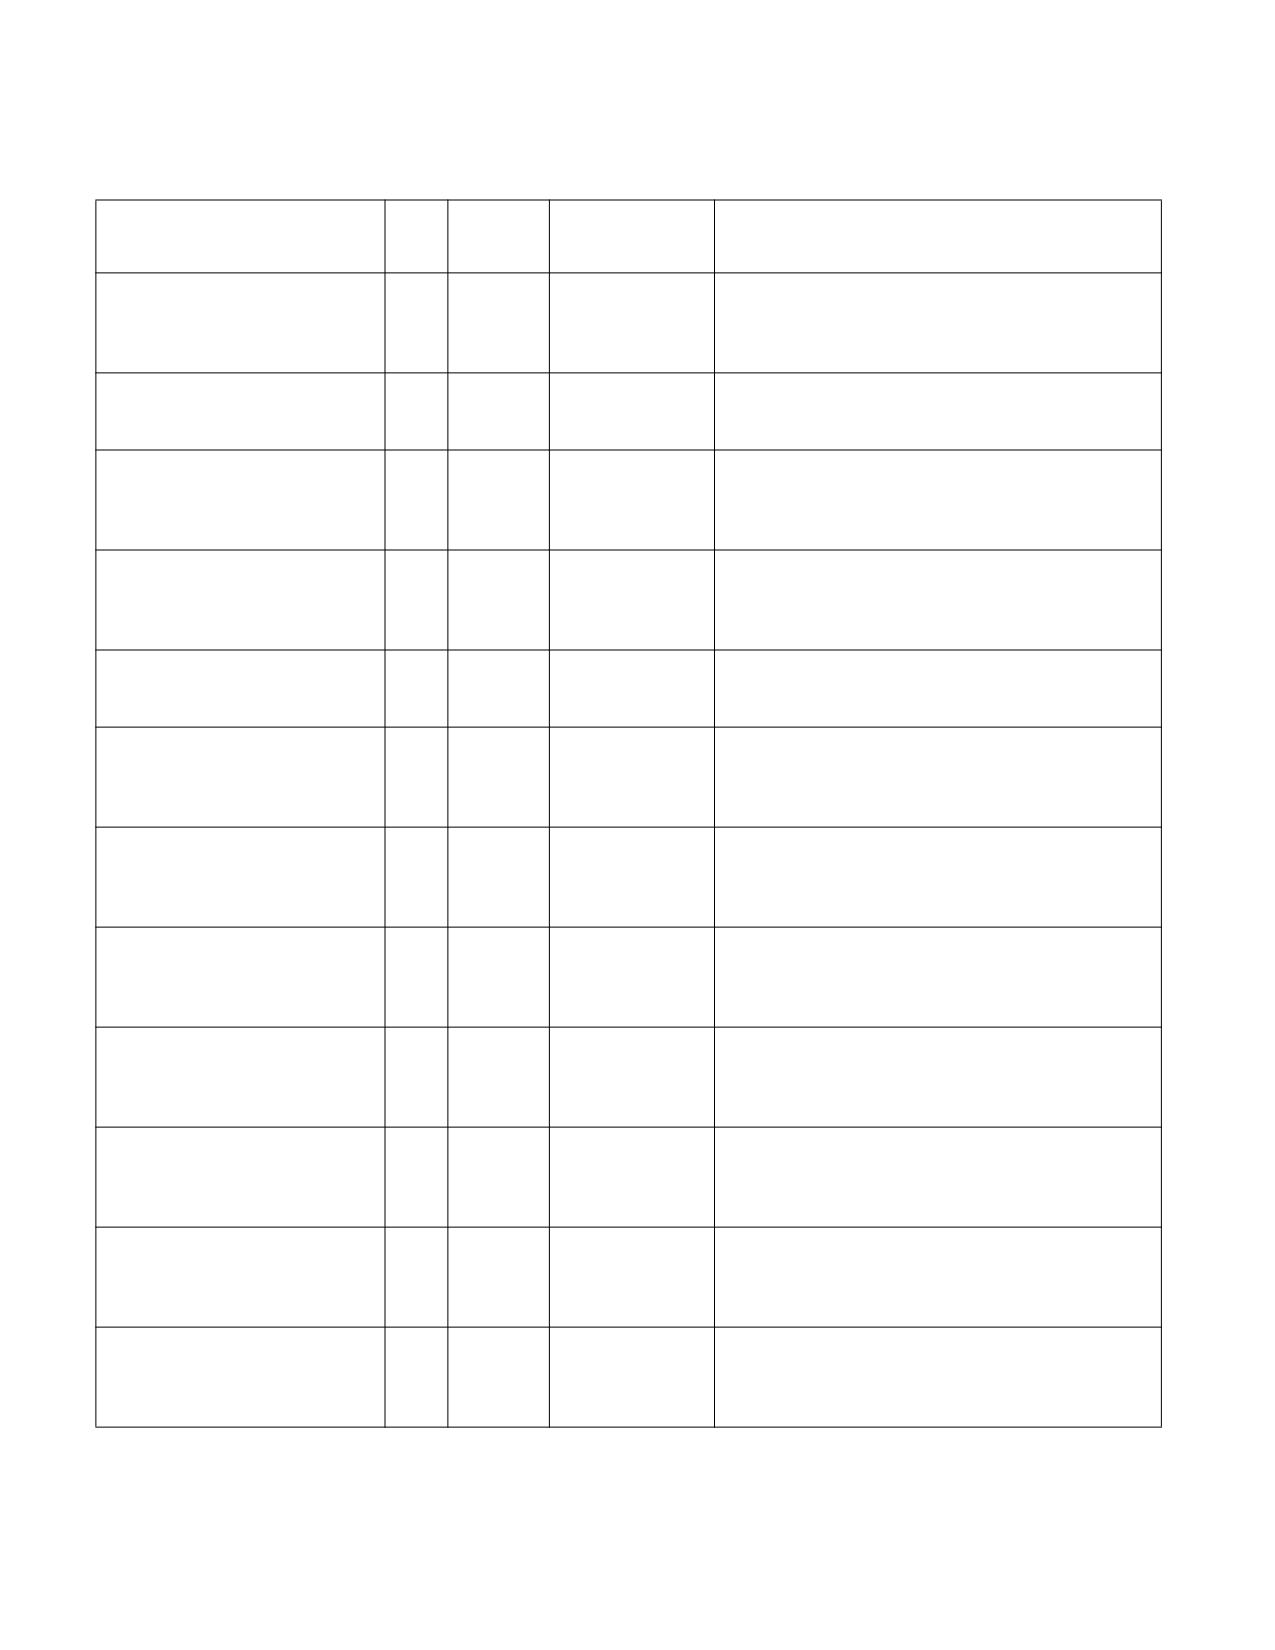
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed
Single Precision Floating-Point Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
VEX.128.66.0F38.W0 9C /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMADD132PS xmm1, xmm2,
from xmm1 and xmm3/mem, negate the
xmm3/m128
multiplication result and add to xmm2 and put result
in xmm1.
VEX.128.66.0F38.W0 AC /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMADD213PS xmm1, xmm2,
from xmm1 and xmm2, negate the multiplication
xmm3/m128
result and add to xmm3/mem and put result in xmm1.
VEX.128.66.0F38.W0 BC /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMADD231PS xmm1, xmm2,
from xmm2 and xmm3/mem, negate the
xmm3/m128
multiplication result and add to xmm1 and put result
in xmm1.
VEX.256.66.0F38.W0 9C /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMADD132PS ymm1, ymm2,
from ymm1 and ymm3/mem, negate the
ymm3/m256
multiplication result and add to ymm2 and put result
in ymm1.
VEX.256.66.0F38.W0 AC /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMADD213PS ymm1, ymm2,
from ymm1 and ymm2, negate the multiplication
ymm3/m256
result and add to ymm3/mem and put result in ymm1.
VEX.256.66.0F38.0 BC /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMADD231PS ymm1, ymm2,
from ymm2 and ymm3/mem, negate the
ymm3/m256
multiplication result and add to ymm1 and put result
in ymm1.
EVEX.128.66.0F38.W0 9C /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD132PS xmm1 {k1}{z},
AVX512F) OR
from xmm1 and xmm3/m128/m32bcst, negate the
xmm2, xmm3/m128/m32bcst
AVX10.1
multiplication result and add to xmm2 and put result
in xmm1.
EVEX.128.66.0F38.W0 AC /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD213PS xmm1 {k1}{z},
AVX512F) OR
from xmm1 and xmm2, negate the multiplication
xmm2, xmm3/m128/m32bcst
AVX10.1
result and add to xmm3/m128/m32bcst and put
result in xmm1.
EVEX.128.66.0F38.W0 BC /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD231PS xmm1 {k1}{z},
AVX512F) OR
from xmm2 and xmm3/m128/m32bcst, negate the
xmm2, xmm3/m128/m32bcst
AVX10.1
multiplication result and add to xmm1 and put result
in xmm1.
EVEX.256.66.0F38.W0 9C /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD132PS ymm1 {k1}{z},
AVX512F) OR
from ymm1 and ymm3/m256/m32bcst, negate the
ymm2, ymm3/m256/m32bcst
AVX10.1
multiplication result and add to ymm2 and put result
in ymm1.
EVEX.256.66.0F38.W0 AC /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD213PS ymm1 {k1}{z},
AVX512F) OR
from ymm1 and ymm2, negate the multiplication
ymm2, ymm3/m256/m32bcst
AVX10.1
result and add to ymm3/m256/m32bcst and put
result in ymm1.
EVEX.256.66.0F38.W0 BC /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD231PS ymm1 {k1}{z},
AVX512F) OR
from ymm2 and ymm3/m256/m32bcst, negate the
ymm2, ymm3/m256/m32bcst
AVX10.1
multiplication result and add to ymm1 and put result
in ymm1.
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-312
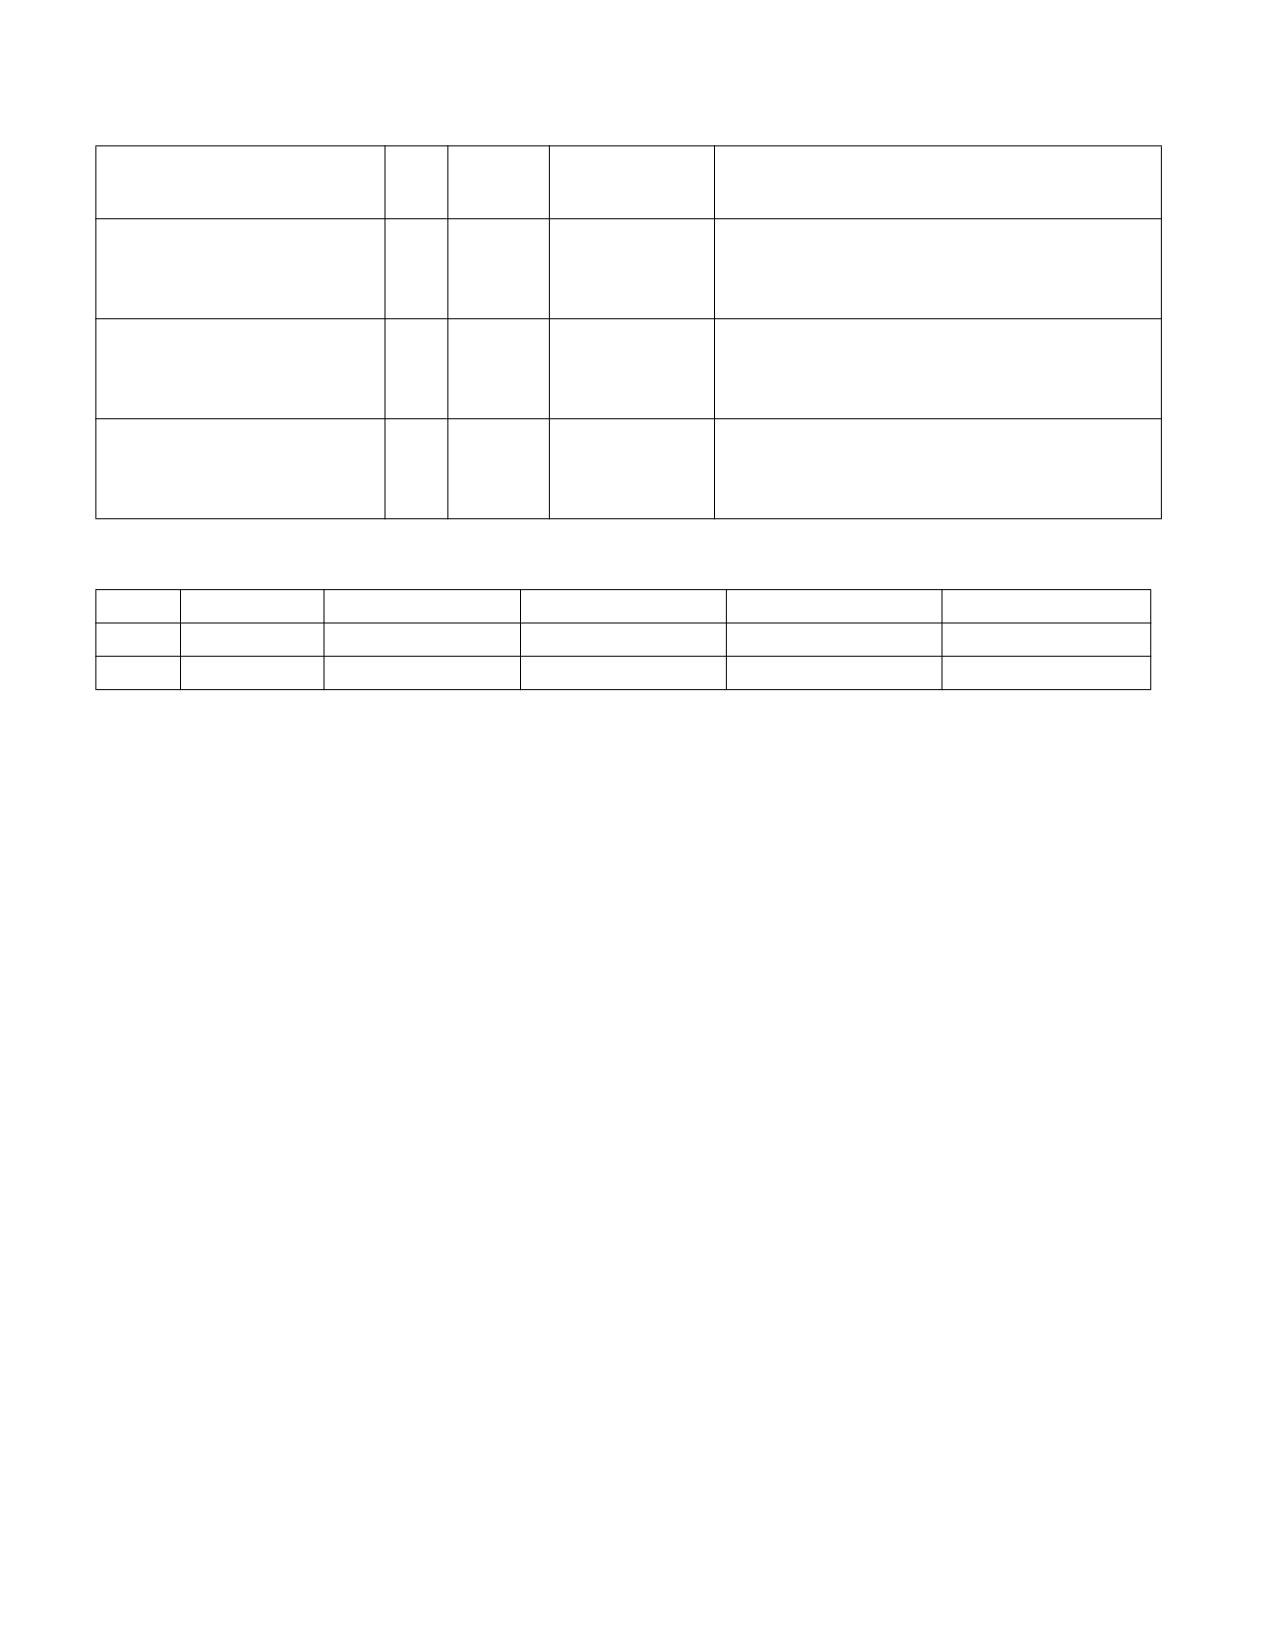
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.512.66.0F38.W0 9C /r
B
V/V
(AVX512VL AND
Multiply packed single precision floating-point values
VFNMADD132PS zmm1 {k1}{z},
AVX512F) OR
from zmm1 and zmm3/m512/m32bcst, negate the
zmm2, zmm3/m512/m32bcst{er}
AVX10.1
multiplication result and add to zmm2 and put result
in zmm1.
EVEX.512.66.0F38.W0 AC /r
B
V/V
AVX512F OR
Multiply packed single precision floating-point values
VFNMADD213PS zmm1 {k1}{z},
AVX10.1
from zmm1 and zmm2, negate the multiplication
zmm2, zmm3/m512/m32bcst{er}
result and add to zmm3/m512/m32bcst and put
result in zmm1.
EVEX.512.66.0F38.W0 BC /r
B
V/V
AVX512F OR
Multiply packed single precision floating-point values
VFNMADD231PS zmm1 {k1}{z},
AVX10.1
from zmm2 and zmm3/m512/m32bcst, negate the
zmm2, zmm3/m512/m32bcst{er}
multiplication result and add to zmm1 and put result
in zmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMADD132PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the first
source operand to the four, eight or sixteen packed single precision floating-point values in the third source
operand, adds the negated infinite precision intermediate result to the four, eight or sixteen packed single precision
floating-point values in the second source operand, performs rounding and stores the resulting four, eight or
sixteen packed single precision floating-point values to the destination operand (first source operand).
VFNMADD213PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the second
source operand to the four, eight or sixteen packed single precision floating-point values in the first source
operand, adds the negated infinite precision intermediate result to the four, eight or sixteen packed single precision
floating-point values in the third source operand, performs rounding and stores the resulting the four, eight or
sixteen packed single precision floating-point values to the destination operand (first source operand).
VFNMADD231PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the second
source operand to the four, eight or sixteen packed single precision floating-point values in the third source
operand, adds the negated infinite precision intermediate result to the four, eight or sixteen packed single precision
floating-point values in the first source operand, performs rounding and stores the resulting four, eight or sixteen
packed single precision floating-point values to the destination operand (first source operand).
EVEX encoded versions: The destination operand (also first source operand) and the second source operand are
ZMM/YMM/XMM register. The third source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory loca-
tion or a 512/256/128-bit vector broadcasted from a 32-bit memory location. The destination operand is condition-
ally updated with write mask k1.
VEX.256 encoded version: The destination operand (also first source operand) is a YMM register and encoded in
reg_field. The second source operand is a YMM register and encoded in VEX.vvvv. The third source operand is a
YMM register or a 256-bit memory location and encoded in rm_field.
VEX.128 encoded version: The destination operand (also first source operand) is a XMM register and encoded in
reg_field. The second source operand is a XMM register and encoded in VEX.vvvv. The third source operand is a
XMM register or a 128-bit memory location and encoded in rm_field. The upper 128 bits of the YMM destination
register are zeroed.
Operation
In the operations below, “*” and “+” symbols represent multiplication and addition with infinite precision inputs and outputs (no
rounding).
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-313
VFNMADD132PS DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 32*i;
DEST[n+31:n] := RoundFPControl_MXCSR(- (DEST[n+31:n]*SRC3[n+31:n]) + SRC2[n+31:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMADD213PS DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 32*i;
DEST[n+31:n] := RoundFPControl_MXCSR(- (SRC2[n+31:n]*DEST[n+31:n]) + SRC3[n+31:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMADD231PS DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 32*i;
DEST[n+31:n] := RoundFPControl_MXCSR(- (SRC2[n+31:n]*SRC3[n+31:n]) + DEST[n+31:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-314
VFNMADD132PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
RoundFPControl(-(DEST[i+31:i]*SRC3[i+31:i]) + SRC2[i+31:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(DEST[i+31:i]*SRC3[31:0]) + SRC2[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(DEST[i+31:i]*SRC3[i+31:i]) + SRC2[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-315
VFNMADD213PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
RoundFPControl(-(SRC2[i+31:i]*DEST[i+31:i]) + SRC3[i+31:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD213PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*DEST[i+31:i]) + SRC3[31:0])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*DEST[i+31:i]) + SRC3[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-316
VFNMADD231PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
RoundFPControl(-(SRC2[i+31:i]*SRC3[i+31:i]) + DEST[i+31:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD231PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*SRC3[31:0]) + DEST[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*SRC3[i+31:i]) + DEST[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-317
Intel C/C++ Compiler Intrinsic Equivalent
VFNMADDxxxPS __m512 _mm512_fnmadd_ps(__m512 a, __m512 b, __m512 c);
VFNMADDxxxPS __m512 _mm512_fnmadd_round_ps(__m512 a, __m512 b, __m512 c, int r);
VFNMADDxxxPS __m512 _mm512_mask_fnmadd_ps(__m512 a, __mmask16 k, __m512 b, __m512 c);
VFNMADDxxxPS __m512 _mm512_maskz_fnmadd_ps(__mmask16 k, __m512 a, __m512 b, __m512 c);
VFNMADDxxxPS __m512 _mm512_mask3_fnmadd_ps(__m512 a, __m512 b, __m512 c, __mmask16 k);
VFNMADDxxxPS __m512 _mm512_mask_fnmadd_round_ps(__m512 a, __mmask16 k, __m512 b, __m512 c, int r);
VFNMADDxxxPS __m512 _mm512_maskz_fnmadd_round_ps(__mmask16 k, __m512 a, __m512 b, __m512 c, int r);
VFNMADDxxxPS __m512 _mm512_mask3_fnmadd_round_ps(__m512 a, __m512 b, __m512 c, __mmask16 k, int r);
VFNMADDxxxPS __m256 _mm256_mask_fnmadd_ps(__m256 a, __mmask8 k, __m256 b, __m256 c);
VFNMADDxxxPS __m256 _mm256_maskz_fnmadd_ps(__mmask8 k, __m256 a, __m256 b, __m256 c);
VFNMADDxxxPS __m256 _mm256_mask3_fnmadd_ps(__m256 a, __m256 b, __m256 c, __mmask8 k);
VFNMADDxxxPS __m128 _mm_mask_fnmadd_ps(__m128 a, __mmask8 k, __m128 b, __m128 c);
VFNMADDxxxPS __m128 _mm_maskz_fnmadd_ps(__mmask8 k, __m128 a, __m128 b, __m128 c);
VFNMADDxxxPS __m128 _mm_mask3_fnmadd_ps(__m128 a, __m128 b, __m128 c, __mmask8 k);
VFNMADDxxxPS __m128 _mm_fnmadd_ps (__m128 a, __m128 b, __m128 c);
VFNMADDxxxPS __m256 _mm256_fnmadd_ps (__m256 a, __m256 b, __m256 c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-19, “Type 2 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-48, “Type E2 Class Exception Conditions.”
VFNMADD132PS/VFNMADD213PS/VFNMADD231PS-Fused Negative Multiply-Add of Packed Single Precision Floating-Point Values
Vol. 2C
5-318
VFNMADD132SD/VFNMADD213SD/VFNMADD231SD-Fused Negative Multiply-Add of Scalar
Double Precision Floating-Point Values
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
Bit Mode
Feature Flag
Support
VEX.LIG.66.0F38.W1 9D /r
A
V/V
FMA
Multiply scalar double precision floating-point value from
VFNMADD132SD xmm1, xmm2,
xmm1 and xmm3/mem, negate the multiplication result
xmm3/m64
and add to xmm2 and put result in xmm1.
VEX.LIG.66.0F38.W1 AD /r
A
V/V
FMA
Multiply scalar double precision floating-point value from
VFNMADD213SD xmm1, xmm2,
xmm1 and xmm2, negate the multiplication result and add
xmm3/m64
to xmm3/mem and put result in xmm1.
VEX.LIG.66.0F38.W1 BD /r
A
V/V
FMA
Multiply scalar double precision floating-point value from
VFNMADD231SD xmm1, xmm2,
xmm2 and xmm3/mem, negate the multiplication result
xmm3/m64
and add to xmm1 and put result in xmm1.
EVEX.LLIG.66.0F38.W1 9D /r
B
V/V
AVX512F
Multiply scalar double precision floating-point value from
VFNMADD132SD xmm1 {k1}{z},
OR AVX10.1
xmm1 and xmm3/m64, negate the multiplication result
xmm2, xmm3/m64{er}
and add to xmm2 and put result in xmm1.
EVEX.LLIG.66.0F38.W1 AD /r
B
V/V
AVX512F
Multiply scalar double precision floating-point value from
VFNMADD213SD xmm1 {k1}{z},
OR AVX10.1
xmm1 and xmm2, negate the multiplication result and add
xmm2, xmm3/m64{er}
to xmm3/m64 and put result in xmm1.
EVEX.LLIG.66.0F38.W1 BD /r
B
V/V
AVX512F
Multiply scalar double precision floating-point value from
VFNMADD231SD xmm1 {k1}{z},
OR AVX10.1
xmm2 and xmm3/m64, negate the multiplication result
xmm2, xmm3/m64{er}
and add to xmm1 and put result in xmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Tuple1 Scalar
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMADD132SD: Multiplies the low packed double precision floating-point value from the first source operand to
the low packed double precision floating-point value in the third source operand, adds the negated infinite precision
intermediate result to the low packed double precision floating-point values in the second source operand,
performs rounding and stores the resulting packed double precision floating-point value to the destination operand
(first source operand).
VFNMADD213SD: Multiplies the low packed double precision floating-point value from the second source operand
to the low packed double precision floating-point value in the first source operand, adds the negated infinite preci-
sion intermediate result to the low packed double precision floating-point value in the third source operand,
performs rounding and stores the resulting packed double precision floating-point value to the destination operand
(first source operand).
VFNMADD231SD: Multiplies the low packed double precision floating-point value from the second source to the low
packed double precision floating-point value in the third source operand, adds the negated infinite precision inter-
mediate result to the low packed double precision floating-point value in the first source operand, performs
rounding and stores the resulting packed double precision floating-point value to the destination operand (first
source operand).
VEX.128 and EVEX encoded version: The destination operand (also first source operand) is encoded in reg_field.
The second source operand is encoded in VEX.vvvv/EVEX.vvvv. The third source operand is encoded in rm_field.
Bits 127:64 of the destination are unchanged. Bits MAXVL-1:128 of the destination register are zeroed.
EVEX encoded version: The low quadword element of the destination is updated according to the writemask.
Compiler tools may optionally support a complementary mnemonic for each instruction mnemonic listed in the
opcode/instruction column of the summary table. The behavior of the complementary mnemonic in situations
VFNMADD132SD/VFNMADD213SD/VFNMADD231SD-Fused Negative Multiply-Add of Scalar Double Precision Floating-Point Values
Vol. 2C
5-319
involving NANs are governed by the definition of the instruction mnemonic defined in the opcode/instruction
column.
Operation
In the operations below, “*” and “+” symbols represent multiplication and addition with infinite precision inputs and outputs (no
rounding).
VFNMADD132SD DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[63:0] := RoundFPControl(-(DEST[63:0]*SRC3[63:0]) + SRC2[63:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] := 0
FI;
FI;
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMADD213SD DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[63:0] := RoundFPControl(-(SRC2[63:0]*DEST[63:0]) + SRC3[63:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] := 0
FI;
FI;
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMADD132SD/VFNMADD213SD/VFNMADD231SD-Fused Negative Multiply-Add of Scalar Double Precision Floating-Point Values
Vol. 2C
5-320
VFNMADD231SD DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[63:0] := RoundFPControl(-(SRC2[63:0]*SRC3[63:0]) + DEST[63:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] := 0
FI;
FI;
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMADD132SD DEST, SRC2, SRC3 (VEX encoded version)
DEST[63:0] := RoundFPControl_MXCSR(- (DEST[63:0]*SRC3[63:0]) + SRC2[63:0])
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMADD213SD DEST, SRC2, SRC3 (VEX encoded version)
DEST[63:0] := RoundFPControl_MXCSR(- (SRC2[63:0]*DEST[63:0]) + SRC3[63:0])
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMADD231SD DEST, SRC2, SRC3 (VEX encoded version)
DEST[63:0] := RoundFPControl_MXCSR(- (SRC2[63:0]*SRC3[63:0]) + DEST[63:0])
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFNMADDxxxSD __m128d _mm_fnmadd_round_sd(__m128d a, __m128d b, __m128d c, int r);
VFNMADDxxxSD __m128d _mm_mask_fnmadd_sd(__m128d a, __mmask8 k, __m128d b, __m128d c);
VFNMADDxxxSD __m128d _mm_maskz_fnmadd_sd(__mmask8 k, __m128d a, __m128d b, __m128d c);
VFNMADDxxxSD __m128d _mm_mask3_fnmadd_sd(__m128d a, __m128d b, __m128d c, __mmask8 k);
VFNMADDxxxSD __m128d _mm_mask_fnmadd_round_sd(__m128d a, __mmask8 k, __m128d b, __m128d c, int r);
VFNMADDxxxSD __m128d _mm_maskz_fnmadd_round_sd(__mmask8 k, __m128d a, __m128d b, __m128d c, int r);
VFNMADDxxxSD __m128d _mm_mask3_fnmadd_round_sd(__m128d a, __m128d b, __m128d c, __mmask8 k, int r);
VFNMADDxxxSD __m128d _mm_fnmadd_sd (__m128d a, __m128d b, __m128d c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal
Other Exceptions
VEX-encoded instructions, see Table 2-20, “Type 3 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-49, “Type E3 Class Exception Conditions.”
VFNMADD132SD/VFNMADD213SD/VFNMADD231SD-Fused Negative Multiply-Add of Scalar Double Precision Floating-Point Values
Vol. 2C
5-321
VFNMADD132SS/VFNMADD213SS/VFNMADD231SS-Fused Negative Multiply-Add of Scalar
Single Precision Floating-Point Values
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
Bit Mode
Feature Flag
Support
VEX.LIG.66.0F38.W0 9D /r
A
V/V
FMA
Multiply scalar single precision floating-point value
VFNMADD132SS xmm1, xmm2,
from xmm1 and xmm3/m32, negate the multiplication
xmm3/m32
result and add to xmm2 and put result in xmm1.
VEX.LIG.66.0F38.W0 AD /r
A
V/V
FMA
Multiply scalar single precision floating-point value
VFNMADD213SS xmm1, xmm2,
from xmm1 and xmm2, negate the multiplication
xmm3/m32
result and add to xmm3/m32 and put result in xmm1.
VEX.LIG.66.0F38.W0 BD /r
A
V/V
FMA
Multiply scalar single precision floating-point value
VFNMADD231SS xmm1, xmm2,
from xmm2 and xmm3/m32, negate the multiplication
xmm3/m32
result and add to xmm1 and put result in xmm1.
EVEX.LLIG.66.0F38.W0 9D /r
B
V/V
AVX512F
Multiply scalar single-precision floating-point value
VFNMADD132SS xmm1 {k1}{z},
OR AVX10.1
from xmm1 and xmm3/m32, negate the multiplication
xmm2, xmm3/m32{er}
result and add to xmm2 and put result in xmm1.
EVEX.LLIG.66.0F38.W0 AD /r
B
V/V
AVX512F
Multiply scalar single-precision floating-point value
VFNMADD213SS xmm1 {k1}{z},
OR AVX10.1
from xmm1 and xmm2, negate the multiplication
xmm2, xmm3/m32{er}
result and add to xmm3/m32 and put result in xmm1.
EVEX.LLIG.66.0F38.W0 BD /r
B
V/V
AVX512F
Multiply scalar single-precision floating-point value
VFNMADD231SS xmm1 {k1}{z},
OR AVX10.1
from xmm2 and xmm3/m32, negate the multiplication
xmm2, xmm3/m32{er}
result and add to xmm1 and put result in xmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Tuple1 Scalar
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMADD132SS: Multiplies the low packed single precision floating-point value from the first source operand to
the low packed single precision floating-point value in the third source operand, adds the negated infinite precision
intermediate result to the low packed single precision floating-point value in the second source operand, performs
rounding and stores the resulting packed single precision floating-point value to the destination operand (first
source operand).
VFNMADD213SS: Multiplies the low packed single precision floating-point value from the second source operand to
the low packed single precision floating-point value in the first source operand, adds the negated infinite precision
intermediate result to the low packed single precision floating-point value in the third source operand, performs
rounding and stores the resulting packed single precision floating-point value to the destination operand (first
source operand).
VFNMADD231SS: Multiplies the low packed single precision floating-point value from the second source operand to
the low packed single precision floating-point value in the third source operand, adds the negated infinite precision
intermediate result to the low packed single precision floating-point value in the first source operand, performs
rounding and stores the resulting packed single precision floating-point value to the destination operand (first
source operand).
VEX.128 and EVEX encoded version: The destination operand (also first source operand) is encoded in reg_field.
The second source operand is encoded in VEX.vvvv/EVEX.vvvv. The third source operand is encoded in rm_field.
Bits 127:32 of the destination are unchanged. Bits MAXVL-1:128 of the destination register are zeroed.
EVEX encoded version: The low doubleword element of the destination is updated according to the writemask.
Compiler tools may optionally support a complementary mnemonic for each instruction mnemonic listed in the
opcode/instruction column of the summary table. The behavior of the complementary mnemonic in situations
VFNMADD132SS/VFNMADD213SS/VFNMADD231SS-Fused Negative Multiply-Add of Scalar Single Precision Floating-Point Values
Vol. 2C
5-322
involving NANs are governed by the definition of the instruction mnemonic defined in the opcode/instruction
column.
Operation
In the operations below, “*” and “+” symbols represent multiplication and addition with infinite precision inputs and outputs (no
rounding).
VFNMADD132SS DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[31:0] := RoundFPControl(-(DEST[31:0]*SRC3[31:0]) + SRC2[31:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] := 0
FI;
FI;
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMADD213SS DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[31:0] := RoundFPControl(-(SRC2[31:0]*DEST[31:0]) + SRC3[31:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] := 0
FI;
FI;
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMADD132SS/VFNMADD213SS/VFNMADD231SS-Fused Negative Multiply-Add of Scalar Single Precision Floating-Point Values
Vol. 2C
5-323
VFNMADD231SS DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[31:0] := RoundFPControl(-(SRC2[31:0]*SRC3[63:0]) + DEST[31:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] := 0
FI;
FI;
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMADD132SS DEST, SRC2, SRC3 (VEX encoded version)
DEST[31:0] := RoundFPControl_MXCSR(- (DEST[31:0]*SRC3[31:0]) + SRC2[31:0])
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMADD213SS DEST, SRC2, SRC3 (VEX encoded version)
DEST[31:0] := RoundFPControl_MXCSR(- (SRC2[31:0]*DEST[31:0]) + SRC3[31:0])
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMADD231SS DEST, SRC2, SRC3 (VEX encoded version)
DEST[31:0] := RoundFPControl_MXCSR(- (SRC2[31:0]*SRC3[31:0]) + DEST[31:0])
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFNMADDxxxSS __m128 _mm_fnmadd_round_ss(__m128 a, __m128 b, __m128 c, int r);
VFNMADDxxxSS __m128 _mm_mask_fnmadd_ss(__m128 a, __mmask8 k, __m128 b, __m128 c);
VFNMADDxxxSS __m128 _mm_maskz_fnmadd_ss(__mmask8 k, __m128 a, __m128 b, __m128 c);
VFNMADDxxxSS __m128 _mm_mask3_fnmadd_ss(__m128 a, __m128 b, __m128 c, __mmask8 k);
VFNMADDxxxSS __m128 _mm_mask_fnmadd_round_ss(__m128 a, __mmask8 k, __m128 b, __m128 c, int r);
VFNMADDxxxSS __m128 _mm_maskz_fnmadd_round_ss(__mmask8 k, __m128 a, __m128 b, __m128 c, int r);
VFNMADDxxxSS __m128 _mm_mask3_fnmadd_round_ss(__m128 a, __m128 b, __m128 c, __mmask8 k, int r);
VFNMADDxxxSS __m128 _mm_fnmadd_ss (__m128 a, __m128 b, __m128 c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal
Other Exceptions
VEX-encoded instructions, see Table 2-20, “Type 3 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-49, “Type E3 Class Exception Conditions.”
VFNMADD132SS/VFNMADD213SS/VFNMADD231SS-Fused Negative Multiply-Add of Scalar Single Precision Floating-Point Values
Vol. 2C
5-324
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of
Packed Double Precision Floating-Point Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
VEX.128.66.0F38.W1 9E /r
A
V/V
FMA
Multiply packed double precision floating-point values
VFNMSUB132PD xmm1, xmm2,
from xmm1 and xmm3/mem, negate the
xmm3/m128
multiplication result and subtract xmm2 and put
result in xmm1.
VEX.128.66.0F38.W1 AE /r
A
V/V
FMA
Multiply packed double precision floating-point values
VFNMSUB213PD xmm1, xmm2,
from xmm1 and xmm2, negate the multiplication
xmm3/m128
result and subtract xmm3/mem and put result in
xmm1.
VEX.128.66.0F38.W1 BE /r
A
V/V
FMA
Multiply packed double precision floating-point values
VFNMSUB231PD xmm1, xmm2,
from xmm2 and xmm3/mem, negate the
xmm3/m128
multiplication result and subtract xmm1 and put
result in xmm1.
VEX.256.66.0F38.W1 9E /r
A
V/V
FMA
Multiply packed double precision floating-point values
VFNMSUB132PD ymm1, ymm2,
from ymm1 and ymm3/mem, negate the
ymm3/m256
multiplication result and subtract ymm2 and put
result in ymm1.
VEX.256.66.0F38.W1 AE /r
A
V/V
FMA
Multiply packed double precision floating-point values
VFNMSUB213PD ymm1, ymm2,
from ymm1 and ymm2, negate the multiplication
ymm3/m256
result and subtract ymm3/mem and put result in
ymm1.
VEX.256.66.0F38.W1 BE /r
A
V/V
FMA
Multiply packed double precision floating-point values
VFNMSUB231PD ymm1, ymm2,
from ymm2 and ymm3/mem, negate the
ymm3/m256
multiplication result and subtract ymm1 and put
result in ymm1.
EVEX.128.66.0F38.W1 9E /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point values
VFNMSUB132PD xmm1 {k1}{z},
AVX512F) OR
from xmm1 and xmm3/m128/m64bcst, negate the
xmm2, xmm3/m128/m64bcst
AVX10.1
multiplication result and subtract xmm2 and put
result in xmm1.
EVEX.128.66.0F38.W1 AE /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point values
VFNMSUB213PD xmm1 {k1}{z},
AVX512F) OR
from xmm1 and xmm2, negate the multiplication
xmm2, xmm3/m128/m64bcst
AVX10.1
result and subtract xmm3/m128/m64bcst and put
result in xmm1.
EVEX.128.66.0F38.W1 BE /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point values
VFNMSUB231PD xmm1 {k1}{z},
AVX512F) OR
from xmm2 and xmm3/m128/m64bcst, negate the
xmm2, xmm3/m128/m64bcst
AVX10.1
multiplication result and subtract xmm1 and put
result in xmm1.
EVEX.256.66.0F38.W1 9E /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point values
VFNMSUB132PD ymm1 {k1}{z},
AVX512F) OR
from ymm1 and ymm3/m256/m64bcst, negate the
ymm2, ymm3/m256/m64bcst
AVX10.1
multiplication result and subtract ymm2 and put
result in ymm1.
EVEX.256.66.0F38.W1 AE /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point values
VFNMSUB213PD ymm1 {k1}{z},
AVX512F) OR
from ymm1 and ymm2, negate the multiplication
ymm2, ymm3/m256/m64bcst
AVX10.1
result and subtract ymm3/m256/m64bcst and put
result in ymm1.
EVEX.256.66.0F38.W1 BE /r
B
V/V
(AVX512VL AND
Multiply packed double precision floating-point values
VFNMSUB231PD ymm1 {k1}{z},
AVX512F) OR
from ymm2 and ymm3/m256/m64bcst, negate the
ymm2, ymm3/m256/m64bcst
AVX10.1
multiplication result and subtract ymm1 and put
result in ymm1.
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-325
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.512.66.0F38.W1 9E /r
B
V/V
AVX512F
Multiply packed double precision floating-point values
VFNMSUB132PD zmm1 {k1}{z},
OR AVX10.1
from zmm1 and zmm3/m512/m64bcst, negate the
zmm2, zmm3/m512/m64bcst{er}
multiplication result and subtract zmm2 and put
result in zmm1.
EVEX.512.66.0F38.W1 AE /r
B
V/V
AVX512F
Multiply packed double precision floating-point values
VFNMSUB213PD zmm1 {k1}{z},
OR AVX10.1
from zmm1 and zmm2, negate the multiplication
zmm2, zmm3/m512/m64bcst{er}
result and subtract zmm3/m512/m64bcst and put
result in zmm1.
EVEX.512.66.0F38.W1 BE /r
B
V/V
AVX512F
Multiply packed double precision floating-point values
VFNMSUB231PD zmm1 {k1}{z},
OR AVX10.1
from zmm2 and zmm3/m512/m64bcst, negate the
zmm2, zmm3/m512/m64bcst{er}
multiplication result and subtract zmm1 and put
result in zmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMSUB132PD: Multiplies the two, four or eight packed double precision floating-point values from the first
source operand to the two, four or eight packed double precision floating-point values in the third source operand.
From negated infinite precision intermediate results, subtracts the two, four or eight packed double precision
floating-point values in the second source operand, performs rounding and stores the resulting two, four or eight
packed double precision floating-point values to the destination operand (first source operand).
VFNMSUB213PD: Multiplies the two, four or eight packed double precision floating-point values from the second
source operand to the two, four or eight packed double precision floating-point values in the first source operand.
From negated infinite precision intermediate results, subtracts the two, four or eight packed double precision
floating-point values in the third source operand, performs rounding and stores the resulting two, four or eight
packed double precision floating-point values to the destination operand (first source operand).
VFNMSUB231PD: Multiplies the two, four or eight packed double precision floating-point values from the second
source to the two, four or eight packed double precision floating-point values in the third source operand. From
negated infinite precision intermediate results, subtracts the two, four or eight packed double precision floating-
point values in the first source operand, performs rounding and stores the resulting two, four or eight packed
double precision floating-point values to the destination operand (first source operand).
EVEX encoded versions: The destination operand (also first source operand) and the second source operand are
ZMM/YMM/XMM register. The third source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory loca-
tion or a 512/256/128-bit vector broadcasted from a 64-bit memory location. The destination operand is condition-
ally updated with write mask k1.
VEX.256 encoded version: The destination operand (also first source operand) is a YMM register and encoded in
reg_field. The second source operand is a YMM register and encoded in VEX.vvvv. The third source operand is a
YMM register or a 256-bit memory location and encoded in rm_field.
VEX.128 encoded version: The destination operand (also first source operand) is a XMM register and encoded in
reg_field. The second source operand is a XMM register and encoded in VEX.vvvv. The third source operand is a
XMM register or a 128-bit memory location and encoded in rm_field. The upper 128 bits of the YMM destination
register are zeroed.
Operation
In the operations below, “*” and “-” symbols represent multiplication and subtraction with infinite precision inputs and outputs (no
rounding).
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-326
VFNMSUB132PD DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 64*i;
DEST[n+63:n] := RoundFPControl_MXCSR( - (DEST[n+63:n]*SRC3[n+63:n]) - SRC2[n+63:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMSUB213PD DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 64*i;
DEST[n+63:n] := RoundFPControl_MXCSR( - (SRC2[n+63:n]*DEST[n+63:n]) - SRC3[n+63:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMSUB231PD DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 64*i;
DEST[n+63:n] := RoundFPControl_MXCSR( - (SRC2[n+63:n]*SRC3[n+63:n]) - DEST[n+63:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-327
VFNMSUB132PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] :=
RoundFPControl(-(DEST[i+63:i]*SRC3[i+63:i]) - SRC2[i+63:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(DEST[i+63:i]*SRC3[63:0]) - SRC2[i+63:i])
ELSE
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(DEST[i+63:i]*SRC3[i+63:i]) - SRC2[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-328
VFNMSUB213PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] :=
RoundFPControl(-(SRC2[i+63:i]*DEST[i+63:i]) - SRC3[i+63:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB213PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*DEST[i+63:i]) - SRC3[63:0])
ELSE
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*DEST[i+63:i]) - SRC3[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-329
VFNMSUB231PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (2, 128), (4, 256), (8, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] :=
RoundFPControl(-(SRC2[i+63:i]*SRC3[i+63:i]) - DEST[i+63:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB231PD DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*SRC3[63:0]) - DEST[i+63:i])
ELSE
DEST[i+63:i] :=
RoundFPControl_MXCSR(-(SRC2[i+63:i]*SRC3[i+63:i]) - DEST[i+63:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-330
Intel C/C++ Compiler Intrinsic Equivalent
VFNMSUBxxxPD __m512d _mm512_fnmsub_pd(__m512d a, __m512d b, __m512d c);
VFNMSUBxxxPD __m512d _mm512_fnmsub_round_pd(__m512d a, __m512d b, __m512d c, int r);
VFNMSUBxxxPD __m512d _mm512_mask_fnmsub_pd(__m512d a, __mmask8 k, __m512d b, __m512d c);
VFNMSUBxxxPD __m512d _mm512_maskz_fnmsub_pd(__mmask8 k, __m512d a, __m512d b, __m512d c);
VFNMSUBxxxPD __m512d _mm512_mask3_fnmsub_pd(__m512d a, __m512d b, __m512d c, __mmask8 k);
VFNMSUBxxxPD __m512d _mm512_mask_fnmsub_round_pd(__m512d a, __mmask8 k, __m512d b, __m512d c, int r);
VFNMSUBxxxPD __m512d _mm512_maskz_fnmsub_round_pd(__mmask8 k, __m512d a, __m512d b, __m512d c, int r);
VFNMSUBxxxPD __m512d _mm512_mask3_fnmsub_round_pd(__m512d a, __m512d b, __m512d c, __mmask8 k, int r);
VFNMSUBxxxPD __m256d _mm256_mask_fnmsub_pd(__m256d a, __mmask8 k, __m256d b, __m256d c);
VFNMSUBxxxPD __m256d _mm256_maskz_fnmsub_pd(__mmask8 k, __m256d a, __m256d b, __m256d c);
VFNMSUBxxxPD __m256d _mm256_mask3_fnmsub_pd(__m256d a, __m256d b, __m256d c, __mmask8 k);
VFNMSUBxxxPD __m128d _mm_mask_fnmsub_pd(__m128d a, __mmask8 k, __m128d b, __m128d c);
VFNMSUBxxxPD __m128d _mm_maskz_fnmsub_pd(__mmask8 k, __m128d a, __m128d b, __m128d c);
VFNMSUBxxxPD __m128d _mm_mask3_fnmsub_pd(__m128d a, __m128d b, __m128d c, __mmask8 k);
VFNMSUBxxxPD __m128d _mm_fnmsub_pd (__m128d a, __m128d b, __m128d c);
VFNMSUBxxxPD __m256d _mm256_fnmsub_pd (__m256d a, __m256d b, __m256d c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-19, “Type 2 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-48, “Type E2 Class Exception Conditions.”
VFNMSUB132PD/VFNMSUB213PD/VFNMSUB231PD-Fused Negative Multiply-Subtract of Packed Double Precision Floating-Point
Vol. 2C
5-331
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of
Packed Single Precision Floating-Point Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
VEX.128.66.0F38.W0 9E /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMSUB132PS xmm1, xmm2,
from xmm1 and xmm3/mem, negate the
xmm3/m128
multiplication result and subtract xmm2 and put
result in xmm1.
VEX.128.66.0F38.W0 AE /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMSUB213PS xmm1, xmm2,
from xmm1 and xmm2, negate the multiplication
xmm3/m128
result and subtract xmm3/mem and put result in
xmm1.
VEX.128.66.0F38.W0 BE /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMSUB231PS xmm1, xmm2,
from xmm2 and xmm3/mem, negate the
xmm3/m128
multiplication result and subtract xmm1 and put
result in xmm1.
VEX.256.66.0F38.W0 9E /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMSUB132PS ymm1, ymm2,
from ymm1 and ymm3/mem, negate the
ymm3/m256
multiplication result and subtract ymm2 and put
result in ymm1.
VEX.256.66.0F38.W0 AE /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMSUB213PS ymm1, ymm2,
from ymm1 and ymm2, negate the multiplication
ymm3/m256
result and subtract ymm3/mem and put result in
ymm1.
VEX.256.66.0F38.0 BE /r
A
V/V
FMA
Multiply packed single precision floating-point values
VFNMSUB231PS ymm1, ymm2,
from ymm2 and ymm3/mem, negate the
ymm3/m256
multiplication result and subtract ymm1 and put
result in ymm1.
EVEX.128.66.0F38.W0 9E /r
B
V/V
(AVX512VL AND
Multiply packed single-precision floating-point values
VFNMSUB132PS xmm1 {k1}{z},
AVX512F) OR
from xmm1 and xmm3/m128/m32bcst, negate the
xmm2, xmm3/m128/m32bcst
AVX10.1
multiplication result and subtract xmm2 and put
result in xmm1.
EVEX.128.66.0F38.W0 AE /r
B
V/V
(AVX512VL AND
Multiply packed single-precision floating-point values
VFNMSUB213PS xmm1 {k1}{z},
AVX512F) OR
from xmm1 and xmm2, negate the multiplication
xmm2, xmm3/m128/m32bcst
AVX10.1
result and subtract xmm3/m128/m32bcst and put
result in xmm1.
EVEX.128.66.0F38.W0 BE /r
B
V/V
(AVX512VL AND
Multiply packed single-precision floating-point values
VFNMSUB231PS xmm1 {k1}{z},
AVX512F) OR
from xmm2 and xmm3/m128/m32bcst, negate the
xmm2, xmm3/m128/m32bcst
AVX10.1
multiplication result subtract add to xmm1 and put
result in xmm1.
EVEX.256.66.0F38.W0 9E /r
B
V/V
(AVX512VL AND
Multiply packed single-precision floating-point values
VFNMSUB132PS ymm1 {k1}{z},
AVX512F) OR
from ymm1 and ymm3/m256/m32bcst, negate the
ymm2, ymm3/m256/m32bcst
AVX10.1
multiplication result and subtract ymm2 and put
result in ymm1.
EVEX.256.66.0F38.W0 AE /r
B
V/V
(AVX512VL AND
Multiply packed single-precision floating-point values
VFNMSUB213PS ymm1 {k1}{z},
AVX512F) OR
from ymm1 and ymm2, negate the multiplication
ymm2, ymm3/m256/m32bcst
AVX10.1
result and subtract ymm3/m256/m32bcst and put
result in ymm1.
EVEX.256.66.0F38.W0 BE /r
B
V/V
(AVX512VL AND
Multiply packed single-precision floating-point values
VFNMSUB231PS ymm1 {k1}{z},
AVX512F) OR
from ymm2 and ymm3/m256/m32bcst, negate the
ymm2, ymm3/m256/m32bcst
AVX10.1
multiplication result subtract add to ymm1 and put
result in ymm1.
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-332
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.512.66.0F38.W0 9E /r
B
V/V
AVX512F
Multiply packed single-precision floating-point values
VFNMSUB132PS zmm1 {k1}{z},
OR AVX10.1
from zmm1 and zmm3/m512/m32bcst, negate the
zmm2, zmm3/m512/m32bcst{er}
multiplication result and subtract zmm2 and put
result in zmm1.
EVEX.512.66.0F38.W0 AE /r
B
V/V
AVX512F
Multiply packed single-precision floating-point values
VFNMSUB213PS zmm1 {k1}{z},
OR AVX10.1
from zmm1 and zmm2, negate the multiplication
zmm2, zmm3/m512/m32bcst{er}
result and subtract zmm3/m512/m32bcst and put
result in zmm1.
EVEX.512.66.0F38.W0 BE /r
B
V/V
AVX512F
Multiply packed single-precision floating-point values
VFNMSUB231PS zmm1 {k1}{z},
OR AVX10.1
from zmm2 and zmm3/m512/m32bcst, negate the
zmm2, zmm3/m512/m32bcst{er}
multiplication result subtract add to zmm1 and put
result in zmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Full
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMSUB132PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the first
source operand to the four, eight or sixteen packed single precision floating-point values in the third source
operand. From negated infinite precision intermediate results, subtracts the four, eight or sixteen packed single
precision floating-point values in the second source operand, performs rounding and stores the resulting four, eight
or sixteen packed single precision floating-point values to the destination operand (first source operand).
VFNMSUB213PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the second
source operand to the four, eight or sixteen packed single precision floating-point values in the first source
operand. From negated infinite precision intermediate results, subtracts the four, eight or sixteen packed single
precision floating-point values in the third source operand, performs rounding and stores the resulting four, eight
or sixteen packed single precision floating-point values to the destination operand (first source operand).
VFNMSUB231PS: Multiplies the four, eight or sixteen packed single precision floating-point values from the second
source to the four, eight or sixteen packed single precision floating-point values in the third source operand. From
negated infinite precision intermediate results, subtracts the four, eight or sixteen packed single precision floating-
point values in the first source operand, performs rounding and stores the resulting four, eight or sixteen packed
single precision floating-point values to the destination operand (first source operand).
EVEX encoded versions: The destination operand (also first source operand) and the second source operand are
ZMM/YMM/XMM register. The third source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory loca-
tion or a 512/256/128-bit vector broadcasted from a 32-bit memory location. The destination operand is condition-
ally updated with write mask k1.
VEX.256 encoded version: The destination operand (also first source operand) is a YMM register and encoded in
reg_field. The second source operand is a YMM register and encoded in VEX.vvvv. The third source operand is a
YMM register or a 256-bit memory location and encoded in rm_field.
VEX.128 encoded version: The destination operand (also first source operand) is a XMM register and encoded in
reg_field. The second source operand is a XMM register and encoded in VEX.vvvv. The third source operand is a
XMM register or a 128-bit memory location and encoded in rm_field. The upper 128 bits of the YMM destination
register are zeroed.
Operation
In the operations below, “*” and “-” symbols represent multiplication and subtraction with infinite precision inputs and outputs (no
rounding).
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-333
VFNMSUB132PS DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 32*i;
DEST[n+31:n] := RoundFPControl_MXCSR( - (DEST[n+31:n]*SRC3[n+31:n]) - SRC2[n+31:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMSUB213PS DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 32*i;
DEST[n+31:n] := RoundFPControl_MXCSR( - (SRC2[n+31:n]*DEST[n+31:n]) - SRC3[n+31:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMSUB231PS DEST, SRC2, SRC3 (VEX encoded version)
IF (VEX.128) THEN
MAXNUM := 2
ELSEIF (VEX.256)
MAXNUM := 4
FI
For i = 0 to MAXNUM-1 {
n := 32*i;
DEST[n+31:n] := RoundFPControl_MXCSR( - (SRC2[n+31:n]*SRC3[n+31:n]) - DEST[n+31:n])
}
IF (VEX.128) THEN
DEST[MAXVL-1:128] := 0
ELSEIF (VEX.256)
DEST[MAXVL-1:256] := 0
FI
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-334
VFNMSUB132PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
RoundFPControl(-(DEST[i+31:i]*SRC3[i+31:i]) - SRC2[i+31:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(DEST[i+31:i]*SRC3[31:0]) - SRC2[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(DEST[i+31:i]*SRC3[i+31:i]) - SRC2[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-335
VFNMSUB213PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*DEST[i+31:i]) - SRC3[i+31:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB213PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*DEST[i+31:i]) - SRC3[31:0])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*DEST[i+31:i]) - SRC3[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-336
VFNMSUB231PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a register)
(KL, VL) = (4, 128), (8, 256), (16, 512)
IF (VL = 512) AND (EVEX.b = 1)
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*SRC3[i+31:i]) - DEST[i+31:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB231PS DEST, SRC2, SRC3 (EVEX encoded version, when src3 operand is a memory source)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b = 1)
THEN
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*SRC3[31:0]) - DEST[i+31:i])
ELSE
DEST[i+31:i] :=
RoundFPControl_MXCSR(-(SRC2[i+31:i]*SRC3[i+31:i]) - DEST[i+31:i])
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-337
Intel C/C++ Compiler Intrinsic Equivalent
VFNMSUBxxxPS __m512 _mm512_fnmsub_ps(__m512 a, __m512 b, __m512 c);
VFNMSUBxxxPS __m512 _mm512_fnmsub_round_ps(__m512 a, __m512 b, __m512 c, int r);
VFNMSUBxxxPS __m512 _mm512_mask_fnmsub_ps(__m512 a, __mmask16 k, __m512 b, __m512 c);
VFNMSUBxxxPS __m512 _mm512_maskz_fnmsub_ps(__mmask16 k, __m512 a, __m512 b, __m512 c);
VFNMSUBxxxPS __m512 _mm512_mask3_fnmsub_ps(__m512 a, __m512 b, __m512 c, __mmask16 k);
VFNMSUBxxxPS __m512 _mm512_mask_fnmsub_round_ps(__m512 a, __mmask16 k, __m512 b, __m512 c, int r);
VFNMSUBxxxPS __m512 _mm512_maskz_fnmsub_round_ps(__mmask16 k, __m512 a, __m512 b, __m512 c, int r);
VFNMSUBxxxPS __m512 _mm512_mask3_fnmsub_round_ps(__m512 a, __m512 b, __m512 c, __mmask16 k, int r);
VFNMSUBxxxPS __m256 _mm256_mask_fnmsub_ps(__m256 a, __mmask8 k, __m256 b, __m256 c);
VFNMSUBxxxPS __m256 _mm256_maskz_fnmsub_ps(__mmask8 k, __m256 a, __m256 b, __m256 c);
VFNMSUBxxxPS __m256 _mm256_mask3_fnmsub_ps(__m256 a, __m256 b, __m256 c, __mmask8 k);
VFNMSUBxxxPS __m128 _mm_mask_fnmsub_ps(__m128 a, __mmask8 k, __m128 b, __m128 c);
VFNMSUBxxxPS __m128 _mm_maskz_fnmsub_ps(__mmask8 k, __m128 a, __m128 b, __m128 c);
VFNMSUBxxxPS __m128 _mm_mask3_fnmsub_ps(__m128 a, __m128 b, __m128 c, __mmask8 k);
VFNMSUBxxxPS __m128 _mm_fnmsub_ps (__m128 a, __m128 b, __m128 c);
VFNMSUBxxxPS __m256 _mm256_fnmsub_ps (__m256 a, __m256 b, __m256 c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-19, “Type 2 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-48, “Type E2 Class Exception Conditions.”
VFNMSUB132PS/VFNMSUB213PS/VFNMSUB231PS-Fused Negative Multiply-Subtract of Packed Single Precision Floating-Point Val-
Vol. 2C
5-338
VFNMSUB132SD/VFNMSUB213SD/VFNMSUB231SD-Fused Negative Multiply-Subtract of
Scalar Double Precision Floating-Point Values
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
Bit Mode
Feature Flag
Support
VEX.LIG.66.0F38.W1 9F /r
A
V/V
FMA
Multiply scalar double precision floating-point value from
VFNMSUB132SD xmm1, xmm2,
xmm1 and xmm3/mem, negate the multiplication result
xmm3/m64
and subtract xmm2 and put result in xmm1.
VEX.LIG.66.0F38.W1 AF /r
A
V/V
FMA
Multiply scalar double precision floating-point value from
VFNMSUB213SD xmm1, xmm2,
xmm1 and xmm2, negate the multiplication result and
xmm3/m64
subtract xmm3/mem and put result in xmm1.
VEX.LIG.66.0F38.W1 BF /r
A
V/V
FMA
Multiply scalar double precision floating-point value from
VFNMSUB231SD xmm1, xmm2,
xmm2 and xmm3/mem, negate the multiplication result
xmm3/m64
and subtract xmm1 and put result in xmm1.
EVEX.LLIG.66.0F38.W1 9F /r
B
V/V
AVX512F
Multiply scalar double precision floating-point value from
VFNMSUB132SD xmm1 {k1}{z},
OR AVX10.1
xmm1 and xmm3/m64, negate the multiplication result
xmm2, xmm3/m64{er}
and subtract xmm2 and put result in xmm1.
EVEX.LLIG.66.0F38.W1 AF /r
B
V/V
AVX512F
Multiply scalar double precision floating-point value from
VFNMSUB213SD xmm1 {k1}{z},
OR AVX10.1
xmm1 and xmm2, negate the multiplication result and
xmm2, xmm3/m64{er}
subtract xmm3/m64 and put result in xmm1.
EVEX.LLIG.66.0F38.W1 BF /r
B
V/V
AVX512F
Multiply scalar double precision floating-point value from
VFNMSUB231SD xmm1 {k1}{z},
OR AVX10.1
xmm2 and xmm3/m64, negate the multiplication result
xmm2, xmm3/m64{er}
and subtract xmm1 and put result in xmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Tuple1 Scalar
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMSUB132SD: Multiplies the low packed double precision floating-point value from the first source operand to
the low packed double precision floating-point value in the third source operand. From negated infinite precision
intermediate result, subtracts the low double precision floating-point value in the second source operand, performs
rounding and stores the resulting packed double precision floating-point value to the destination operand (first
source operand).
VFNMSUB213SD: Multiplies the low packed double precision floating-point value from the second source operand
to the low packed double precision floating-point value in the first source operand. From negated infinite precision
intermediate result, subtracts the low double precision floating-point value in the third source operand, performs
rounding and stores the resulting packed double precision floating-point value to the destination operand (first
source operand).
VFNMSUB231SD: Multiplies the low packed double precision floating-point value from the second source to the low
packed double precision floating-point value in the third source operand. From negated infinite precision interme-
diate result, subtracts the low double precision floating-point value in the first source operand, performs rounding
and stores the resulting packed double precision floating-point value to the destination operand (first source
operand).
VEX.128 and EVEX encoded version: The destination operand (also first source operand) is encoded in reg_field.
The second source operand is encoded in VEX.vvvv/EVEX.vvvv. The third source operand is encoded in rm_field.
Bits 127:64 of the destination are unchanged. Bits MAXVL-1:128 of the destination register are zeroed.
EVEX encoded version: The low quadword element of the destination is updated according to the writemask.
Compiler tools may optionally support a complementary mnemonic for each instruction mnemonic listed in the
opcode/instruction column of the summary table. The behavior of the complementary mnemonic in situations
VFNMSUB132SD/VFNMSUB213SD/VFNMSUB231SD-Fused Negative Multiply-Subtract of Scalar Double Precision Floating-Point Val-
Vol. 2C
5-339
involving NANs are governed by the definition of the instruction mnemonic defined in the opcode/instruction
column.
Operation
In the operations below, “*” and “-” symbols represent multiplication and subtraction with infinite precision inputs and outputs (no
rounding).
VFNMSUB132SD DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[63:0] := RoundFPControl(-(DEST[63:0]*SRC3[63:0]) - SRC2[63:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] := 0
FI;
FI;
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMSUB213SD DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[63:0] := RoundFPControl(-(SRC2[63:0]*DEST[63:0]) - SRC3[63:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] := 0
FI;
FI;
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMSUB132SD/VFNMSUB213SD/VFNMSUB231SD-Fused Negative Multiply-Subtract of Scalar Double Precision Floating-Point Val-
Vol. 2C
5-340
VFNMSUB231SD DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[63:0] := RoundFPControl(-(SRC2[63:0]*SRC3[63:0]) - DEST[63:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[63:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[63:0] := 0
FI;
FI;
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMSUB132SD DEST, SRC2, SRC3 (VEX encoded version)
DEST[63:0] := RoundFPControl_MXCSR(- (DEST[63:0]*SRC3[63:0]) - SRC2[63:0])
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMSUB213SD DEST, SRC2, SRC3 (VEX encoded version)
DEST[63:0] := RoundFPControl_MXCSR(- (SRC2[63:0]*DEST[63:0]) - SRC3[63:0])
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
VFNMSUB231SD DEST, SRC2, SRC3 (VEX encoded version)
DEST[63:0] := RoundFPControl_MXCSR(- (SRC2[63:0]*SRC3[63:0]) - DEST[63:0])
DEST[127:64] := DEST[127:64]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFNMSUBxxxSD __m128d _mm_fnmsub_round_sd(__m128d a, __m128d b, __m128d c, int r);
VFNMSUBxxxSD __m128d _mm_mask_fnmsub_sd(__m128d a, __mmask8 k, __m128d b, __m128d c);
VFNMSUBxxxSD __m128d _mm_maskz_fnmsub_sd(__mmask8 k, __m128d a, __m128d b, __m128d c);
VFNMSUBxxxSD __m128d _mm_mask3_fnmsub_sd(__m128d a, __m128d b, __m128d c, __mmask8 k);
VFNMSUBxxxSD __m128d _mm_mask_fnmsub_round_sd(__m128d a, __mmask8 k, __m128d b, __m128d c, int r);
VFNMSUBxxxSD __m128d _mm_maskz_fnmsub_round_sd(__mmask8 k, __m128d a, __m128d b, __m128d c, int r);
VFNMSUBxxxSD __m128d _mm_mask3_fnmsub_round_sd(__m128d a, __m128d b, __m128d c, __mmask8 k, int r);
VFNMSUBxxxSD __m128d _mm_fnmsub_sd (__m128d a, __m128d b, __m128d c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-20, “Type 3 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-49, “Type E3 Class Exception Conditions.”
VFNMSUB132SD/VFNMSUB213SD/VFNMSUB231SD-Fused Negative Multiply-Subtract of Scalar Double Precision Floating-Point Val-
Vol. 2C
5-341
VFNMSUB132SS/VFNMSUB213SS/VFNMSUB231SS-Fused Negative Multiply-Subtract of
Scalar Single Precision Floating-Point Values
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
Bit Mode
Feature Flag
Support
VEX.LIG.66.0F38.W0 9F /r
A
V/V
FMA
Multiply scalar single precision floating-point value from
VFNMSUB132SS xmm1, xmm2,
xmm1 and xmm3/m32, negate the multiplication result
xmm3/m32
and subtract xmm2 and put result in xmm1.
VEX.LIG.66.0F38.W0 AF /r
A
V/V
FMA
Multiply scalar single precision floating-point value from
VFNMSUB213SS xmm1, xmm2,
xmm1 and xmm2, negate the multiplication result and
xmm3/m32
subtract xmm3/m32 and put result in xmm1.
VEX.LIG.66.0F38.W0 BF /r
A
V/V
FMA
Multiply scalar single precision floating-point value from
VFNMSUB231SS xmm1, xmm2,
xmm2 and xmm3/m32, negate the multiplication result
xmm3/m32
and subtract xmm1 and put result in xmm1.
EVEX.LLIG.66.0F38.W0 9F /r
B
V/V
AVX512F
Multiply scalar single-precision floating-point value from
VFNMSUB132SS xmm1 {k1}{z},
OR AVX10.1
xmm1 and xmm3/m32, negate the multiplication result
xmm2, xmm3/m32{er}
and subtract xmm2 and put result in xmm1.
EVEX.LLIG.66.0F38.W0 AF /r
B
V/V
AVX512F
Multiply scalar single-precision floating-point value from
VFNMSUB213SS xmm1 {k1}{z},
OR AVX10.1
xmm1 and xmm2, negate the multiplication result and
xmm2, xmm3/m32{er}
subtract xmm3/m32 and put result in xmm1.
EVEX.LLIG.66.0F38.W0 BF /r
B
V/V
AVX512F
Multiply scalar single-precision floating-point value from
VFNMSUB231SS xmm1 {k1}{z},
OR AVX10.1
xmm2 and xmm3/m32, negate the multiplication result
xmm2, xmm3/m32{er}
and subtract xmm1 and put result in xmm1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
B
Tuple1 Scalar
ModRM:reg (r, w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
VFNMSUB132SS: Multiplies the low packed single precision floating-point value from the first source operand to
the low packed single precision floating-point value in the third source operand. From negated infinite precision
intermediate result, the low single precision floating-point value in the second source operand, performs rounding
and stores the resulting packed single precision floating-point value to the destination operand (first source
operand).
VFNMSUB213SS: Multiplies the low packed single precision floating-point value from the second source operand to
the low packed single precision floating-point value in the first source operand. From negated infinite precision
intermediate result, the low single precision floating-point value in the third source operand, performs rounding
and stores the resulting packed single precision floating-point value to the destination operand (first source
operand).
VFNMSUB231SS: Multiplies the low packed single precision floating-point value from the second source to the low
packed single precision floating-point value in the third source operand. From negated infinite precision interme-
diate result, the low single precision floating-point value in the first source operand, performs rounding and stores
the resulting packed single precision floating-point value to the destination operand (first source operand).
VEX.128 and EVEX encoded version: The destination operand (also first source operand) is encoded in reg_field.
The second source operand is encoded in VEX.vvvv/EVEX.vvvv. The third source operand is encoded in rm_field.
Bits 127:32 of the destination are unchanged. Bits MAXVL-1:128 of the destination register are zeroed.
EVEX encoded version: The low doubleword element of the destination is updated according to the writemask.
Compiler tools may optionally support a complementary mnemonic for each instruction mnemonic listed in the
opcode/instruction column of the summary table. The behavior of the complementary mnemonic in situations
VFNMSUB132SS/VFNMSUB213SS/VFNMSUB231SS-Fused Negative Multiply-Subtract of Scalar Single Precision Floating-Point Val-
Vol. 2C
5-342
involving NANs are governed by the definition of the instruction mnemonic defined in the opcode/instruction
column.
Operation
In the operations below, “*” and “-” symbols represent multiplication and subtraction with infinite precision inputs and outputs (no
rounding).
VFNMSUB132SS DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[31:0] := RoundFPControl(-(DEST[31:0]*SRC3[31:0]) - SRC2[31:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] := 0
FI;
FI;
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMSUB213SS DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[31:0] := RoundFPControl(-(SRC2[31:0]*DEST[31:0]) - SRC3[31:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] := 0
FI;
FI;
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMSUB132SS/VFNMSUB213SS/VFNMSUB231SS-Fused Negative Multiply-Subtract of Scalar Single Precision Floating-Point Val-
Vol. 2C
5-343
VFNMSUB231SS DEST, SRC2, SRC3 (EVEX encoded version)
IF (EVEX.b = 1) and SRC3 *is a register*
THEN
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(EVEX.RC);
ELSE
SET_ROUNDING_MODE_FOR_THIS_INSTRUCTION(MXCSR.RC);
FI;
IF k1[0] or *no writemask*
THEN
DEST[31:0] := RoundFPControl(-(SRC2[31:0]*SRC3[63:0]) - DEST[31:0])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[31:0] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[31:0] := 0
FI;
FI;
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMSUB132SS DEST, SRC2, SRC3 (VEX encoded version)
DEST[31:0] := RoundFPControl_MXCSR(- (DEST[31:0]*SRC3[31:0]) - SRC2[31:0])
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMSUB213SS DEST, SRC2, SRC3 (VEX encoded version)
DEST[31:0] := RoundFPControl_MXCSR(- (SRC2[31:0]*DEST[31:0]) - SRC3[31:0])
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
VFNMSUB231SS DEST, SRC2, SRC3 (VEX encoded version)
DEST[31:0] := RoundFPControl_MXCSR(- (SRC2[31:0]*SRC3[31:0]) - DEST[31:0])
DEST[127:32] := DEST[127:32]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFNMSUBxxxSS __m128 _mm_fnmsub_round_ss(__m128 a, __m128 b, __m128 c, int r);
VFNMSUBxxxSS __m128 _mm_mask_fnmsub_ss(__m128 a, __mmask8 k, __m128 b, __m128 c);
VFNMSUBxxxSS __m128 _mm_maskz_fnmsub_ss(__mmask8 k, __m128 a, __m128 b, __m128 c);
VFNMSUBxxxSS __m128 _mm_mask3_fnmsub_ss(__m128 a, __m128 b, __m128 c, __mmask8 k);
VFNMSUBxxxSS __m128 _mm_mask_fnmsub_round_ss(__m128 a, __mmask8 k, __m128 b, __m128 c, int r);
VFNMSUBxxxSS __m128 _mm_maskz_fnmsub_round_ss(__mmask8 k, __m128 a, __m128 b, __m128 c, int r);
VFNMSUBxxxSS __m128 _mm_mask3_fnmsub_round_ss(__m128 a, __m128 b, __m128 c, __mmask8 k, int r);
VFNMSUBxxxSS __m128 _mm_fnmsub_ss (__m128 a, __m128 b, __m128 c);
SIMD Floating-Point Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
VEX-encoded instructions, see Table 2-20, “Type 3 Class Exception Conditions.”
EVEX-encoded instructions, see Table 2-49, “Type E3 Class Exception Conditions.”
VFNMSUB132SS/VFNMSUB213SS/VFNMSUB231SS-Fused Negative Multiply-Subtract of Scalar Single Precision Floating-Point Val-
Vol. 2C
5-344
VFPCLASSPD-Tests Types of Packed Float64 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.128.66.0F3A.W1 66 /r ib
A
V/V
(AVX512VL AND
Tests the input for the following categories: NaN, +0, -
VFPCLASSPD k2 {k1},
AVX512DQ) OR
0, +Infinity, -Infinity, denormal, finite negative. The
xmm2/m128/m64bcst, imm8
AVX10.1
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
EVEX.256.66.0F3A.W1 66 /r ib
A
V/V
(AVX512VL AND
Tests the input for the following categories: NaN, +0, -
VFPCLASSPD k2 {k1},
AVX512DQ) OR
0, +Infinity, -Infinity, denormal, finite negative. The
ymm2/m256/m64bcst, imm8
AVX10.1
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
EVEX.512.66.0F3A.W1 66 /r ib
A
V/V
AVX512DQ
Tests the input for the following categories: NaN, +0, -
VFPCLASSPD k2 {k1},
OR AVX10.1
0, +Infinity, -Infinity, denormal, finite negative. The
zmm2/m512/m64bcst, imm8
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
The FPCLASSPD instruction checks the packed double precision floating-point values for special categories, speci-
fied by the set bits in the imm8 byte. Each set bit in imm8 specifies a category of floating-point values that the
input data element is classified against. The classified results of all specified categories of an input value are ORed
together to form the final boolean result for the input element. The result of each element is written to the corre-
sponding bit in a mask register k2 according to the writemask k1. Bits [MAX_KL-1:8/4/2] of the destination are
cleared.
The classification categories specified by imm8 are shown in Figure 5-13. The classification test for each category
is listed in Table 5-11.
7
6
5
4
3
2
1
0
SNaN
Neg. Finite
Denormal
Neg. INF
+INF
Neg. 0
+0
QNaN
Figure 5-13. Imm8 Byte Specifier of Special Case Floating-Point Values for VFPCLASSPD/SD/PS/SS
Table 5-11. Classifier Operations for VFPCLASSPD/SD/PS/SS
Bits
Imm8[0]
Imm8[1]
Imm8[2]
Imm8[3]
Imm8[4]
Imm8[5]
Imm8[6]
Imm8[7]
Category
QNAN
PosZero
NegZero
PosINF
NegINF
Denormal
Negative
SNAN
Classifier
Checks for
Checks for
Checks for -
Checks for
Checks for -
Checks for
Checks for
Checks for
QNaN
+0
0
+INF
INF
Denormal
Negative finite
SNaN
The source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory location, or a 512/256/128-bit vector
broadcasted from a 64-bit memory location.
VFPCLASSPD-Tests Types of Packed Float64 Values
Vol. 2C
5-345
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Operation
CheckFPClassDP (tsrc[63:0], imm8[7:0]){
//* Start checking the source operand for special type *//
NegNum := tsrc[63];
IF (tsrc[62:52]=07FFh) Then ExpAllOnes := 1; FI;
IF (tsrc[62:52]=0h) Then ExpAllZeros := 1;
IF (ExpAllZeros AND MXCSR.DAZ) Then
MantAllZeros := 1;
ELSIF (tsrc[51:0]=0h) Then
MantAllZeros := 1;
FI;
ZeroNumber := ExpAllZeros AND MantAllZeros
SignalingBit := tsrc[51];
sNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND NOT(SignalingBit); // sNaN
qNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND SignalingBit; // qNaN
Pzero_res := NOT(NegNum) AND ExpAllZeros AND MantAllZeros; // +0
Nzero_res := NegNum AND ExpAllZeros AND MantAllZeros; // -0
PInf_res := NOT(NegNum) AND ExpAllOnes AND MantAllZeros; // +Inf
NInf_res := NegNum AND ExpAllOnes AND MantAllZeros; // -Inf
Denorm_res := ExpAllZeros AND NOT(MantAllZeros); // denorm
FinNeg_res := NegNum AND NOT(ExpAllOnes) AND NOT(ZeroNumber); // -finite
bResult = ( imm8[0] AND qNaN_res ) OR (imm8[1] AND Pzero_res ) OR
( imm8[2] AND Nzero_res ) OR ( imm8[3] AND PInf_res ) OR
( imm8[4] AND NInf_res ) OR ( imm8[5] AND Denorm_res ) OR
( imm8[6] AND FinNeg_res ) OR ( imm8[7] AND sNaN_res );
Return bResult;
} //* end of CheckFPClassDP() *//
VFPCLASSPD-Tests Types of Packed Float64 Values
Vol. 2C
5-346
VFPCLASSPD (EVEX Encoded versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b == 1) AND (SRC *is memory*)
THEN
DEST[j] := CheckFPClassDP(SRC1[63:0], imm8[7:0]);
ELSE
DEST[j] := CheckFPClassDP(SRC1[i+63:i], imm8[7:0]);
FI;
ELSE DEST[j] := 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFPCLASSPD __mmask8 _mm512_fpclass_pd_mask( __m512d a, int c);
VFPCLASSPD __mmask8 _mm512_mask_fpclass_pd_mask( __mmask8 m, __m512d a, int c)
VFPCLASSPD __mmask8 _mm256_fpclass_pd_mask( __m256d a, int c)
VFPCLASSPD __mmask8 _mm256_mask_fpclass_pd_mask( __mmask8 m, __m256d a, int c)
VFPCLASSPD __mmask8 _mm_fpclass_pd_mask( __m128d a, int c)
VFPCLASSPD __mmask8 _mm_mask_fpclass_pd_mask( __mmask8 m, __m128d a, int c)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B.
VFPCLASSPD-Tests Types of Packed Float64 Values
Vol. 2C
5-347
VFPCLASSPH-Test Types of Packed FP16 Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.128.NP.0F3A.W0 66 /r /ib
A
V/V
(AVX512_FP16
Test the input for the following categories: NaN,
VFPCLASSPH k1{k2},
AND AVX512VL)
+0, -0, +Infinity, -Infinity, denormal, finite
xmm1/m128/m16bcst, imm8
OR AVX10.1
negative. The immediate field provides a mask
bit for each of these category tests. The masked
test results are OR-ed together to form a mask
result.
EVEX.256.NP.0F3A.W0 66 /r /ib
A
V/V
(AVX512_FP16
Test the input for the following categories: NaN,
VFPCLASSPH k1{k2},
AND AVX512VL)
+0, -0, +Infinity, -Infinity, denormal, finite
ymm1/m256/m16bcst, imm8
OR AVX10.1
negative. The immediate field provides a mask
bit for each of these category tests. The masked
test results are OR-ed together to form a mask
result.
EVEX.512.NP.0F3A.W0 66 /r /ib
A
V/V
AVX512_FP16
Test the input for the following categories: NaN,
VFPCLASSPH k1{k2},
OR AVX10.1
+0, -0, +Infinity, -Infinity, denormal, finite
zmm1/m512/m16bcst, imm8
negative. The immediate field provides a mask
bit for each of these category tests. The masked
test results are OR-ed together to form a mask
result.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
imm8 (r)
N/A
Description
This instruction checks the packed FP16 values in the source operand for special categories, specified by the set
bits in the imm8 byte. Each set bit in imm8 specifies a category of floating-point values that the input data element
is classified against; see Table 5-12 for the categories. The classified results of all specified categories of an input
value are ORed together to form the final boolean result for the input element. The result is written to the corre-
sponding bits in the destination mask register according to the writemask.
Table 5-12. Classifier Operations for VFPCLASSPH/VFPCLASSSH
Bits
Category
Classifier
imm8[0]
QNAN
Checks for QNAN
imm8[1]
PosZero
Checks +0
imm8[2]
NegZero
Checks for -0
imm8[3]
PosINF
Checks for +∞
imm8[4]
NegINF
Checks for -∞
imm8[5]
Denormal
Checks for Denormal
imm8[6]
Negative
Checks for Negative finite
imm8[7]
SNAN
Checks for SNAN
VFPCLASSPH-Test Types of Packed FP16 Values
Vol. 2C
5-348
Operation
def check_fp_class_fp16(tsrc, imm8):
negative := tsrc[15]
exponent_all_ones := (tsrc[14:10] == 0x1F)
exponent_all_zeros := (tsrc[14:10] == 0)
mantissa_all_zeros := (tsrc[9:0] == 0)
zero := exponent_all_zeros and mantissa_all_zeros
signaling_bit := tsrc[9]
snan := exponent_all_ones and not(mantissa_all_zeros) and not(signaling_bit)
qnan := exponent_all_ones and not(mantissa_all_zeros) and signaling_bit
positive_zero := not(negative) and zero
negative_zero := negative and zero
positive_infinity := not(negative) and exponent_all_ones and mantissa_all_zeros
negative_infinity := negative and exponent_all_ones and mantissa_all_zeros
denormal := exponent_all_zeros and not(mantissa_all_zeros)
finite_negative := negative and not(exponent_all_ones) and not(zero)
return (imm8[0] and qnan) OR
(imm8[1] and positive_zero) OR
(imm8[2] and negative_zero) OR
(imm8[3] and positive_infinity) OR
(imm8[4] and negative_infinity) OR
(imm8[5] and denormal) OR
(imm8[6] and finite_negative) OR
(imm8[7] and snan)
VFPCLASSPH dest{k2}, src, imm8
VL = 128, 256 or 512
KL := VL/16
FOR i := 0 to KL-1:
IF k2[i] or *no writemask*:
IF SRC is memory and (EVEX.b = 1):
tsrc := SRC.fp16[0]
ELSE:
tsrc := SRC.fp16[i]
DEST.bit[i] := check_fp_class_fp16(tsrc, imm8)
ELSE:
DEST.bit[i] := 0
DEST[MAXKL-1:kl] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFPCLASSPH __mmask8 _mm_fpclass_ph_mask (__m128h a, int imm8);
VFPCLASSPH __mmask8 _mm_mask_fpclass_ph_mask (__mmask8 k1, __m128h a, int imm8);
VFPCLASSPH __mmask16 _mm256_fpclass_ph_mask (__m256h a, int imm8);
VFPCLASSPH __mmask16 _mm256_mask_fpclass_ph_mask (__mmask16 k1, __m256h a, int imm8);
VFPCLASSPH __mmask32 _mm512_fpclass_ph_mask (__m512h a, int imm8);
VFPCLASSPH __mmask32 _mm512_mask_fpclass_ph_mask (__mmask32 k1, __m512h a, int imm8);
SIMD Floating-Point Exceptions
None.
VFPCLASSPH-Test Types of Packed FP16 Values
Vol. 2C
5-349
Other Exceptions
EVEX-encoded instructions, see Table 2-51, “Type E4 Class Exception Conditions.”
VFPCLASSPH-Test Types of Packed FP16 Values
Vol. 2C
5-350
VFPCLASSPS-Tests Types of Packed Float32 Values
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.128.66.0F3A.W0 66 /r ib
A
V/V
(AVX512VL AND
Tests the input for the following categories: NaN, +0, -
VFPCLASSPS k2 {k1},
AVX512DQ) OR
0, +Infinity, -Infinity, denormal, finite negative. The
xmm2/m128/m32bcst, imm8
AVX10.1
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
EVEX.256.66.0F3A.W0 66 /r ib
A
V/V
(AVX512VL AND
Tests the input for the following categories: NaN, +0, -
VFPCLASSPS k2 {k1},
AVX512DQ) OR
0, +Infinity, -Infinity, denormal, finite negative. The
ymm2/m256/m32bcst, imm8
AVX10.1
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
EVEX.512.66.0F3A.W0 66 /r ib
A
V/V
AVX512DQ
Tests the input for the following categories: NaN, +0, -
VFPCLASSPS k2 {k1},
OR AVX10.1
0, +Infinity, -Infinity, denormal, finite negative. The
zmm2/m512/m32bcst, imm8
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Full
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
The FPCLASSPS instruction checks the packed single precision floating-point values for special categories, specified
by the set bits in the imm8 byte. Each set bit in imm8 specifies a category of floating-point values that the input
data element is classified against. The classified results of all specified categories of an input value are ORed
together to form the final boolean result for the input element. The result of each element is written to the corre-
sponding bit in a mask register k2 according to the writemask k1. Bits [MAX_KL-1:16/8/4] of the destination are
cleared.
The classification categories specified by imm8 are shown in Figure 5-13. The classification test for each category
is listed in Table 5-11.
The source operand is a ZMM/YMM/XMM register, a 512/256/128-bit memory location, or a 512/256/128-bit vector
broadcasted from a 32-bit memory location.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Operation
CheckFPClassSP (tsrc[31:0], imm8[7:0]){
//* Start checking the source operand for special type *//
NegNum := tsrc[31];
IF (tsrc[30:23]=0FFh) Then ExpAllOnes := 1; FI;
IF (tsrc[30:23]=0h) Then ExpAllZeros := 1;
IF (ExpAllZeros AND MXCSR.DAZ) Then
MantAllZeros := 1;
ELSIF (tsrc[22:0]=0h) Then
MantAllZeros := 1;
FI;
ZeroNumber= ExpAllZeros AND MantAllZeros
SignalingBit= tsrc[22];
VFPCLASSPS-Tests Types of Packed Float32 Values
Vol. 2C
5-351
sNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND NOT(SignalingBit); // sNaN
qNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND SignalingBit; // qNaN
Pzero_res := NOT(NegNum) AND ExpAllZeros AND MantAllZeros; // +0
Nzero_res := NegNum AND ExpAllZeros AND MantAllZeros; // -0
PInf_res := NOT(NegNum) AND ExpAllOnes AND MantAllZeros; // +Inf
NInf_res := NegNum AND ExpAllOnes AND MantAllZeros; // -Inf
Denorm_res := ExpAllZeros AND NOT(MantAllZeros); // denorm
FinNeg_res := NegNum AND NOT(ExpAllOnes) AND NOT(ZeroNumber); // -finite
bResult = ( imm8[0] AND qNaN_res ) OR (imm8[1] AND Pzero_res ) OR
( imm8[2] AND Nzero_res ) OR ( imm8[3] AND PInf_res ) OR
( imm8[4] AND NInf_res ) OR ( imm8[5] AND Denorm_res ) OR
( imm8[6] AND FinNeg_res ) OR ( imm8[7] AND sNaN_res );
Return bResult;
} //* end of CheckSPClassSP() *//
VFPCLASSPS (EVEX encoded versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN
IF (EVEX.b == 1) AND (SRC *is memory*)
THEN
DEST[j] := CheckFPClassDP(SRC1[31:0], imm8[7:0]);
ELSE
DEST[j] := CheckFPClassDP(SRC1[i+31:i], imm8[7:0]);
FI;
ELSE DEST[j] := 0
; zeroing-masking only
FI;
ENDFOR
DEST[MAX_KL-1:KL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFPCLASSPS __mmask16 _mm512_fpclass_ps_mask( __m512 a, int c);
VFPCLASSPS __mmask16 _mm512_mask_fpclass_ps_mask( __mmask16 m, __m512 a, int c)
VFPCLASSPS __mmask8 _mm256_fpclass_ps_mask( __m256 a, int c)
VFPCLASSPS __mmask8 _mm256_mask_fpclass_ps_mask( __mmask8 m, __m256 a, int c)
VFPCLASSPS __mmask8 _mm_fpclass_ps_mask( __m128 a, int c)
VFPCLASSPS __mmask8 _mm_mask_fpclass_ps_mask( __mmask8 m, __m128 a, int c)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-51, “Type E4 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B.
VFPCLASSPS-Tests Types of Packed Float32 Values
Vol. 2C
5-352
VFPCLASSSD-Tests Type of a Scalar Float64 Value
Opcode/
Op /
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.LLIG.66.0F3A.W1 67 /r ib
A
V/V
AVX512DQ
Tests the input for the following categories: NaN, +0, -0,
VFPCLASSSD k2 {k1},
OR AVX10.1
+Infinity, -Infinity, denormal, finite negative. The
xmm2/m64, imm8
immediate field provides a mask bit for each of these
category tests. The masked test results are OR-ed
together to form a mask result.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
The FPCLASSSD instruction checks the low double precision floating-point value in the source operand for special
categories, specified by the set bits in the imm8 byte. Each set bit in imm8 specifies a category of floating-point
values that the input data element is classified against. The classified results of all specified categories of an input
value are ORed together to form the final boolean result for the input element. The result is written to the low bit
in a mask register k2 according to the writemask k1. Bits MAX_KL-1: 1 of the destination are cleared.
The classification categories specified by imm8 are shown in Figure 5-13. The classification test for each category
is listed in Table 5-11.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Operation
CheckFPClassDP (tsrc[63:0], imm8[7:0]){
NegNum := tsrc[63];
IF (tsrc[62:52]=07FFh) Then ExpAllOnes := 1; FI;
IF (tsrc[62:52]=0h) Then ExpAllZeros := 1;
IF (ExpAllZeros AND MXCSR.DAZ) Then
MantAllZeros := 1;
ELSIF (tsrc[51:0]=0h) Then
MantAllZeros := 1;
FI;
ZeroNumber := ExpAllZeros AND MantAllZeros
SignalingBit := tsrc[51];
sNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND NOT(SignalingBit); // sNaN
qNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND SignalingBit; // qNaN
Pzero_res := NOT(NegNum) AND ExpAllZeros AND MantAllZeros; // +0
Nzero_res := NegNum AND ExpAllZeros AND MantAllZeros; // -0
PInf_res := NOT(NegNum) AND ExpAllOnes AND MantAllZeros; // +Inf
NInf_res := NegNum AND ExpAllOnes AND MantAllZeros; // -Inf
Denorm_res := ExpAllZeros AND NOT(MantAllZeros); // denorm
FinNeg_res := NegNum AND NOT(ExpAllOnes) AND NOT(ZeroNumber); // -finite
bResult = ( imm8[0] AND qNaN_res ) OR (imm8[1] AND Pzero_res ) OR
( imm8[2] AND Nzero_res ) OR ( imm8[3] AND PInf_res ) OR
( imm8[4] AND NInf_res ) OR ( imm8[5] AND Denorm_res ) OR
( imm8[6] AND FinNeg_res ) OR ( imm8[7] AND sNaN_res );
Return bResult;
VFPCLASSSD-Tests Type of a Scalar Float64 Value
Vol. 2C
5-353
} //* end of CheckFPClassDP() *//
VFPCLASSSD (EVEX encoded version)
IF k1[0] OR *no writemask*
THEN DEST[0] :=
CheckFPClassDP(SRC1[63:0], imm8[7:0])
ELSE DEST[0] := 0
; zeroing-masking only
FI;
DEST[MAX_KL-1:1] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFPCLASSSD __mmask8 _mm_fpclass_sd_mask( __m128d a, int c)
VFPCLASSSD __mmask8 _mm_mask_fpclass_sd_mask( __mmask8 m, __m128d a, int c)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-55, “Type E6 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B.
VFPCLASSSD-Tests Type of a Scalar Float64 Value
Vol. 2C
5-354
VFPCLASSSH-Test Types of Scalar FP16 Values
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.LLIG.NP.0F3A.W0 67 /r /ib
A
V/V
AVX512_FP16
Test the input for the following categories: NaN,
VFPCLASSSH k1{k2}, xmm1/m16,
OR AVX10.1
+0, -0, +Infinity, -Infinity, denormal, finite
imm8
negative. The immediate field provides a mask
bit for each of these category tests. The masked
test results are OR-ed together to form a mask
result.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
Scalar
ModRM:reg (w)
ModRM:r/m (r)
imm8 (r)
N/A
Description
This instruction checks the low FP16 value in the source operand for special categories, specified by the set bits in
the imm8 byte. Each set bit in imm8 specifies a category of floating-point values that the input data element is clas-
sified against; see Table 5-12 for the categories. The classified results of all specified categories of an input value
are ORed together to form the final boolean result for the input element. The result is written to the low bit in the
destination mask register according to the writemask. The other bits in the destination mask register are zeroed.
Operation
VFPCLASSSH dest{k2}, src, imm8
IF k2[0] or *no writemask*:
DEST.bit[0] := check_fp_class_fp16(src.fp16[0], imm8)
// see VFPCLASSPH
ELSE:
DEST.bit[0] := 0
DEST[MAXKL-1:1] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFPCLASSSH __mmask8 _mm_fpclass_sh_mask (__m128h a, int imm8);
VFPCLASSSH __mmask8 _mm_mask_fpclass_sh_mask (__mmask8 k1, __m128h a, int imm8);
SIMD Floating-Point Exceptions
None.
Other Exceptions
EVEX-encoded instructions, see Table 2-60, “Type E10 Class Exception Conditions.”
VFPCLASSSH-Test Types of Scalar FP16 Values
Vol. 2C
5-355
VFPCLASSSS-Tests Type of a Scalar Float32 Value
Opcode/
Op /
64/32
CPUID
Description
Instruction
En
Bit Mode
Feature Flag
Support
EVEX.LLIG.66.0F3A.W0 67 /r
A
V/V
AVX512DQ
Tests the input for the following categories: NaN, +0, -0,
VFPCLASSSS k2 {k1},
OR AVX10.1
+Infinity, -Infinity, denormal, finite negative. The immediate
xmm2/m32, imm8
field provides a mask bit for each of these category tests.
The masked test results are OR-ed together to form a mask
result.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
Tuple1 Scalar
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
The FPCLASSSS instruction checks the low single precision floating-point value in the source operand for special
categories, specified by the set bits in the imm8 byte. Each set bit in imm8 specifies a category of floating-point
values that the input data element is classified against. The classified results of all specified categories of an input
value are ORed together to form the final boolean result for the input element. The result is written to the low bit
in a mask register k2 according to the writemask k1. Bits MAX_KL-1: 1 of the destination are cleared.
The classification categories specified by imm8 are shown in Figure 5-13. The classification test for each category
is listed in Table 5-11.
EVEX.vvvv is reserved and must be 1111b otherwise instructions will #UD.
Operation
CheckFPClassSP (tsrc[31:0], imm8[7:0]){
//* Start checking the source operand for special type *//
NegNum := tsrc[31];
IF (tsrc[30:23]=0FFh) Then ExpAllOnes := 1; FI;
IF (tsrc[30:23]=0h) Then ExpAllZeros := 1;
IF (ExpAllZeros AND MXCSR.DAZ) Then
MantAllZeros := 1;
ELSIF (tsrc[22:0]=0h) Then
MantAllZeros := 1;
FI;
ZeroNumber= ExpAllZeros AND MantAllZeros
SignalingBit= tsrc[22];
sNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND NOT(SignalingBit); // sNaN
qNaN_res := ExpAllOnes AND NOT(MantAllZeros) AND SignalingBit; // qNaN
Pzero_res := NOT(NegNum) AND ExpAllZeros AND MantAllZeros; // +0
Nzero_res := NegNum AND ExpAllZeros AND MantAllZeros; // -0
PInf_res := NOT(NegNum) AND ExpAllOnes AND MantAllZeros; // +Inf
NInf_res := NegNum AND ExpAllOnes AND MantAllZeros; // -Inf
Denorm_res := ExpAllZeros AND NOT(MantAllZeros); // denorm
FinNeg_res := NegNum AND NOT(ExpAllOnes) AND NOT(ZeroNumber); // -finite
bResult = ( imm8[0] AND qNaN_res ) OR (imm8[1] AND Pzero_res ) OR
( imm8[2] AND Nzero_res ) OR ( imm8[3] AND PInf_res ) OR
( imm8[4] AND NInf_res ) OR ( imm8[5] AND Denorm_res ) OR
( imm8[6] AND FinNeg_res ) OR ( imm8[7] AND sNaN_res );
VFPCLASSSS-Tests Type of a Scalar Float32 Value
Vol. 2C
5-356
Return bResult;
} //* end of CheckSPClassSP() *//
VFPCLASSSS (EVEX encoded version)
IF k1[0] OR *no writemask*
THEN DEST[0] :=
CheckFPClassSP(SRC1[31:0], imm8[7:0])
ELSE DEST[0] := 0
; zeroing-masking only
FI;
DEST[MAX_KL-1:1] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VFPCLASSSS __mmask8 _mm_fpclass_ss_mask( __m128 a, int c)
VFPCLASSSS __mmask8 _mm_mask_fpclass_ss_mask( __mmask8 m, __m128 a, int c)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-55, “Type E6 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B.
VFPCLASSSS-Tests Type of a Scalar Float32 Value
Vol. 2C
5-357
VGATHERDPD/VGATHERQPD-Gather Packed Double Precision Floating-Point Values Using
Signed Dword/Qword Indices
Opcode/
Op/
64/32
CPUID
Description
Instruction
En
Bit Mode
Feature
Support
Flag
VEX.128.66.0F38.W1 92 /r
RMV
V/V
AVX2
Using dword indices specified in vm32x, gather double
VGATHERDPD xmm1, vm32x, xmm2
precision floating-point values from memory conditioned
on mask specified by xmm2. Conditionally gathered ele-
ments are merged into xmm1.
VEX.128.66.0F38.W1 93 /r
RMV
V/V
AVX2
Using qword indices specified in vm64x, gather double
VGATHERQPD xmm1, vm64x, xmm2
precision floating-point values from memory conditioned
on mask specified by xmm2. Conditionally gathered ele-
ments are merged into xmm1.
VEX.256.66.0F38.W1 92 /r
RMV
V/V
AVX2
Using dword indices specified in vm32x, gather double
VGATHERDPD ymm1, vm32x, ymm2
precision floating-point values from memory conditioned
on mask specified by ymm2. Conditionally gathered ele-
ments are merged into ymm1.
VEX.256.66.0F38.W1 93 /r
RMV
V/V
AVX2
Using qword indices specified in vm64y, gather double
VGATHERQPD ymm1, vm64y, ymm2
precision floating-point values from memory conditioned
on mask specified by ymm2. Conditionally gathered ele-
ments are merged into ymm1.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RMV
ModRM:reg (r,w)
BaseReg (R): VSIB:base,
VEX.vvvv (r, w)
N/A
VectorReg(R): VSIB:index
Description
The instruction conditionally loads up to 2 or 4 double precision floating-point values from memory addresses spec-
ified by the memory operand (the second operand) and using qword indices. The memory operand uses the VSIB
form of the SIB byte to specify a general purpose register operand as the common base, a vector register for an
array of indices relative to the base and a constant scale factor.
The mask operand (the third operand) specifies the conditional load operation from each memory address and the
corresponding update of each data element of the destination operand (the first operand). Conditionality is speci-
fied by the most significant bit of each data element of the mask register. If an element’s mask bit is not set, the
corresponding element of the destination register is left unchanged. The width of data element in the destination
register and mask register are identical. The entire mask register will be set to zero by this instruction unless the
instruction causes an exception.
Using dword indices in the lower half of the mask register, the instruction conditionally loads up to 2 or 4 double
precision floating-point values from the VSIB addressing memory operand, and updates the destination register.
This instruction can be suspended by an exception if at least one element is already gathered (i.e., if the exception
is triggered by an element other than the rightmost one with its mask bit set). When this happens, the destination
register and the mask operand are partially updated; those elements that have been gathered are placed into the
destination register and have their mask bits set to zero. If any traps or interrupts are pending from already gath-
ered elements, they will be delivered in lieu of the exception; in this case, EFLAG.RF is set to one so an instruction
breakpoint is not re-triggered when the instruction is continued.
If the data size and index size are different, part of the destination register and part of the mask register do not
correspond to any elements being gathered. This instruction sets those parts to zero. It may do this to one or both
of those registers even if the instruction triggers an exception, and even if the instruction triggers the exception
before gathering any elements.
VEX.128 version: The instruction will gather two double precision floating-point values. For dword indices, only the
lower two indices in the vector index register are used.
VGATHERDPD/VGATHERQPD-Gather Packed Double Precision Floating-Point Values Using Signed Dword/Qword Indices
Vol. 2C
5-358
VEX.256 version: The instruction will gather four double precision floating-point values. For dword indices, only the
lower four indices in the vector index register are used.
Note that:
• If any pair of the index, mask, or destination registers are the same, this instruction results a #UD fault.
• The values may be read from memory in any order. Memory ordering with other instructions follows the Intel-
64 memory-ordering model.
• Faults are delivered in a right-to-left manner. That is, if a fault is triggered by an element and delivered, all
elements closer to the LSB of the destination will be completed (and non-faulting). Individual elements closer
to the MSB may or may not be completed. If a given element triggers multiple faults, they are delivered in the
conventional order.
• Elements may be gathered in any order, but faults must be delivered in a right-to-left order; thus, elements to
the left of a faulting one may be gathered before the fault is delivered. A given implementation of this
instruction is repeatable - given the same input values and architectural state, the same set of elements to the
left of the faulting one will be gathered.
• This instruction does not perform AC checks, and so will never deliver an AC fault.
• This instruction will cause a #UD if the address size attribute is 16-bit.
• This instruction will cause a #UD if the memory operand is encoded without the SIB byte.
• This instruction should not be used to access memory mapped I/O as the ordering of the individual loads it does
is implementation specific, and some implementations may use loads larger than the data element size or load
elements an indeterminate number of times.
• The scaled index may require more bits to represent than the address bits used by the processor (e.g., in 32-
bit mode, if the scale is greater than one). In this case, the most significant bits beyond the number of address
bits are ignored.
Operation
DEST := SRC1;
BASE_ADDR: base register encoded in VSIB addressing;
VINDEX: the vector index register encoded by VSIB addressing;
SCALE: scale factor encoded by SIB:[7:6];
DISP: optional 1, 4 byte displacement;
MASK := SRC3;
VGATHERDPD (VEX.128 version)
MASK[MAXVL-1:128] := 0;
FOR j := 0 to 1
i := j * 64;
IF MASK[63+i] THEN
MASK[i +63:i] := FFFFFFFF_FFFFFFFFH; // extend from most significant bit
ELSE
MASK[i +63:i] := 0;
FI;
ENDFOR
FOR j := 0 to 1
k := j * 32;
i := j * 64;
DATA_ADDR := BASE_ADDR + (SignExtend(VINDEX[k+31:k])*SCALE + DISP;
IF MASK[63+i] THEN
DEST[i +63:i] := FETCH_64BITS(DATA_ADDR); // a fault exits the instruction
FI;
MASK[i +63: i] := 0;
ENDFOR
DEST[MAXVL-1:128] := 0;
VGATHERDPD/VGATHERQPD-Gather Packed Double Precision Floating-Point Values Using Signed Dword/Qword Indices
Vol. 2C
5-359
VGATHERQPD (VEX.128 version)
MASK[MAXVL-1:128] := 0;
FOR j := 0 to 1
i := j * 64;
IF MASK[63+i] THEN
MASK[i +63:i] := FFFFFFFF_FFFFFFFFH; // extend from most significant bit
ELSE
MASK[i +63:i] := 0;
FI;
ENDFOR
FOR j := 0 to 1
i := j * 64;
DATA_ADDR := BASE_ADDR + (SignExtend(VINDEX1[i+63:i])*SCALE + DISP;
IF MASK[63+i] THEN
DEST[i +63:i] := FETCH_64BITS(DATA_ADDR); // a fault exits this instruction
FI;
MASK[i +63: i] := 0;
ENDFOR
DEST[MAXVL-1:128] := 0;
VGATHERQPD (VEX.256 version)
MASK[MAXVL-1:256] := 0;
FOR j := 0 to 3
i := j * 64;
IF MASK[63+i] THEN
MASK[i +63:i] := FFFFFFFF_FFFFFFFFH; // extend from most significant bit
ELSE
MASK[i +63:i] := 0;
FI;
ENDFOR
FOR j := 0 to 3
i := j * 64;
DATA_ADDR := BASE_ADDR + (SignExtend(VINDEX1[i+63:i])*SCALE + DISP;
IF MASK[63+i] THEN
DEST[i +63:i] := FETCH_64BITS(DATA_ADDR); // a fault exits the instruction
FI;
MASK[i +63: i] := 0;
ENDFOR
DEST[MAXVL-1:256] := 0;
VGATHERDPD (VEX.256 version)
MASK[MAXVL-1:256] := 0;
FOR j := 0 to 3
i := j * 64;
IF MASK[63+i] THEN
MASK[i +63:i] := FFFFFFFF_FFFFFFFFH; // extend from most significant bit
ELSE
MASK[i +63:i] := 0;
FI;
ENDFOR
FOR j := 0 to 3
k := j * 32;
i := j * 64;
DATA_ADDR := BASE_ADDR + (SignExtend(VINDEX1[k+31:k])*SCALE + DISP;
VGATHERDPD/VGATHERQPD-Gather Packed Double Precision Floating-Point Values Using Signed Dword/Qword Indices
Vol. 2C
5-360
IF MASK[63+i] THEN
DEST[i +63:i] := FETCH_64BITS(DATA_ADDR); // a fault exits the instruction
FI;
MASK[i +63:i] := 0;
ENDFOR
DEST[MAXVL-1:256] := 0;
Intel C/C++ Compiler Intrinsic Equivalent
VGATHERDPD: __m128d _mm_i32gather_pd (double const * base, __m128i index, const int scale);
VGATHERDPD: __m128d _mm_mask_i32gather_pd (__m128d src, double const * base, __m128i index, __m128d mask, const int
scale);
VGATHERDPD: __m256d _mm256_i32gather_pd (double const * base, __m128i index, const int scale);
VGATHERDPD: __m256d _mm256_mask_i32gather_pd (__m256d src, double const * base, __m128i index, __m256d mask, const int
scale);
VGATHERQPD: __m128d _mm_i64gather_pd (double const * base, __m128i index, const int scale);
VGATHERQPD: __m128d _mm_mask_i64gather_pd (__m128d src, double const * base, __m128i index, __m128d mask, const int
scale);
VGATHERQPD: __m256d _mm256_i64gather_pd (double const * base, __m256i index, const int scale);
VGATHERQPD: __m256d _mm256_mask_i64gather_pd (__m256d src, double const * base, __m256i index, __m256d mask, const int
scale);
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-27, “Type 12 Class Exception Conditions.”
VGATHERDPD/VGATHERQPD-Gather Packed Double Precision Floating-Point Values Using Signed Dword/Qword Indices
Vol. 2C
5-361
VGATHERDPS/VGATHERDPD-Gather Packed Single, Packed Double with Signed Dword Indices
Opcode/
Op/
64/32
CPUID Feature
Description
Instruction
En
Bit Mode
Flag
Support
EVEX.128.66.0F38.W0 92 /vsib
A
V/V
(AVX512VL AND
Using signed dword indices, gather single-precision
VGATHERDPS xmm1 {k1}, vm32x
AVX512F) OR
floating-point values from memory using k1 as
AVX10.1
completion mask.
EVEX.256.66.0F38.W0 92 /vsib
A
V/V
(AVX512VL AND
Using signed dword indices, gather single-precision
VGATHERDPS ymm1 {k1}, vm32y
AVX512F) OR
floating-point values from memory using k1 as
AVX10.1
completion mask.
EVEX.512.66.0F38.W0 92 /vsib
A
V/V
AVX512F
Using signed dword indices, gather single-precision
VGATHERDPS zmm1 {k1}, vm32z
OR AVX10.1
floating-point values from memory using k1 as
completion mask.
EVEX.128.66.0F38.W1 92 /vsib
A
V/V
(AVX512VL AND
Using signed dword indices, gather float64 vector into
VGATHERDPD xmm1 {k1},
AVX512F) R
float64 vector xmm1 using k1 as completion mask.
vm32x
AVX10.11
EVEX.256.66.0F38.W1 92 /vsib
A
V/V
(AVX512VL AND
Using signed dword indices, gather float64 vector into
VGATHERDPD ymm1 {k1},
AVX512F) OR
float64 vector ymm1 using k1 as completion mask.
vm32x
AVX10.1
EVEX.512.66.0F38.W1 92 /vsib
A
V/V
AVX512F
Using signed dword indices, gather float64 vector into
VGATHERDPD zmm1 {k1}, vm32y
OR AVX10.1
float64 vector zmm1 using k1 as completion mask.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
BaseReg (R): VSIB:base,
A
Tuple1 Scalar
ModRM:reg (w)
N/A
N/A
VectorReg(R): VSIB:index
Description
A set of single precision/double precision faulting-point memory locations pointed by base address BASE_ADDR
and index vector V_INDEX with scale SCALE are gathered. The result is written into a vector register. The elements
are specified via the VSIB (i.e., the index register is a vector register, holding packed indices). Elements will only
be loaded if their corresponding mask bit is one. If an element’s mask bit is not set, the corresponding element of
the destination register is left unchanged. The entire mask register will be set to zero by this instruction unless it
triggers an exception.
This instruction can be suspended by an exception if at least one element is already gathered (i.e., if the exception
is triggered by an element other than the right most one with its mask bit set). When this happens, the destination
register and the mask register (k1) are partially updated; those elements that have been gathered are placed into
the destination register and have their mask bits set to zero. If any traps or interrupts are pending from already
gathered elements, they will be delivered in lieu of the exception; in this case, EFLAG.RF is set to one so an instruc-
tion breakpoint is not re-triggered when the instruction is continued.
If the data element size is less than the index element size, the higher part of the destination register and the mask
register do not correspond to any elements being gathered. This instruction sets those higher parts to zero. It may
update these unused elements to one or both of those registers even if the instruction triggers an exception, and
even if the instruction triggers the exception before gathering any elements.
Note that:
• The values may be read from memory in any order. Memory ordering with other instructions follows the Intel-
64 memory-ordering model.
• Faults are delivered in a right-to-left manner. That is, if a fault is triggered by an element and delivered, all
elements closer to the LSB of the destination zmm will be completed (and non-faulting). Individual elements
closer to the MSB may or may not be completed. If a given element triggers multiple faults, they are delivered
in the conventional order.
VGATHERDPS/VGATHERDPD-Gather Packed Single, Packed Double with Signed Dword Indices
Vol. 2C
5-362
• Elements may be gathered in any order, but faults must be delivered in a right-to left order; thus, elements to
the left of a faulting one may be gathered before the fault is delivered. A given implementation of this
instruction is repeatable - given the same input values and architectural state, the same set of elements to the
left of the faulting one will be gathered.
• This instruction does not perform AC checks, and so will never deliver an AC fault.
• Not valid with 16-bit effective addresses. Will deliver a #UD fault.
Note that the presence of VSIB byte is enforced in this instruction. Hence, the instruction will #UD fault if
ModRM.rm is different than 100b.
This instruction has special disp8*N and alignment rules. N is considered to be the size of a single vector element.
The scaled index may require more bits to represent than the address bits used by the processor (e.g., in 32-bit
mode, if the scale is greater than one). In this case, the most significant bits beyond the number of address bits are
ignored.
The instruction will #UD fault if the destination vector zmm1 is the same as index vector VINDEX. The instruction
will #UD fault if the k0 mask register is specified.
Operation
BASE_ADDR stands for the memory operand base address (a GPR); may not exist
VINDEX stands for the memory operand vector of indices (a vector register)
SCALE stands for the memory operand scalar (1, 2, 4 or 8)
DISP is the optional 1 or 4 byte displacement
VGATHERDPS (EVEX encoded version)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j]
THEN DEST[i+31:i] :=
MEM[BASE_ADDR +
SignExtend(VINDEX[i+31:i]) * SCALE + DISP]
k1[j] := 0
ELSE *DEST[i+31:i] := remains unchanged*
FI;
ENDFOR
k1[MAX_KL-1:KL] := 0
DEST[MAXVL-1:VL] := 0
VGATHERDPD (EVEX encoded version)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
k := j * 32
IF k1[j]
THEN DEST[i+63:i] := MEM[BASE_ADDR +
SignExtend(VINDEX[k+31:k]) * SCALE + DISP]
k1[j] := 0
ELSE *DEST[i+63:i] := remains unchanged*
FI;
ENDFOR
k1[MAX_KL-1:KL] := 0
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VGATHERDPD __m512d _mm512_i32gather_pd( __m256i vdx, void * base, int scale);
VGATHERDPS/VGATHERDPD-Gather Packed Single, Packed Double with Signed Dword Indices
Vol. 2C
5-363