Intel 64 and IA-32 Architectures. Software Developer’s Manual (2026) - page 24
PHSUBW/PHSUBD-Packed Horizontal Subtract
Opcode/
Op/
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
NP 0F 38 05 /r1
RM
V/V
SSSE3
Subtract 16-bit signed integers horizontally,
pack to mm1.
PHSUBW mm1, mm2/m64
66 0F 38 05 /r
RM
V/V
SSSE3
Subtract 16-bit signed integers horizontally,
pack to xmm1.
PHSUBW xmm1, xmm2/m128
NP 0F 38 06 /r
RM
V/V
SSSE3
Subtract 32-bit signed integers horizontally,
PHSUBD mm1, mm2/m64
pack to mm1.
66 0F 38 06 /r
RM
V/V
SSSE3
Subtract 32-bit signed integers horizontally,
pack to xmm1.
PHSUBD xmm1, xmm2/m128
VEX.128.66.0F38.WIG 05 /r
RVM
V/V
AVX
Subtract 16-bit signed integers horizontally,
pack to xmm1.
VPHSUBW xmm1, xmm2, xmm3/m128
VEX.128.66.0F38.WIG 06 /r
RVM
V/V
AVX
Subtract 32-bit signed integers horizontally,
pack to xmm1.
VPHSUBD xmm1, xmm2, xmm3/m128
VEX.256.66.0F38.WIG 05 /r
RVM
V/V
AVX2
Subtract 16-bit signed integers horizontally,
pack to ymm1.
VPHSUBW ymm1, ymm2, ymm3/m256
VEX.256.66.0F38.WIG 06 /r
RVM
V/V
AVX2
Subtract 32-bit signed integers horizontally,
pack to ymm1.
VPHSUBD ymm1, ymm2, ymm3/m256
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX
Registers,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
RVM
ModRM:reg (r, w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
(V)PHSUBW performs horizontal subtraction on each adjacent pair of 16-bit signed integers by subtracting the
most significant word from the least significant word of each pair in the source and destination operands, and packs
the signed 16-bit results to the destination operand (first operand). (V)PHSUBD performs horizontal subtraction on
each adjacent pair of 32-bit signed integers by subtracting the most significant doubleword from the least signifi-
cant doubleword of each pair, and packs the signed 32-bit result to the destination operand. When the source
operand is a 128-bit memory operand, the operand must be aligned on a 16-byte boundary or a general-protection
exception (#GP) will be generated.
Legacy SSE version: Both operands can be MMX registers. The second source operand can be an MMX register or
a 64-bit memory location.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding YMM destina-
tion register remain unchanged.
In 64-bit mode, use the REX prefix to access additional registers.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the destination YMM register are
zeroed.
PHSUBW/PHSUBD-Packed Horizontal Subtract
Vol. 2B
4-302
VEX.256 encoded version: The first source and destination operands are YMM registers. The second source
operand can be an YMM register or a 256-bit memory location.
Operation
PHSUBW (With 64-bit Operands)
mm1[15-0] = mm1[15-0] - mm1[31-16];
mm1[31-16] = mm1[47-32] - mm1[63-48];
mm1[47-32] = mm2/m64[15-0] - mm2/m64[31-16];
mm1[63-48] = mm2/m64[47-32] - mm2/m64[63-48];
PHSUBW (With 128-bit Operands)
xmm1[15-0] = xmm1[15-0] - xmm1[31-16];
xmm1[31-16] = xmm1[47-32] - xmm1[63-48];
xmm1[47-32] = xmm1[79-64] - xmm1[95-80];
xmm1[63-48] = xmm1[111-96] - xmm1[127-112];
xmm1[79-64] = xmm2/m128[15-0] - xmm2/m128[31-16];
xmm1[95-80] = xmm2/m128[47-32] - xmm2/m128[63-48];
xmm1[111-96] = xmm2/m128[79-64] - xmm2/m128[95-80];
xmm1[127-112] = xmm2/m128[111-96] - xmm2/m128[127-112];
VPHSUBW (VEX.128 Encoded Version)
DEST[15:0] := SRC1[15:0] - SRC1[31:16]
DEST[31:16] := SRC1[47:32] - SRC1[63:48]
DEST[47:32] := SRC1[79:64] - SRC1[95:80]
DEST[63:48] := SRC1[111:96] - SRC1[127:112]
DEST[79:64] := SRC2[15:0] - SRC2[31:16]
DEST[95:80] := SRC2[47:32] - SRC2[63:48]
DEST[111:96] := SRC2[79:64] - SRC2[95:80]
DEST[127:112] := SRC2[111:96] - SRC2[127:112]
DEST[MAXVL-1:128] := 0
VPHSUBW (VEX.256 Encoded Version)
DEST[15:0] := SRC1[15:0] - SRC1[31:16]
DEST[31:16] := SRC1[47:32] - SRC1[63:48]
DEST[47:32] := SRC1[79:64] - SRC1[95:80]
DEST[63:48] := SRC1[111:96] - SRC1[127:112]
DEST[79:64] := SRC2[15:0] - SRC2[31:16]
DEST[95:80] := SRC2[47:32] - SRC2[63:48]
DEST[111:96] := SRC2[79:64] - SRC2[95:80]
DEST[127:112] := SRC2[111:96] - SRC2[127:112]
DEST[143:128] := SRC1[143:128] - SRC1[159:144]
DEST[159:144] := SRC1[175:160] - SRC1[191:176]
DEST[175:160] := SRC1[207:192] - SRC1[223:208]
DEST[191:176] := SRC1[239:224] - SRC1[255:240]
DEST[207:192] := SRC2[143:128] - SRC2[159:144]
DEST[223:208] := SRC2[175:160] - SRC2[191:176]
DEST[239:224] := SRC2[207:192] - SRC2[223:208]
DEST[255:240] := SRC2[239:224] - SRC2[255:240]
PHSUBD (With 64-bit Operands)
mm1[31-0] = mm1[31-0] - mm1[63-32];
mm1[63-32] = mm2/m64[31-0] - mm2/m64[63-32];
PHSUBW/PHSUBD-Packed Horizontal Subtract
Vol. 2B
4-303
PHSUBD (With 128-bit Operands)
xmm1[31-0] = xmm1[31-0] - xmm1[63-32];
xmm1[63-32] = xmm1[95-64] - xmm1[127-96];
xmm1[95-64] = xmm2/m128[31-0] - xmm2/m128[63-32];
xmm1[127-96] = xmm2/m128[95-64] - xmm2/m128[127-96];
VPHSUBD (VEX.128 Encoded Version)
DEST[31-0] := SRC1[31-0] - SRC1[63-32]
DEST[63-32] := SRC1[95-64] - SRC1[127-96]
DEST[95-64] := SRC2[31-0] - SRC2[63-32]
DEST[127-96] := SRC2[95-64] - SRC2[127-96]
DEST[MAXVL-1:128] := 0
VPHSUBD (VEX.256 Encoded Version)
DEST[31:0] := SRC1[31:0] - SRC1[63:32]
DEST[63:32] := SRC1[95:64] - SRC1[127:96]
DEST[95:64] := SRC2[31:0] - SRC2[63:32]
DEST[127:96] := SRC2[95:64] - SRC2[127:96]
DEST[159:128] := SRC1[159:128] - SRC1[191:160]
DEST[191:160] := SRC1[223:192] - SRC1[255:224]
DEST[223:192] := SRC2[159:128] - SRC2[191:160]
DEST[255:224] := SRC2[223:192] - SRC2[255:224]
Intel C/C++ Compiler Intrinsic Equivalents
PHSUBW __m64 _mm_hsub_pi16 (__m64 a, __m64 b)
PHSUBD __m64 _mm_hsub_pi32 (__m64 a, __m64 b)
(V)PHSUBW __m128i _mm_hsub_epi16 (__m128i a, __m128i b)
(V)PHSUBD __m128i _mm_hsub_epi32 (__m128i a, __m128i b)
VPHSUBW __m256i _mm256_hsub_epi16 (__m256i a, __m256i b)
VPHSUBD __m256i _mm256_hsub_epi32 (__m256i a, __m256i b)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-21, “Type 4 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
PHSUBW/PHSUBD-Packed Horizontal Subtract
Vol. 2B
4-304
PINSRB/PINSRD/PINSRQ-Insert Byte/Dword/Qword
Opcode/
Op/ En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
66 0F 3A 20 /r ib
A
V/V
SSE4_1
Insert a byte integer value from r32/m8 into
PINSRB xmm1, r32/m8, imm8
xmm1 at the destination element in xmm1
specified by imm8.
66 0F 3A 22 /r ib
A
V/V
SSE4_1
Insert a dword integer value from r/m32 into
PINSRD xmm1, r/m32, imm8
the xmm1 at the destination element
specified by imm8.
66 REX.W 0F 3A 22 /r ib
A
V/N. E.
SSE4_1
Insert a qword integer value from r/m64 into
PINSRQ xmm1, r/m64, imm8
the xmm1 at the destination element
specified by imm8.
VEX.128.66.0F3A.W0 20 /r ib
B
V1/V
AVX
Merge a byte integer value from r32/m8 and
VPINSRB xmm1, xmm2, r32/m8, imm8
rest from xmm2 into xmm1 at the byte offset
in imm8.
VEX.128.66.0F3A.W0 22 /r ib
B
V/V
AVX
Insert a dword integer value from r32/m32
VPINSRD xmm1, xmm2, r/m32, imm8
and rest from xmm2 into xmm1 at the dword
offset in imm8.
VEX.128.66.0F3A.W1 22 /r ib
B
V/I2
AVX
Insert a qword integer value from r64/m64
VPINSRQ xmm1, xmm2, r/m64, imm8
and rest from xmm2 into xmm1 at the qword
offset in imm8.
EVEX.128.66.0F3A.WIG 20 /r ib
C
V/V
AVX512BW
Merge a byte integer value from r32/m8 and
VPINSRB xmm1, xmm2, r32/m8, imm8
OR AVX10.1
rest from xmm2 into xmm1 at the byte offset
in imm8.
EVEX.128.66.0F3A.W0 22 /r ib
C
V/V
AVX512DQ
Insert a dword integer value from r32/m32
VPINSRD xmm1, xmm2, r32/m32, imm8
OR AVX10.1
and rest from xmm2 into xmm1 at the dword
offset in imm8.
EVEX.128.66.0F3A.W1 22 /r ib
C
V/N.E.2
AVX512DQ
Insert a qword integer value from r64/m64
VPINSRQ xmm1, xmm2, r64/m64, imm8
OR AVX10.1
and rest from xmm2 into xmm1 at the qword
offset in imm8.
NOTES:
1. In 64-bit mode, VEX.W1 is ignored for VPINSRB (similar to legacy REX.W=1 prefix with PINSRB).
2. VEX.W/EVEX.W in non-64 bit is ignored; the instructions behaves as if the W0 version is used.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
imm8
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8
C
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Copies a byte/dword/qword from the source operand (second operand) and inserts it in the destination operand
(first operand) at the location specified with the count operand (third operand). (The other elements in the desti-
nation register are left untouched.) The source operand can be a general-purpose register or a memory location.
(When the source operand is a general-purpose register, PINSRB copies the low byte of the register.) The destina-
tion operand is an XMM register. The count operand is an 8-bit immediate. When specifying a qword[dword, byte]
location in an XMM register, the [2, 4] least-significant bit(s) of the count operand specify the location.
PINSRB/PINSRD/PINSRQ-Insert Byte/Dword/Qword
Vol. 2B
4-305
In 64-bit mode and not encoded with VEX/EVEX, using a REX prefix in the form of REX.R permits this instruction to
access additional registers (XMM8-XMM15, R8-15). Use of REX.W permits the use of 64 bit general purpose regis-
ters.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding YMM destination register remain
unchanged.
VEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed. VEX.L must be 0, otherwise
the instruction will #UD. Attempt to execute VPINSRQ in non-64-bit mode will cause #UD.
EVEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed. EVEX.L’L must be 0, other-
wise the instruction will #UD.
Operation
CASE OF
PINSRB: SEL := COUNT[3:0];
MASK := (0FFH << (SEL * 8));
TEMP := (((SRC[7:0] << (SEL *8)) AND MASK);
PINSRD: SEL := COUNT[1:0];
MASK := (0FFFFFFFFH << (SEL * 32));
TEMP := (((SRC << (SEL *32)) AND MASK)
;
PINSRQ: SEL := COUNT[0]
MASK := (0FFFFFFFFFFFFFFFFH << (SEL * 64));
TEMP := (((SRC << (SEL *64)) AND MASK)
;
ESAC;
DEST := ((DEST AND NOT MASK) OR TEMP);
VPINSRB (VEX/EVEX Encoded Version)
SEL := imm8[3:0]
DEST[127:0] := write_b_element(SEL, SRC2, SRC1)
DEST[MAXVL-1:128] := 0
VPINSRD (VEX/EVEX Encoded Version)
SEL := imm8[1:0]
DEST[127:0] := write_d_element(SEL, SRC2, SRC1)
DEST[MAXVL-1:128] := 0
VPINSRQ (VEX/EVEX Encoded Version)
SEL := imm8[0]
DEST[127:0] := write_q_element(SEL, SRC2, SRC1)
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
PINSRB __m128i _mm_insert_epi8 (__m128i s1, int s2, const int ndx);
PINSRD __m128i _mm_insert_epi32 (__m128i s2, int s, const int ndx);
PINSRQ __m128i _mm_insert_epi64(__m128i s2, __int64 s, const int ndx);
Flags Affected
None.
SIMD Floating-Point Exceptions
None.
PINSRB/PINSRD/PINSRQ-Insert Byte/Dword/Qword
Vol. 2B
4-306
Other Exceptions
EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
Additionally:
#UD
If VEX.L = 1 or EVEX.L’L > 0.
PINSRB/PINSRD/PINSRQ-Insert Byte/Dword/Qword
Vol. 2B
4-307
PINSRW-Insert Word
Opcode/
Op/ En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
NP 0F C4 /r ib1
A
V/V
SSE
Insert the low word from r32 or from m16 into
mm at the word position specified by imm8.
PINSRW mm, r32/m16, imm8
66 0F C4 /r ib
A
V/V
SSE2
Move the low word of r32 or from m16 into
xmm at the word position specified by imm8.
PINSRW xmm, r32/m16, imm8
VEX.128.66.0F.W0 C4 /r ib
B
V2/V
AVX
Insert the word from r32/m16 at the offset
indicated by imm8 into the value from xmm2
VPINSRW xmm1, xmm2, r32/m16, imm8
and store result in xmm1.
EVEX.128.66.0F.WIG C4 /r ib
C
V/V
AVX512BW OR
Insert the word from r32/m16 at the offset
VPINSRW xmm1, xmm2, r32/m16, imm8
AVX10.1
indicated by imm8 into the value from xmm2
and store result in xmm1.
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX
Registers,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
2. In 64-bit mode, VEX.W1 is ignored for VPINSRW (similar to legacy REX.W=1 prefix in PINSRW).
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
imm8
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8
C
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
Three operand MMX and SSE instructions:
Copies a word from the source operand and inserts it in the destination operand at the location specified with the
count operand. (The other words in the destination register are left untouched.) The source operand can be a
general-purpose register or a 16-bit memory location. (When the source operand is a general-purpose register, the
low word of the register is copied.) The destination operand can be an MMX technology register or an XMM register.
The count operand is an 8-bit immediate. When specifying a word location in an MMX technology register, the 2
least-significant bits of the count operand specify the location; for an XMM register, the 3 least-significant bits
specify the location.
Bits (MAXVL-1:128) of the corresponding YMM destination register remain unchanged.
Four operand AVX and AVX-512 instructions:
Combines a word from the first source operand with the second source operand, and inserts it in the destination
operand at the location specified with the count operand. The second source operand can be a general-purpose
register or a 16-bit memory location. (When the source operand is a general-purpose register, the low word of the
register is copied.) The first source and destination operands are XMM registers. The count operand is an 8-bit
immediate. When specifying a word location, the 3 least-significant bits specify the location.
Bits (MAXVL-1:128) of the destination YMM register are zeroed. VEX.L/EVEX.L’L must be 0, otherwise the instruc-
tion will #UD.
PINSRW-Insert Word
Vol. 2B
4-308
Operation
PINSRW dest, src, imm8 (MMX)
SEL := imm8[1:0]
DEST.word[SEL] := src.word[0]
PINSRW dest, src, imm8 (SSE)
SEL := imm8[2:0]
DEST.word[SEL] := src.word[0]
VPINSRW dest, src1, src2, imm8 (AVX/AVX512)
SEL := imm8[2:0]
DEST := src1
DEST.word[SEL] := src2.word[0]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
PINSRW __m64 _mm_insert_pi16 (__m64 a, int d, int n)
PINSRW __m128i _mm_insert_epi16 ( __m128i a, int b, int imm)
Flags Affected
None.
Numeric Exceptions
None.
Other Exceptions
EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
Additionally:
#UD
If VEX.L = 1 or EVEX.L’L > 0.
PINSRW-Insert Word
Vol. 2B
4-309
PMADDUBSW-Multiply and Add Packed Signed and Unsigned Bytes
Opcode/
Op/
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
NP 0F 38 04 /r1
A
V/V
SSSE3
Multiply signed and unsigned bytes, add
horizontal pair of signed words, pack saturated
PMADDUBSW mm1, mm2/m64
signed-words to mm1.
66 0F 38 04 /r
A
V/V
SSSE3
Multiply signed and unsigned bytes, add
horizontal pair of signed words, pack saturated
PMADDUBSW xmm1, xmm2/m128
signed-words to xmm1.
VEX.128.66.0F38.WIG 04 /r
B
V/V
AVX
Multiply signed and unsigned bytes, add
horizontal pair of signed words, pack saturated
VPMADDUBSW xmm1, xmm2, xmm3/m128
signed-words to xmm1.
VEX.256.66.0F38.WIG 04 /r
B
V/V
AVX2
Multiply signed and unsigned bytes, add
horizontal pair of signed words, pack saturated
VPMADDUBSW ymm1, ymm2, ymm3/m256
signed-words to ymm1.
EVEX.128.66.0F38.WIG 04 /r
C
V/V
(AVX512VL AND
Multiply signed and unsigned bytes, add
VPMADDUBSW xmm1 {k1}{z}, xmm2,
AVX512BW) OR
horizontal pair of signed words, pack saturated
xmm3/m128
AVX10.1
signed-words to xmm1 under writemask k1.
EVEX.256.66.0F38.WIG 04 /r
C
V/V
(AVX512VL AND
Multiply signed and unsigned bytes, add
VPMADDUBSW ymm1 {k1}{z}, ymm2,
AVX512BW) OR
horizontal pair of signed words, pack saturated
ymm3/m256
AVX10.1
signed-words to ymm1 under writemask k1.
EVEX.512.66.0F38.WIG 04 /r
C
V/V
AVX512BW
Multiply signed and unsigned bytes, add
VPMADDUBSW zmm1 {k1}{z}, zmm2,
OR AVX10.1
horizontal pair of signed words, pack saturated
zmm3/m512
signed-words to zmm1 under writemask k1.
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX Reg-
isters,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
(V)PMADDUBSW multiplies vertically each unsigned byte of the destination operand (first operand) with the corre-
sponding signed byte of the source operand (second operand), producing intermediate signed 16-bit integers.
Each adjacent pair of signed words is added and the saturated result is packed to the destination operand. For
example, the lowest-order bytes (bits 7-0) in the source and destination operands are multiplied and the interme-
diate signed word result is added with the corresponding intermediate result from the 2nd lowest-order bytes (bits
15-8) of the operands; the sign-saturated result is stored in the lowest word of the destination register (15-0). The
same operation is performed on the other pairs of adjacent bytes. Both operands can be MMX register or XMM
registers. When the source operand is a 128-bit memory operand, the operand must be aligned on a 16-byte
boundary or a general-protection exception (#GP) will be generated.
In 64-bit mode and not encoded with VEX/EVEX, use the REX prefix to access XMM8-XMM15.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
PMADDUBSW-Multiply and Add Packed Signed and Unsigned Bytes
Vol. 2B
4-310
VEX.128 and EVEX.128 encoded versions: The first source and destination operands are XMM registers. The
second source operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding
destination register are zeroed.
VEX.256 and EVEX.256 encoded versions: The second source operand can be an YMM register or a 256-bit memory
location. The first source and destination operands are YMM registers. Bits (MAXVL-1:256) of the corresponding
ZMM register are zeroed.
EVEX.512 encoded version: The second source operand can be an ZMM register or a 512-bit memory location. The
first source and destination operands are ZMM registers.
Operation
PMADDUBSW (With 64-bit Operands)
DEST[15-0] = SaturateToSignedWord(SRC[15-8]*DEST[15-8]+SRC[7-0]*DEST[7-0]);
DEST[31-16] = SaturateToSignedWord(SRC[31-24]*DEST[31-24]+SRC[23-16]*DEST[23-16]);
DEST[47-32] = SaturateToSignedWord(SRC[47-40]*DEST[47-40]+SRC[39-32]*DEST[39-32]);
DEST[63-48] = SaturateToSignedWord(SRC[63-56]*DEST[63-56]+SRC[55-48]*DEST[55-48]);
PMADDUBSW (With 128-bit Operands)
DEST[15-0] = SaturateToSignedWord(SRC[15-8]* DEST[15-8]+SRC[7-0]*DEST[7-0]);
// Repeat operation for 2nd through 7th word
SRC1/DEST[127-112] = SaturateToSignedWord(SRC[127-120]*DEST[127-120]+ SRC[119-112]* DEST[119-112]);
VPMADDUBSW (VEX.128 Encoded Version)
DEST[15:0] := SaturateToSignedWord(SRC2[15:8]* SRC1[15:8]+SRC2[7:0]*SRC1[7:0])
// Repeat operation for 2nd through 7th word
DEST[127:112] := SaturateToSignedWord(SRC2[127:120]*SRC1[127:120]+ SRC2[119:112]* SRC1[119:112])
DEST[MAXVL-1:128] := 0
VPMADDUBSW (VEX.256 Encoded Version)
DEST[15:0] := SaturateToSignedWord(SRC2[15:8]* SRC1[15:8]+SRC2[7:0]*SRC1[7:0])
// Repeat operation for 2nd through 15th word
DEST[255:240] := SaturateToSignedWord(SRC2[255:248]*SRC1[255:248]+ SRC2[247:240]* SRC1[247:240])
DEST[MAXVL-1:256] := 0
VPMADDUBSW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SaturateToSignedWord(SRC2[i+15:i+8]* SRC1[i+15:i+8] + SRC2[i+7:i]*SRC1[i+7:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+15:i] = 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalents
VPMADDUBSW __m512i _mm512_maddubs_epi16( __m512i a, __m512i b);
VPMADDUBSW __m512i _mm512_mask_maddubs_epi16(__m512i s, __mmask32 k, __m512i a, __m512i b);
PMADDUBSW-Multiply and Add Packed Signed and Unsigned Bytes
Vol. 2B
4-311
VPMADDUBSW __m512i _mm512_maskz_maddubs_epi16( __mmask32 k, __m512i a, __m512i b);
VPMADDUBSW __m256i _mm256_mask_maddubs_epi16(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMADDUBSW __m256i _mm256_maskz_maddubs_epi16( __mmask16 k, __m256i a, __m256i b);
VPMADDUBSW __m128i _mm_mask_maddubs_epi16(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMADDUBSW __m128i _mm_maskz_maddubs_epi16( __mmask8 k, __m128i a, __m128i b);
PMADDUBSW __m64 _mm_maddubs_pi16 (__m64 a, __m64 b)
(V)PMADDUBSW __m128i _mm_maddubs_epi16 (__m128i a, __m128i b)
VPMADDUBSW __m256i _mm256_maddubs_epi16 (__m256i a, __m256i b)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Exceptions Type E4NF.nb in Table 2-52, “Type E4NF Class Exception Conditions.”
PMADDUBSW-Multiply and Add Packed Signed and Unsigned Bytes
Vol. 2B
4-312
PMADDWD-Multiply and Add Packed Integers
Opcode/
Op/
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
NP 0F F5 /r1
A
V/V
MMX
Multiply the packed words in mm by the packed
words in mm/m64, add adjacent doubleword
PMADDWD mm, mm/m64
results, and store in mm.
66 0F F5 /r
A
V/V
SSE2
Multiply the packed word integers in xmm1 by
the packed word integers in xmm2/m128, add
PMADDWD xmm1, xmm2/m128
adjacent doubleword results, and store in
xmm1.
VEX.128.66.0F.WIG F5 /r
B
V/V
AVX
Multiply the packed word integers in xmm2 by
the packed word integers in xmm3/m128, add
VPMADDWD xmm1, xmm2, xmm3/m128
adjacent doubleword results, and store in
xmm1.
VEX.256.66.0F.WIG F5 /r
B
V/V
AVX2
Multiply the packed word integers in ymm2 by
the packed word integers in ymm3/m256, add
VPMADDWD ymm1, ymm2, ymm3/m256
adjacent doubleword results, and store in
ymm1.
EVEX.128.66.0F.WIG F5 /r
C
V/V
(AVX512VL AND
Multiply the packed word integers in xmm2 by
VPMADDWD xmm1 {k1}{z}, xmm2,
AVX512BW) OR
the packed word integers in xmm3/m128, add
xmm3/m128
AVX10.1
adjacent doubleword results, and store in
xmm1 under writemask k1.
EVEX.256.66.0F.WIG F5 /r
C
V/V
(AVX512VL AND
Multiply the packed word integers in ymm2 by
VPMADDWD ymm1 {k1}{z}, ymm2,
AVX512BW) OR
the packed word integers in ymm3/m256, add
ymm3/m256
AVX10.1
adjacent doubleword results, and store in
ymm1 under writemask k1.
EVEX.512.66.0F.WIG F5 /r
C
V/V
AVX512BW
Multiply the packed word integers in zmm2 by
VPMADDWD zmm1 {k1}{z}, zmm2,
OR AVX10.1
the packed word integers in zmm3/m512, add
zmm3/m512
adjacent doubleword results, and store in
zmm1 under writemask k1.
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX Reg-
isters,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Multiplies the individual signed words of the destination operand (first operand) by the corresponding signed words
of the source operand (second operand), producing temporary signed, doubleword results. The adjacent double-
word results are then summed and stored in the destination operand. For example, the corresponding low-order
words (15-0) and (31-16) in the source and destination operands are multiplied by one another and the double-
word results are added together and stored in the low doubleword of the destination register (31-0). The same
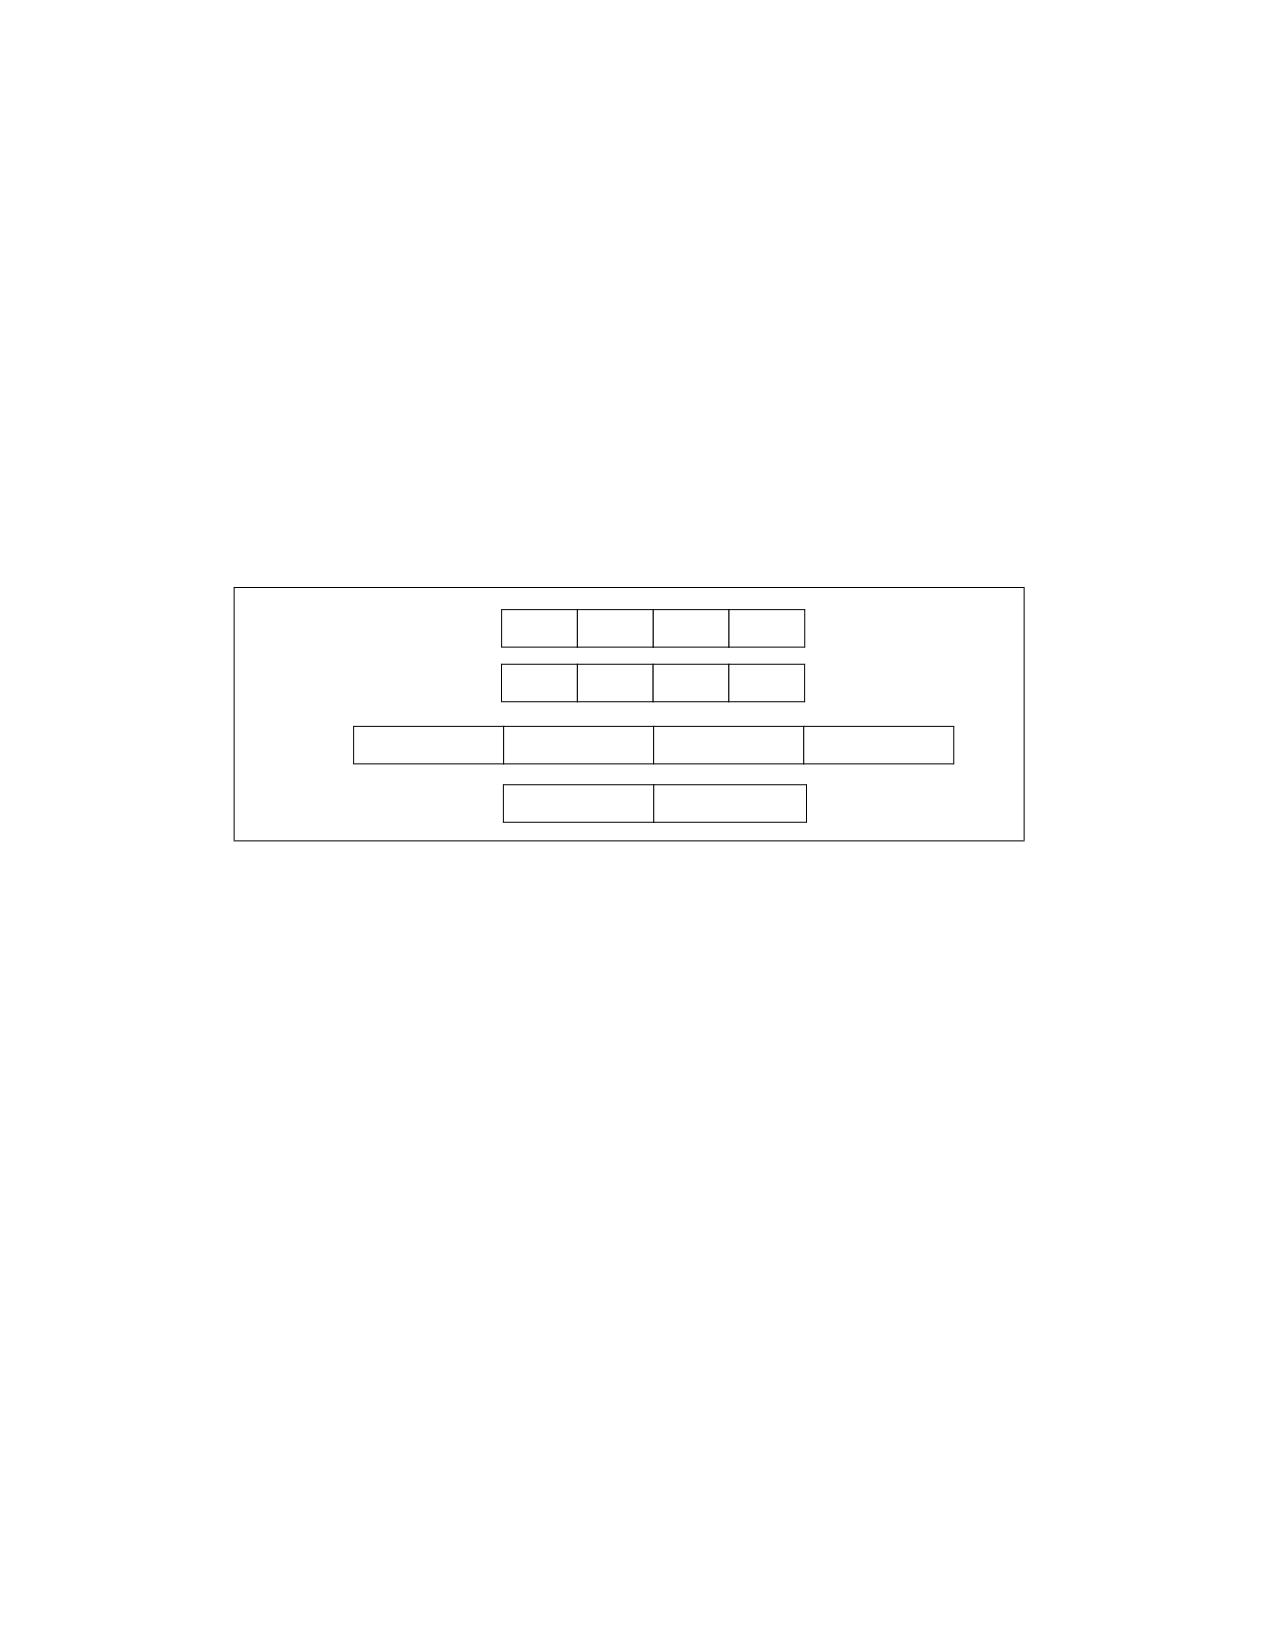
operation is performed on the other pairs of adjacent words. (Figure 4-11 shows this operation when using 64-bit
operands).
PMADDWD-Multiply and Add Packed Integers
Vol. 2B
4-313
The (V)PMADDWD instruction wraps around only in one situation: when the 2 pairs of words being operated on in
a group are all 8000H. In this case, the result wraps around to 80000000H.
In 64-bit mode and not encoded with VEX/EVEX, using a REX prefix in the form of REX.R permits this instruction to
access additional registers (XMM8-XMM15).
Legacy SSE version: The first source and destination operands are MMX registers. The second source operand is an
MMX register or a 64-bit memory location.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding YMM destina-
tion register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the destination YMM register are
zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers.
EVEX.512 encoded version: The second source operand can be an ZMM register or a 512-bit memory location. The
first source and destination operands are ZMM registers.
SRC
X3
X2
X1
X0
DEST
Y3
Y2
Y1
Y0
TEMP
X3 ∗ Y3
X2 ∗ Y2
X1 ∗ Y1
X0 ∗ Y0
DEST
(X3∗Y3) + (X2∗Y2)
(X1∗Y1) + (X0∗Y0)
Figure 4-11. PMADDWD Execution Model Using 64-bit Operands
Operation
PMADDWD (With 64-bit Operands)
DEST[31:0] := (DEST[15:0] ∗ SRC[15:0]) + (DEST[31:16] ∗ SRC[31:16]);
DEST[63:32] := (DEST[47:32] ∗ SRC[47:32]) + (DEST[63:48] ∗ SRC[63:48]);
PMADDWD (With 128-bit Operands)
DEST[31:0] := (DEST[15:0] ∗ SRC[15:0]) + (DEST[31:16] ∗ SRC[31:16]);
DEST[63:32] := (DEST[47:32] ∗ SRC[47:32]) + (DEST[63:48] ∗ SRC[63:48]);
DEST[95:64] := (DEST[79:64] ∗ SRC[79:64]) + (DEST[95:80] ∗ SRC[95:80]);
DEST[127:96] := (DEST[111:96] ∗ SRC[111:96]) + (DEST[127:112] ∗ SRC[127:112]);
VPMADDWD (VEX.128 Encoded Version)
DEST[31:0] := (SRC1[15:0] * SRC2[15:0]) + (SRC1[31:16] * SRC2[31:16])
DEST[63:32] := (SRC1[47:32] * SRC2[47:32]) + (SRC1[63:48] * SRC2[63:48])
DEST[95:64] := (SRC1[79:64] * SRC2[79:64]) + (SRC1[95:80] * SRC2[95:80])
DEST[127:96] := (SRC1[111:96] * SRC2[111:96]) + (SRC1[127:112] * SRC2[127:112])
DEST[MAXVL-1:128] := 0
PMADDWD-Multiply and Add Packed Integers
Vol. 2B
4-314
VPMADDWD (VEX.256 Encoded Version)
DEST[31:0] := (SRC1[15:0] * SRC2[15:0]) + (SRC1[31:16] * SRC2[31:16])
DEST[63:32] := (SRC1[47:32] * SRC2[47:32]) + (SRC1[63:48] * SRC2[63:48])
DEST[95:64] := (SRC1[79:64] * SRC2[79:64]) + (SRC1[95:80] * SRC2[95:80])
DEST[127:96] := (SRC1[111:96] * SRC2[111:96]) + (SRC1[127:112] * SRC2[127:112])
DEST[159:128] := (SRC1[143:128] * SRC2[143:128]) + (SRC1[159:144] * SRC2[159:144])
DEST[191:160] := (SRC1[175:160] * SRC2[175:160]) + (SRC1[191:176] * SRC2[191:176])
DEST[223:192] := (SRC1[207:192] * SRC2[207:192]) + (SRC1[223:208] * SRC2[223:208])
DEST[255:224] := (SRC1[239:224] * SRC2[239:224]) + (SRC1[255:240] * SRC2[255:240])
DEST[MAXVL-1:256] := 0
VPMADDWD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := (SRC2[i+31:i+16]* SRC1[i+31:i+16]) + (SRC2[i+15:i]*SRC1[i+15:i])
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+31:i] = 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VPMADDWD __m512i _mm512_madd_epi16( __m512i a, __m512i b);
VPMADDWD __m512i _mm512_mask_madd_epi16(__m512i s, __mmask32 k, __m512i a, __m512i b);
VPMADDWD __m512i _mm512_maskz_madd_epi16( __mmask32 k, __m512i a, __m512i b);
VPMADDWD __m256i _mm256_mask_madd_epi16(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMADDWD __m256i _mm256_maskz_madd_epi16( __mmask16 k, __m256i a, __m256i b);
VPMADDWD __m128i _mm_mask_madd_epi16(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMADDWD __m128i _mm_maskz_madd_epi16( __mmask8 k, __m128i a, __m128i b);
PMADDWD __m64 _mm_madd_pi16(__m64 m1, __m64 m2)
(V)PMADDWD __m128i _mm_madd_epi16 ( __m128i a, __m128i b)
VPMADDWD __m256i _mm256_madd_epi16 ( __m256i a, __m256i b)
Flags Affected
None.
Numeric Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Exceptions Type E4NF.nb in Table 2-52, “Type E4NF Class Exception Conditions.”
PMADDWD-Multiply and Add Packed Integers
Vol. 2B
4-315

PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
NP 0F EE /r1
A
V/V
SSE
Compare signed word integers in mm2/m64 and
mm1 and return maximum values.
PMAXSW mm1, mm2/m64
66 0F 38 3C /r
A
V/V
SSE4_1
Compare packed signed byte integers in xmm1
PMAXSB xmm1, xmm2/m128
and xmm2/m128 and store packed maximum
values in xmm1.
66 0F EE /r
A
V/V
SSE2
Compare packed signed word integers in
PMAXSW xmm1, xmm2/m128
xmm2/m128 and xmm1 and stores maximum
packed values in xmm1.
66 0F 38 3D /r
A
V/V
SSE4_1
Compare packed signed dword integers in xmm1
PMAXSD xmm1, xmm2/m128
and xmm2/m128 and store packed maximum
values in xmm1.
VEX.128.66.0F38.WIG 3C /r
B
V/V
AVX
Compare packed signed byte integers in xmm2
VPMAXSB xmm1, xmm2, xmm3/m128
and xmm3/m128 and store packed maximum
values in xmm1.
VEX.128.66.0F.WIG EE /r
B
V/V
AVX
Compare packed signed word integers in
VPMAXSW xmm1, xmm2, xmm3/m128
xmm3/m128 and xmm2 and store packed
maximum values in xmm1.
VEX.128.66.0F38.WIG 3D /r
B
V/V
AVX
Compare packed signed dword integers in xmm2
VPMAXSD xmm1, xmm2, xmm3/m128
and xmm3/m128 and store packed maximum
values in xmm1.
VEX.256.66.0F38.WIG 3C /r
B
V/V
AVX2
Compare packed signed byte integers in ymm2
VPMAXSB ymm1, ymm2, ymm3/m256
and ymm3/m256 and store packed maximum
values in ymm1.
VEX.256.66.0F.WIG EE /r
B
V/V
AVX2
Compare packed signed word integers in
VPMAXSW ymm1, ymm2, ymm3/m256
ymm3/m256 and ymm2 and store packed
maximum values in ymm1.
VEX.256.66.0F38.WIG 3D /r
B
V/V
AVX2
Compare packed signed dword integers in ymm2
VPMAXSD ymm1, ymm2, ymm3/m256
and ymm3/m256 and store packed maximum
values in ymm1.
EVEX.128.66.0F38.WIG 3C /r
C
V/V
(AVX512VL AND
Compare packed signed byte integers in xmm2
VPMAXSB xmm1{k1}{z}, xmm2,
AVX512BW) OR
and xmm3/m128 and store packed maximum
xmm3/m128
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F38.WIG 3C /r
C
V/V
(AVX512VL AND
Compare packed signed byte integers in ymm2
VPMAXSB ymm1{k1}{z}, ymm2,
AVX512BW) OR
and ymm3/m256 and store packed maximum
ymm3/m256
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F38.WIG 3C /r
C
V/V
AVX512BW OR
Compare packed signed byte integers in zmm2
VPMAXSB zmm1{k1}{z}, zmm2,
AVX10.1
and zmm3/m512 and store packed maximum
zmm3/m512
values in zmm1 under writemask k1.
EVEX.128.66.0F.WIG EE /r
C
V/V
(AVX512VL AND
Compare packed signed word integers in xmm2
VPMAXSW xmm1{k1}{z}, xmm2,
AVX512BW) OR
and xmm3/m128 and store packed maximum
xmm3/m128
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F.WIG EE /r
C
V/V
(AVX512VL AND
Compare packed signed word integers in ymm2
VPMAXSW ymm1{k1}{z}, ymm2,
AVX512BW) OR
and ymm3/m256 and store packed maximum
ymm3/m256
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F.WIG EE /r
C
V/V
AVX512BW OR
Compare packed signed word integers in zmm2
VPMAXSW zmm1{k1}{z}, zmm2,
AVX10.1
and zmm3/m512 and store packed maximum
zmm3/m512
values in zmm1 under writemask k1.
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-316

Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
EVEX.128.66.0F38.W0 3D /r
D
V/V
(AVX512VL AND
Compare packed signed dword integers in xmm2
VPMAXSD xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128/m32bcst and store packed
xmm3/m128/m32bcst
AVX10.1
maximum values in xmm1 using writemask k1.
EVEX.256.66.0F38.W0 3D /r
D
V/V
(AVX512VL AND
Compare packed signed dword integers in ymm2
VPMAXSD ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256/m32bcst and store packed
ymm3/m256/m32bcst
AVX10.1
maximum values in ymm1 using writemask k1.
EVEX.512.66.0F38.W0 3D /r
D
V/V
AVX512F
Compare packed signed dword integers in zmm2
VPMAXSD zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m32bcst and store packed
zmm3/m512/m32bcst
maximum values in zmm1 using writemask k1.
EVEX.128.66.0F38.W1 3D /r
D
V/V
(AVX512VL AND
Compare packed signed qword integers in xmm2
VPMAXSQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128/m64bcst and store packed
xmm3/m128/m64bcst
AVX10.1
maximum values in xmm1 using writemask k1.
EVEX.256.66.0F38.W1 3D /r
D
V/V
(AVX512VL AND
Compare packed signed qword integers in ymm2
VPMAXSQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256/m64bcst and store packed
ymm3/m256/m64bcst
AVX10.1
maximum values in ymm1 using writemask k1.
EVEX.512.66.0F38.W1 3D /r
D
V/V
AVX512F
Compare packed signed qword integers in zmm2
VPMAXSQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m64bcst and store packed
zmm3/m512/m64bcst
maximum values in zmm1 using writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
D
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed signed byte, word, dword or qword integers in the second source operand
and the first source operand and returns the maximum value for each pair of integers to the destination operand.
Legacy SSE version PMAXSW: The source operand can be an MMX technology register or a 64-bit memory location.
The destination operand can be an MMX technology register.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding YMM destina-
tion register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers. Bits (MAXVL-1:256) of the corresponding destination
register are zeroed.
EVEX encoded VPMAXSD/Q: The first source operand is a ZMM/YMM/XMM register; The second source operand is
a ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512/256/128-bit vector broadcasted from a
32/64-bit memory location. The destination operand is conditionally updated based on writemask k1.
EVEX encoded VPMAXSB/W: The first source operand is a ZMM/YMM/XMM register; The second source operand is
a ZMM/YMM/XMM register, a 512/256/128-bit memory location. The destination operand is conditionally updated
based on writemask k1.
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-317
Operation
PMAXSW (64-bit Operands)
IF DEST[15:0] > SRC[15:0]) THEN
DEST[15:0] := DEST[15:0];
ELSE
DEST[15:0] := SRC[15:0]; FI;
(* Repeat operation for 2nd and 3rd words in source and destination operands *)
IF DEST[63:48] > SRC[63:48]) THEN
DEST[63:48] := DEST[63:48];
ELSE
DEST[63:48] := SRC[63:48]; FI;
PMAXSB (128-bit Legacy SSE Version)
IF DEST[7:0] > SRC[7:0] THEN
DEST[7:0] := DEST[7:0];
ELSE
DEST[7:0] := SRC[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF DEST[127:120] >SRC[127:120] THEN
DEST[127:120] := DEST[127:120];
ELSE
DEST[127:120] := SRC[127:120]; FI;
DEST[MAXVL-1:128] (Unmodified)
VPMAXSB (VEX.128 Encoded Version)
IF SRC1[7:0] > SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[7:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF SRC1[127:120] >SRC2[127:120] THEN
DEST[127:120] := SRC1[127:120];
ELSE
DEST[127:120] := SRC2[127:120]; FI;
DEST[MAXVL-1:128] := 0
VPMAXSB (VEX.256 Encoded Version)
IF SRC1[7:0] > SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[7:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 31st bytes in source and destination operands *)
IF SRC1[255:248] >SRC2[255:248] THEN
DEST[255:248] := SRC1[255:248];
ELSE
DEST[255:248] := SRC2[255:248]; FI;
DEST[MAXVL-1:256] := 0
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-318
VPMAXSB (EVEX Encoded Versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask* THEN
IF SRC1[i+7:i] > SRC2[i+7:i]
THEN DEST[i+7:i] := SRC1[i+7:i];
ELSE DEST[i+7:i] := SRC2[i+7:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMAXSW (128-bit Legacy SSE Version)
IF DEST[15:0] >SRC[15:0] THEN
DEST[15:0] := DEST[15:0];
ELSE
DEST[15:0] := SRC[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:112] >SRC[127:112] THEN
DEST[127:112] := DEST[127:112];
ELSE
DEST[127:112] := SRC[127:112]; FI;
DEST[MAXVL-1:128] (Unmodified)
VPMAXSW (VEX.128 Encoded Version)
IF SRC1[15:0] > SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF SRC1[127:112] >SRC2[127:112] THEN
DEST[127:112] := SRC1[127:112];
ELSE
DEST[127:112] := SRC2[127:112]; FI;
DEST[MAXVL-1:128] := 0
VPMAXSW (VEX.256 Encoded Version)
IF SRC1[15:0] > SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 15th words in source and destination operands *)
IF SRC1[255:240] >SRC2[255:240] THEN
DEST[255:240] := SRC1[255:240];
ELSE
DEST[255:240] := SRC2[255:240]; FI;
DEST[MAXVL-1:256] := 0
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-319
VPMAXSW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask* THEN
IF SRC1[i+15:i] > SRC2[i+15:i]
THEN DEST[i+15:i] := SRC1[i+15:i];
ELSE DEST[i+15:i] := SRC2[i+15:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMAXSD (128-bit Legacy SSE Version)
IF DEST[31:0] >SRC[31:0] THEN
DEST[31:0] := DEST[31:0];
ELSE
DEST[31:0] := SRC[31:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:96] >SRC[127:96] THEN
DEST[127:96] := DEST[127:96];
ELSE
DEST[127:96] := SRC[127:96]; FI;
DEST[MAXVL-1:128] (Unmodified)
VPMAXSD (VEX.128 Encoded Version)
IF SRC1[31:0] > SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 3rd dwords in source and destination operands *)
IF SRC1[127:96] > SRC2[127:96] THEN
DEST[127:96] := SRC1[127:96];
ELSE
DEST[127:96] := SRC2[127:96]; FI;
DEST[MAXVL-1:128] := 0
VPMAXSD (VEX.256 Encoded Version)
IF SRC1[31:0] > SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 7th dwords in source and destination operands *)
IF SRC1[255:224] > SRC2[255:224] THEN
DEST[255:224] := SRC1[255:224];
ELSE
DEST[255:224] := SRC2[255:224]; FI;
DEST[MAXVL-1:256] := 0
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-320
VPMAXSD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+31:i] > SRC2[31:0]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[31:0];
FI;
ELSE
IF SRC1[i+31:i] > SRC2[i+31:i]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[i+31:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMAXSQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+63:i] > SRC2[63:0]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[63:0];
FI;
ELSE
IF SRC1[i+63:i] > SRC2[i+63:i]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[i+63:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[i+63:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-321
Intel C/C++ Compiler Intrinsic Equivalent
VPMAXSB __m512i _mm512_max_epi8( __m512i a, __m512i b);
VPMAXSB __m512i _mm512_mask_max_epi8(__m512i s, __mmask64 k, __m512i a, __m512i b);
VPMAXSB __m512i _mm512_maskz_max_epi8( __mmask64 k, __m512i a, __m512i b);
VPMAXSW __m512i _mm512_max_epi16( __m512i a, __m512i b);
VPMAXSW __m512i _mm512_mask_max_epi16(__m512i s, __mmask32 k, __m512i a, __m512i b);
VPMAXSW __m512i _mm512_maskz_max_epi16( __mmask32 k, __m512i a, __m512i b);
VPMAXSB __m256i _mm256_mask_max_epi8(__m256i s, __mmask32 k, __m256i a, __m256i b);
VPMAXSB __m256i _mm256_maskz_max_epi8( __mmask32 k, __m256i a, __m256i b);
VPMAXSW __m256i _mm256_mask_max_epi16(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMAXSW __m256i _mm256_maskz_max_epi16( __mmask16 k, __m256i a, __m256i b);
VPMAXSB __m128i _mm_mask_max_epi8(__m128i s, __mmask16 k, __m128i a, __m128i b);
VPMAXSB __m128i _mm_maskz_max_epi8( __mmask16 k, __m128i a, __m128i b);
VPMAXSW __m128i _mm_mask_max_epi16(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMAXSW __m128i _mm_maskz_max_epi16( __mmask8 k, __m128i a, __m128i b);
VPMAXSD __m256i _mm256_mask_max_epi32(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMAXSD __m256i _mm256_maskz_max_epi32( __mmask16 k, __m256i a, __m256i b);
VPMAXSQ __m256i _mm256_mask_max_epi64(__m256i s, __mmask8 k, __m256i a, __m256i b);
VPMAXSQ __m256i _mm256_maskz_max_epi64( __mmask8 k, __m256i a, __m256i b);
VPMAXSD __m128i _mm_mask_max_epi32(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMAXSD __m128i _mm_maskz_max_epi32( __mmask8 k, __m128i a, __m128i b);
VPMAXSQ __m128i _mm_mask_max_epi64(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMAXSQ __m128i _mm_maskz_max_epu64( __mmask8 k, __m128i a, __m128i b);
VPMAXSD __m512i _mm512_max_epi32( __m512i a, __m512i b);
VPMAXSD __m512i _mm512_mask_max_epi32(__m512i s, __mmask16 k, __m512i a, __m512i b);
VPMAXSD __m512i _mm512_maskz_max_epi32( __mmask16 k, __m512i a, __m512i b);
VPMAXSQ __m512i _mm512_max_epi64( __m512i a, __m512i b);
VPMAXSQ __m512i _mm512_mask_max_epi64(__m512i s, __mmask8 k, __m512i a, __m512i b);
VPMAXSQ __m512i _mm512_maskz_max_epi64( __mmask8 k, __m512i a, __m512i b);
(V)PMAXSB __m128i _mm_max_epi8 ( __m128i a, __m128i b);
(V)PMAXSW __m128i _mm_max_epi16 ( __m128i a, __m128i b)
(V)PMAXSD __m128i _mm_max_epi32 ( __m128i a, __m128i b);
VPMAXSB __m256i _mm256_max_epi8 ( __m256i a, __m256i b);
VPMAXSW __m256i _mm256_max_epi16 ( __m256i a, __m256i b)
VPMAXSD __m256i _mm256_max_epi32 ( __m256i a, __m256i b);
PMAXSW:__m64 _mm_max_pi16(__m64 a, __m64 b)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded VPMAXSD/Q, see Table 2-51, “Type E4 Class Exception Conditions.”
EVEX-encoded VPMAXSB/W, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
PMAXSB/PMAXSW/PMAXSD/PMAXSQ-Maximum of Packed Signed Integers
Vol. 2B
4-322

PMAXUB/PMAXUW-Maximum of Packed Unsigned Integers
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
NP 0F DE /r1
A
V/V
SSE
Compare unsigned byte integers in mm2/m64 and
mm1 and returns maximum values.
PMAXUB mm1, mm2/m64
66 0F DE /r
A
V/V
SSE2
Compare packed unsigned byte integers in xmm1
PMAXUB xmm1, xmm2/m128
and xmm2/m128 and store packed maximum
values in xmm1.
66 0F 38 3E/r
A
V/V
SSE4_1
Compare packed unsigned word integers in
PMAXUW xmm1, xmm2/m128
xmm2/m128 and xmm1 and stores maximum
packed values in xmm1.
VEX.128.66.0F DE /r
B
V/V
AVX
Compare packed unsigned byte integers in xmm2
VPMAXUB xmm1, xmm2, xmm3/m128
and xmm3/m128 and store packed maximum
values in xmm1.
VEX.128.66.0F38 3E/r
B
V/V
AVX
Compare packed unsigned word integers in
VPMAXUW xmm1, xmm2, xmm3/m128
xmm3/m128 and xmm2 and store maximum
packed values in xmm1.
VEX.256.66.0F DE /r
B
V/V
AVX2
Compare packed unsigned byte integers in ymm2
VPMAXUB ymm1, ymm2, ymm3/m256
and ymm3/m256 and store packed maximum
values in ymm1.
VEX.256.66.0F38 3E/r
B
V/V
AVX2
Compare packed unsigned word integers in
VPMAXUW ymm1, ymm2, ymm3/m256
ymm3/m256 and ymm2 and store maximum
packed values in ymm1.
EVEX.128.66.0F.WIG DE /r
C
V/V
(AVX512VL AND
Compare packed unsigned byte integers in xmm2
VPMAXUB xmm1{k1}{z}, xmm2,
AVX512BW) OR
and xmm3/m128 and store packed maximum
xmm3/m128
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F.WIG DE /r
C
V/V
(AVX512VL AND
Compare packed unsigned byte integers in ymm2
VPMAXUB ymm1{k1}{z}, ymm2,
AVX512BW) OR
and ymm3/m256 and store packed maximum
ymm3/m256
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F.WIG DE /r
C
V/V
AVX512BW
Compare packed unsigned byte integers in zmm2
VPMAXUB zmm1{k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512 and store packed maximum
zmm3/m512
values in zmm1 under writemask k1.
EVEX.128.66.0F38.WIG 3E /r
C
V/V
(AVX512VL AND
Compare packed unsigned word integers in xmm2
VPMAXUW xmm1{k1}{z}, xmm2,
AVX512BW) OR
and xmm3/m128 and store packed maximum
xmm3/m128
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F38.WIG 3E /r
C
V/V
(AVX512VL AND
Compare packed unsigned word integers in ymm2
VPMAXUW ymm1{k1}{z}, ymm2,
AVX512BW) OR
and ymm3/m256 and store packed maximum
ymm3/m256
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F38.WIG 3E /r
C
V/V
AVX512BW
Compare packed unsigned word integers in zmm2
VPMAXUW zmm1{k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512 and store packed maximum
zmm3/m512
values in zmm1 under writemask k1.
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX Reg-
isters,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
PMAXUB/PMAXUW-Maximum of Packed Unsigned Integers
Vol. 2B
4-323

Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed unsigned byte, word integers in the second source operand and the first
source operand and returns the maximum value for each pair of integers to the destination operand.
Legacy SSE version PMAXUB: The source operand can be an MMX technology register or a 64-bit memory location.
The destination operand can be an MMX technology register.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers.
EVEX encoded versions: The first source operand is a ZMM/YMM/XMM register; The second source operand is a
ZMM/YMM/XMM register or a 512/256/128-bit memory location. The destination operand is conditionally updated
based on writemask k1.
Operation
PMAXUB (64-bit Operands)
IF DEST[7:0] > SRC[17:0]) THEN
DEST[7:0] := DEST[7:0];
ELSE
DEST[7:0] := SRC[7:0]; FI;
(* Repeat operation for 2nd through 7th bytes in source and destination operands *)
IF DEST[63:56] > SRC[63:56]) THEN
DEST[63:56] := DEST[63:56];
ELSE
DEST[63:56] := SRC[63:56]; FI;
PMAXUB (128-bit Legacy SSE Version)
IF DEST[7:0] >SRC[7:0] THEN
DEST[7:0] := DEST[7:0];
ELSE
DEST[15:0] := SRC[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF DEST[127:120] >SRC[127:120] THEN
DEST[127:120] := DEST[127:120];
ELSE
DEST[127:120] := SRC[127:120]; FI;
DEST[MAXVL-1:128] (Unmodified)
PMAXUB/PMAXUW-Maximum of Packed Unsigned Integers
Vol. 2B
4-324
VPMAXUB (VEX.128 Encoded Version)
IF SRC1[7:0] >SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[7:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF SRC1[127:120] >SRC2[127:120] THEN
DEST[127:120] := SRC1[127:120];
ELSE
DEST[127:120] := SRC2[127:120]; FI;
DEST[MAXVL-1:128] := 0
VPMAXUB (VEX.256 Encoded Version)
IF SRC1[7:0] >SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[15:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 31st bytes in source and destination operands *)
IF SRC1[255:248] >SRC2[255:248] THEN
DEST[255:248] := SRC1[255:248];
ELSE
DEST[255:248] := SRC2[255:248]; FI;
DEST[MAXVL-1:128] := 0
VPMAXUB (EVEX Encoded Versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask* THEN
IF SRC1[i+7:i] > SRC2[i+7:i]
THEN DEST[i+7:i] := SRC1[i+7:i];
ELSE DEST[i+7:i] := SRC2[i+7:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMAXUW (128-bit Legacy SSE Version)
IF DEST[15:0] >SRC[15:0] THEN
DEST[15:0] := DEST[15:0];
ELSE
DEST[15:0] := SRC[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:112] >SRC[127:112] THEN
DEST[127:112] := DEST[127:112];
ELSE
DEST[127:112] := SRC[127:112]; FI;
DEST[MAXVL-1:128] (Unmodified)
PMAXUB/PMAXUW-Maximum of Packed Unsigned Integers
Vol. 2B
4-325
VPMAXUW (VEX.128 Encoded Version)
IF SRC1[15:0] > SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF SRC1[127:112] >SRC2[127:112] THEN
DEST[127:112] := SRC1[127:112];
ELSE
DEST[127:112] := SRC2[127:112]; FI;
DEST[MAXVL-1:128] := 0
VPMAXUW (VEX.256 Encoded Version)
IF SRC1[15:0] > SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 15th words in source and destination operands *)
IF SRC1[255:240] >SRC2[255:240] THEN
DEST[255:240] := SRC1[255:240];
ELSE
DEST[255:240] := SRC2[255:240]; FI;
DEST[MAXVL-1:128] := 0
VPMAXUW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask* THEN
IF SRC1[i+15:i] > SRC2[i+15:i]
THEN DEST[i+15:i] := SRC1[i+15:i];
ELSE DEST[i+15:i] := SRC2[i+15:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMAXUB/PMAXUW-Maximum of Packed Unsigned Integers
Vol. 2B
4-326
Intel C/C++ Compiler Intrinsic Equivalent
VPMAXUB __m512i _mm512_max_epu8( __m512i a, __m512i b);
VPMAXUB __m512i _mm512_mask_max_epu8(__m512i s, __mmask64 k, __m512i a, __m512i b);
VPMAXUB __m512i _mm512_maskz_max_epu8( __mmask64 k, __m512i a, __m512i b);
VPMAXUW __m512i _mm512_max_epu16( __m512i a, __m512i b);
VPMAXUW __m512i _mm512_mask_max_epu16(__m512i s, __mmask32 k, __m512i a, __m512i b);
VPMAXUW __m512i _mm512_maskz_max_epu16( __mmask32 k, __m512i a, __m512i b);
VPMAXUB __m256i _mm256_mask_max_epu8(__m256i s, __mmask32 k, __m256i a, __m256i b);
VPMAXUB __m256i _mm256_maskz_max_epu8( __mmask32 k, __m256i a, __m256i b);
VPMAXUW __m256i _mm256_mask_max_epu16(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMAXUW __m256i _mm256_maskz_max_epu16( __mmask16 k, __m256i a, __m256i b);
VPMAXUB __m128i _mm_mask_max_epu8(__m128i s, __mmask16 k, __m128i a, __m128i b);
VPMAXUB __m128i _mm_maskz_max_epu8( __mmask16 k, __m128i a, __m128i b);
VPMAXUW __m128i _mm_mask_max_epu16(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMAXUW __m128i _mm_maskz_max_epu16( __mmask8 k, __m128i a, __m128i b);
(V)PMAXUB __m128i _mm_max_epu8 ( __m128i a, __m128i b);
(V)PMAXUW __m128i _mm_max_epu16 ( __m128i a, __m128i b)
VPMAXUB __m256i _mm256_max_epu8 ( __m256i a, __m256i b);
VPMAXUW __m256i _mm256_max_epu16 ( __m256i a, __m256i b);
PMAXUB __m64 _mm_max_pu8(__m64 a, __m64 b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
PMAXUB/PMAXUW-Maximum of Packed Unsigned Integers
Vol. 2B
4-327

PMAXUD/PMAXUQ-Maximum of Packed Unsigned Integers
Opcode/
Op/En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
66 0F 38 3F /r
A
V/V
SSE4_1
Compare packed unsigned dword integers in xmm1
PMAXUD xmm1, xmm2/m128
and xmm2/m128 and store packed maximum
values in xmm1.
VEX.128.66.0F38.WIG 3F /r
B
V/V
AVX
Compare packed unsigned dword integers in xmm2
VPMAXUD xmm1, xmm2, xmm3/m128
and xmm3/m128 and store packed maximum
values in xmm1.
VEX.256.66.0F38.WIG 3F /r
B
V/V
AVX2
Compare packed unsigned dword integers in ymm2
VPMAXUD ymm1, ymm2, ymm3/m256
and ymm3/m256 and store packed maximum
values in ymm1.
EVEX.128.66.0F38.W0 3F /r
C
V/V
(AVX512VL AND
Compare packed unsigned dword integers in xmm2
VPMAXUD xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128/m32bcst and store packed
xmm3/m128/m32bcst
AVX10.1
maximum values in xmm1 under writemask k1.
EVEX.256.66.0F38.W0 3F /r
C
V/V
(AVX512VL AND
Compare packed unsigned dword integers in ymm2
VPMAXUD ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256/m32bcst and store packed
ymm3/m256/m32bcst
AVX10.1
maximum values in ymm1 under writemask k1.
EVEX.512.66.0F38.W0 3F /r
C
V/V
AVX512F
Compare packed unsigned dword integers in zmm2
VPMAXUD zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m32bcst and store packed
zmm3/m512/m32bcst
maximum values in zmm1 under writemask k1.
EVEX.128.66.0F38.W1 3F /r
C
V/V
(AVX512VL AND
Compare packed unsigned qword integers in xmm2
VPMAXUQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128/m64bcst and store packed
xmm3/m128/m64bcst
AVX10.1
maximum values in xmm1 under writemask k1.
EVEX.256.66.0F38.W1 3F /r
C
V/V
(AVX512VL AND
Compare packed unsigned qword integers in ymm2
VPMAXUQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256/m64bcst and store packed
ymm3/m256/m64bcst
AVX10.1
maximum values in ymm1 under writemask k1.
EVEX.512.66.0F38.W1 3F /r
C
V/V
AVX512F
Compare packed unsigned qword integers in zmm2
VPMAXUQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m64bcst and store packed
zmm3/m512/m64bcst
maximum values in zmm1 under writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv
ModRM:r/m (r)
N/A
C
Full
ModRM:reg (w)
EVEX.vvvv
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed unsigned dword or qword integers in the second source operand and the
first source operand and returns the maximum value for each pair of integers to the destination operand.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The first source operand is a YMM register; The second source operand is a YMM register
or 256-bit memory location. Bits (MAXVL-1:256) of the corresponding destination register are zeroed.
PMAXUD/PMAXUQ-Maximum of Packed Unsigned Integers
Vol. 2B
4-328
EVEX encoded versions: The first source operand is a ZMM/YMM/XMM register; The second source operand is a
ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512/256/128-bit vector broadcasted from a
32/64-bit memory location. The destination operand is conditionally updated based on writemask k1.
Operation
PMAXUD (128-bit Legacy SSE Version)
IF DEST[31:0] >SRC[31:0] THEN
DEST[31:0] := DEST[31:0];
ELSE
DEST[31:0] := SRC[31:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:96] >SRC[127:96] THEN
DEST[127:96] := DEST[127:96];
ELSE
DEST[127:96] := SRC[127:96]; FI;
DEST[MAXVL-1:128] (Unmodified)
VPMAXUD (VEX.128 Encoded Version)
IF SRC1[31:0] > SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 3rd dwords in source and destination operands *)
IF SRC1[127:96] > SRC2[127:96] THEN
DEST[127:96] := SRC1[127:96];
ELSE
DEST[127:96] := SRC2[127:96]; FI;
DEST[MAXVL-1:128] := 0
VPMAXUD (VEX.256 Encoded Version)
IF SRC1[31:0] > SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 7th dwords in source and destination operands *)
IF SRC1[255:224] > SRC2[255:224] THEN
DEST[255:224] := SRC1[255:224];
ELSE
DEST[255:224] := SRC2[255:224]; FI;
DEST[MAXVL-1:256] := 0
PMAXUD/PMAXUQ-Maximum of Packed Unsigned Integers
Vol. 2B
4-329
VPMAXUD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+31:i] > SRC2[31:0]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[31:0];
FI;
ELSE
IF SRC1[i+31:i] > SRC2[i+31:i]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[i+31:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[i+31:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
VPMAXUQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+63:i] > SRC2[63:0]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[63:0];
FI;
ELSE
IF SRC1[i+31:i] > SRC2[i+31:i]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[i+63:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
THEN DEST[i+63:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMAXUD/PMAXUQ-Maximum of Packed Unsigned Integers
Vol. 2B
4-330
Intel C/C++ Compiler Intrinsic Equivalent
VPMAXUD __m512i _mm512_max_epu32( __m512i a, __m512i b);
VPMAXUD __m512i _mm512_mask_max_epu32(__m512i s, __mmask16 k, __m512i a, __m512i b);
VPMAXUD __m512i _mm512_maskz_max_epu32( __mmask16 k, __m512i a, __m512i b);
VPMAXUQ __m512i _mm512_max_epu64( __m512i a, __m512i b);
VPMAXUQ __m512i _mm512_mask_max_epu64(__m512i s, __mmask8 k, __m512i a, __m512i b);
VPMAXUQ __m512i _mm512_maskz_max_epu64( __mmask8 k, __m512i a, __m512i b);
VPMAXUD __m256i _mm256_mask_max_epu32(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMAXUD __m256i _mm256_maskz_max_epu32( __mmask16 k, __m256i a, __m256i b);
VPMAXUQ __m256i _mm256_mask_max_epu64(__m256i s, __mmask8 k, __m256i a, __m256i b);
VPMAXUQ __m256i _mm256_maskz_max_epu64( __mmask8 k, __m256i a, __m256i b);
VPMAXUD __m128i _mm_mask_max_epu32(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMAXUD __m128i _mm_maskz_max_epu32( __mmask8 k, __m128i a, __m128i b);
VPMAXUQ __m128i _mm_mask_max_epu64(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMAXUQ __m128i _mm_maskz_max_epu64( __mmask8 k, __m128i a, __m128i b);
(V)PMAXUD __m128i _mm_max_epu32 ( __m128i a, __m128i b);
VPMAXUD __m256i _mm256_max_epu32 ( __m256i a, __m256i b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
PMAXUD/PMAXUQ-Maximum of Packed Unsigned Integers
Vol. 2B
4-331

PMINSB/PMINSW-Minimum of Packed Signed Integers
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
NP 0F EA /r1
A
V/V
SSE
Compare signed word integers in mm2/m64 and
mm1 and return minimum values.
PMINSW mm1, mm2/m64
66 0F 38 38 /r
A
V/V
SSE4_1
Compare packed signed byte integers in xmm1 and
PMINSB xmm1, xmm2/m128
xmm2/m128 and store packed minimum values in
xmm1.
66 0F EA /r
A
V/V
SSE2
Compare packed signed word integers in
PMINSW xmm1, xmm2/m128
xmm2/m128 and xmm1 and store packed
minimum values in xmm1.
VEX.128.66.0F38 38 /r
B
V/V
AVX
Compare packed signed byte integers in xmm2 and
VPMINSB xmm1, xmm2, xmm3/m128
xmm3/m128 and store packed minimum values in
xmm1.
VEX.128.66.0F EA /r
B
V/V
AVX
Compare packed signed word integers in
VPMINSW xmm1, xmm2, xmm3/m128
xmm3/m128 and xmm2 and return packed
minimum values in xmm1.
VEX.256.66.0F38 38 /r
B
V/V
AVX2
Compare packed signed byte integers in ymm2 and
VPMINSB ymm1, ymm2, ymm3/m256
ymm3/m256 and store packed minimum values in
ymm1.
VEX.256.66.0F EA /r
B
V/V
AVX2
Compare packed signed word integers in
VPMINSW ymm1, ymm2, ymm3/m256
ymm3/m256 and ymm2 and return packed
minimum values in ymm1.
EVEX.128.66.0F38.WIG 38 /r
C
V/V
(AVX512VL AND
Compare packed signed byte integers in xmm2 and
VPMINSB xmm1{k1}{z}, xmm2,
AVX512BW) OR
xmm3/m128 and store packed minimum values in
xmm3/m128
AVX10.1
xmm1 under writemask k1.
EVEX.256.66.0F38.WIG 38 /r
C
V/V
(AVX512VL AND
Compare packed signed byte integers in ymm2 and
VPMINSB ymm1{k1}{z}, ymm2,
AVX512BW) OR
ymm3/m256 and store packed minimum values in
ymm3/m256
AVX10.1
ymm1 under writemask k1.
EVEX.512.66.0F38.WIG 38 /r
C
V/V
AVX512BW OR
Compare packed signed byte integers in zmm2 and
VPMINSB zmm1{k1}{z}, zmm2,
AVX10.1
zmm3/m512 and store packed minimum values in
zmm3/m512
zmm1 under writemask k1.
EVEX.128.66.0F.WIG EA /r
C
V/V
(AVX512VL AND
Compare packed signed word integers in xmm2
VPMINSW xmm1{k1}{z}, xmm2,
AVX512BW) OR
and xmm3/m128 and store packed minimum
xmm3/m128
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F.WIG EA /r
C
V/V
(AVX512VL AND
Compare packed signed word integers in ymm2
VPMINSW ymm1{k1}{z}, ymm2,
AVX512BW) OR
and ymm3/m256 and store packed minimum
ymm3/m256
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F.WIG EA /r
C
V/V
AVX512BW OR
Compare packed signed word integers in zmm2 and
VPMINSW zmm1{k1}{z}, zmm2,
AVX10.1
zmm3/m512 and store packed minimum values in
zmm3/m512
zmm1 under writemask k1.
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX Reg-
isters,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
PMINSB/PMINSW-Minimum of Packed Signed Integers
Vol. 2B
4-332

Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed signed byte, word, or dword integers in the second source operand and
the first source operand and returns the minimum value for each pair of integers to the destination operand.
Legacy SSE version PMINSW: The source operand can be an MMX technology register or a 64-bit memory location.
The destination operand can be an MMX technology register.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers.
EVEX encoded versions: The first source operand is a ZMM/YMM/XMM register; The second source operand is a
ZMM/YMM/XMM register or a 512/256/128-bit memory location. The destination operand is conditionally updated
based on writemask k1.
Operation
PMINSW (64-bit Operands)
IF DEST[15:0] < SRC[15:0] THEN
DEST[15:0] := DEST[15:0];
ELSE
DEST[15:0] := SRC[15:0]; FI;
(* Repeat operation for 2nd and 3rd words in source and destination operands *)
IF DEST[63:48] < SRC[63:48] THEN
DEST[63:48] := DEST[63:48];
ELSE
DEST[63:48] := SRC[63:48]; FI;
PMINSB (128-bit Legacy SSE Version)
IF DEST[7:0] < SRC[7:0] THEN
DEST[7:0] := DEST[7:0];
ELSE
DEST[15:0] := SRC[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF DEST[127:120] < SRC[127:120] THEN
DEST[127:120] := DEST[127:120];
ELSE
DEST[127:120] := SRC[127:120]; FI;
DEST[MAXVL-1:128] (Unmodified)
PMINSB/PMINSW-Minimum of Packed Signed Integers
Vol. 2B
4-333
VPMINSB (VEX.128 Encoded Version)
IF SRC1[7:0] < SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[7:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF SRC1[127:120] < SRC2[127:120] THEN
DEST[127:120] := SRC1[127:120];
ELSE
DEST[127:120] := SRC2[127:120]; FI;
DEST[MAXVL-1:128] := 0
VPMINSB (VEX.256 Encoded Version)
IF SRC1[7:0] < SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[15:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 31st bytes in source and destination operands *)
IF SRC1[255:248] < SRC2[255:248] THEN
DEST[255:248] := SRC1[255:248];
ELSE
DEST[255:248] := SRC2[255:248]; FI;
DEST[MAXVL-1:256] := 0
VPMINSB (EVEX Encoded Versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask* THEN
IF SRC1[i+7:i] < SRC2[i+7:i]
THEN DEST[i+7:i] := SRC1[i+7:i];
ELSE DEST[i+7:i] := SRC2[i+7:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMINSW (128-bit Legacy SSE Version)
IF DEST[15:0] < SRC[15:0] THEN
DEST[15:0] := DEST[15:0];
ELSE
DEST[15:0] := SRC[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:112] < SRC[127:112] THEN
DEST[127:112] := DEST[127:112];
ELSE
DEST[127:112] := SRC[127:112]; FI;
DEST[MAXVL-1:128] (Unmodified)
PMINSB/PMINSW-Minimum of Packed Signed Integers
Vol. 2B
4-334
VPMINSW (VEX.128 Encoded Version)
IF SRC1[15:0] < SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF SRC1[127:112] < SRC2[127:112] THEN
DEST[127:112] := SRC1[127:112];
ELSE
DEST[127:112] := SRC2[127:112]; FI;
DEST[MAXVL-1:128] := 0
VPMINSW (VEX.256 Encoded Version)
IF SRC1[15:0] < SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 15th words in source and destination operands *)
IF SRC1[255:240] < SRC2[255:240] THEN
DEST[255:240] := SRC1[255:240];
ELSE
DEST[255:240] := SRC2[255:240]; FI;
DEST[MAXVL-1:256] := 0
VPMINSW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask* THEN
IF SRC1[i+15:i] < SRC2[i+15:i]
THEN DEST[i+15:i] := SRC1[i+15:i];
ELSE DEST[i+15:i] := SRC2[i+15:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMINSB/PMINSW-Minimum of Packed Signed Integers
Vol. 2B
4-335
Intel C/C++ Compiler Intrinsic Equivalent
VPMINSB __m512i _mm512_min_epi8( __m512i a, __m512i b);
VPMINSB __m512i _mm512_mask_min_epi8(__m512i s, __mmask64 k, __m512i a, __m512i b);
VPMINSB __m512i _mm512_maskz_min_epi8( __mmask64 k, __m512i a, __m512i b);
VPMINSW __m512i _mm512_min_epi16( __m512i a, __m512i b);
VPMINSW __m512i _mm512_mask_min_epi16(__m512i s, __mmask32 k, __m512i a, __m512i b);
VPMINSW __m512i _mm512_maskz_min_epi16( __mmask32 k, __m512i a, __m512i b);
VPMINSB __m256i _mm256_mask_min_epi8(__m256i s, __mmask32 k, __m256i a, __m256i b);
VPMINSB __m256i _mm256_maskz_min_epi8( __mmask32 k, __m256i a, __m256i b);
VPMINSW __m256i _mm256_mask_min_epi16(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMINSW __m256i _mm256_maskz_min_epi16( __mmask16 k, __m256i a, __m256i b);
VPMINSB __m128i _mm_mask_min_epi8(__m128i s, __mmask16 k, __m128i a, __m128i b);
VPMINSB __m128i _mm_maskz_min_epi8( __mmask16 k, __m128i a, __m128i b);
VPMINSW __m128i _mm_mask_min_epi16(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMINSW __m128i _mm_maskz_min_epi16( __mmask8 k, __m128i a, __m128i b);
(V)PMINSB __m128i _mm_min_epi8 ( __m128i a, __m128i b);
(V)PMINSW __m128i _mm_min_epi16 ( __m128i a, __m128i b)
VPMINSB __m256i _mm256_min_epi8 ( __m256i a, __m256i b);
VPMINSW __m256i _mm256_min_epi16 ( __m256i a, __m256i b)
PMINSW__m64 _mm_min_pi16 (__m64 a, __m64 b)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
Additionally:
#MF
(64-bit operations only) If there is a pending x87 FPU exception.
PMINSB/PMINSW-Minimum of Packed Signed Integers
Vol. 2B
4-336

PMINSD/PMINSQ-Minimum of Packed Signed Integers
Opcode/
Op/E
64/32 bit
CPUID Feature
Description
Instruction
n
Mode
Flag
Support
66 0F 38 39 /r
A
V/V
SSE4_1
Compare packed signed dword integers in xmm1
PMINSD xmm1, xmm2/m128
and xmm2/m128 and store packed minimum values
in xmm1.
VEX.128.66.0F38.WIG 39 /r
B
V/V
AVX
Compare packed signed dword integers in xmm2
VPMINSD xmm1, xmm2, xmm3/m128
and xmm3/m128 and store packed minimum values
in xmm1.
VEX.256.66.0F38.WIG 39 /r
B
V/V
AVX2
Compare packed signed dword integers in ymm2
VPMINSD ymm1, ymm2, ymm3/m256
and ymm3/m128 and store packed minimum values
in ymm1.
EVEX.128.66.0F38.W0 39 /r
C
V/V
(AVX512VL AND
Compare packed signed dword integers in xmm2
VPMINSD xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128 and store packed minimum values
xmm3/m128/m32bcst
AVX10.1
in xmm1 under writemask k1.
EVEX.256.66.0F38.W0 39 /r
C
V/V
(AVX512VL AND
Compare packed signed dword integers in ymm2
VPMINSD ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256 and store packed minimum values
ymm3/m256/m32bcst
AVX10.1
in ymm1 under writemask k1.
EVEX.512.66.0F38.W0 39 /r
C
V/V
AVX512F
Compare packed signed dword integers in zmm2
VPMINSD zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m32bcst and store packed
zmm3/m512/m32bcst
minimum values in zmm1 under writemask k1.
EVEX.128.66.0F38.W1 39 /r
C
V/V
(AVX512VL AND
Compare packed signed qword integers in xmm2
VPMINSQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128 and store packed minimum values
xmm3/m128/m64bcst
AVX10.1
in xmm1 under writemask k1.
EVEX.256.66.0F38.W1 39 /r
C
V/V
(AVX512VL AND
Compare packed signed qword integers in ymm2
VPMINSQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256 and store packed minimum values
ymm3/m256/m64bcst
AVX10.1
in ymm1 under writemask k1.
EVEX.512.66.0F38.W1 39 /r
C
V/V
AVX512F
Compare packed signed qword integers in zmm2
VPMINSQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m64bcst and store packed
zmm3/m512/m64bcst
minimum values in zmm1 under writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed signed dword or qword integers in the second source operand and the first
source operand and returns the minimum value for each pair of integers to the destination operand.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers. Bits (MAXVL-1:256) of the corresponding destination
register are zeroed.
PMINSD/PMINSQ-Minimum of Packed Signed Integers
Vol. 2B
4-337
EVEX encoded versions: The first source operand is a ZMM/YMM/XMM register; The second source operand is a
ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512/256/128-bit vector broadcasted from a
32/64-bit memory location. The destination operand is conditionally updated based on writemask k1.
Operation
PMINSD (128-bit Legacy SSE Version)
IF DEST[31:0] < SRC[31:0] THEN
DEST[31:0] := DEST[31:0];
ELSE
DEST[31:0] := SRC[31:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:96] < SRC[127:96] THEN
DEST[127:96] := DEST[127:96];
ELSE
DEST[127:96] := SRC[127:96]; FI;
DEST[MAXVL-1:128] (Unmodified)
VPMINSD (VEX.128 Encoded Version)
IF SRC1[31:0] < SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 3rd dwords in source and destination operands *)
IF SRC1[127:96] < SRC2[127:96] THEN
DEST[127:96] := SRC1[127:96];
ELSE
DEST[127:96] := SRC2[127:96]; FI;
DEST[MAXVL-1:128] := 0
VPMINSD (VEX.256 Encoded Version)
IF SRC1[31:0] < SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 7th dwords in source and destination operands *)
IF SRC1[255:224] < SRC2[255:224] THEN
DEST[255:224] := SRC1[255:224];
ELSE
DEST[255:224] := SRC2[255:224]; FI;
DEST[MAXVL-1:256] := 0
PMINSD/PMINSQ-Minimum of Packed Signed Integers
Vol. 2B
4-338
VPMINSD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+31:i] < SRC2[31:0]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[31:0];
FI;
ELSE
IF SRC1[i+31:i] < SRC2[i+31:i]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[i+31:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
VPMINSQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+63:i] < SRC2[63:0]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[63:0];
FI;
ELSE
IF SRC1[i+63:i] < SRC2[i+63:i]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[i+63:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMINSD/PMINSQ-Minimum of Packed Signed Integers
Vol. 2B
4-339
Intel C/C++ Compiler Intrinsic Equivalent
VPMINSD __m512i _mm512_min_epi32( __m512i a, __m512i b);
VPMINSD __m512i _mm512_mask_min_epi32(__m512i s, __mmask16 k, __m512i a, __m512i b);
VPMINSD __m512i _mm512_maskz_min_epi32( __mmask16 k, __m512i a, __m512i b);
VPMINSQ __m512i _mm512_min_epi64( __m512i a, __m512i b);
VPMINSQ __m512i _mm512_mask_min_epi64(__m512i s, __mmask8 k, __m512i a, __m512i b);
VPMINSQ __m512i _mm512_maskz_min_epi64( __mmask8 k, __m512i a, __m512i b);
VPMINSD __m256i _mm256_mask_min_epi32(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMINSD __m256i _mm256_maskz_min_epi32( __mmask16 k, __m256i a, __m256i b);
VPMINSQ __m256i _mm256_mask_min_epi64(__m256i s, __mmask8 k, __m256i a, __m256i b);
VPMINSQ __m256i _mm256_maskz_min_epi64( __mmask8 k, __m256i a, __m256i b);
VPMINSD __m128i _mm_mask_min_epi32(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMINSD __m128i _mm_maskz_min_epi32( __mmask8 k, __m128i a, __m128i b);
VPMINSQ __m128i _mm_mask_min_epi64(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMINSQ __m128i _mm_maskz_min_epu64( __mmask8 k, __m128i a, __m128i b);
(V)PMINSD __m128i _mm_min_epi32 ( __m128i a, __m128i b);
VPMINSD __m256i _mm256_min_epi32 (__m256i a, __m256i b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
PMINSD/PMINSQ-Minimum of Packed Signed Integers
Vol. 2B
4-340

PMINUB/PMINUW-Minimum of Packed Unsigned Integers
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
NP 0F DA /r1
A
V/V
SSE
Compare unsigned byte integers in mm2/m64 and
mm1 and returns minimum values.
PMINUB mm1, mm2/m64
66 0F DA /r
A
V/V
SSE2
Compare packed unsigned byte integers in xmm1
PMINUB xmm1, xmm2/m128
and xmm2/m128 and store packed minimum values
in xmm1.
66 0F 38 3A/r
A
V/V
SSE4_1
Compare packed unsigned word integers in
PMINUW xmm1, xmm2/m128
xmm2/m128 and xmm1 and store packed minimum
values in xmm1.
VEX.128.66.0F DA /r
B
V/V
AVX
Compare packed unsigned byte integers in xmm2
VPMINUB xmm1, xmm2, xmm3/m128
and xmm3/m128 and store packed minimum values
in xmm1.
VEX.128.66.0F38 3A/r
B
V/V
AVX
Compare packed unsigned word integers in
VPMINUW xmm1, xmm2, xmm3/m128
xmm3/m128 and xmm2 and return packed
minimum values in xmm1.
VEX.256.66.0F DA /r
B
V/V
AVX2
Compare packed unsigned byte integers in ymm2
VPMINUB ymm1, ymm2, ymm3/m256
and ymm3/m256 and store packed minimum values
in ymm1.
VEX.256.66.0F38 3A/r
B
V/V
AVX2
Compare packed unsigned word integers in
VPMINUW ymm1, ymm2, ymm3/m256
ymm3/m256 and ymm2 and return packed
minimum values in ymm1.
EVEX.128.66.0F DA /r
C
V/V
(AVX512VL AND
Compare packed unsigned byte integers in xmm2
VPMINUB xmm1 {k1}{z}, xmm2,
AVX512BW) OR
and xmm3/m128 and store packed minimum values
xmm3/m128
AVX10.1
in xmm1 under writemask k1.
EVEX.256.66.0F DA /r
C
V/V
(AVX512VL AND
Compare packed unsigned byte integers in ymm2
VPMINUB ymm1 {k1}{z}, ymm2,
AVX512BW) OR
and ymm3/m256 and store packed minimum values
ymm3/m256
AVX10.1
in ymm1 under writemask k1.
EVEX.512.66.0F DA /r
C
V/V
AVX512BW
Compare packed unsigned byte integers in zmm2
VPMINUB zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512 and store packed minimum values
zmm3/m512
in zmm1 under writemask k1.
EVEX.128.66.0F38 3A/r
C
V/V
(AVX512VL AND
Compare packed unsigned word integers in
VPMINUW xmm1{k1}{z}, xmm2,
AVX512BW) OR
xmm3/m128 and xmm2 and return packed
xmm3/m128
AVX10.1
minimum values in xmm1 under writemask k1.
EVEX.256.66.0F38 3A/r
C
V/V
(AVX512VL AND
Compare packed unsigned word integers in
VPMINUW ymm1{k1}{z}, ymm2,
AVX512BW) OR
ymm3/m256 and ymm2 and return packed
ymm3/m256
AVX10.1
minimum values in ymm1 under writemask k1.
EVEX.512.66.0F38 3A/r
C
V/V
AVX512BW
Compare packed unsigned word integers in
VPMINUW zmm1{k1}{z}, zmm2,
OR AVX10.1
zmm3/m512 and zmm2 and return packed
zmm3/m512
minimum values in zmm1 under writemask k1.
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX
Registers,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
PMINUB/PMINUW-Minimum of Packed Unsigned Integers
Vol. 2B
4-341

Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed unsigned byte or word integers in the second source operand and the first
source operand and returns the minimum value for each pair of integers to the destination operand.
Legacy SSE version PMINUB: The source operand can be an MMX technology register or a 64-bit memory location.
The destination operand can be an MMX technology register.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers.
EVEX encoded versions: The first source operand is a ZMM/YMM/XMM register; The second source operand is a
ZMM/YMM/XMM register or a 512/256/128-bit memory location. The destination operand is conditionally updated
based on writemask k1.
Operation
PMINUB (64-bit Operands)
IF DEST[7:0] < SRC[17:0] THEN
DEST[7:0] := DEST[7:0];
ELSE
DEST[7:0] := SRC[7:0]; FI;
(* Repeat operation for 2nd through 7th bytes in source and destination operands *)
IF DEST[63:56] < SRC[63:56] THEN
DEST[63:56] := DEST[63:56];
ELSE
DEST[63:56] := SRC[63:56]; FI;
PMINUB (128-bit Operands)
IF DEST[7:0] < SRC[7:0] THEN
DEST[7:0] := DEST[7:0];
ELSE
DEST[15:0] := SRC[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF DEST[127:120] < SRC[127:120] THEN
DEST[127:120] := DEST[127:120];
ELSE
DEST[127:120] := SRC[127:120]; FI;
DEST[MAXVL-1:128] (Unmodified)
PMINUB/PMINUW-Minimum of Packed Unsigned Integers
Vol. 2B
4-342
VPMINUB (VEX.128 Encoded Version)
IF SRC1[7:0] < SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[7:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 15th bytes in source and destination operands *)
IF SRC1[127:120] < SRC2[127:120] THEN
DEST[127:120] := SRC1[127:120];
ELSE
DEST[127:120] := SRC2[127:120]; FI;
DEST[MAXVL-1:128] := 0
VPMINUB (VEX.256 Encoded Version)
IF SRC1[7:0] < SRC2[7:0] THEN
DEST[7:0] := SRC1[7:0];
ELSE
DEST[15:0] := SRC2[7:0]; FI;
(* Repeat operation for 2nd through 31st bytes in source and destination operands *)
IF SRC1[255:248] < SRC2[255:248] THEN
DEST[255:248] := SRC1[255:248];
ELSE
DEST[255:248] := SRC2[255:248]; FI;
DEST[MAXVL-1:256] := 0
VPMINUB (EVEX Encoded Versions)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask* THEN
IF SRC1[i+7:i] < SRC2[i+7:i]
THEN DEST[i+7:i] := SRC1[i+7:i];
ELSE DEST[i+7:i] := SRC2[i+7:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+7:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMINUW (128-bit Operands)
IF DEST[15:0] < SRC[15:0] THEN
DEST[15:0] := DEST[15:0];
ELSE
DEST[15:0] := SRC[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:112] < SRC[127:112] THEN
DEST[127:112] := DEST[127:112];
ELSE
DEST[127:112] := SRC[127:112]; FI;
DEST[MAXVL-1:128] (Unmodified)
PMINUB/PMINUW-Minimum of Packed Unsigned Integers
Vol. 2B
4-343
VPMINUW (VEX.128 Encoded Version)
IF SRC1[15:0] < SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF SRC1[127:112] < SRC2[127:112] THEN
DEST[127:112] := SRC1[127:112];
ELSE
DEST[127:112] := SRC2[127:112]; FI;
DEST[MAXVL-1:128] := 0
VPMINUW (VEX.256 Encoded Version)
IF SRC1[15:0] < SRC2[15:0] THEN
DEST[15:0] := SRC1[15:0];
ELSE
DEST[15:0] := SRC2[15:0]; FI;
(* Repeat operation for 2nd through 15th words in source and destination operands *)
IF SRC1[255:240] < SRC2[255:240] THEN
DEST[255:240] := SRC1[255:240];
ELSE
DEST[255:240] := SRC2[255:240]; FI;
DEST[MAXVL-1:256] := 0
VPMINUW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask* THEN
IF SRC1[i+15:i] < SRC2[i+15:i]
THEN DEST[i+15:i] := SRC1[i+15:i];
ELSE DEST[i+15:i] := SRC2[i+15:i];
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMINUB/PMINUW-Minimum of Packed Unsigned Integers
Vol. 2B
4-344
Intel C/C++ Compiler Intrinsic Equivalent
VPMINUB __m512i _mm512_min_epu8( __m512i a, __m512i b);
VPMINUB __m512i _mm512_mask_min_epu8(__m512i s, __mmask64 k, __m512i a, __m512i b);
VPMINUB __m512i _mm512_maskz_min_epu8( __mmask64 k, __m512i a, __m512i b);
VPMINUW __m512i _mm512_min_epu16( __m512i a, __m512i b);
VPMINUW __m512i _mm512_mask_min_epu16(__m512i s, __mmask32 k, __m512i a, __m512i b);
VPMINUW __m512i _mm512_maskz_min_epu16( __mmask32 k, __m512i a, __m512i b);
VPMINUB __m256i _mm256_mask_min_epu8(__m256i s, __mmask32 k, __m256i a, __m256i b);
VPMINUB __m256i _mm256_maskz_min_epu8( __mmask32 k, __m256i a, __m256i b);
VPMINUW __m256i _mm256_mask_min_epu16(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMINUW __m256i _mm256_maskz_min_epu16( __mmask16 k, __m256i a, __m256i b);
VPMINUB __m128i _mm_mask_min_epu8(__m128i s, __mmask16 k, __m128i a, __m128i b);
VPMINUB __m128i _mm_maskz_min_epu8( __mmask16 k, __m128i a, __m128i b);
VPMINUW __m128i _mm_mask_min_epu16(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMINUW __m128i _mm_maskz_min_epu16( __mmask8 k, __m128i a, __m128i b);
(V)PMINUB __m128i _mm_min_epu8 ( __m128i a, __m128i b)
(V)PMINUW __m128i _mm_min_epu16 ( __m128i a, __m128i b);
VPMINUB __m256i _mm256_min_epu8 ( __m256i a, __m256i b)
VPMINUW __m256i _mm256_min_epu16 ( __m256i a, __m256i b);
PMINUB __m64 _m_min_pu8 (__m64 a, __m64 b)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
PMINUB/PMINUW-Minimum of Packed Unsigned Integers
Vol. 2B
4-345

PMINUD/PMINUQ-Minimum of Packed Unsigned Integers
Opcode/
Op/E
64/32 bit
CPUID Feature
Description
Instruction
n
Mode
Flag
Support
66 0F 38 3B /r
A
V/V
SSE4_1
Compare packed unsigned dword integers in xmm1
PMINUD xmm1, xmm2/m128
and xmm2/m128 and store packed minimum values in
xmm1.
VEX.128.66.0F38.WIG 3B /r
B
V/V
AVX
Compare packed unsigned dword integers in xmm2
VPMINUD xmm1, xmm2,
and xmm3/m128 and store packed minimum values in
xmm3/m128
xmm1.
VEX.256.66.0F38.WIG 3B /r
B
V/V
AVX2
Compare packed unsigned dword integers in ymm2
VPMINUD ymm1, ymm2,
and ymm3/m256 and store packed minimum values in
ymm3/m256
ymm1.
EVEX.128.66.0F38.W0 3B /r
C
V/V
(AVX512VL AND
Compare packed unsigned dword integers in xmm2
VPMINUD xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128/m32bcst and store packed minimum
xmm3/m128/m32bcst
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F38.W0 3B /r
C
V/V
(AVX512VL AND
Compare packed unsigned dword integers in ymm2
VPMINUD ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256/m32bcst and store packed minimum
ymm3/m256/m32bcst
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F38.W0 3B /r
C
V/V
AVX512F
Compare packed unsigned dword integers in zmm2
VPMINUD zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m32bcst and store packed minimum
zmm3/m512/m32bcst
values in zmm1 under writemask k1.
EVEX.128.66.0F38.W1 3B /r
C
V/V
(AVX512VL AND
Compare packed unsigned qword integers in xmm2
VPMINUQ xmm1 {k1}{z}, xmm2,
AVX512F) OR
and xmm3/m128/m64bcst and store packed minimum
xmm3/m128/m64bcst
AVX10.1
values in xmm1 under writemask k1.
EVEX.256.66.0F38.W1 3B /r
C
V/V
(AVX512VL AND
Compare packed unsigned qword integers in ymm2
VPMINUQ ymm1 {k1}{z}, ymm2,
AVX512F) OR
and ymm3/m256/m64bcst and store packed minimum
ymm3/m256/m64bcst
AVX10.1
values in ymm1 under writemask k1.
EVEX.512.66.0F38.W1 3B /r
C
V/V
AVX512F
Compare packed unsigned qword integers in zmm2
VPMINUQ zmm1 {k1}{z}, zmm2,
OR AVX10.1
and zmm3/m512/m64bcst and store packed minimum
zmm3/m512/m64bcst
values in zmm1 under writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Performs a SIMD compare of the packed unsigned dword/qword integers in the second source operand and the first
source operand and returns the minimum value for each pair of integers to the destination operand.
128-bit Legacy SSE version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register remain unchanged.
VEX.128 encoded version: The first source and destination operands are XMM registers. The second source
operand is an XMM register or a 128-bit memory location. Bits (MAXVL-1:128) of the corresponding destination
register are zeroed.
VEX.256 encoded version: The second source operand can be an YMM register or a 256-bit memory location. The
first source and destination operands are YMM registers. Bits (MAXVL-1:256) of the corresponding destination
register are zeroed.
PMINUD/PMINUQ-Minimum of Packed Unsigned Integers
Vol. 2B
4-346
EVEX encoded versions: The first source operand is a ZMM/YMM/XMM register; The second source operand is a
ZMM/YMM/XMM register, a 512/256/128-bit memory location or a 512/256/128-bit vector broadcasted from a
32/64-bit memory location. The destination operand is conditionally updated based on writemask k1.
Operation
PMINUD (128-bit Legacy SSE Version)
PMINUD instruction for 128-bit operands:
IF DEST[31:0] < SRC[31:0] THEN
DEST[31:0] := DEST[31:0];
ELSE
DEST[31:0] := SRC[31:0]; FI;
(* Repeat operation for 2nd through 7th words in source and destination operands *)
IF DEST[127:96] < SRC[127:96] THEN
DEST[127:96] := DEST[127:96];
ELSE
DEST[127:96] := SRC[127:96]; FI;
DEST[MAXVL-1:128] (Unmodified)
VPMINUD (VEX.128 Encoded Version)
VPMINUD instruction for 128-bit operands:
IF SRC1[31:0] < SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 3rd dwords in source and destination operands *)
IF SRC1[127:96] < SRC2[127:96] THEN
DEST[127:96] := SRC1[127:96];
ELSE
DEST[127:96] := SRC2[127:96]; FI;
DEST[MAXVL-1:128] := 0
VPMINUD (VEX.256 Encoded Version)
VPMINUD instruction for 128-bit operands:
IF SRC1[31:0] < SRC2[31:0] THEN
DEST[31:0] := SRC1[31:0];
ELSE
DEST[31:0] := SRC2[31:0]; FI;
(* Repeat operation for 2nd through 7th dwords in source and destination operands *)
IF SRC1[255:224] < SRC2[255:224] THEN
DEST[255:224] := SRC1[255:224];
ELSE
DEST[255:224] := SRC2[255:224]; FI;
DEST[MAXVL-1:256] := 0
PMINUD/PMINUQ-Minimum of Packed Unsigned Integers
Vol. 2B
4-347
VPMINUD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+31:i] < SRC2[31:0]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[31:0];
FI;
ELSE
IF SRC1[i+31:i] < SRC2[i+31:i]
THEN DEST[i+31:i] := SRC1[i+31:i];
ELSE DEST[i+31:i] := SRC2[i+31:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
VPMINUQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask* THEN
IF (EVEX.b = 1) AND (SRC2 *is memory*)
THEN
IF SRC1[i+63:i] < SRC2[63:0]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[63:0];
FI;
ELSE
IF SRC1[i+63:i] < SRC2[i+63:i]
THEN DEST[i+63:i] := SRC1[i+63:i];
ELSE DEST[i+63:i] := SRC2[i+63:i];
FI;
FI;
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR;
DEST[MAXVL-1:VL] := 0
PMINUD/PMINUQ-Minimum of Packed Unsigned Integers
Vol. 2B
4-348
Intel C/C++ Compiler Intrinsic Equivalent
VPMINUD __m512i _mm512_min_epu32( __m512i a, __m512i b);
VPMINUD __m512i _mm512_mask_min_epu32(__m512i s, __mmask16 k, __m512i a, __m512i b);
VPMINUD __m512i _mm512_maskz_min_epu32( __mmask16 k, __m512i a, __m512i b);
VPMINUQ __m512i _mm512_min_epu64( __m512i a, __m512i b);
VPMINUQ __m512i _mm512_mask_min_epu64(__m512i s, __mmask8 k, __m512i a, __m512i b);
VPMINUQ __m512i _mm512_maskz_min_epu64( __mmask8 k, __m512i a, __m512i b);
VPMINUD __m256i _mm256_mask_min_epu32(__m256i s, __mmask16 k, __m256i a, __m256i b);
VPMINUD __m256i _mm256_maskz_min_epu32( __mmask16 k, __m256i a, __m256i b);
VPMINUQ __m256i _mm256_mask_min_epu64(__m256i s, __mmask8 k, __m256i a, __m256i b);
VPMINUQ __m256i _mm256_maskz_min_epu64( __mmask8 k, __m256i a, __m256i b);
VPMINUD __m128i _mm_mask_min_epu32(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMINUD __m128i _mm_maskz_min_epu32( __mmask8 k, __m128i a, __m128i b);
VPMINUQ __m128i _mm_mask_min_epu64(__m128i s, __mmask8 k, __m128i a, __m128i b);
VPMINUQ __m128i _mm_maskz_min_epu64( __mmask8 k, __m128i a, __m128i b);
(V)PMINUD __m128i _mm_min_epu32 ( __m128i a, __m128i b);
VPMINUD __m256i _mm256_min_epu32 ( __m256i a, __m256i b);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-51, “Type E4 Class Exception Conditions.”
PMINUD/PMINUQ-Minimum of Packed Unsigned Integers
Vol. 2B
4-349

PMOVMSKB-Move Byte Mask
Opcode/
Op/
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
NP 0F D7 /r1
RM
V/V
SSE
Move a byte mask of mm to reg. The upper
bits of r32 or r64 are zeroed
PMOVMSKB reg, mm
66 0F D7 /r
RM
V/V
SSE2
Move a byte mask of xmm to reg. The upper
bits of r32 or r64 are zeroed
PMOVMSKB reg, xmm
VEX.128.66.0F.WIG D7 /r
RM
V/V
AVX
Move a byte mask of xmm1 to reg. The upper
bits of r32 or r64 are filled with zeros.
VPMOVMSKB reg, xmm1
VEX.256.66.0F.WIG D7 /r
RM
V/V
AVX2
Move a 32-bit mask of ymm1 to reg. The
upper bits of r64 are filled with zeros.
VPMOVMSKB reg, ymm1
NOTES:
1. See note in Section 2.5, “Intel® AVX and Intel® SSE Instruction Exception Classification,” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A, and Section 25.25.3, “Exception Conditions of Legacy SIMD Instructions Operating on MMX
Registers,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3B.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Creates a mask made up of the most significant bit of each byte of the source operand (second operand) and stores
the result in the low byte or word of the destination operand (first operand).
The byte mask is 8 bits for 64-bit source operand, 16 bits for 128-bit source operand and 32 bits for 256-bit source
operand. The destination operand is a general-purpose register.
In 64-bit mode, the instruction can access additional registers (XMM8-XMM15, R8-R15) when used with a REX.R
prefix. The default operand size is 64-bit in 64-bit mode.
Legacy SSE version: The source operand is an MMX technology register.
128-bit Legacy SSE version: The source operand is an XMM register.
VEX.128 encoded version: The source operand is an XMM register.
VEX.256 encoded version: The source operand is a YMM register.
Note: VEX.vvvv is reserved and must be 1111b.
Operation
PMOVMSKB (With 64-bit Source Operand and r32)
r32[0] := SRC[7];
r32[1] := SRC[15];
(* Repeat operation for bytes 2 through 6 *)
r32[7] := SRC[63];
r32[31:8] := ZERO_FILL;
PMOVMSKB-Move Byte Mask
Vol. 2B
4-350
(V)PMOVMSKB (With 128-bit Source Operand and r32)
r32[0] := SRC[7];
r32[1] := SRC[15];
(* Repeat operation for bytes 2 through 14 *)
r32[15] := SRC[127];
r32[31:16] := ZERO_FILL;
VPMOVMSKB (With 256-bit Source Operand and r32)
r32[0] := SRC[7];
r32[1] := SRC[15];
(* Repeat operation for bytes 3rd through 31*)
r32[31] := SRC[255];
PMOVMSKB (With 64-bit Source Operand and r64)
r64[0] := SRC[7];
r64[1] := SRC[15];
(* Repeat operation for bytes 2 through 6 *)
r64[7] := SRC[63];
r64[63:8] := ZERO_FILL;
(V)PMOVMSKB (With 128-bit Source Operand and r64)
r64[0] := SRC[7];
r64[1] := SRC[15];
(* Repeat operation for bytes 2 through 14 *)
r64[15] := SRC[127];
r64[63:16] := ZERO_FILL;
VPMOVMSKB (With 256-bit Source Operand and r64)
r64[0] := SRC[7];
r64[1] := SRC[15];
(* Repeat operation for bytes 2 through 31*)
r64[31] := SRC[255];
r64[63:32] := ZERO_FILL;
Intel C/C++ Compiler Intrinsic Equivalent
PMOVMSKB int _mm_movemask_pi8(__m64 a)
(V)PMOVMSKB int _mm_movemask_epi8 ( __m128i a)
VPMOVMSKB int _mm256_movemask_epi8 ( __m256i a)
Flags Affected
None.
Numeric Exceptions
None.
Other Exceptions
See Table 2-24, “Type 7 Class Exception Conditions,” additionally:
#UD
If VEX.vvvv ≠ 1111B.
PMOVMSKB-Move Byte Mask
Vol. 2B
4-351

PMOVSX-Packed Move With Sign Extend
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0f 38 20 /r
A
V/V
SSE4_1
Sign extend 8 packed 8-bit integers in the low 8 bytes
PMOVSXBW xmm1, xmm2/m64
of xmm2/m64 to 8 packed 16-bit integers in xmm1.
66 0f 38 21 /r
A
V/V
SSE4_1
Sign extend 4 packed 8-bit integers in the low 4 bytes
PMOVSXBD xmm1, xmm2/m32
of xmm2/m32 to 4 packed 32-bit integers in xmm1.
66 0f 38 22 /r
A
V/V
SSE4_1
Sign extend 2 packed 8-bit integers in the low 2 bytes
PMOVSXBQ xmm1, xmm2/m16
of xmm2/m16 to 2 packed 64-bit integers in xmm1.
66 0f 38 23/r
A
V/V
SSE4_1
Sign extend 4 packed 16-bit integers in the low 8
PMOVSXWD xmm1, xmm2/m64
bytes of xmm2/m64 to 4 packed 32-bit integers in
xmm1.
66 0f 38 24 /r
A
V/V
SSE4_1
Sign extend 2 packed 16-bit integers in the low 4
PMOVSXWQ xmm1, xmm2/m32
bytes of xmm2/m32 to 2 packed 64-bit integers in
xmm1.
66 0f 38 25 /r
A
V/V
SSE4_1
Sign extend 2 packed 32-bit integers in the low 8
PMOVSXDQ xmm1, xmm2/m64
bytes of xmm2/m64 to 2 packed 64-bit integers in
xmm1.
VEX.128.66.0F38.WIG 20 /r
A
V/V
AVX
Sign extend 8 packed 8-bit integers in the low 8 bytes
VPMOVSXBW xmm1, xmm2/m64
of xmm2/m64 to 8 packed 16-bit integers in xmm1.
VEX.128.66.0F38.WIG 21 /r
A
V/V
AVX
Sign extend 4 packed 8-bit integers in the low 4 bytes
VPMOVSXBD xmm1, xmm2/m32
of xmm2/m32 to 4 packed 32-bit integers in xmm1.
VEX.128.66.0F38.WIG 22 /r
A
V/V
AVX
Sign extend 2 packed 8-bit integers in the low 2 bytes
VPMOVSXBQ xmm1, xmm2/m16
of xmm2/m16 to 2 packed 64-bit integers in xmm1.
VEX.128.66.0F38.WIG 23 /r
A
V/V
AVX
Sign extend 4 packed 16-bit integers in the low 8
VPMOVSXWD xmm1, xmm2/m64
bytes of xmm2/m64 to 4 packed 32-bit integers in
xmm1.
VEX.128.66.0F38.WIG 24 /r
A
V/V
AVX
Sign extend 2 packed 16-bit integers in the low 4
VPMOVSXWQ xmm1, xmm2/m32
bytes of xmm2/m32 to 2 packed 64-bit integers in
xmm1.
VEX.128.66.0F38.WIG 25 /r
A
V/V
AVX
Sign extend 2 packed 32-bit integers in the low 8
VPMOVSXDQ xmm1, xmm2/m64
bytes of xmm2/m64 to 2 packed 64-bit integers in
xmm1.
VEX.256.66.0F38.WIG 20 /r
A
V/V
AVX2
Sign extend 16 packed 8-bit integers in xmm2/m128
VPMOVSXBW ymm1, xmm2/m128
to 16 packed 16-bit integers in ymm1.
VEX.256.66.0F38.WIG 21 /r
A
V/V
AVX2
Sign extend 8 packed 8-bit integers in the low 8 bytes
VPMOVSXBD ymm1, xmm2/m64
of xmm2/m64 to 8 packed 32-bit integers in ymm1.
VEX.256.66.0F38.WIG 22 /r
A
V/V
AVX2
Sign extend 4 packed 8-bit integers in the low 4 bytes
VPMOVSXBQ ymm1, xmm2/m32
of xmm2/m32 to 4 packed 64-bit integers in ymm1.
VEX.256.66.0F38.WIG 23 /r
A
V/V
AVX2
Sign extend 8 packed 16-bit integers in xmm2/m128
VPMOVSXWD ymm1, xmm2/m128
to 8 packed 32-bit integers in ymm1.
VEX.256.66.0F38.WIG 24 /r
A
V/V
AVX2
Sign extend 4 packed 16-bit integers in the low 8
VPMOVSXWQ ymm1, xmm2/m64
bytes of xmm2/m64 to 4 packed 64-bit integers in
ymm1.
VEX.256.66.0F38.WIG 25 /r
A
V/V
AVX2
Sign extend 4 packed 32-bit integers in xmm2/m128
VPMOVSXDQ ymm1, xmm2/m128
to 4 packed 64-bit integers in ymm1.
EVEX.128.66.0F38.WIG 20 /r
B
V/V
(AVX512VL AND
Sign extend 8 packed 8-bit integers in the low 8 bytes
VPMOVSXBW xmm1 {k1}{z},
AVX512BW) OR
of xmm2/m64 to 8 packed 16-bit integers in xmm1
xmm2/m64
AVX10.1
subject to writemask k1.
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-352

Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
EVEX.256.66.0F38.WIG 20 /r
B
V/V
(AVX512VL AND
Sign extend 16 packed 8-bit integers in xmm2/m128
VPMOVSXBW ymm1 {k1}{z},
AVX512BW) OR
to 16 packed 16-bit integers in ymm1 subject to
xmm2/m128
AVX10.1
writemask k1.
EVEX.512.66.0F38.WIG 20 /r
B
V/V
AVX512BW
Sign extend 32 packed 8-bit integers in ymm2/m256
VPMOVSXBW zmm1 {k1}{z},
OR AVX10.1
to 32 packed 16-bit integers in zmm1 subject to
ymm2/m256
writemask k1.
EVEX.128.66.0F38.WIG 21 /r
C
V/V
(AVX512VL AND
Sign extend 4 packed 8-bit integers in the low 4 bytes
VPMOVSXBD xmm1 {k1}{z},
AVX512F) OR
of xmm2/m32 to 4 packed 32-bit integers in xmm1
xmm2/m32
AVX10.1
subject to writemask k1.
EVEX.256.66.0F38.WIG 21 /r
C
V/V
(AVX512VL AND
Sign extend 8 packed 8-bit integers in the low 8 bytes
VPMOVSXBD ymm1 {k1}{z},
AVX512F) OR
of xmm2/m64 to 8 packed 32-bit integers in ymm1
xmm2/m64
AVX10.1
subject to writemask k1.
EVEX.512.66.0F38.WIG 21 /r
C
V/V
AVX512F
Sign extend 16 packed 8-bit integers in xmm2/m128
VPMOVSXBD zmm1 {k1}{z},
OR AVX10.1
to 16 packed 32-bit integers in zmm1 subject to
xmm2/m128
writemask k1.
EVEX.128.66.0F38.WIG 22 /r
D
V/V
(AVX512VL AND
Sign extend 2 packed 8-bit integers in the low 2 bytes
VPMOVSXBQ xmm1 {k1}{z},
AVX512F) OR
of xmm2/m16 to 2 packed 64-bit integers in xmm1
xmm2/m16
AVX10.1
subject to writemask k1.
EVEX.256.66.0F38.WIG 22 /r
D
V/V
(AVX512VL AND
Sign extend 4 packed 8-bit integers in the low 4 bytes
VPMOVSXBQ ymm1 {k1}{z},
AVX512F) OR
of xmm2/m32 to 4 packed 64-bit integers in ymm1
xmm2/m32
AVX10.1
subject to writemask k1.
EVEX.512.66.0F38.WIG 22 /r
D
V/V
AVX512F
Sign extend 8 packed 8-bit integers in the low 8 bytes
VPMOVSXBQ zmm1 {k1}{z},
OR AVX10.1
of xmm2/m64 to 8 packed 64-bit integers in zmm1
xmm2/m64
subject to writemask k1.
EVEX.128.66.0F38.WIG 23 /r
B
V/V
(AVX512VL AND
Sign extend 4 packed 16-bit integers in the low 8
VPMOVSXWD xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 4 packed 32-bit integers in
xmm2/m64
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 23 /r
B
V/V
(AVX512VL AND
Sign extend 8 packed 16-bit integers in xmm2/m128
VPMOVSXWD ymm1 {k1}{z},
AVX512F) OR
to 8 packed 32-bit integers in ymm1 subject to
xmm2/m128
AVX10.1
writemask k1.
EVEX.512.66.0F38.WIG 23 /r
B
V/V
AVX512F
Sign extend 16 packed 16-bit integers in ymm2/m256
VPMOVSXWD zmm1 {k1}{z},
OR AVX10.1
to 16 packed 32-bit integers in zmm1 subject to
ymm2/m256
writemask k1.
EVEX.128.66.0F38.WIG 24 /r
C
V/V
(AVX512VL AND
Sign extend 2 packed 16-bit integers in the low 4
VPMOVSXWQ xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m32 to 2 packed 64-bit integers in
xmm2/m32
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 24 /r
C
V/V
(AVX512VL AND
Sign extend 4 packed 16-bit integers in the low 8
VPMOVSXWQ ymm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 4 packed 64-bit integers in
xmm2/m64
AVX10.1
ymm1 subject to writemask k1.
EVEX.512.66.0F38.WIG 24 /r
C
V/V
AVX512F
Sign extend 8 packed 16-bit integers in xmm2/m128
VPMOVSXWQ zmm1 {k1}{z},
OR AVX10.1
to 8 packed 64-bit integers in zmm1 subject to
xmm2/m128
writemask k1.
EVEX.128.66.0F38.W0 25 /r
B
V/V
(AVX512VL AND
Sign extend 2 packed 32-bit integers in the low 8
VPMOVSXDQ xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 2 packed 64-bit integers in
xmm2/m64
AVX10.1
xmm1 using writemask k1.
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-353
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
EVEX.256.66.0F38.W0 25 /r
B
V/V
(AVX512VL AND
Sign extend 4 packed 32-bit integers in xmm2/m128
VPMOVSXDQ ymm1 {k1}{z},
AVX512F) OR
to 4 packed 64-bit integers in ymm1 using writemask
xmm2/m128
AVX10.1
k1.
EVEX.512.66.0F38.W0 25 /r
B
V/V
AVX512F
Sign extend 8 packed 32-bit integers in ymm2/m256
VPMOVSXDQ zmm1 {k1}{z},
OR AVX10.1
to 8 packed 64-bit integers in zmm1 using writemask
ymm2/m256
k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
Half Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
C
Quarter Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Eighth Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Legacy and VEX encoded versions: Packed byte, word, or dword integers in the low bytes of the source operand
(second operand) are sign extended to word, dword, or quadword integers and stored in packed signed bytes the
destination operand.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding destination register remain unchanged.
VEX.128 and EVEX.128 encoded versions: Bits (MAXVL-1:128) of the corresponding destination register are
zeroed.
VEX.256 and EVEX.256 encoded versions: Bits (MAXVL-1:256) of the corresponding destination register are
zeroed.
EVEX encoded versions: Packed byte, word or dword integers starting from the low bytes of the source operand
(second operand) are sign extended to word, dword or quadword integers and stored to the destination operand
under the writemask. The destination register is XMM, YMM or ZMM Register.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
Operation
Packed_Sign_Extend_BYTE_to_WORD(DEST, SRC)
DEST[15:0] := SignExtend(SRC[7:0]);
DEST[31:16] := SignExtend(SRC[15:8]);
DEST[47:32] := SignExtend(SRC[23:16]);
DEST[63:48] := SignExtend(SRC[31:24]);
DEST[79:64] := SignExtend(SRC[39:32]);
DEST[95:80] := SignExtend(SRC[47:40]);
DEST[111:96] := SignExtend(SRC[55:48]);
DEST[127:112] := SignExtend(SRC[63:56]);
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-354
Packed_Sign_Extend_BYTE_to_DWORD(DEST, SRC)
DEST[31:0] := SignExtend(SRC[7:0]);
DEST[63:32] := SignExtend(SRC[15:8]);
DEST[95:64] := SignExtend(SRC[23:16]);
DEST[127:96] := SignExtend(SRC[31:24]);
Packed_Sign_Extend_BYTE_to_QWORD(DEST, SRC)
DEST[63:0] := SignExtend(SRC[7:0]);
DEST[127:64] := SignExtend(SRC[15:8]);
Packed_Sign_Extend_WORD_to_DWORD(DEST, SRC)
DEST[31:0] := SignExtend(SRC[15:0]);
DEST[63:32] := SignExtend(SRC[31:16]);
DEST[95:64] := SignExtend(SRC[47:32]);
DEST[127:96] := SignExtend(SRC[63:48]);
Packed_Sign_Extend_WORD_to_QWORD(DEST, SRC)
DEST[63:0] := SignExtend(SRC[15:0]);
DEST[127:64] := SignExtend(SRC[31:16]);
Packed_Sign_Extend_DWORD_to_QWORD(DEST, SRC)
DEST[63:0] := SignExtend(SRC[31:0]);
DEST[127:64] := SignExtend(SRC[63:32]);
VPMOVSXBW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
Packed_Sign_Extend_BYTE_to_WORD(TMP_DEST[127:0], SRC[63:0])
IF VL >= 256
Packed_Sign_Extend_BYTE_to_WORD(TMP_DEST[255:128], SRC[127:64])
FI;
IF VL >= 512
Packed_Sign_Extend_BYTE_to_WORD(TMP_DEST[383:256], SRC[191:128])
Packed_Sign_Extend_BYTE_to_WORD(TMP_DEST[511:384], SRC[255:192])
FI;
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := TEMP_DEST[i+15:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-355
VPMOVSXBD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
Packed_Sign_Extend_BYTE_to_DWORD(TMP_DEST[127:0], SRC[31:0])
IF VL >= 256
Packed_Sign_Extend_BYTE_to_DWORD(TMP_DEST[255:128], SRC[63:32])
FI;
IF VL >= 512
Packed_Sign_Extend_BYTE_to_DWORD(TMP_DEST[383:256], SRC[95:64])
Packed_Sign_Extend_BYTE_to_DWORD(TMP_DEST[511:384], SRC[127:96])
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := TEMP_DEST[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMOVSXBQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
Packed_Sign_Extend_BYTE_to_QWORD(TMP_DEST[127:0], SRC[15:0])
IF VL >= 256
Packed_Sign_Extend_BYTE_to_QWORD(TMP_DEST[255:128], SRC[31:16])
FI;
IF VL >= 512
Packed_Sign_Extend_BYTE_to_QWORD(TMP_DEST[383:256], SRC[47:32])
Packed_Sign_Extend_BYTE_to_QWORD(TMP_DEST[511:384], SRC[63:48])
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TEMP_DEST[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-356
VPMOVSXWD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
Packed_Sign_Extend_WORD_to_DWORD(TMP_DEST[127:0], SRC[63:0])
IF VL >= 256
Packed_Sign_Extend_WORD_to_DWORD(TMP_DEST[255:128], SRC[127:64])
FI;
IF VL >= 512
Packed_Sign_Extend_WORD_to_DWORD(TMP_DEST[383:256], SRC[191:128])
Packed_Sign_Extend_WORD_to_DWORD(TMP_DEST[511:384], SRC[256:192])
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := TEMP_DEST[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMOVSXWQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
Packed_Sign_Extend_WORD_to_QWORD(TMP_DEST[127:0], SRC[31:0])
IF VL >= 256
Packed_Sign_Extend_WORD_to_QWORD(TMP_DEST[255:128], SRC[63:32])
FI;
IF VL >= 512
Packed_Sign_Extend_WORD_to_QWORD(TMP_DEST[383:256], SRC[95:64])
Packed_Sign_Extend_WORD_to_QWORD(TMP_DEST[511:384], SRC[127:96])
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TEMP_DEST[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-357
VPMOVSXDQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
Packed_Sign_Extend_DWORD_to_QWORD(TEMP_DEST[127:0], SRC[63:0])
IF VL >= 256
Packed_Sign_Extend_DWORD_to_QWORD(TEMP_DEST[255:128], SRC[127:64])
FI;
IF VL >= 512
Packed_Sign_Extend_DWORD_to_QWORD(TEMP_DEST[383:256], SRC[191:128])
Packed_Sign_Extend_DWORD_to_QWORD(TEMP_DEST[511:384], SRC[255:192])
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TEMP_DEST[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMOVSXBW (VEX.256 Encoded Version)
Packed_Sign_Extend_BYTE_to_WORD(DEST[127:0], SRC[63:0])
Packed_Sign_Extend_BYTE_to_WORD(DEST[255:128], SRC[127:64])
DEST[MAXVL-1:256] := 0
VPMOVSXBD (VEX.256 Encoded Version)
Packed_Sign_Extend_BYTE_to_DWORD(DEST[127:0], SRC[31:0])
Packed_Sign_Extend_BYTE_to_DWORD(DEST[255:128], SRC[63:32])
DEST[MAXVL-1:256] := 0
VPMOVSXBQ (VEX.256 Encoded Version)
Packed_Sign_Extend_BYTE_to_QWORD(DEST[127:0], SRC[15:0])
Packed_Sign_Extend_BYTE_to_QWORD(DEST[255:128], SRC[31:16])
DEST[MAXVL-1:256] := 0
VPMOVSXWD (VEX.256 Encoded Version)
Packed_Sign_Extend_WORD_to_DWORD(DEST[127:0], SRC[63:0])
Packed_Sign_Extend_WORD_to_DWORD(DEST[255:128], SRC[127:64])
DEST[MAXVL-1:256] := 0
VPMOVSXWQ (VEX.256 Encoded Version)
Packed_Sign_Extend_WORD_to_QWORD(DEST[127:0], SRC[31:0])
Packed_Sign_Extend_WORD_to_QWORD(DEST[255:128], SRC[63:32])
DEST[MAXVL-1:256] := 0
VPMOVSXDQ (VEX.256 Encoded Version)
Packed_Sign_Extend_DWORD_to_QWORD(DEST[127:0], SRC[63:0])
Packed_Sign_Extend_DWORD_to_QWORD(DEST[255:128], SRC[127:64])
DEST[MAXVL-1:256] := 0
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-358
VPMOVSXBW (VEX.128 Encoded Version)
Packed_Sign_Extend_BYTE_to_WORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] := 0
VPMOVSXBD (VEX.128 Encoded Version)
Packed_Sign_Extend_BYTE_to_DWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] := 0
VPMOVSXBQ (VEX.128 Encoded Version)
Packed_Sign_Extend_BYTE_to_QWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] := 0
VPMOVSXWD (VEX.128 Encoded Version)
Packed_Sign_Extend_WORD_to_DWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] := 0
VPMOVSXWQ (VEX.128 Encoded Version)
Packed_Sign_Extend_WORD_to_QWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] := 0
VPMOVSXDQ (VEX.128 Encoded Version)
Packed_Sign_Extend_DWORD_to_QWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] := 0
PMOVSXBW
Packed_Sign_Extend_BYTE_to_WORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] (Unmodified)
PMOVSXBD
Packed_Sign_Extend_BYTE_to_DWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] (Unmodified)
PMOVSXBQ
Packed_Sign_Extend_BYTE_to_QWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] (Unmodified)
PMOVSXWD
Packed_Sign_Extend_WORD_to_DWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] (Unmodified)
PMOVSXWQ
Packed_Sign_Extend_WORD_to_QWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] (Unmodified)
PMOVSXDQ
Packed_Sign_Extend_DWORD_to_QWORD(DEST[127:0], SRC[127:0])
DEST[MAXVL-1:128] (Unmodified)
Intel C/C++ Compiler Intrinsic Equivalent
VPMOVSXBW __m512i _mm512_cvtepi8_epi16(__m512i a);
VPMOVSXBW __m512i _mm512_mask_cvtepi8_epi16(__m512i a, __mmask32 k, __m512i b);
VPMOVSXBW __m512i _mm512_maskz_cvtepi8_epi16( __mmask32 k, __m512i b);
VPMOVSXBD __m512i _mm512_cvtepi8_epi32(__m512i a);
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-359
VPMOVSXBD __m512i _mm512_mask_cvtepi8_epi32(__m512i a, __mmask16 k, __m512i b);
VPMOVSXBD __m512i _mm512_maskz_cvtepi8_epi32( __mmask16 k, __m512i b);
VPMOVSXBQ __m512i _mm512_cvtepi8_epi64(__m512i a);
VPMOVSXBQ __m512i _mm512_mask_cvtepi8_epi64(__m512i a, __mmask8 k, __m512i b);
VPMOVSXBQ __m512i _mm512_maskz_cvtepi8_epi64( __mmask8 k, __m512i a);
VPMOVSXDQ __m512i _mm512_cvtepi32_epi64(__m512i a);
VPMOVSXDQ __m512i _mm512_mask_cvtepi32_epi64(__m512i a, __mmask8 k, __m512i b);
VPMOVSXDQ __m512i _mm512_maskz_cvtepi32_epi64( __mmask8 k, __m512i a);
VPMOVSXWD __m512i _mm512_cvtepi16_epi32(__m512i a);
VPMOVSXWD __m512i _mm512_mask_cvtepi16_epi32(__m512i a, __mmask16 k, __m512i b);
VPMOVSXWD __m512i _mm512_maskz_cvtepi16_epi32(__mmask16 k, __m512i a);
VPMOVSXWQ __m512i _mm512_cvtepi16_epi64(__m512i a);
VPMOVSXWQ __m512i _mm512_mask_cvtepi16_epi64(__m512i a, __mmask8 k, __m512i b);
VPMOVSXWQ __m512i _mm512_maskz_cvtepi16_epi64( __mmask8 k, __m512i a);
VPMOVSXBW __m256i _mm256_cvtepi8_epi16(__m256i a);
VPMOVSXBW __m256i _mm256_mask_cvtepi8_epi16(__m256i a, __mmask16 k, __m256i b);
VPMOVSXBW __m256i _mm256_maskz_cvtepi8_epi16( __mmask16 k, __m256i b);
VPMOVSXBD __m256i _mm256_cvtepi8_epi32(__m256i a);
VPMOVSXBD __m256i _mm256_mask_cvtepi8_epi32(__m256i a, __mmask8 k, __m256i b);
VPMOVSXBD __m256i _mm256_maskz_cvtepi8_epi32( __mmask8 k, __m256i b);
VPMOVSXBQ __m256i _mm256_cvtepi8_epi64(__m256i a);
VPMOVSXBQ __m256i _mm256_mask_cvtepi8_epi64(__m256i a, __mmask8 k, __m256i b);
VPMOVSXBQ __m256i _mm256_maskz_cvtepi8_epi64( __mmask8 k, __m256i a);
VPMOVSXDQ __m256i _mm256_cvtepi32_epi64(__m256i a);
VPMOVSXDQ __m256i _mm256_mask_cvtepi32_epi64(__m256i a, __mmask8 k, __m256i b);
VPMOVSXDQ __m256i _mm256_maskz_cvtepi32_epi64( __mmask8 k, __m256i a);
VPMOVSXWD __m256i _mm256_cvtepi16_epi32(__m256i a);
VPMOVSXWD __m256i _mm256_mask_cvtepi16_epi32(__m256i a, __mmask16 k, __m256i b);
VPMOVSXWD __m256i _mm256_maskz_cvtepi16_epi32(__mmask16 k, __m256i a);
VPMOVSXWQ __m256i _mm256_cvtepi16_epi64(__m256i a);
VPMOVSXWQ __m256i _mm256_mask_cvtepi16_epi64(__m256i a, __mmask8 k, __m256i b);
VPMOVSXWQ __m256i _mm256_maskz_cvtepi16_epi64( __mmask8 k, __m256i a);
VPMOVSXBW __m128i _mm_mask_cvtepi8_epi16(__m128i a, __mmask8 k, __m128i b);
VPMOVSXBW __m128i _mm_maskz_cvtepi8_epi16( __mmask8 k, __m128i b);
VPMOVSXBD __m128i _mm_mask_cvtepi8_epi32(__m128i a, __mmask8 k, __m128i b);
VPMOVSXBD __m128i _mm_maskz_cvtepi8_epi32( __mmask8 k, __m128i b);
VPMOVSXBQ __m128i _mm_mask_cvtepi8_epi64(__m128i a, __mmask8 k, __m128i b);
VPMOVSXBQ __m128i _mm_maskz_cvtepi8_epi64( __mmask8 k, __m128i a);
VPMOVSXDQ __m128i _mm_mask_cvtepi32_epi64(__m128i a, __mmask8 k, __m128i b);
VPMOVSXDQ __m128i _mm_maskz_cvtepi32_epi64( __mmask8 k, __m128i a);
VPMOVSXWD __m128i _mm_mask_cvtepi16_epi32(__m128i a, __mmask16 k, __m128i b);
VPMOVSXWD __m128i _mm_maskz_cvtepi16_epi32(__mmask16 k, __m128i a);
VPMOVSXWQ __m128i _mm_mask_cvtepi16_epi64(__m128i a, __mmask8 k, __m128i b);
VPMOVSXWQ __m128i _mm_maskz_cvtepi16_epi64( __mmask8 k, __m128i a);
PMOVSXBW __m128i _mm_ cvtepi8_epi16 ( __m128i a);
PMOVSXBD __m128i _mm_ cvtepi8_epi32 ( __m128i a);
PMOVSXBQ __m128i _mm_ cvtepi8_epi64 ( __m128i a);
PMOVSXWD __m128i _mm_ cvtepi16_epi32 ( __m128i a);
PMOVSXWQ __m128i _mm_ cvtepi16_epi64 ( __m128i a);
PMOVSXDQ __m128i _mm_ cvtepi32_epi64 ( __m128i a);
SIMD Floating-Point Exceptions
None.
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-360
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-53, “Type E5 Class Exception Conditions.”
Additionally:
#UD
If VEX.vvvv != 1111B, or EVEX.vvvv != 1111B.
PMOVSX-Packed Move With Sign Extend
Vol. 2B
4-361

PMOVZX-Packed Move With Zero Extend
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0f 38 30 /r
A
V/V
SSE4_1
Zero extend 8 packed 8-bit integers in the low 8
PMOVZXBW xmm1, xmm2/m64
bytes of xmm2/m64 to 8 packed 16-bit integers in
xmm1.
66 0f 38 31 /r
A
V/V
SSE4_1
Zero extend 4 packed 8-bit integers in the low 4
PMOVZXBD xmm1, xmm2/m32
bytes of xmm2/m32 to 4 packed 32-bit integers in
xmm1.
66 0f 38 32 /r
A
V/V
SSE4_1
Zero extend 2 packed 8-bit integers in the low 2
PMOVZXBQ xmm1, xmm2/m16
bytes of xmm2/m16 to 2 packed 64-bit integers in
xmm1.
66 0f 38 33 /r
A
V/V
SSE4_1
Zero extend 4 packed 16-bit integers in the low 8
PMOVZXWD xmm1, xmm2/m64
bytes of xmm2/m64 to 4 packed 32-bit integers in
xmm1.
66 0f 38 34 /r
A
V/V
SSE4_1
Zero extend 2 packed 16-bit integers in the low 4
PMOVZXWQ xmm1, xmm2/m32
bytes of xmm2/m32 to 2 packed 64-bit integers in
xmm1.
66 0f 38 35 /r
A
V/V
SSE4_1
Zero extend 2 packed 32-bit integers in the low 8
PMOVZXDQ xmm1, xmm2/m64
bytes of xmm2/m64 to 2 packed 64-bit integers in
xmm1.
VEX.128.66.0F38.WIG 30 /r
A
V/V
AVX
Zero extend 8 packed 8-bit integers in the low 8
VPMOVZXBW xmm1, xmm2/m64
bytes of xmm2/m64 to 8 packed 16-bit integers in
xmm1.
VEX.128.66.0F38.WIG 31 /r
A
V/V
AVX
Zero extend 4 packed 8-bit integers in the low 4
VPMOVZXBD xmm1, xmm2/m32
bytes of xmm2/m32 to 4 packed 32-bit integers in
xmm1.
VEX.128.66.0F38.WIG 32 /r
A
V/V
AVX
Zero extend 2 packed 8-bit integers in the low 2
VPMOVZXBQ xmm1, xmm2/m16
bytes of xmm2/m16 to 2 packed 64-bit integers in
xmm1.
VEX.128.66.0F38.WIG 33 /r
A
V/V
AVX
Zero extend 4 packed 16-bit integers in the low 8
VPMOVZXWD xmm1, xmm2/m64
bytes of xmm2/m64 to 4 packed 32-bit integers in
xmm1.
VEX.128.66.0F38.WIG 34 /r
A
V/V
AVX
Zero extend 2 packed 16-bit integers in the low 4
VPMOVZXWQ xmm1, xmm2/m32
bytes of xmm2/m32 to 2 packed 64-bit integers in
xmm1.
VEX.128.66.0F 38.WIG 35 /r
A
V/V
AVX
Zero extend 2 packed 32-bit integers in the low 8
VPMOVZXDQ xmm1, xmm2/m64
bytes of xmm2/m64 to 2 packed 64-bit integers in
xmm1.
VEX.256.66.0F38.WIG 30 /r
A
V/V
AVX2
Zero extend 16 packed 8-bit integers in
VPMOVZXBW ymm1, xmm2/m128
xmm2/m128 to 16 packed 16-bit integers in ymm1.
VEX.256.66.0F38.WIG 31 /r
A
V/V
AVX2
Zero extend 8 packed 8-bit integers in the low 8
VPMOVZXBD ymm1, xmm2/m64
bytes of xmm2/m64 to 8 packed 32-bit integers in
ymm1.
VEX.256.66.0F38.WIG 32 /r
A
V/V
AVX2
Zero extend 4 packed 8-bit integers in the low 4
VPMOVZXBQ ymm1, xmm2/m32
bytes of xmm2/m32 to 4 packed 64-bit integers in
ymm1.
VEX.256.66.0F38.WIG 33 /r
A
V/V
AVX2
Zero extend 8 packed 16-bit integers xmm2/m128
VPMOVZXWD ymm1, xmm2/m128
to 8 packed 32-bit integers in ymm1.
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-362

Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
VEX.256.66.0F38.WIG 34 /r
A
V/V
AVX2
Zero extend 4 packed 16-bit integers in the low 8
VPMOVZXWQ ymm1, xmm2/m64
bytes of xmm2/m64 to 4 packed 64-bit integers in
ymm1.
VEX.256.66.0F38.WIG 35 /r
A
V/V
AVX2
Zero extend 4 packed 32-bit integers in
VPMOVZXDQ ymm1, xmm2/m128
xmm2/m128 to 4 packed 64-bit integers in ymm1.
EVEX.128.66.0F38 30.WIG /r
B
V/V
(AVX512VL AND
Zero extend 8 packed 8-bit integers in the low 8
VPMOVZXBW xmm1 {k1}{z},
AVX512BW) OR
bytes of xmm2/m64 to 8 packed 16-bit integers in
xmm2/m64
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 30 /r
B
V/V
(AVX512VL AND
Zero extend 16 packed 8-bit integers in
VPMOVZXBW ymm1 {k1}{z},
AVX512BW) OR
xmm2/m128 to 16 packed 16-bit integers in ymm1
xmm2/m128
AVX10.1
subject to writemask k1.
EVEX.512.66.0F38.WIG 30 /r
B
V/V
AVX512BW
Zero extend 32 packed 8-bit integers in
VPMOVZXBW zmm1 {k1}{z},
OR AVX10.1
ymm2/m256 to 32 packed 16-bit integers in zmm1
ymm2/m256
subject to writemask k1.
EVEX.128.66.0F38.WIG 31 /r
C
V/V
(AVX512VL AND
Zero extend 4 packed 8-bit integers in the low 4
VPMOVZXBD xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m32 to 4 packed 32-bit integers in
xmm2/m32
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 31 /r
C
V/V
(AVX512VL AND
Zero extend 8 packed 8-bit integers in the low 8
VPMOVZXBD ymm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 8 packed 32-bit integers in
xmm2/m64
AVX10.1
ymm1 subject to writemask k1.
EVEX.512.66.0F38.WIG 31 /r
C
V/V
AVX512F
Zero extend 16 packed 8-bit integers in
VPMOVZXBD zmm1 {k1}{z},
OR AVX10.1
xmm2/m128 to 16 packed 32-bit integers in zmm1
xmm2/m128
subject to writemask k1.
EVEX.128.66.0F38.WIG 32 /r
D
V/V
(AVX512VL AND
Zero extend 2 packed 8-bit integers in the low 2
VPMOVZXBQ xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m16 to 2 packed 64-bit integers in
xmm2/m16
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 32 /r
D
V/V
(AVX512VL AND
Zero extend 4 packed 8-bit integers in the low 4
VPMOVZXBQ ymm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m32 to 4 packed 64-bit integers in
xmm2/m32
AVX10.1
ymm1 subject to writemask k1.
EVEX.512.66.0F38.WIG 32 /r
D
V/V
AVX512F
Zero extend 8 packed 8-bit integers in the low 8
VPMOVZXBQ zmm1 {k1}{z},
OR AVX10.1
bytes of xmm2/m64 to 8 packed 64-bit integers in
xmm2/m64
zmm1 subject to writemask k1.
EVEX.128.66.0F38.WIG 33 /r
B
V/V
(AVX512VL AND
Zero extend 4 packed 16-bit integers in the low 8
VPMOVZXWD xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 4 packed 32-bit integers in
xmm2/m64
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 33 /r
B
V/V
(AVX512VL AND
Zero extend 8 packed 16-bit integers in
VPMOVZXWD ymm1 {k1}{z},
AVX512F) OR
xmm2/m128 to 8 packed 32-bit integers in ymm1
xmm2/m128
AVX10.1
subject to writemask k1.
EVEX.512.66.0F38.WIG 33 /r
B
V/V
AVX512F
Zero extend 16 packed 16-bit integers in
VPMOVZXWD zmm1 {k1}{z},
OR AVX10.1
ymm2/m256 to 16 packed 32-bit integers in zmm1
ymm2/m256
subject to writemask k1.
EVEX.128.66.0F38.WIG 34 /r
C
V/V
(AVX512VL AND
Zero extend 2 packed 16-bit integers in the low 4
VPMOVZXWQ xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m32 to 2 packed 64-bit integers in
xmm2/m32
AVX10.1
xmm1 subject to writemask k1.
EVEX.256.66.0F38.WIG 34 /r
C
V/V
(AVX512VL AND
Zero extend 4 packed 16-bit integers in the low 8
VPMOVZXWQ ymm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 4 packed 64-bit integers in
xmm2/m64
AVX10.1
ymm1 subject to writemask k1.
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-363

Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
EVEX.512.66.0F38.WIG 34 /r
C
V/V
AVX512F
Zero extend 8 packed 16-bit integers in
VPMOVZXWQ zmm1 {k1}{z},
OR AVX10.1
xmm2/m128 to 8 packed 64-bit integers in zmm1
xmm2/m128
subject to writemask k1.
EVEX.128.66.0F38.W0 35 /r
B
V/V
(AVX512VL AND
Zero extend 2 packed 32-bit integers in the low 8
VPMOVZXDQ xmm1 {k1}{z},
AVX512F) OR
bytes of xmm2/m64 to 2 packed 64-bit integers in
xmm2/m64
AVX10.1
xmm1 using writemask k1.
EVEX.256.66.0F38.W0 35 /r
B
V/V
(AVX512VL AND
Zero extend 4 packed 32-bit integers in
VPMOVZXDQ ymm1 {k1}{z},
AVX512F) OR
xmm2/m128 to 4 packed 64-bit integers in ymm1
xmm2/m128
AVX10.1
using writemask k1.
EVEX.512.66.0F38.W0 35 /r
B
V/V
AVX512F
Zero extend 8 packed 32-bit integers in
VPMOVZXDQ zmm1 {k1}{z},
OR AVX10.1
ymm2/m256 to 8 packed 64-bit integers in zmm1
ymm2/m256
using writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
Half Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
C
Quarter Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Eighth Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Legacy, VEX, and EVEX encoded versions: Packed byte, word, or dword integers starting from the low bytes of the
source operand (second operand) are zero extended to word, dword, or quadword integers and stored in packed
signed bytes the destination operand.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding destination register remain unchanged.
VEX.128 encoded version: Bits (MAXVL-1:128) of the corresponding destination register are zeroed.
VEX.256 encoded version: Bits (MAXVL-1:256) of the corresponding destination register are zeroed.
EVEX encoded versions: Packed dword integers starting from the low bytes of the source operand (second
operand) are zero extended to quadword integers and stored to the destination operand under the writemask.The
destination register is XMM, YMM or ZMM Register.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
Operation
Packed_Zero_Extend_BYTE_to_WORD(DEST, SRC)
DEST[15:0] := ZeroExtend(SRC[7:0]);
DEST[31:16] := ZeroExtend(SRC[15:8]);
DEST[47:32] := ZeroExtend(SRC[23:16]);
DEST[63:48] := ZeroExtend(SRC[31:24]);
DEST[79:64] := ZeroExtend(SRC[39:32]);
DEST[95:80] := ZeroExtend(SRC[47:40]);
DEST[111:96] := ZeroExtend(SRC[55:48]);
DEST[127:112] := ZeroExtend(SRC[63:56]);
Packed_Zero_Extend_BYTE_to_DWORD(DEST, SRC)
DEST[31:0] := ZeroExtend(SRC[7:0]);
DEST[63:32] := ZeroExtend(SRC[15:8]);
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-364
DEST[95:64] := ZeroExtend(SRC[23:16]);
DEST[127:96] := ZeroExtend(SRC[31:24]);
Packed_Zero_Extend_BYTE_to_QWORD(DEST, SRC)
DEST[63:0] := ZeroExtend(SRC[7:0]);
DEST[127:64] := ZeroExtend(SRC[15:8]);
Packed_Zero_Extend_WORD_to_DWORD(DEST, SRC)
DEST[31:0] := ZeroExtend(SRC[15:0]);
DEST[63:32] := ZeroExtend(SRC[31:16]);
DEST[95:64] := ZeroExtend(SRC[47:32]);
DEST[127:96] := ZeroExtend(SRC[63:48]);
Packed_Zero_Extend_WORD_to_QWORD(DEST, SRC)
DEST[63:0] := ZeroExtend(SRC[15:0]);
DEST[127:64] := ZeroExtend(SRC[31:16]);
Packed_Zero_Extend_DWORD_to_QWORD(DEST, SRC)
DEST[63:0] := ZeroExtend(SRC[31:0]);
DEST[127:64] := ZeroExtend(SRC[63:32]);
VPMOVZXBW (EVEX Encoded Versions)
(KL, VL) = (8, 128), (16, 256), (32, 512)
Packed_Zero_Extend_BYTE_to_WORD(TMP_DEST[127:0], SRC[63:0])
IF VL >= 256
Packed_Zero_Extend_BYTE_to_WORD(TMP_DEST[255:128], SRC[127:64])
FI;
IF VL >= 512
Packed_Zero_Extend_BYTE_to_WORD(TMP_DEST[383:256], SRC[191:128])
Packed_Zero_Extend_BYTE_to_WORD(TMP_DEST[511:384], SRC[255:192])
FI;
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := TEMP_DEST[i+15:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+15:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-365
VPMOVZXBD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
Packed_Zero_Extend_BYTE_to_DWORD(TMP_DEST[127:0], SRC[31:0])
IF VL >= 256
Packed_Zero_Extend_BYTE_to_DWORD(TMP_DEST[255:128], SRC[63:32])
FI;
IF VL >= 512
Packed_Zero_Extend_BYTE_to_DWORD(TMP_DEST[383:256], SRC[95:64])
Packed_Zero_Extend_BYTE_to_DWORD(TMP_DEST[511:384], SRC[127:96])
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := TEMP_DEST[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMOVZXBQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
Packed_Zero_Extend_BYTE_to_QWORD(TMP_DEST[127:0], SRC[15:0])
IF VL >= 256
Packed_Zero_Extend_BYTE_to_QWORD(TMP_DEST[255:128], SRC[31:16])
FI;
IF VL >= 512
Packed_Zero_Extend_BYTE_to_QWORD(TMP_DEST[383:256], SRC[47:32])
Packed_Zero_Extend_BYTE_to_QWORD(TMP_DEST[511:384], SRC[63:48])
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TEMP_DEST[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-366
VPMOVZXWD (EVEX Encoded Versions)
(KL, VL) = (4, 128), (8, 256), (16, 512)
Packed_Zero_Extend_WORD_to_DWORD(TMP_DEST[127:0], SRC[63:0])
IF VL >= 256
Packed_Zero_Extend_WORD_to_DWORD(TMP_DEST[255:128], SRC[127:64])
FI;
IF VL >= 512
Packed_Zero_Extend_WORD_to_DWORD(TMP_DEST[383:256], SRC[191:128])
Packed_Zero_Extend_WORD_to_DWORD(TMP_DEST[511:384], SRC[256:192])
FI;
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := TEMP_DEST[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+31:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMOVZXWQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
Packed_Zero_Extend_WORD_to_QWORD(TMP_DEST[127:0], SRC[31:0])
IF VL >= 256
Packed_Zero_Extend_WORD_to_QWORD(TMP_DEST[255:128], SRC[63:32])
FI;
IF VL >= 512
Packed_Zero_Extend_WORD_to_QWORD(TMP_DEST[383:256], SRC[95:64])
Packed_Zero_Extend_WORD_to_QWORD(TMP_DEST[511:384], SRC[127:96])
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TEMP_DEST[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-367
VPMOVZXDQ (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
Packed_Zero_Extend_DWORD_to_QWORD(TEMP_DEST[127:0], SRC[63:0])
IF VL >= 256
Packed_Zero_Extend_DWORD_to_QWORD(TEMP_DEST[255:128], SRC[127:64])
FI;
IF VL >= 512
Packed_Zero_Extend_DWORD_to_QWORD(TEMP_DEST[383:256], SRC[191:128])
Packed_Zero_Extend_DWORD_to_QWORD(TEMP_DEST[511:384], SRC[255:192])
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TEMP_DEST[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE *zeroing-masking*
; zeroing-masking
DEST[i+63:i] := 0
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VPMOVZXBW (VEX.256 Encoded Version)
Packed_Zero_Extend_BYTE_to_WORD(DEST[127:0], SRC[63:0])
Packed_Zero_Extend_BYTE_to_WORD(DEST[255:128], SRC[127:64])
DEST[MAXVL-1:256] := 0
VPMOVZXBD (VEX.256 Encoded Version)
Packed_Zero_Extend_BYTE_to_DWORD(DEST[127:0], SRC[31:0])
Packed_Zero_Extend_BYTE_to_DWORD(DEST[255:128], SRC[63:32])
DEST[MAXVL-1:256] := 0
VPMOVZXBQ (VEX.256 Encoded Version)
Packed_Zero_Extend_BYTE_to_QWORD(DEST[127:0], SRC[15:0])
Packed_Zero_Extend_BYTE_to_QWORD(DEST[255:128], SRC[31:16])
DEST[MAXVL-1:256] := 0
VPMOVZXWD (VEX.256 Encoded Version)
Packed_Zero_Extend_WORD_to_DWORD(DEST[127:0], SRC[63:0])
Packed_Zero_Extend_WORD_to_DWORD(DEST[255:128], SRC[127:64])
DEST[MAXVL-1:256] := 0
VPMOVZXWQ (VEX.256 Encoded Version)
Packed_Zero_Extend_WORD_to_QWORD(DEST[127:0], SRC[31:0])
Packed_Zero_Extend_WORD_to_QWORD(DEST[255:128], SRC[63:32])
DEST[MAXVL-1:256] := 0
VPMOVZXDQ (VEX.256 Encoded Version)
Packed_Zero_Extend_DWORD_to_QWORD(DEST[127:0], SRC[63:0])
Packed_Zero_Extend_DWORD_to_QWORD(DEST[255:128], SRC[127:64])
DEST[MAXVL-1:256] := 0
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-368
VPMOVZXBW (VEX.128 Encoded Version)
Packed_Zero_Extend_BYTE_to_WORD()
DEST[MAXVL-1:128] := 0
VPMOVZXBD (VEX.128 Encoded Version)
Packed_Zero_Extend_BYTE_to_DWORD()
DEST[MAXVL-1:128] := 0
VPMOVZXBQ (VEX.128 Encoded Version)
Packed_Zero_Extend_BYTE_to_QWORD()
DEST[MAXVL-1:128] := 0
VPMOVZXWD (VEX.128 Encoded Version)
Packed_Zero_Extend_WORD_to_DWORD()
DEST[MAXVL-1:128] := 0
VPMOVZXWQ (VEX.128 Encoded Version)
Packed_Zero_Extend_WORD_to_QWORD()
DEST[MAXVL-1:128] := 0
VPMOVZXDQ (VEX.128 Encoded Version)
Packed_Zero_Extend_DWORD_to_QWORD()
DEST[MAXVL-1:128] := 0
PMOVZXBW
Packed_Zero_Extend_BYTE_to_WORD()
DEST[MAXVL-1:128] (Unmodified)
PMOVZXBD
Packed_Zero_Extend_BYTE_to_DWORD()
DEST[MAXVL-1:128] (Unmodified)
PMOVZXBQ
Packed_Zero_Extend_BYTE_to_QWORD()
DEST[MAXVL-1:128] (Unmodified)
PMOVZXWD
Packed_Zero_Extend_WORD_to_DWORD()
DEST[MAXVL-1:128] (Unmodified)
PMOVZXWQ
Packed_Zero_Extend_WORD_to_QWORD()
DEST[MAXVL-1:128] (Unmodified)
PMOVZXDQ
Packed_Zero_Extend_DWORD_to_QWORD()
DEST[MAXVL-1:128] (Unmodified)
Intel C/C++ Compiler Intrinsic Equivalent
VPMOVZXBW __m512i _mm512_cvtepu8_epi16(__m256i a);
VPMOVZXBW __m512i _mm512_mask_cvtepu8_epi16(__m512i a, __mmask32 k, __m256i b);
VPMOVZXBW __m512i _mm512_maskz_cvtepu8_epi16( __mmask32 k, __m256i b);
VPMOVZXBD __m512i _mm512_cvtepu8_epi32(__m128i a);
PMOVZX-Packed Move With Zero Extend
Vol. 2B
4-369