Intel 64 and IA-32 Architectures. Software Developer’s Manual (2026) - page 20

MONITOR-Set Up Monitor Address
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
0F 01 C8
MONITOR
ZO
Valid
Valid
Sets up a linear address range to be monitored by
hardware and activates the monitor. The address range
should be a write-back memory caching type. The
address is DS:RAX/EAX/AX.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
ZO
N/A
N/A
N/A
N/A
Description
The MONITOR instruction arms address monitoring hardware using an address specified in EAX (the address range
that the monitoring hardware checks for store operations can be determined by using CPUID). A store to an
address within the specified address range triggers the monitoring hardware. The state of monitor hardware is
used by MWAIT.
The address is specified in RAX/EAX/AX and the size is based on the effective address size of the encoded instruc-
tion. By default, the DS segment is used to create a linear address that is monitored. Segment overrides can be
used.
ECX and EDX are also used. They communicate other information to MONITOR. ECX specifies optional extensions.
EDX specifies optional hints; it does not change the architectural behavior of the instruction. For the Pentium 4
processor (family 15, model 3), no extensions or hints are defined. Undefined hints in EDX are ignored by the
processor; undefined extensions in ECX raises a general protection fault.
The address range must use memory of the write-back type. Only write-back memory will correctly trigger the
monitoring hardware. Additional information on determining what address range to use in order to prevent false
wake-ups is described in Chapter 11, “Multiple-Processor Management‚” of the Intel® 64 and IA-32 Architectures
Software Developer’s Manual, Volume 3A.
The MONITOR instruction is ordered as a load operation with respect to other memory transactions. The instruction
is subject to the permission checking and faults associated with a byte load. Like a load, MONITOR sets the A-bit
but not the D-bit in page tables.
CPUID.01H:ECX.MONITOR[3] indicates the availability of MONITOR and MWAIT in the processor. When set,
MONITOR may be executed only at privilege level 0 (use at any other privilege level results in an invalid-opcode
exception). The operating system or system BIOS may disable this instruction by using the IA32_MISC_ENABLE
MSR; disabling MONITOR clears the CPUID feature flag and causes execution to generate an invalid-opcode excep-
tion.
The instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
MONITOR sets up an address range for the monitor hardware using the content of EAX (RAX in 64-bit mode) as an effective address
and puts the monitor hardware in armed state. Always use memory of the write-back caching type. A store to the specified address
range will trigger the monitor hardware. The content of ECX and EDX are used to communicate other information to the monitor
hardware.
Intel C/C++ Compiler Intrinsic Equivalent
MONITOR void _mm_monitor(void const *p, unsigned extensions,unsigned hints)
Numeric Exceptions
None.
MONITOR-Set Up Monitor Address
Vol. 2B
4-26
Protected Mode Exceptions
#GP(0)
If the value in EAX is outside the CS, DS, ES, FS, or GS segment limit.
If the DS, ES, FS, or GS register is used to access memory and it contains a NULL segment
selector.
If ECX ≠ 0.
#SS(0)
If the value in EAX is outside the SS segment limit.
#PF(fault-code)
For a page fault.
#UD
If CPUID.01H:ECX.MONITOR[3] = 0.
If current privilege level is not 0.
Real Address Mode Exceptions
#GP
If the CS, DS, ES, FS, or GS register is used to access memory and the value in EAX is outside
of the effective address space from 0 to FFFFH.
If ECX ≠ 0.
#SS
If the SS register is used to access memory and the value in EAX is outside of the effective
address space from 0 to FFFFH.
#UD
If CPUID.01H:ECX.MONITOR[3] = 0.
Virtual 8086 Mode Exceptions
#UD
The MONITOR instruction is not recognized in virtual-8086 mode (even if
CPUID.01H:ECX.MONITOR[3] = 1).
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#GP(0)
If the linear address of the operand in the CS, DS, ES, FS, or GS segment is in a non-canonical
form.
If RCX ≠ 0.
#SS(0)
If the SS register is used to access memory and the value in EAX is in a non-canonical form.
#PF(fault-code)
For a page fault.
#UD
If the current privilege level is not 0.
If CPUID.01H:ECX.MONITOR[3] = 0.
MONITOR-Set Up Monitor Address
Vol. 2B
4-27

MOV-Move
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
88 /r
MOV r/m81, r81
MR
Valid
Valid
Move r8 to r/m8.
89 /r
MOV r/m16, r16
MR
Valid
Valid
Move r16 to r/m16.
89 /r
MOV r/m32, r32
MR
Valid
Valid
Move r32 to r/m32.
REX.W + 89 /r
MOV r/m64, r64
MR
Valid
N.E.
Move r64 to r/m64.
8A /r
MOV r81, r/m81
RM
Valid
Valid
Move r/m8 to r8.
8B /r
MOV r16, r/m16
RM
Valid
Valid
Move r/m16 to r16.
8B /r
MOV r32, r/m32
RM
Valid
Valid
Move r/m32 to r32.
REX.W + 8B /r
MOV r64, r/m64
RM
Valid
N.E.
Move r/m64 to r64.
8C /r
MOV r/m16, Sreg2
MR
Valid
Valid
Move segment register to r/m16.
8C /r
MOV r16/r32/m16, Sreg2
MR
Valid
Valid
Move zero extended 16-bit segment register
to r16/r32/m16.
REX.W + 8C /r
MOV r64/m16, Sreg2
MR
Valid
Valid
Move zero extended 16-bit segment register
to r64/m16.
8E /r
MOV Sreg, r/m162
RM
Valid
Valid
Move r/m16 to segment register.
REX.W + 8E /r
MOV Sreg, r/m642
RM
Valid
Valid
Move lower 16 bits of r/m64 to segment
register.
A0
MOV AL, moffs83
FD
Valid
Valid
Move byte at (seg:offset) to AL.
REX.W + A0
MOV AL, moffs83
FD
Valid
N.E.
Move byte at (offset) to AL.
A1
MOV AX, moffs163
FD
Valid
Valid
Move word at (seg:offset) to AX.
A1
MOV EAX, moffs323
FD
Valid
Valid
Move doubleword at (seg:offset) to EAX.
REX.W + A1
MOV RAX, moffs643
FD
Valid
N.E.
Move quadword at (offset) to RAX.
A2
MOV moffs8, AL
TD
Valid
Valid
Move AL to (seg:offset).
REX.W + A2
MOV moffs81, AL
TD
Valid
N.E.
Move AL to (offset).
A3
MOV moffs163, AX
TD
Valid
Valid
Move AX to (seg:offset).
A3
MOV moffs323, EAX
TD
Valid
Valid
Move EAX to (seg:offset).
REX.W + A3
MOV moffs643, RAX
TD
Valid
N.E.
Move RAX to (offset).
B0+ rb ib
MOV r81, imm8
OI
Valid
Valid
Move imm8 to r8.
B8+ rw iw
MOV r16, imm16
OI
Valid
Valid
Move imm16 to r16.
B8+ rd id
MOV r32, imm32
OI
Valid
Valid
Move imm32 to r32.
REX.W + B8+ rd io
MOV r64, imm64
OI
Valid
N.E.
Move imm64 to r64.
C6 /0 ib
MOV r/m81, imm8
MI
Valid
Valid
Move imm8 to r/m8.
C7 /0 iw
MOV r/m16, imm16
MI
Valid
Valid
Move imm16 to r/m16.
C7 /0 id
MOV r/m32, imm32
MI
Valid
Valid
Move imm32 to r/m32.
REX.W + C7 /0 id
MOV r/m64, imm32
MI
Valid
N.E.
Move imm32 sign extended to 64-bits to
r/m64.
NOTES:
1. With a REX prefix in 64-bit mode, attempts to access AH, BH, CH, or DH will instead access SPL, DIL, BPL, or SIL, respectively.
2. In 32-bit mode, the assembler may insert the 16-bit operand-size prefix with this instruction (see the following “Description” section
for further information).
3. The moffs8, moffs16, moffs32, and moffs64 operands specify a simple offset relative to the segment base, where 8, 16, 32, and 64
refer to the size of the data. The address-size attribute of the instruction determines the size of the offset, either 16, 32, or 64 bits.
MOV-Move
Vol. 2B
4-28

Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
MR
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
FD
AL/AX/EAX/RAX
Moffs
N/A
N/A
TD
Moffs (w)
AL/AX/EAX/RAX
N/A
N/A
OI
opcode + rd (w)
imm8/16/32/64
N/A
N/A
MI
ModRM:r/m (w)
imm8/16/32/64
N/A
N/A
Description
Copies the second operand (source operand) to the first operand (destination operand). The source operand can be
an immediate value, general-purpose register, segment register, or memory location; the destination register can
be a general-purpose register, segment register, or memory location. Both operands must be the same size, which
can be a byte, a word, a doubleword, or a quadword.
The MOV instruction cannot be used to load the CS register. Attempting to do so results in an invalid opcode excep-
tion (#UD). To load the CS register, use the far JMP, CALL, or RET instruction.
If the destination operand is a segment register (DS, ES, FS, GS, or SS), the source operand must be a valid
segment selector. In protected mode, moving a segment selector into a segment register automatically causes the
segment descriptor information associated with that segment selector to be loaded into the hidden (shadow) part
of the segment register. While loading this information, the segment selector and segment descriptor information
is validated (see the “Operation” algorithm below). The segment descriptor data is obtained from the GDT or LDT
entry for the specified segment selector.
A NULL segment selector (values 0000-0003) can be loaded into the DS, ES, FS, and GS registers without causing
a protection exception. However, any subsequent attempt to reference a segment whose corresponding segment
register is loaded with a NULL value causes a general protection exception (#GP) and no memory reference occurs.
Loading the SS register with a MOV instruction suppresses or inhibits some debug exceptions and inhibits inter-
rupts on the following instruction boundary. (The inhibition ends after delivery of an exception or the execution of
the next instruction.) This behavior allows a stack pointer to be loaded into the ESP register with the next instruc-
tion (MOV ESP, stack-pointer value) before an event can be delivered. See Section 7.8.3, “Masking Exceptions
and Interrupts When Switching Stacks,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual,
Volume 3A. Intel recommends that software use the LSS instruction to load the SS register and ESP together.
When executing MOV Reg, Sreg, the processor copies the content of Sreg to the 16 least significant bits of the
general-purpose register. The upper bits of the destination register are zero for most IA-32 processors (Pentium
Pro processors and later) and all Intel 64 processors, with the exception that bits 31:16 are undefined for Intel
Quark X1000 processors, Pentium, and earlier processors.
In 64-bit mode, the instruction’s default operation size is 32 bits. Use of the REX.R prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. See the summary chart at the
beginning of this section for encoding data and limits.
Operation
DEST := SRC;
Loading a segment register while in protected mode results in special checks and actions, as described in the following listing. These
checks are performed on the segment selector and the segment descriptor to which it points.
IF SS is loaded
THEN
IF segment selector is NULL
THEN #GP(0); FI;
IF segment selector index is outside descriptor table limits
OR segment selector's RPL ≠ CPL
MOV-Move
Vol. 2B
4-29
OR segment is not a writable data segment
OR DPL ≠ CPL
THEN #GP(selector); FI;
IF segment not marked present
THEN #SS(selector);
ELSE
SS := segment selector;
SS := segment descriptor; FI;
FI;
IF DS, ES, FS, or GS is loaded with non-NULL selector
THEN
IF segment selector index is outside descriptor table limits
OR segment is not a data or readable code segment
OR ((segment is a data or nonconforming code segment) AND ((RPL > DPL) or (CPL > DPL)))
THEN #GP(selector); FI;
IF segment not marked present
THEN #NP(selector);
ELSE
SegmentRegister := segment selector;
SegmentRegister := segment descriptor; FI;
FI;
IF DS, ES, FS, or GS is loaded with NULL selector
THEN
SegmentRegister := segment selector;
SegmentRegister := segment descriptor;
FI;
Flags Affected
None.
Protected Mode Exceptions
#GP(0)
If attempt is made to load SS register with NULL segment selector.
If the destination operand is in a non-writable segment.
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
If the DS, ES, FS, or GS register contains a NULL segment selector.
#GP(selector)
If segment selector index is outside descriptor table limits.
If the SS register is being loaded and the segment selector's RPL and the segment descriptor’s
DPL are not equal to the CPL.
If the SS register is being loaded and the segment pointed to is a
non-writable data segment.
If the DS, ES, FS, or GS register is being loaded and the segment pointed to is not a data or
readable code segment.
If the DS, ES, FS, or GS register is being loaded and the segment pointed to is a data or
nonconforming code segment, and either the RPL or the CPL is greater than the DPL.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#SS(selector)
If the SS register is being loaded and the segment pointed to is marked not present.
#NP
If the DS, ES, FS, or GS register is being loaded and the segment pointed to is marked not
present.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
MOV-Move
Vol. 2B
4-30
#UD
If attempt is made to load the CS register.
If the LOCK prefix is used.
Real-Address Mode Exceptions
#GP
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS
If a memory operand effective address is outside the SS segment limit.
#UD
If attempt is made to load the CS register.
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made.
#UD
If attempt is made to load the CS register.
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#GP(0)
If the memory address is in a non-canonical form.
If an attempt is made to load SS register with NULL segment selector when CPL = 3.
If an attempt is made to load SS register with NULL segment selector when CPL < 3 and CPL
≠ RPL.
#GP(selector)
If segment selector index is outside descriptor table limits.
If the memory access to the descriptor table is non-canonical.
If the SS register is being loaded and the segment selector's RPL and the segment descriptor’s
DPL are not equal to the CPL.
If the SS register is being loaded and the segment pointed to is a nonwritable data segment.
If the DS, ES, FS, or GS register is being loaded and the segment pointed to is not a data or
readable code segment.
If the DS, ES, FS, or GS register is being loaded and the segment pointed to is a data or
nonconforming code segment, but both the RPL and the CPL are greater than the DPL.
#SS(0)
If the stack address is in a non-canonical form.
#SS(selector)
If the SS register is being loaded and the segment pointed to is marked not present.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If attempt is made to load the CS register.
If the LOCK prefix is used.
MOV-Move
Vol. 2B
4-31

MOV-Move to/from Control Registers
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
0F 20/r
MOV r32, CR0-CR7
MR
N.E.
Valid
Move control register to r32.
0F 20/r
MOV r64, CR0-CR7
MR
Valid
N.E.
Move extended control register to r64.
REX.R + 0F 20 /0
MOV r64, CR8
MR
Valid
N.E.
Move extended CR8 to r64.1
0F 22 /r
MOV CR0-CR7, r32
RM
N.E.
Valid
Move r32 to control register.
0F 22 /r
MOV CR0-CR7, r64
RM
Valid
N.E.
Move r64 to extended control register.
REX.R + 0F 22 /0
MOV CR8, r64
RM
Valid
N.E.
Move r64 to extended CR8.1
NOTES:
1. MOV CR* instructions, except for MOV CR8, are serializing instructions. MOV CR8 is not architecturally defined as a serializing instruc-
tion. For more information, see Chapter 11 in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3A.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
MR
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Moves the contents of a control register (CR0, CR2, CR3, CR4, or CR8) to a general-purpose register or the
contents of a general-purpose register to a control register. The operand size for these instructions is always 32 bits
in non-64-bit modes, regardless of the operand-size attribute. On a 64-bit capable processor, an execution of MOV
to CR outside of 64-bit mode zeros the upper 32 bits of the control register. (See “Control Registers” in Chapter 2
of the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3A, for a detailed description of the
flags and fields in the control registers.) This instruction can be executed only when the current privilege level is 0.
At the opcode level, the reg field within the ModR/M byte specifies which of the control registers is loaded or read.
The 2 bits in the mod field are ignored. The r/m field specifies the general-purpose register loaded or read. Some
of the bits in CR0, CR3, and CR4 are reserved and must be written with zeros. Attempting to set any reserved bits
in CR0[31:0] is ignored. Attempting to set any reserved bits in CR0[63:32] results in a general-protection excep-
tion, #GP(0). When PCIDs are not enabled, bits 2:0 and bits 11:5 of CR3 are not used and attempts to set them
are ignored. See the next paragraph for treatment of bits reserved in CR3. Attempting to set any reserved bits in
CR4 results in #GP(0). On Pentium 4, Intel Xeon and P6 family processors, CR0.ET remains set after any load of
CR0; attempts to clear this bit have no impact.
Normally, MAXPHYADDR is the value enumerated in CPUID.80000008H:EAX[7:0]. However, if IA32_TME_ACTI-
VATE[0] = 1 (indicating that TME has been configured), MAXPHYADDR is reduced by the value of IA32_TME_ACTI-
VATE[39:36] when a logical processor is outside secure arbitration mode (SEAM; see Chapter 35 of the Intel® 64
and IA-32 Architectures Software Developer’s Manual, Volume 3); the value is not reduced in SEAM. An attempt to
set any reserved bit in CR3[63:MAXPHYADDR] results in #GP(0).
In certain cases, these instructions have the side effect of invalidating entries in the TLBs and the paging-structure
caches. See Section 5.10.4.1, “Operations that Invalidate TLBs and Paging-Structure Caches,” in the Intel® 64 and
IA-32 Architectures Software Developer’s Manual, Volume 3A, for details.
The following side effects are implementation-specific for the Pentium 4, Intel Xeon, and P6 processor family: when
modifying PE or PG in register CR0, or PSE or PAE in register CR4, all TLB entries are flushed, including global
entries. Software should not depend on this functionality in all Intel 64 or IA-32 processors.
In 64-bit mode, the instruction’s default operation size is 64 bits. The REX.R prefix must be used to access CR8.
Use of REX.B permits access to additional registers (R8-R15). Use of the REX.W prefix or 66H prefix is ignored. Use
of the REX.R prefix to specify a register other than CR8 causes an invalid-opcode exception. See the summary
chart at the beginning of this section for encoding data and limits.
MOV-Move to/from Control Registers
Vol. 2B
4-32
If CR4.PCIDE = 1, bit 63 of the source operand to MOV to CR3 determines whether the instruction invalidates
entries in the TLBs and the paging-structure caches (see Section 5.10.4.1, “Operations that Invalidate TLBs and
Paging-Structure Caches,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 3A). The
instruction does not modify bit 63 of CR3, which is reserved and always 0.
See “Changes to Instruction Behavior in VMX Non-Root Operation” in Chapter 27 of the Intel® 64 and IA-32 Archi-
tectures Software Developer’s Manual, Volume 3C, for more information about the behavior of this instruction in
VMX non-root operation.
Operation
DEST := SRC;
Flags Affected
The OF, SF, ZF, AF, PF, and CF flags are undefined.
Protected Mode Exceptions
#GP(0)
If the current privilege level is not 0.
If an attempt is made to write invalid bit combinations in CR0 (such as setting the PG flag to 1
when the PE flag is set to 0, or setting the CD flag to 0 when the NW flag is set to 1).
If an attempt is made to write a 1 to any reserved bit in CR4.
If an attempt is made to write 1 to CR4.PCIDE.
If any of the reserved bits are set in the page-directory pointers table (PDPT) and the loading
of a control register causes the PDPT to be loaded into the processor.
If an attempt is made to activate IA-32e mode and either the current CS has the L-bit set or
the TR references a 16-bit TSS.
#UD
If the LOCK prefix is used.
If an attempt is made to access CR1, CR5, CR6, CR7, or CR9-CR15.
Real-Address Mode Exceptions
#GP
If an attempt is made to write a 1 to any reserved bit in CR4.
If an attempt is made to write 1 to CR4.PCIDE.
If an attempt is made to write invalid bit combinations in CR0 (such as setting the PG flag to 1
when the PE flag is set to 0).
If an attempt is made to activate IA-32e mode and either the current CS has the L-bit set or
the TR references a 16-bit TSS.
#UD
If the LOCK prefix is used.
If an attempt is made to access CR1, CR5, CR6, CR7, or CR9-CR15.
Virtual-8086 Mode Exceptions
#GP(0)
These instructions cannot be executed in virtual-8086 mode.
Compatibility Mode Exceptions
#GP(0)
If the current privilege level is not 0.
If an attempt is made to write invalid bit combinations in CR0 (such as setting the PG flag to 1
when the PE flag is set to 0, or setting the CD flag to 0 when the NW flag is set to 1).
If an attempt is made to change CR4.PCIDE from 0 to 1 while CR3[11:0] ≠ 000H.
If an attempt is made to clear CR0.PG[bit 31] while CR4.PCIDE = 1.
If an attempt is made to leave IA-32e mode by clearing CR4.PAE[bit 5].
#UD
If the LOCK prefix is used.
If an attempt is made to access CR1, CR5, CR6, CR7, or CR9-CR15.
MOV-Move to/from Control Registers
Vol. 2B
4-33
64-Bit Mode Exceptions
#GP(0)
If the current privilege level is not 0.
If an attempt is made to write invalid bit combinations in CR0 (such as setting the PG flag to 1
when the PE flag is set to 0, or setting the CD flag to 0 when the NW flag is set to 1).
If an attempt is made to change CR4.PCIDE from 0 to 1 while CR3[11:0] ≠ 000H.
If an attempt is made to clear CR0.PG[bit 31].
If an attempt is made to write a 1 to any reserved bit in CR4.
If an attempt is made to write a 1 to any reserved bit in CR8.
If an attempt is made to write a 1 to any reserved bit in CR3[63:MAXPHYADDR].
If an attempt is made to leave IA-32e mode by clearing CR4.PAE[bit 5].
#UD
If the LOCK prefix is used.
If an attempt is made to access CR1, CR5, CR6, CR7, or CR9-CR15.
If the REX.R prefix is used to specify a register other than CR8.
MOV-Move to/from Control Registers
Vol. 2B
4-34

MOV-Move to/from Debug Registers
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
0F 21/r
MOV r32, DR0-DR7
MR
N.E.
Valid
Move debug register to r32.
0F 21/r
MOV r64, DR0-DR7
MR
Valid
N.E.
Move extended debug register to r64.
0F 23 /r
MOV DR0-DR7, r32
RM
N.E.
Valid
Move r32 to debug register.
0F 23 /r
MOV DR0-DR7, r64
RM
Valid
N.E.
Move r64 to extended debug register.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
MR
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Moves the contents of a debug register (DR0, DR1, DR2, DR3, DR4, DR5, DR6, or DR7) to a general-purpose
register or vice versa. The operand size for these instructions is always 32 bits in non-64-bit modes, regardless of
the operand-size attribute. (See Section 20.2, “Debug Registers”, of the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 3A, for a detailed description of the flags and fields in the debug registers.)
The instructions must be executed at privilege level 0 or in real-address mode.
When the debug extension (DE) flag in register CR4 is clear, these instructions operate on debug registers in a
manner that is compatible with Intel386 and Intel486 processors. In this mode, references to DR4 and DR5 refer
to DR6 and DR7, respectively. When the DE flag in CR4 is set, attempts to reference DR4 and DR5 result in an
undefined opcode (#UD) exception. (The CR4 register was added to the IA-32 Architecture beginning with the
Pentium processor.)
At the opcode level, the reg field within the ModR/M byte specifies which of the debug registers is loaded or read.
The two bits in the mod field are ignored. The r/m field specifies the general-purpose register loaded or read.
In 64-bit mode, the instruction’s default operation size is 64 bits. Use of the REX.B prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W or 66H prefix is ignored. Use of the REX.R prefix causes an invalid-
opcode exception. See the summary chart at the beginning of this section for encoding data and limits.
Operation
IF ((DE = 1) and (SRC or DEST = DR4 or DR5))
THEN
#UD;
ELSE
DEST := SRC;
FI;
Flags Affected
The OF, SF, ZF, AF, PF, and CF flags are undefined.
MOV-Move to/from Debug Registers
Vol. 2B
4-35
Protected Mode Exceptions
#GP(0)
If the current privilege level is not 0.
#UD
If CR4.DE[bit 3] = 1 (debug extensions) and a MOV instruction is executed involving DR4 or
DR5.
If the LOCK prefix is used.
#DB
If any debug register is accessed while the DR7.GD[bit 13] = 1.
Real-Address Mode Exceptions
#UD
If CR4.DE[bit 3] = 1 (debug extensions) and a MOV instruction is executed involving DR4 or
DR5.
If the LOCK prefix is used.
#DB
If any debug register is accessed while the DR7.GD[bit 13] = 1.
Virtual-8086 Mode Exceptions
#GP(0)
The debug registers cannot be loaded or read when in virtual-8086 mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#GP(0)
If the current privilege level is not 0.
If an attempt is made to write a 1 to any of bits 63:32 in DR6.
If an attempt is made to write a 1 to any of bits 63:32 in DR7.
#UD
If CR4.DE[bit 3] = 1 (debug extensions) and a MOV instruction is executed involving DR4 or
DR5.
If the LOCK prefix is used.
If the REX.R prefix is used.
#DB
If any debug register is accessed while the DR7.GD[bit 13] = 1.
MOV-Move to/from Debug Registers
Vol. 2B
4-36

MOVAPD-Move Aligned Packed Double Precision Floating-Point Values
Opcode/
Op/En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
66 0F 28 /r
A
V/V
SSE2
Move aligned packed double precision floating-
MOVAPD xmm1, xmm2/m128
point values from xmm2/mem to xmm1.
66 0F 29 /r
B
V/V
SSE2
Move aligned packed double precision floating-
MOVAPD xmm2/m128, xmm1
point values from xmm1 to xmm2/mem.
VEX.128.66.0F.WIG 28 /r
A
V/V
AVX
Move aligned packed double precision floating-
VMOVAPD xmm1, xmm2/m128
point values from xmm2/mem to xmm1.
VEX.128.66.0F.WIG 29 /r
B
V/V
AVX
Move aligned packed double precision floating-
VMOVAPD xmm2/m128, xmm1
point values from xmm1 to xmm2/mem.
VEX.256.66.0F.WIG 28 /r
A
V/V
AVX
Move aligned packed double precision floating-
VMOVAPD ymm1, ymm2/m256
point values from ymm2/mem to ymm1.
VEX.256.66.0F.WIG 29 /r
B
V/V
AVX
Move aligned packed double precision floating-
VMOVAPD ymm2/m256, ymm1
point values from ymm1 to ymm2/mem.
EVEX.128.66.0F.W1 28 /r
C
V/V
(AVX512VL AND
Move aligned packed double precision floating-
VMOVAPD xmm1 {k1}{z}, xmm2/m128
AVX512F) OR
point values from xmm2/m128 to xmm1 using
AVX10.1
writemask k1.
EVEX.256.66.0F.W1 28 /r
C
V/V
(AVX512VL AND
Move aligned packed double precision floating-
VMOVAPD ymm1 {k1}{z}, ymm2/m256
AVX512F) OR
point values from ymm2/m256 to ymm1 using
AVX10.1
writemask k1.
EVEX.512.66.0F.W1 28 /r
C
V/V
AVX512F
Move aligned packed double precision floating-
VMOVAPD zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
point values from zmm2/m512 to zmm1 using
writemask k1.
EVEX.128.66.0F.W1 29 /r
D
V/V
(AVX512VL AND
Move aligned packed double precision floating-
VMOVAPD xmm2/m128 {k1}{z}, xmm1
AVX512F) OR
point values from xmm1 to xmm2/m128 using
AVX10.1
writemask k1.
EVEX.256.66.0F.W1 29 /r
D
V/V
(AVX512VL AND
Move aligned packed double precision floating-
VMOVAPD ymm2/m256 {k1}{z}, ymm1
AVX512F) OR
point values from ymm1 to ymm2/m256 using
AVX10.1
writemask k1.
EVEX.512.66.0F.W1 29 /r
D
V/V
AVX512F
Move aligned packed double precision floating-
VMOVAPD zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
point values from zmm1 to zmm2/m512 using
writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
C
Full Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Full Mem
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Moves 2, 4 or 8 double precision floating-point values from the source operand (second operand) to the destination
operand (first operand). This instruction can be used to load an XMM, YMM or ZMM register from an 128-bit, 256-
bit or 512-bit memory location, to store the contents of an XMM, YMM or ZMM register into a 128-bit, 256-bit or
512-bit memory location, or to move data between two XMM, two YMM or two ZMM registers.
When the source or destination operand is a memory operand, the operand must be aligned on a 16-byte (128-bit
versions), 32-byte (256-bit version) or 64-byte (EVEX.512 encoded version) boundary or a general-protection
MOVAPD-Move Aligned Packed Double Precision Floating-Point Values
Vol. 2B
4-37
exception (#GP) will be generated. For EVEX encoded versions, the operand must be aligned to the size of the
memory operand. To move double precision floating-point values to and from unaligned memory locations, use the
VMOVUPD instruction.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
EVEX.512 encoded version:
Moves 512 bits of packed double precision floating-point values from the source operand (second operand) to the
destination operand (first operand). This instruction can be used to load a ZMM register from a 512-bit float64
memory location, to store the contents of a ZMM register into a 512-bit float64 memory location, or to move data
between two ZMM registers. When the source or destination operand is a memory operand, the operand must be
aligned on a 64-byte boundary or a general-protection exception (#GP) will be generated. To move single precision
floating-point values to and from unaligned memory locations, use the VMOVUPD instruction.
VEX.256 and EVEX.256 encoded versions:
Moves 256 bits of packed double precision floating-point values from the source operand (second operand) to the
destination operand (first operand). This instruction can be used to load a YMM register from a 256-bit memory
location, to store the contents of a YMM register into a 256-bit memory location, or to move data between two YMM
registers. When the source or destination operand is a memory operand, the operand must be aligned on a 32-byte
boundary or a general-protection exception (#GP) will be generated. To move double precision floating-point
values to and from unaligned memory locations, use the VMOVUPD instruction.
128-bit versions:
Moves 128 bits of packed double precision floating-point values from the source operand (second operand) to the
destination operand (first operand). This instruction can be used to load an XMM register from a 128-bit memory
location, to store the contents of an XMM register into a 128-bit memory location, or to move data between two
XMM registers. When the source or destination operand is a memory operand, the operand must be aligned on a
16-byte boundary or a general-protection exception (#GP) will be generated. To move single precision floating-
point values to and from unaligned memory locations, use the VMOVUPD instruction.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding ZMM destination register remain
unchanged.
(E)VEX.128 encoded version: Bits (MAXVL-1:128) of the destination ZMM register destination are zeroed.
Operation
VMOVAPD (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
MOVAPD-Move Aligned Packed Double Precision Floating-Point Values
Vol. 2B
4-38
VMOVAPD (EVEX Encoded Versions, Store-Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
ELSE *DEST[i+63:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVAPD (EVEX Encoded Versions, Load-Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVAPD (VEX.256 Encoded Version, Load - and Register Copy)
DEST[255:0] := SRC[255:0]
DEST[MAXVL-1:256] := 0
VMOVAPD (VEX.256 Encoded Version, Store-Form)
DEST[255:0] := SRC[255:0]
VMOVAPD (VEX.128 Encoded Version, Load - and Register Copy)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] := 0
MOVAPD (128-bit Load- and Register-Copy- Form Legacy SSE Version)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] (Unmodified)
(V)MOVAPD (128-bit Store-Form Version)
DEST[127:0] := SRC[127:0]
MOVAPD-Move Aligned Packed Double Precision Floating-Point Values
Vol. 2B
4-39
Intel C/C++ Compiler Intrinsic Equivalent
VMOVAPD __m512d _mm512_load_pd( void * m);
VMOVAPD __m512d _mm512_mask_load_pd(__m512d s, __mmask8 k, void * m);
VMOVAPD __m512d _mm512_maskz_load_pd( __mmask8 k, void * m);
VMOVAPD void _mm512_store_pd( void * d, __m512d a);
VMOVAPD void _mm512_mask_store_pd( void * d, __mmask8 k, __m512d a);
VMOVAPD __m256d _mm256_mask_load_pd(__m256d s, __mmask8 k, void * m);
VMOVAPD __m256d _mm256_maskz_load_pd( __mmask8 k, void * m);
VMOVAPD void _mm256_mask_store_pd( void * d, __mmask8 k, __m256d a);
VMOVAPD __m128d _mm_mask_load_pd(__m128d s, __mmask8 k, void * m);
VMOVAPD __m128d _mm_maskz_load_pd( __mmask8 k, void * m);
VMOVAPD void _mm_mask_store_pd( void * d, __mmask8 k, __m128d a);
MOVAPD __m256d _mm256_load_pd (double * p);
MOVAPD void _mm256_store_pd(double * p, __m256d a);
MOVAPD __m128d _mm_load_pd (double * p);
MOVAPD void _mm_store_pd(double * p, __m128d a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Exceptions Type1.SSE2 in Table 2-18, “Type 1 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-46, “Type E1 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B or VEX.vvvv != 1111B.
MOVAPD-Move Aligned Packed Double Precision Floating-Point Values
Vol. 2B
4-40

MOVAPS-Move Aligned Packed Single Precision Floating-Point Values
Opcode/
Op/En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
NP 0F 28 /r
A
V/V
SSE
Move aligned packed single precision floating-point
MOVAPS xmm1, xmm2/m128
values from xmm2/mem to xmm1.
NP 0F 29 /r
B
V/V
SSE
Move aligned packed single precision floating-point
MOVAPS xmm2/m128, xmm1
values from xmm1 to xmm2/mem.
VEX.128.0F.WIG 28 /r
A
V/V
AVX
Move aligned packed single precision floating-point
VMOVAPS xmm1, xmm2/m128
values from xmm2/mem to xmm1.
VEX.128.0F.WIG 29 /r
B
V/V
AVX
Move aligned packed single precision floating-point
VMOVAPS xmm2/m128, xmm1
values from xmm1 to xmm2/mem.
VEX.256.0F.WIG 28 /r
A
V/V
AVX
Move aligned packed single precision floating-point
VMOVAPS ymm1, ymm2/m256
values from ymm2/mem to ymm1.
VEX.256.0F.WIG 29 /r
B
V/V
AVX
Move aligned packed single precision floating-point
VMOVAPS ymm2/m256, ymm1
values from ymm1 to ymm2/mem.
EVEX.128.0F.W0 28 /r
C
V/V
(AVX512VL AND
Move aligned packed single precision floating-point
VMOVAPS xmm1 {k1}{z}, xmm2/m128
AVX512F) OR
values from xmm2/m128 to xmm1 using writemask
AVX10.1
k1.
EVEX.256.0F.W0 28 /r
C
V/V
(AVX512VL AND
Move aligned packed single precision floating-point
VMOVAPS ymm1 {k1}{z}, ymm2/m256
AVX512F) OR
values from ymm2/m256 to ymm1 using writemask
AVX10.1
k1.
EVEX.512.0F.W0 28 /r
C
V/V
AVX512F
Move aligned packed single precision floating-point
VMOVAPS zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
values from zmm2/m512 to zmm1 using writemask
k1.
EVEX.128.0F.W0 29 /r
D
V/V
(AVX512VL AND
Move aligned packed single precision floating-point
VMOVAPS xmm2/m128 {k1}{z}, xmm1
AVX512F) OR
values from xmm1 to xmm2/m128 using writemask
AVX10.1
k1.
EVEX.256.0F.W0 29 /r
D
V/V
(AVX512VL AND
Move aligned packed single precision floating-point
VMOVAPS ymm2/m256 {k1}{z}, ymm1
AVX512F) OR
values from ymm1 to ymm2/m256 using writemask
AVX10.1
k1.
EVEX.512.0F.W0 29 /r
D
V/V
AVX512F
Move aligned packed single precision floating-point
VMOVAPS zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
values from zmm1 to zmm2/m512 using writemask
k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
C
Full Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Full Mem
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Moves 4, 8 or 16 single precision floating-point values from the source operand (second operand) to the destination
operand (first operand). This instruction can be used to load an XMM, YMM or ZMM register from an 128-bit, 256-
bit or 512-bit memory location, to store the contents of an XMM, YMM or ZMM register into a 128-bit, 256-bit or
512-bit memory location, or to move data between two XMM, two YMM or two ZMM registers.
When the source or destination operand is a memory operand, the operand must be aligned on a 16-byte (128-bit
version), 32-byte (VEX.256 encoded version) or 64-byte (EVEX.512 encoded version) boundary or a general-
MOVAPS-Move Aligned Packed Single Precision Floating-Point Values
Vol. 2B
4-41
protection exception (#GP) will be generated. For EVEX.512 encoded versions, the operand must be aligned to the
size of the memory operand. To move single precision floating-point values to and from unaligned memory loca-
tions, use the VMOVUPS instruction.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
EVEX.512 encoded version:
Moves 512 bits of packed single precision floating-point values from the source operand (second operand) to the
destination operand (first operand). This instruction can be used to load a ZMM register from a 512-bit float32
memory location, to store the contents of a ZMM register into a float32 memory location, or to move data between
two ZMM registers. When the source or destination operand is a memory operand, the operand must be aligned on
a 64-byte boundary or a general-protection exception (#GP) will be generated. To move single precision floating-
point values to and from unaligned memory locations, use the VMOVUPS instruction.
VEX.256 and EVEX.256 encoded version:
Moves 256 bits of packed single precision floating-point values from the source operand (second operand) to the
destination operand (first operand). This instruction can be used to load a YMM register from a 256-bit memory
location, to store the contents of a YMM register into a 256-bit memory location, or to move data between two YMM
registers. When the source or destination operand is a memory operand, the operand must be aligned on a 32-byte
boundary or a general-protection exception (#GP) will be generated.
128-bit versions:
Moves 128 bits of packed single precision floating-point values from the source operand (second operand) to the
destination operand (first operand). This instruction can be used to load an XMM register from a 128-bit memory
location, to store the contents of an XMM register into a 128-bit memory location, or to move data between two
XMM registers. When the source or destination operand is a memory operand, the operand must be aligned on a
16-byte boundary or a general-protection exception (#GP) will be generated. To move single precision floating-
point values to and from unaligned memory locations, use the VMOVUPS instruction.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding ZMM destination register remain
unchanged.
(E)VEX.128 encoded version: Bits (MAXVL-1:128) of the destination ZMM register are zeroed.
Operation
VMOVAPS (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
MOVAPS-Move Aligned Packed Single Precision Floating-Point Values
Vol. 2B
4-42
VMOVAPS (EVEX Encoded Versions, Store Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
SRC[i+31:i]
ELSE *DEST[i+31:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVAPS (EVEX Encoded Versions, Load Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVAPS (VEX.256 Encoded Version, Load - and Register Copy)
DEST[255:0] := SRC[255:0]
DEST[MAXVL-1:256] := 0
VMOVAPS (VEX.256 Encoded Version, Store-Form)
DEST[255:0] := SRC[255:0]
VMOVAPS (VEX.128 Encoded Version, Load - and Register Copy)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] := 0
MOVAPS (128-bit Load- and Register-Copy- Form Legacy SSE Version)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] (Unmodified)
(V)MOVAPS (128-bit Store-Form Version)
DEST[127:0] := SRC[127:0]
MOVAPS-Move Aligned Packed Single Precision Floating-Point Values
Vol. 2B
4-43
Intel C/C++ Compiler Intrinsic Equivalent
VMOVAPS __m512 _mm512_load_ps( void * m);
VMOVAPS __m512 _mm512_mask_load_ps(__m512 s, __mmask16 k, void * m);
VMOVAPS __m512 _mm512_maskz_load_ps( __mmask16 k, void * m);
VMOVAPS void _mm512_store_ps( void * d, __m512 a);
VMOVAPS void _mm512_mask_store_ps( void * d, __mmask16 k, __m512 a);
VMOVAPS __m256 _mm256_mask_load_ps(__m256 a, __mmask8 k, void * s);
VMOVAPS __m256 _mm256_maskz_load_ps( __mmask8 k, void * s);
VMOVAPS void _mm256_mask_store_ps( void * d, __mmask8 k, __m256 a);
VMOVAPS __m128 _mm_mask_load_ps(__m128 a, __mmask8 k, void * s);
VMOVAPS __m128 _mm_maskz_load_ps( __mmask8 k, void * s);
VMOVAPS void _mm_mask_store_ps( void * d, __mmask8 k, __m128 a);
MOVAPS __m256 _mm256_load_ps (float * p);
MOVAPS void _mm256_store_ps(float * p, __m256 a);
MOVAPS __m128 _mm_load_ps (float * p);
MOVAPS void _mm_store_ps(float * p, __m128 a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Exceptions Type1.SSE in Table 2-18, “Type 1 Class Exception Conditions,”
additionally:
#UD
If VEX.vvvv != 1111B.
EVEX-encoded instruction, see Table 2-46, “Type E1 Class Exception Conditions.”
MOVAPS-Move Aligned Packed Single Precision Floating-Point Values
Vol. 2B
4-44
MOVBE-Move Data After Swapping Bytes
Opcode/
Op/
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
NFx 0F 38 F0 /r
RM
V/V
MOVBE
Reverse byte order in m16 and move to r16.
MOVBE r16, m16
NFx 0F 38 F0 /r
RM
V/V
MOVBE
Reverse byte order in m32 and move to r32.
MOVBE r32, m32
NFx REX.W + 0F 38 F0 /r
RM
V/N.E.
MOVBE
Reverse byte order in m64 and move to r64.
MOVBE r64, m64
NFx 0F 38 F1 /r
MR
V/V
MOVBE
Reverse byte order in r16 and move to m16.
MOVBE m16, r16
NFx 0F 38 F1 /r
MR
V/V
MOVBE
Reverse byte order in r32 and move to m32.
MOVBE m32, r32
NFx REX.W + 0F 38 F1 /r
MR
V/N.E.
MOVBE
Reverse byte order in r64 and move to m64.
MOVBE m64, r64
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
MR
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Performs a byte swap operation on the data copied from the second operand (source operand) and store the result
in the first operand (destination operand). The source operand can be a general-purpose register, or memory loca-
tion; the destination register can be a general-purpose register, or a memory location; however, both operands can
not be registers, and only one operand can be a memory location. Both operands must be the same size, which can
be a word, a doubleword or quadword.
The MOVBE instruction is provided for swapping the bytes on a read from memory or on a write to memory; thus
providing support for converting little-endian values to big-endian format and vice versa.
In 64-bit mode, the instruction's default operation size is 32 bits. Use of the REX.R prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. See the summary chart at the
beginning of this section for encoding data and limits.
Operation
TEMP := SRC
IF ( OperandSize = 16)
THEN
DEST[7:0] := TEMP[15:8];
DEST[15:8] := TEMP[7:0];
ELES IF
( OperandSize = 32)
DEST[7:0] := TEMP[31:24];
DEST[15:8] := TEMP[23:16];
DEST[23:16] := TEMP[15:8];
DEST[31:23] := TEMP[7:0];
ELSE IF ( OperandSize = 64)
DEST[7:0] := TEMP[63:56];
DEST[15:8] := TEMP[55:48];
MOVBE-Move Data After Swapping Bytes
Vol. 2B
4-45
DEST[23:16] := TEMP[47:40];
DEST[31:24] := TEMP[39:32];
DEST[39:32] := TEMP[31:24];
DEST[47:40] := TEMP[23:16];
DEST[55:48] := TEMP[15:8];
DEST[63:56] := TEMP[7:0];
FI;
Flags Affected
None.
Protected Mode Exceptions
#GP(0)
If the destination operand is in a non-writable segment.
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
If the DS, ES, FS, or GS register contains a NULL segment selector.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If CPUID.01H:ECX.MOVBE[22] = 0.
If the LOCK prefix is used.
Real-Address Mode Exceptions
#GP
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS
If a memory operand effective address is outside the SS segment limit.
#UD
If CPUID.01H:ECX.MOVBE[22] = 0.
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If CPUID.01H:ECX.MOVBE[22] = 0.
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#GP(0)
If the memory address is in a non-canonical form.
#SS(0)
If the stack address is in a non-canonical form.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If CPUID.01H:ECX.MOVBE[22] = 0.
If the LOCK prefix is used.
MOVBE-Move Data After Swapping Bytes
Vol. 2B
4-46
MOVDDUP-Replicate Double Precision Floating-Point Values
Opcode/
Op / En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
F2 0F 12 /r
A
V/V
SSE3
Move double precision floating-point value from
MOVDDUP xmm1, xmm2/m64
xmm2/m64 and duplicate into xmm1.
VEX.128.F2.0F.WIG 12 /r
A
V/V
AVX
Move double precision floating-point value from
VMOVDDUP xmm1, xmm2/m64
xmm2/m64 and duplicate into xmm1.
VEX.256.F2.0F.WIG 12 /r
A
V/V
AVX
Move even index double precision floating-point
VMOVDDUP ymm1, ymm2/m256
values from ymm2/mem and duplicate each element
into ymm1.
EVEX.128.F2.0F.W1 12 /r
B
V/V
(AVX512VL
Move double precision floating-point value from
VMOVDDUP xmm1 {k1}{z},
AND AVX512F)
xmm2/m64 and duplicate each element into xmm1
xmm2/m64
OR AVX10.1
subject to writemask k1.
EVEX.256.F2.0F.W1 12 /r
B
V/V
(AVX512VL
Move even index double precision floating-point
VMOVDDUP ymm1 {k1}{z},
AND AVX512F)
values from ymm2/m256 and duplicate each
ymm2/m256
OR AVX10.1
element into ymm1 subject to writemask k1.
EVEX.512.F2.0F.W1 12 /r
B
V/V
AVX512F
Move even index double precision floating-point
VMOVDDUP zmm1 {k1}{z},
OR AVX10.1
values from zmm2/m512 and duplicate each
zmm2/m512
element into zmm1 subject to writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
MOVDDUP
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
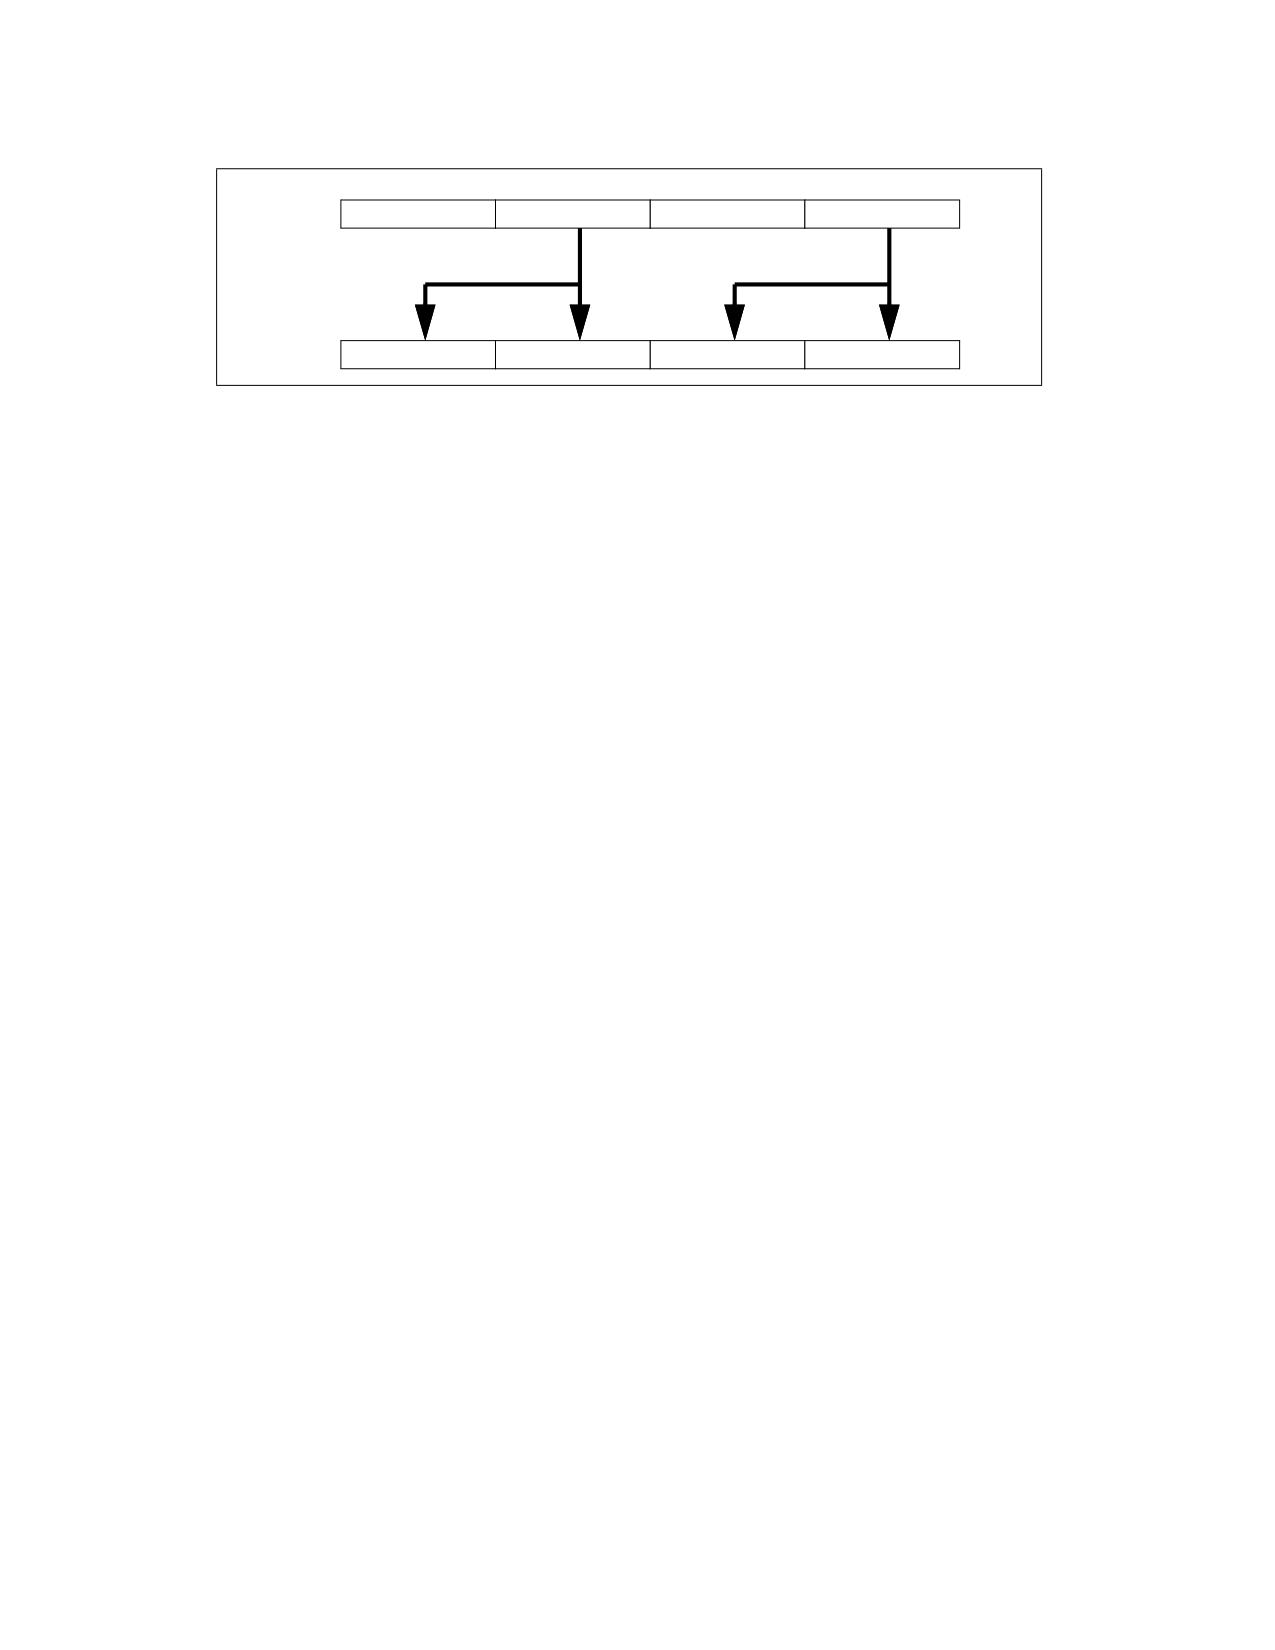
For 256-bit or higher versions: Duplicates even-indexed double precision floating-point values from the source
operand (the second operand) and into adjacent pair and store to the destination operand (the first operand).
For 128-bit versions: Duplicates the low double precision floating-point value from the source operand (the second
operand) and store to the destination operand (the first operand).
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding destination register are unchanged. The
source operand is XMM register or a 64-bit memory location.
VEX.128 and EVEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed. The source
operand is XMM register or a 64-bit memory location. The destination is updated conditionally under the writemask
for EVEX version.
VEX.256 and EVEX.256 encoded version: Bits (MAXVL-1:256) of the destination register are zeroed. The source
operand is YMM register or a 256-bit memory location. The destination is updated conditionally under the write-
mask for EVEX version.
EVEX.512 encoded version: The destination is updated according to the writemask. The source operand is ZMM
register or a 512-bit memory location.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
MOVDDUP-Replicate Double Precision Floating-Point Values
Vol. 2B
4-47
SRC
X3
X2
X1
X0
DEST
X2
X2
X0
X0
Figure 4-2. VMOVDDUP Operation
Operation
VMOVDDUP (EVEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256), (8, 512)
TMP_SRC[63:0] := SRC[63:0]
TMP_SRC[127:64] := SRC[63:0]
IF VL >= 256
TMP_SRC[191:128] := SRC[191:128]
TMP_SRC[255:192] := SRC[191:128]
FI;
IF VL >= 512
TMP_SRC[319:256] := SRC[319:256]
TMP_SRC[383:320] := SRC[319:256]
TMP_SRC[477:384] := SRC[477:384]
TMP_SRC[511:484] := SRC[477:384]
FI;
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := TMP_SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE
; zeroing-masking
DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDDUP (VEX.256 Encoded Version)
DEST[63:0] := SRC[63:0]
DEST[127:64] := SRC[63:0]
DEST[191:128] := SRC[191:128]
DEST[255:192] := SRC[191:128]
DEST[MAXVL-1:256] := 0
VMOVDDUP (VEX.128 Encoded Version)
DEST[63:0] := SRC[63:0]
DEST[127:64] := SRC[63:0]
DEST[MAXVL-1:128] := 0
MOVDDUP-Replicate Double Precision Floating-Point Values
Vol. 2B
4-48
MOVDDUP (128-bit Legacy SSE Version)
DEST[63:0] := SRC[63:0]
DEST[127:64] := SRC[63:0]
DEST[MAXVL-1:128] (Unmodified)
Intel C/C++ Compiler Intrinsic Equivalent
VMOVDDUP __m512d _mm512_movedup_pd( __m512d a);
VMOVDDUP __m512d _mm512_mask_movedup_pd(__m512d s, __mmask8 k, __m512d a);
VMOVDDUP __m512d _mm512_maskz_movedup_pd( __mmask8 k, __m512d a);
VMOVDDUP __m256d _mm256_mask_movedup_pd(__m256d s, __mmask8 k, __m256d a);
VMOVDDUP __m256d _mm256_maskz_movedup_pd( __mmask8 k, __m256d a);
VMOVDDUP __m128d _mm_mask_movedup_pd(__m128d s, __mmask8 k, __m128d a);
VMOVDDUP __m128d _mm_maskz_movedup_pd( __mmask8 k, __m128d a);
MOVDDUP __m256d _mm256_movedup_pd (__m256d a);
MOVDDUP __m128d _mm_movedup_pd (__m128d a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-54, “Type E5NF Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B or VEX.vvvv != 1111B.
MOVDDUP-Replicate Double Precision Floating-Point Values
Vol. 2B
4-49
MOVDIR64B-Move 64 Bytes as Direct Store
Opcode/
Op/
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
66 0F 38 F8 /r
A
V/V
MOVDIR64B
Move 64-bytes as direct-store with guaranteed 64-
byte write atomicity from the source memory operand
MOVDIR64B r16/r32/r64, m512
address to destination memory address specified as
offset to ES segment in the register operand.
Instruction Operand Encoding1
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Moves 64-bytes as direct-store with 64-byte write atomicity from source memory address to destination memory
address. The source operand is a normal memory operand. The destination operand is a memory location specified
in a general-purpose register. The register content is interpreted as an offset into ES segment without any segment
override. In 64-bit mode, the register operand width is 64-bits (32-bits with 67H prefix). Outside of 64-bit mode,
the register width is 32-bits when CS.D=1 (16-bits with 67H prefix), and 16-bits when CS.D=0 (32-bits with 67H
prefix). MOVDIR64B requires the destination address to be 64-byte aligned. No alignment restriction is enforced
for source operand.
MOVDIR64B first reads 64-bytes from the source memory address. It then performs a 64-byte direct-store opera-
tion to the destination address. The load operation follows normal read ordering based on source address memory-
type. The direct-store is implemented by using the write combining (WC) memory type protocol for writing data.
Using this protocol, the processor does not write the data into the cache hierarchy, nor does it fetch the corre-
sponding cache line from memory into the cache hierarchy. If the destination address is cached, the line is written-
back (if modified) and invalidated from the cache, before the direct-store.
Unlike stores with non-temporal hint which allow UC/WP memory-type for destination to override the non-temporal
hint, direct-stores always follow WC memory type protocol irrespective of destination address memory type
(including UC/WP types). Unlike WC stores and stores with non-temporal hint, direct-stores are eligible for imme-
diate eviction from the write-combining buffer, and thus not combined with younger stores (including direct-stores)
to the same address. Older WC and non-temporal stores held in the write-combing buffer may be combined with
younger direct stores to the same address. Direct stores are weakly ordered relative to other stores. Software that
desires stronger ordering should use a fencing instruction (MFENCE or SFENCE) before or after a direct store to
enforce the ordering desired.
There is no atomicity guarantee provided for the 64-byte load operation from source address, and processor imple-
mentations may use multiple load operations to read the 64-bytes. The 64-byte direct-store issued by MOVDIR64B
guarantees 64-byte write-completion atomicity. This means that the data arrives at the destination in a single
undivided 64-byte write transaction.
Availability of the MOVDIR64B instruction is indicated by the presence of the CPUID feature flag MOVDIR64B (bit
28 of the ECX register in leaf 07H, see “CPUID-CPU Identification” in the Intel® 64 and IA-32 Architectures Soft-
ware Developer’s Manual, Volume 2A).
Operation
DEST := SRC;
Intel C/C++ Compiler Intrinsic Equivalent
MOVDIR64B void _movdir64b(void *dst, const void* src)
1. The Mod field of the ModR/M byte cannot have value 11B.
MOVDIR64B-Move 64 Bytes as Direct Store
Vol. 2B
4-50
Protected Mode Exceptions
#GP(0)
For an illegal memory operand effective address in the CS, DS, ES, FS or GS segments.
If address in destination (register) operand is not aligned to a 64-byte boundary.
#SS(0)
For an illegal address in the SS segment.
#PF (fault-code)
For a page fault.
#UD
If CPUID.07H.00H:ECX.MOVDIR64B[28] = 0.
If LOCK prefix is used.
Real-Address Mode Exceptions
#GP
If any part of the operand lies outside the effective address space from 0 to FFFFH.
If address in destination (register) operand is not aligned to a 64-byte boundary.
#UD
If CPUID.07H.00H:ECX.MOVDIR64B[28] = 0.
If LOCK prefix is used.
Virtual-8086 Mode Exceptions
Same exceptions as in real address mode.
#PF (fault-code)
For a page fault.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#SS(0)
If memory address referencing the SS segment is in non-canonical form.
#GP(0)
If the memory address is in non-canonical form.
If address in destination (register) operand is not aligned to a 64-byte boundary.
#PF (fault-code)
For a page fault.
#UD
If CPUID.07H.00H:ECX.MOVDIR64B[28] = 0.
If LOCK prefix is used.
MOVDIR64B-Move 64 Bytes as Direct Store
Vol. 2B
4-51

MOVDIRI-Move Doubleword as Direct Store
Opcode/
Op/
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
NP 0F 38 F9 /r
A
V/V
MOVDIRI
Move doubleword from r32 to m32 using direct store.
MOVDIRI m32, r32
NP REX.W + 0F 38 F9 /r
A
V/N.E.
MOVDIRI
Move quadword from r64 to m64 using direct store.
MOVDIRI m64, r64
Instruction Operand Encoding1
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Moves the doubleword integer in the source operand (second operand) to the destination operand (first operand)
using a direct-store operation. The source operand is a general purpose register. The destination operand is a 32-
bit memory location. In 64-bit mode, the instruction’s default operation size is 32 bits. Use of the REX.R prefix
permits access to additional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. See
summary chart at the beginning of this section for encoding data and limits.
The direct-store is implemented by using write combining (WC) memory type protocol for writing data. Using this
protocol, the processor does not write the data into the cache hierarchy, nor does it fetch the corresponding cache
line from memory into the cache hierarchy. If the destination address is cached, the line is written-back (if modi-
fied) and invalidated from the cache, before the direct-store. Unlike stores with non-temporal hint that allow
uncached (UC) and write-protected (WP) memory-type for the destination to override the non-temporal hint,
direct-stores always follow WC memory type protocol irrespective of the destination address memory type
(including UC and WP types).
Unlike WC stores and stores with non-temporal hint, direct-stores are eligible for immediate eviction from the
write-combining buffer, and thus not combined with younger stores (including direct-stores) to the same address.
Older WC and non-temporal stores held in the write-combing buffer may be combined with younger direct stores
to the same address. Direct stores are weakly ordered relative to other stores. Software that desires stronger
ordering should use a fencing instruction (MFENCE or SFENCE) before or after a direct store to enforce the ordering
desired.
Direct-stores issued by MOVDIRI to a destination aligned to a 4-byte boundary (8-byte boundary if used with
REX.W prefix) guarantee 4-byte (8-byte with REX.W prefix) write-completion atomicity. This means that the data
arrives at the destination in a single undivided 4-byte (or 8-byte) write transaction. If the destination is not aligned
for the write size, the direct-stores issued by MOVDIRI are split and arrive at the destination in two parts. Each part
of such split direct-store will not merge with younger stores but can arrive at the destination in either order. Avail-
ability of the MOVDIRI instruction is indicated by the presence of the CPUID feature flag MOVDIRI (bit 27 of the
ECX register in leaf 07H, see “CPUID-CPU Identification” in the Intel® 64 and IA-32 Architectures Software Devel-
oper’s Manual, Volume 2A).
Operation
DEST := SRC;
Intel C/C++ Compiler Intrinsic Equivalent
MOVDIRI void _directstoreu_u32(void *dst, uint32_t val)
MOVDIRI void _directstoreu_u64(void *dst, uint64_t val)
1. The Mod field of the ModR/M byte cannot have value 11B.
MOVDIRI-Move Doubleword as Direct Store
Vol. 2B
4-52
Protected Mode Exceptions
#GP(0)
For an illegal memory operand effective address in the CS, DS, ES, FS or GS segments.
#SS(0)
For an illegal address in the SS segment.
#PF (fault-code)
For a page fault.
#UD
If CPUID.07H.00H:ECX.MOVDIRI[27] = 0.
If LOCK prefix or operand-size (66H) prefix is used.
#AC
If alignment checking is enabled and an unaligned memory reference made while in current
privilege level 3.
Real-Address Mode Exceptions
#GP
If any part of the operand lies outside the effective address space from 0 to FFFFH.
#UD
If CPUID.07H.00H:ECX.MOVDIRI[27] = 0.
If LOCK prefix or operand-size (66H) prefix is used.
Virtual-8086 Mode Exceptions
Same exceptions as in real address mode.
#PF (fault-code)
For a page fault.
#AC
If alignment checking is enabled and an unaligned memory reference made while in current
privilege level 3.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#SS(0)
If memory address referencing the SS segment is in non-canonical form.
#GP(0)
If the memory address is in non-canonical form.
#PF (fault-code)
For a page fault.
#UD
If CPUID.07H.00H:ECX.MOVDIRI[27] = 0.
If LOCK prefix or operand-size (66H) prefix is used.
#AC
If alignment checking is enabled and an unaligned memory reference made while in current
privilege level 3.
MOVDIRI-Move Doubleword as Direct Store
Vol. 2B
4-53

MOVD/MOVQ-Move Doubleword/Move Quadword
Opcode/
Op/ En
64/32-bit
CPUID
Description
Instruction
Mode
Feature Flag
NP 0F 6E /r
A
V/V
MMX
Move doubleword from r/m32 to mm.
MOVD mm, r/m32
NP REX.W + 0F 6E /r
A
V/N.E.
MMX
Move quadword from r/m64 to mm.
MOVQ mm, r/m64
NP 0F 7E /r
B
V/V
MMX
Move doubleword from mm to r/m32.
MOVD r/m32, mm
NP REX.W + 0F 7E /r
B
V/N.E.
MMX
Move quadword from mm to r/m64.
MOVQ r/m64, mm
66 0F 6E /r
A
V/V
SSE2
Move doubleword from r/m32 to xmm.
MOVD xmm, r/m32
66 REX.W 0F 6E /r
A
V/N.E.
SSE2
Move quadword from r/m64 to xmm.
MOVQ xmm, r/m64
66 0F 7E /r
B
V/V
SSE2
Move doubleword from xmm register to r/m32.
MOVD r/m32, xmm
66 REX.W 0F 7E /r
B
V/N.E.
SSE2
Move quadword from xmm register to r/m64.
MOVQ r/m64, xmm
VEX.128.66.0F.W0 6E /
A
V/V
AVX
Move doubleword from r/m32 to xmm1.
VMOVD xmm1, r32/m32
VEX.128.66.0F.W1 6E /r
A
V/N.E.1
AVX
Move quadword from r/m64 to xmm1.
VMOVQ xmm1, r64/m64
VEX.128.66.0F.W0 7E /r
B
V/V
AVX
Move doubleword from xmm1 register to r/m32.
VMOVD r32/m32, xmm1
VEX.128.66.0F.W1 7E /r
B
V/N.E.1
AVX
Move quadword from xmm1 register to r/m64.
VMOVQ r64/m64, xmm1
EVEX.128.66.0F.W0 6E /r
C
V/V
AVX512F
Move doubleword from r/m32 to xmm1.
VMOVD xmm1, r32/m32
OR AVX10.1
EVEX.128.66.0F.W1 6E /r
C
V/N.E.
AVX512F
Move quadword from r/m64 to xmm1.
VMOVQ xmm1, r64/m64
OR AVX10.1
EVEX.128.66.0F.W0 7E /r
D
V/V
AVX512F
Move doubleword from xmm1 register to r/m32.
VMOVD r32/m32, xmm1
OR AVX10.1
EVEX.128.66.0F.W1 7E /r
D
V/N.E.1
AVX512F
Move quadword from xmm1 register to r/m64.
VMOVQ r64/m64, xmm1
OR AVX10.1
NOTES:
1. For this specific instruction, VEX.W/EVEX.W in non-64 bit is ignored; the instruction behaves as if the W0 version is used.
MOVD/MOVQ-Move Doubleword/Move Quadword
Vol. 2B
4-54
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
C
Tuple1 Scalar
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Tuple1 Scalar
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Copies a doubleword from the source operand (second operand) to the destination operand (first operand). The
source and destination operands can be general-purpose registers, MMX technology registers, XMM registers, or
32-bit memory locations. This instruction can be used to move a doubleword to and from the low doubleword of an
MMX technology register and a general-purpose register or a 32-bit memory location, or to and from the low
doubleword of an XMM register and a general-purpose register or a 32-bit memory location. The instruction cannot
be used to transfer data between MMX technology registers, between XMM registers, between general-purpose
registers, or between memory locations.
When the destination operand is an MMX technology register, the source operand is written to the low doubleword
of the register, and the register is zero-extended to 64 bits. When the destination operand is an XMM register, the
source operand is written to the low doubleword of the register, and the register is zero-extended to 128 bits.
In 64-bit mode, the instruction’s default operation size is 32 bits. Use of the REX.B prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. See the summary chart at the
beginning of this section for encoding data and limits.
MOVD/Q with XMM destination:
Moves a dword/qword integer from the source operand and stores it in the low 32/64-bits of the destination XMM
register. The upper bits of the destination are zeroed. The source operand can be a 32/64-bit register or 32/64-bit
memory location.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding YMM destination register remain
unchanged. Qword operation requires the use of REX.W=1.
VEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed. Qword operation requires the
use of VEX.W=1.
EVEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed. Qword operation requires
the use of EVEX.W=1.
MOVD/Q with 32/64 reg/mem destination:
Stores the low dword/qword of the source XMM register to 32/64-bit memory location or general-purpose register.
Qword operation requires the use of REX.W=1, VEX.W=1, or EVEX.W=1.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
If VMOVD or VMOVQ is encoded with VEX.L= 1, an attempt to execute the instruction encoded with VEX.L= 1 will
cause an #UD exception.
Operation
MOVD (When Destination Operand is an MMX Technology Register)
DEST[31:0] := SRC;
DEST[63:32] := 00000000H;
MOVD (When Destination Operand is an XMM Register)
DEST[31:0] := SRC;
DEST[127:32] := 000000000000000000000000H;
DEST[MAXVL-1:128] (Unmodified)
MOVD (When Source Operand is an MMX Technology or XMM Register)
DEST := SRC[31:0];
MOVD/MOVQ-Move Doubleword/Move Quadword
Vol. 2B
4-55
VMOVD (VEX-Encoded Version when Destination is an XMM Register)
DEST[31:0] := SRC[31:0]
DEST[MAXVL-1:32] := 0
MOVQ (When Destination Operand is an XMM Register)
DEST[63:0] := SRC[63:0];
DEST[127:64] := 0000000000000000H;
DEST[MAXVL-1:128] (Unmodified)
MOVQ (When Destination Operand is r/m64)
DEST[63:0] := SRC[63:0];
MOVQ (When Source Operand is an XMM Register or r/m64)
DEST := SRC[63:0];
VMOVQ (VEX-Encoded Version When Destination is an XMM Register)
DEST[63:0] := SRC[63:0]
DEST[MAXVL-1:64] := 0
VMOVD (EVEX-Encoded Version When Destination is an XMM Register)
DEST[31:0] := SRC[31:0]
DEST[MAXVL-1:32] := 0
VMOVQ (EVEX-Encoded Version When Destination is an XMM Register)
DEST[63:0] := SRC[63:0]
DEST[MAXVL-1:64] := 0
Intel C/C++ Compiler Intrinsic Equivalent
MOVD __m64 _mm_cvtsi32_si64 (int i )
MOVD int _mm_cvtsi64_si32 ( __m64m )
MOVD __m128i _mm_cvtsi32_si128 (int a)
MOVD int _mm_cvtsi128_si32 ( __m128i a)
MOVQ __int64 _mm_cvtsi128_si64(__m128i);
MOVQ __m128i _mm_cvtsi64_si128(__int64);
VMOVD __m128i _mm_cvtsi32_si128( int);
VMOVD int _mm_cvtsi128_si32( __m128i );
VMOVQ __m128i _mm_cvtsi64_si128 (__int64);
VMOVQ __int64 _mm_cvtsi128_si64(__m128i );
VMOVQ __m128i _mm_loadl_epi64( __m128i * s);
VMOVQ void _mm_storel_epi64( __m128i * d, __m128i s);
Flags Affected
None.
SIMD Floating-Point Exceptions
None.
MOVD/MOVQ-Move Doubleword/Move Quadword
Vol. 2B
4-56
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
Additionally:
#UD
If VEX.L = 1.
If VEX.vvvv != 1111B or EVEX.vvvv != 1111B.
MOVD/MOVQ-Move Doubleword/Move Quadword
Vol. 2B
4-57
MOVDQ2Q-Move Quadword from XMM to MMX Technology Register
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
F2 0F D6 /r
MOVDQ2Q mm, xmm
RM
Valid
Valid
Move low quadword from xmm to mmx register.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Moves the low quadword from the source operand (second operand) to the destination operand (first operand). The
source operand is an XMM register and the destination operand is an MMX technology register.
This instruction causes a transition from x87 FPU to MMX technology operation (that is, the x87 FPU top-of-stack
pointer is set to 0 and the x87 FPU tag word is set to all 0s [valid]). If this instruction is executed while an x87 FPU
floating-point exception is pending, the exception is handled before the MOVDQ2Q instruction is executed.
In 64-bit mode, use of the REX.R prefix permits this instruction to access additional registers (XMM8-XMM15).
Operation
DEST := SRC[63:0];
Intel C/C++ Compiler Intrinsic Equivalent
MOVDQ2Q __m64 _mm_movepi64_pi64 ( __m128i a)
SIMD Floating-Point Exceptions
None.
Protected Mode Exceptions
#NM
If CR0.TS[bit 3] = 1.
#UD
If CR0.EM[bit 2] = 1.
If CR4.OSFXSR[bit 9] = 0.
If CPUID.01H:EDX.SSE2[26] = 0.
If the LOCK prefix is used.
#MF
If there is a pending x87 FPU exception.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
MOVDQ2Q-Move Quadword from XMM to MMX Technology Register
Vol. 2B
4-58
MOVDQA,VMOVDQA32/64-Move Aligned Packed Integer Values
Opcode/
Op/En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
66 0F 6F /r
A
V/V
SSE2
Move aligned packed integer values from
MOVDQA xmm1, xmm2/m128
xmm2/mem to xmm1.
66 0F 7F /r
B
V/V
SSE2
Move aligned packed integer values from
MOVDQA xmm2/m128, xmm1
xmm1 to xmm2/mem.
VEX.128.66.0F.WIG 6F /r
A
V/V
AVX
Move aligned packed integer values from
VMOVDQA xmm1, xmm2/m128
xmm2/mem to xmm1.
VEX.128.66.0F.WIG 7F /r
B
V/V
AVX
Move aligned packed integer values from
VMOVDQA xmm2/m128, xmm1
xmm1 to xmm2/mem.
VEX.256.66.0F.WIG 6F /r
A
V/V
AVX
Move aligned packed integer values from
VMOVDQA ymm1, ymm2/m256
ymm2/mem to ymm1.
VEX.256.66.0F.WIG 7F /r
B
V/V
AVX
Move aligned packed integer values from
VMOVDQA ymm2/m256, ymm1
ymm1 to ymm2/mem.
EVEX.128.66.0F.W0 6F /r
C
V/V
(AVX512VL
Move aligned packed doubleword integer
VMOVDQA32 xmm1 {k1}{z},
AND AVX512F)
values from xmm2/m128 to xmm1 using
xmm2/m128
OR AVX10.1
writemask k1.
EVEX.256.66.0F.W0 6F /r
C
V/V
(AVX512VL
Move aligned packed doubleword integer
VMOVDQA32 ymm1 {k1}{z},
AND AVX512F)
values from ymm2/m256 to ymm1 using
ymm2/m256
OR AVX10.1
writemask k1.
EVEX.512.66.0F.W0 6F /r
C
V/V
AVX512F
Move aligned packed doubleword integer
VMOVDQA32 zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
values from zmm2/m512 to zmm1 using
writemask k1.
EVEX.128.66.0F.W0 7F /r
D
V/V
(AVX512VL
Move aligned packed doubleword integer
VMOVDQA32 xmm2/m128 {k1}{z},
AND AVX512F)
values from xmm1 to xmm2/m128 using
xmm1
OR AVX10.1
writemask k1.
EVEX.256.66.0F.W0 7F /r
D
V/V
(AVX512VL
Move aligned packed doubleword integer
VMOVDQA32 ymm2/m256 {k1}{z},
AND AVX512F)
values from ymm1 to ymm2/m256 using
ymm1
OR AVX10.1
writemask k1.
EVEX.512.66.0F.W0 7F /r
D
V/V
AVX512F
Move aligned packed doubleword integer
VMOVDQA32 zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
values from zmm1 to zmm2/m512 using
writemask k1.
EVEX.128.66.0F.W1 6F /r
C
V/V
(AVX512VL
Move aligned packed quadword integer values
VMOVDQA64 xmm1 {k1}{z},
AND AVX512F)
from xmm2/m128 to xmm1 using writemask
xmm2/m128
OR AVX10.1
k1.
EVEX.256.66.0F.W1 6F /r
C
V/V
(AVX512VL
Move aligned packed quadword integer values
VMOVDQA64 ymm1 {k1}{z},
AND AVX512F)
from ymm2/m256 to ymm1 using writemask
ymm2/m256
OR AVX10.1
k1.
EVEX.512.66.0F.W1 6F /r
C
V/V
AVX512F
Move aligned packed quadword integer values
VMOVDQA64 zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
from zmm2/m512 to zmm1 using writemask
k1.
EVEX.128.66.0F.W1 7F /r
D
V/V
(AVX512VL
Move aligned packed quadword integer values
VMOVDQA64 xmm2/m128 {k1}{z},
AND AVX512F)
from xmm1 to xmm2/m128 using writemask
xmm1
OR AVX10.1
k1.
EVEX.256.66.0F.W1 7F /r
D
V/V
(AVX512VL
Move aligned packed quadword integer values
VMOVDQA64 ymm2/m256 {k1}{z},
AND AVX512F)
from ymm1 to ymm2/m256 using writemask
ymm1
OR AVX10.1
k1.
EVEX.512.66.0F.W1 7F /r
D
V/V
AVX512F
Move aligned packed quadword integer values
VMOVDQA64 zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
from zmm1 to zmm2/m512 using writemask
k1.
MOVDQA,VMOVDQA32/64-Move Aligned Packed Integer Values
Vol. 2B
4-59
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
C
Full Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Full Mem
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
EVEX encoded versions:
Moves 128, 256 or 512 bits of packed doubleword/quadword integer values from the source operand (the second
operand) to the destination operand (the first operand). This instruction can be used to load a vector register from
an int32/int64 memory location, to store the contents of a vector register into an int32/int64 memory location, or
to move data between two ZMM registers. When the source or destination operand is a memory operand, the
operand must be aligned on a 16 (EVEX.128)/32(EVEX.256)/64(EVEX.512)-byte boundary or a general-protection
exception (#GP) will be generated. To move integer data to and from unaligned memory locations, use the
VMOVDQU instruction.
The destination operand is updated at 32-bit (VMOVDQA32) or 64-bit (VMOVDQA64) granularity according to the
writemask.
VEX.256 encoded version:
Moves 256 bits of packed integer values from the source operand (second operand) to the destination operand
(first operand). This instruction can be used to load a YMM register from a 256-bit memory location, to store the
contents of a YMM register into a 256-bit memory location, or to move data between two YMM registers.
When the source or destination operand is a memory operand, the operand must be aligned on a 32-byte boundary
or a general-protection exception (#GP) will be generated. To move integer data to and from unaligned memory
locations, use the VMOVDQU instruction. Bits (MAXVL-1:256) of the destination register are zeroed.
128-bit versions:
Moves 128 bits of packed integer values from the source operand (second operand) to the destination operand
(first operand). This instruction can be used to load an XMM register from a 128-bit memory location, to store the
contents of an XMM register into a 128-bit memory location, or to move data between two XMM registers.
When the source or destination operand is a memory operand, the operand must be aligned on a 16-byte boundary
or a general-protection exception (#GP) will be generated. To move integer data to and from unaligned memory
locations, use the VMOVDQU instruction.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding ZMM destination register remain
unchanged.
VEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed.
MOVDQA,VMOVDQA32/64-Move Aligned Packed Integer Values
Vol. 2B
4-60
Operation
VMOVDQA32 (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQA32 (EVEX Encoded Versions, Store-Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE *DEST[i+31:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVDQA32 (EVEX Encoded Versions, Load-Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQA64 (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
MOVDQA,VMOVDQA32/64-Move Aligned Packed Integer Values
Vol. 2B
4-61
DEST[MAXVL-1:VL] := 0
VMOVDQA64 (EVEX Encoded Versions, Store-Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE *DEST[i+63:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVDQA64 (EVEX Encoded Versions, Load-Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQA (VEX.256 Encoded Version, Load - and Register Copy)
DEST[255:0] := SRC[255:0]
DEST[MAXVL-1:256] := 0
VMOVDQA (VEX.256 Encoded Version, Store-Form)
DEST[255:0] := SRC[255:0]
VMOVDQA (VEX.128 Encoded Version)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] := 0
VMOVDQA (128-bit Load- and Register-Copy- Form Legacy SSE Version)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] (Unmodified)
(V)MOVDQA (128-bit Store-Form Version)
DEST[127:0] := SRC[127:0]
MOVDQA,VMOVDQA32/64-Move Aligned Packed Integer Values
Vol. 2B
4-62
Intel C/C++ Compiler Intrinsic Equivalent
VMOVDQA32 __m512i _mm512_load_epi32( void * sa);
VMOVDQA32 __m512i _mm512_mask_load_epi32(__m512i s, __mmask16 k, void * sa);
VMOVDQA32 __m512i _mm512_maskz_load_epi32( __mmask16 k, void * sa);
VMOVDQA32 void _mm512_store_epi32(void * d, __m512i a);
VMOVDQA32 void _mm512_mask_store_epi32(void * d, __mmask16 k, __m512i a);
VMOVDQA32 __m256i _mm256_mask_load_epi32(__m256i s, __mmask8 k, void * sa);
VMOVDQA32 __m256i _mm256_maskz_load_epi32( __mmask8 k, void * sa);
VMOVDQA32 void _mm256_store_epi32(void * d, __m256i a);
VMOVDQA32 void _mm256_mask_store_epi32(void * d, __mmask8 k, __m256i a);
VMOVDQA32 __m128i _mm_mask_load_epi32(__m128i s, __mmask8 k, void * sa);
VMOVDQA32 __m128i _mm_maskz_load_epi32( __mmask8 k, void * sa);
VMOVDQA32 void _mm_store_epi32(void * d, __m128i a);
VMOVDQA32 void _mm_mask_store_epi32(void * d, __mmask8 k, __m128i a);
VMOVDQA64 __m512i _mm512_load_epi64( void * sa);
VMOVDQA64 __m512i _mm512_mask_load_epi64(__m512i s, __mmask8 k, void * sa);
VMOVDQA64 __m512i _mm512_maskz_load_epi64( __mmask8 k, void * sa);
VMOVDQA64 void _mm512_store_epi64(void * d, __m512i a);
VMOVDQA64 void _mm512_mask_store_epi64(void * d, __mmask8 k, __m512i a);
VMOVDQA64 __m256i _mm256_mask_load_epi64(__m256i s, __mmask8 k, void * sa);
VMOVDQA64 __m256i _mm256_maskz_load_epi64( __mmask8 k, void * sa);
VMOVDQA64 void _mm256_store_epi64(void * d, __m256i a);
VMOVDQA64 void _mm256_mask_store_epi64(void * d, __mmask8 k, __m256i a);
VMOVDQA64 __m128i _mm_mask_load_epi64(__m128i s, __mmask8 k, void * sa);
VMOVDQA64 __m128i _mm_maskz_load_epi64( __mmask8 k, void * sa);
VMOVDQA64 void _mm_store_epi64(void * d, __m128i a);
VMOVDQA64 void _mm_mask_store_epi64(void * d, __mmask8 k, __m128i a);
MOVDQA void __m256i _mm256_load_si256 (__m256i * p);
MOVDQA _mm256_store_si256(_m256i *p, __m256i a);
MOVDQA __m128i _mm_load_si128 (__m128i * p);
MOVDQA void _mm_store_si128(__m128i *p, __m128i a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Exceptions Type1.SSE2 in Table 2-18, “Type 1 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-46, “Type E1 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B or VEX.vvvv != 1111B.
MOVDQA,VMOVDQA32/64-Move Aligned Packed Integer Values
Vol. 2B
4-63
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Opcode/
Op/En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
F3 0F 6F /r
A
V/V
SSE2
Move unaligned packed integer values
MOVDQU xmm1, xmm2/m128
from xmm2/m128 to xmm1.
F3 0F 7F /r
B
V/V
SSE2
Move unaligned packed integer values
MOVDQU xmm2/m128, xmm1
from xmm1 to xmm2/m128.
VEX.128.F3.0F.WIG 6F /r
A
V/V
AVX
Move unaligned packed integer values
VMOVDQU xmm1, xmm2/m128
from xmm2/m128 to xmm1.
VEX.128.F3.0F.WIG 7F /r
B
V/V
AVX
Move unaligned packed integer values
VMOVDQU xmm2/m128, xmm1
from xmm1 to xmm2/m128.
VEX.256.F3.0F.WIG 6F /r
A
V/V
AVX
Move unaligned packed integer values
VMOVDQU ymm1, ymm2/m256
from ymm2/m256 to ymm1.
VEX.256.F3.0F.WIG 7F /r
B
V/V
AVX
Move unaligned packed integer values
VMOVDQU ymm2/m256, ymm1
from ymm1 to ymm2/m256.
EVEX.128.F2.0F.W0 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed byte integer values
VMOVDQU8 xmm1 {k1}{z}, xmm2/m128
AVX512BW) OR
from xmm2/m128 to xmm1 using
AVX10.1
writemask k1.
EVEX.256.F2.0F.W0 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed byte integer values
VMOVDQU8 ymm1 {k1}{z}, ymm2/m256
AVX512BW) OR
from ymm2/m256 to ymm1 using
AVX10.1
writemask k1.
EVEX.512.F2.0F.W0 6F /r
C
V/V
AVX512BW
Move unaligned packed byte integer values
VMOVDQU8 zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
from zmm2/m512 to zmm1 using
writemask k1.
EVEX.128.F2.0F.W0 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed byte integer values
VMOVDQU8 xmm2/m128 {k1}{z}, xmm1
AVX512BW) OR
from xmm1 to xmm2/m128 using
AVX10.1
writemask k1.
EVEX.256.F2.0F.W0 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed byte integer values
VMOVDQU8 ymm2/m256 {k1}{z}, ymm1
AVX512BW) OR
from ymm1 to ymm2/m256 using
AVX10.1
writemask k1.
EVEX.512.F2.0F.W0 7F /r
D
V/V
AVX512BW
Move unaligned packed byte integer values
VMOVDQU8 zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
from zmm1 to zmm2/m512 using
writemask k1.
EVEX.128.F2.0F.W1 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed word integer
VMOVDQU16 xmm1 {k1}{z}, xmm2/m128
AVX512BW) OR
values from xmm2/m128 to xmm1 using
AVX10.1
writemask k1.
EVEX.256.F2.0F.W1 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed word integer
VMOVDQU16 ymm1 {k1}{z}, ymm2/m256
AVX512BW) OR
values from ymm2/m256 to ymm1 using
AVX10.1
writemask k1.
EVEX.512.F2.0F.W1 6F /r
C
V/V
AVX512BW
Move unaligned packed word integer
VMOVDQU16 zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
values from zmm2/m512 to zmm1 using
writemask k1.
EVEX.128.F2.0F.W1 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed word integer
VMOVDQU16 xmm2/m128 {k1}{z}, xmm1
AVX512BW) OR
values from xmm1 to xmm2/m128 using
AVX10.1
writemask k1.
EVEX.256.F2.0F.W1 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed word integer
VMOVDQU16 ymm2/m256 {k1}{z}, ymm1
AVX512BW) OR
values from ymm1 to ymm2/m256 using
AVX10.1
writemask k1.
EVEX.512.F2.0F.W1 7F /r
D
V/V
AVX512BW
Move unaligned packed word integer
VMOVDQU16 zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
values from zmm1 to zmm2/m512 using
writemask k1.
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-64
Opcode/
Op/En
64/32 bit
CPUID Feature
Description
Instruction
Mode
Flag
Support
EVEX.128.F3.0F.W0 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed doubleword
VMOVDQU32 xmm1 {k1}{z}, xmm2/mm128
AVX512F) OR
integer values from xmm2/m128 to xmm1
AVX10.1
using writemask k1.
EVEX.256.F3.0F.W0 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed doubleword
VMOVDQU32 ymm1 {k1}{z}, ymm2/m256
AVX512F) OR
integer values from ymm2/m256 to ymm1
AVX10.1
using writemask k1.
EVEX.512.F3.0F.W0 6F /r
C
V/V
AVX512F
Move unaligned packed doubleword
VMOVDQU32 zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
integer values from zmm2/m512 to zmm1
using writemask k1.
EVEX.128.F3.0F.W0 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed doubleword
VMOVDQU32 xmm2/m128 {k1}{z}, xmm1
AVX512F) OR
integer values from xmm1 to xmm2/m128
AVX10.1
using writemask k1.
EVEX.256.F3.0F.W0 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed doubleword
VMOVDQU32 ymm2/m256 {k1}{z}, ymm1
AVX512F) OR
integer values from ymm1 to ymm2/m256
AVX10.1
using writemask k1.
EVEX.512.F3.0F.W0 7F /r
D
V/V
AVX512F
Move unaligned packed doubleword
VMOVDQU32 zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
integer values from zmm1 to zmm2/m512
using writemask k1.
EVEX.128.F3.0F.W1 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed quadword integer
VMOVDQU64 xmm1 {k1}{z}, xmm2/m128
AVX512F) OR
values from xmm2/m128 to xmm1 using
AVX10.1
writemask k1.
EVEX.256.F3.0F.W1 6F /r
C
V/V
(AVX512VL AND
Move unaligned packed quadword integer
VMOVDQU64 ymm1 {k1}{z}, ymm2/m256
AVX512F) OR
values from ymm2/m256 to ymm1 using
AVX10.1
writemask k1.
EVEX.512.F3.0F.W1 6F /r
C
V/V
AVX512F
Move unaligned packed quadword integer
VMOVDQU64 zmm1 {k1}{z}, zmm2/m512
OR AVX10.1
values from zmm2/m512 to zmm1 using
writemask k1.
EVEX.128.F3.0F.W1 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed quadword integer
VMOVDQU64 xmm2/m128 {k1}{z}, xmm1
AVX512F) OR
values from xmm1 to xmm2/m128 using
AVX10.1
writemask k1.
EVEX.256.F3.0F.W1 7F /r
D
V/V
(AVX512VL AND
Move unaligned packed quadword integer
VMOVDQU64 ymm2/m256 {k1}{z}, ymm1
AVX512F) OR
values from ymm1 to ymm2/m256 using
AVX10.1
writemask k1.
EVEX.512.F3.0F.W1 7F /r
D
V/V
AVX512F
Move unaligned packed quadword integer
VMOVDQU64 zmm2/m512 {k1}{z}, zmm1
OR AVX10.1
values from zmm1 to zmm2/m512 using
writemask k1.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
C
Full Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
D
Full Mem
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instructions will #UD.
EVEX encoded versions:
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-65
Moves 128, 256 or 512 bits of packed byte/word/doubleword/quadword integer values from the source operand
(the second operand) to the destination operand (first operand). This instruction can be used to load a vector
register from a memory location, to store the contents of a vector register into a memory location, or to move data
between two vector registers.
The destination operand is updated at 8-bit (VMOVDQU8), 16-bit (VMOVDQU16), 32-bit (VMOVDQU32), or 64-bit
(VMOVDQU64) granularity according to the writemask.
VEX.256 encoded version:
Moves 256 bits of packed integer values from the source operand (second operand) to the destination operand
(first operand). This instruction can be used to load a YMM register from a 256-bit memory location, to store the
contents of a YMM register into a 256-bit memory location, or to move data between two YMM registers.
Bits (MAXVL-1:256) of the destination register are zeroed.
128-bit versions:
Moves 128 bits of packed integer values from the source operand (second operand) to the destination operand
(first operand). This instruction can be used to load an XMM register from a 128-bit memory location, to store the
contents of an XMM register into a 128-bit memory location, or to move data between two XMM registers.
128-bit Legacy SSE version: Bits (MAXVL-1:128) of the corresponding destination register remain unchanged.
When the source or destination operand is a memory operand, the operand may be unaligned to any alignment
without causing a general-protection exception (#GP) to be generated
VEX.128 encoded version: Bits (MAXVL-1:128) of the destination register are zeroed.
Operation
VMOVDQU8 (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[i+7:i] := SRC[i+7:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE DEST[i+7:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-66
VMOVDQU8 (EVEX Encoded Versions, Store-Form)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[i+7:i] :=
SRC[i+7:i]
ELSE *DEST[i+7:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVDQU8 (EVEX Encoded Versions, Load-Form)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1
i := j * 8
IF k1[j] OR *no writemask*
THEN DEST[i+7:i] := SRC[i+7:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+7:i] remains unchanged*
ELSE DEST[i+7:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQU16 (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SRC[i+15:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE DEST[i+15:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQU16 (EVEX Encoded Versions, Store-Form)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] :=
SRC[i+15:i]
ELSE *DEST[i+15:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-67
VMOVDQU16 (EVEX Encoded Versions, Load-Form)
(KL, VL) = (8, 128), (16, 256), (32, 512)
FOR j := 0 TO KL-1
i := j * 16
IF k1[j] OR *no writemask*
THEN DEST[i+15:i] := SRC[i+15:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+15:i] remains unchanged*
ELSE DEST[i+15:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQU32 (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQU32 (EVEX Encoded Versions, Store-Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] :=
SRC[i+31:i]
ELSE *DEST[i+31:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVDQU32 (EVEX Encoded Versions, Load-Form)
(KL, VL) = (4, 128), (8, 256), (16, 512)
FOR j := 0 TO KL-1
i := j * 32
IF k1[j] OR *no writemask*
THEN DEST[i+31:i] := SRC[i+31:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+31:i] remains unchanged*
ELSE DEST[i+31:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-68
DEST[MAXVL-1:VL] := 0
VMOVDQU64 (EVEX Encoded Versions, Register-Copy Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQU64 (EVEX Encoded Versions, Store-Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE *DEST[i+63:i] remains unchanged*
; merging-masking
FI;
ENDFOR;
VMOVDQU64 (EVEX Encoded Versions, Load-Form)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1
i := j * 64
IF k1[j] OR *no writemask*
THEN DEST[i+63:i] := SRC[i+63:i]
ELSE
IF *merging-masking*
; merging-masking
THEN *DEST[i+63:i] remains unchanged*
ELSE DEST[i+63:i] := 0
; zeroing-masking
FI
FI;
ENDFOR
DEST[MAXVL-1:VL] := 0
VMOVDQU (VEX.256 Encoded Version, Load - and Register Copy)
DEST[255:0] := SRC[255:0]
DEST[MAXVL-1:256] := 0
VMOVDQU (VEX.256 Encoded Version, Store-Form)
DEST[255:0] := SRC[255:0]
VMOVDQU (VEX.128 encoded version)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] := 0
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-69
VMOVDQU (128-bit Load- and Register-Copy- Form Legacy SSE Version)
DEST[127:0] := SRC[127:0]
DEST[MAXVL-1:128] (Unmodified)
(V)MOVDQU (128-bit Store-Form Version)
DEST[127:0] := SRC[127:0]
Intel C/C++ Compiler Intrinsic Equivalent
VMOVDQU16 __m512i _mm512_mask_loadu_epi16(__m512i s, __mmask32 k, void * sa);
VMOVDQU16 __m512i _mm512_maskz_loadu_epi16( __mmask32 k, void * sa);
VMOVDQU16 void _mm512_mask_storeu_epi16(void * d, __mmask32 k, __m512i a);
VMOVDQU16 __m256i _mm256_mask_loadu_epi16(__m256i s, __mmask16 k, void * sa);
VMOVDQU16 __m256i _mm256_maskz_loadu_epi16( __mmask16 k, void * sa);
VMOVDQU16 void _mm256_mask_storeu_epi16(void * d, __mmask16 k, __m256i a);
VMOVDQU16 __m128i _mm_mask_loadu_epi16(__m128i s, __mmask8 k, void * sa);
VMOVDQU16 __m128i _mm_maskz_loadu_epi16( __mmask8 k, void * sa);
VMOVDQU16 void _mm_mask_storeu_epi16(void * d, __mmask8 k, __m128i a);
VMOVDQU32 __m512i _mm512_loadu_epi32( void * sa);
VMOVDQU32 __m512i _mm512_mask_loadu_epi32(__m512i s, __mmask16 k, void * sa);
VMOVDQU32 __m512i _mm512_maskz_loadu_epi32( __mmask16 k, void * sa);
VMOVDQU32 void _mm512_storeu_epi32(void * d, __m512i a);
VMOVDQU32 void _mm512_mask_storeu_epi32(void * d, __mmask16 k, __m512i a);
VMOVDQU32 __m256i _mm256_mask_loadu_epi32(__m256i s, __mmask8 k, void * sa);
VMOVDQU32 __m256i _mm256_maskz_loadu_epi32( __mmask8 k, void * sa);
VMOVDQU32 void _mm256_storeu_epi32(void * d, __m256i a);
VMOVDQU32 void _mm256_mask_storeu_epi32(void * d, __mmask8 k, __m256i a);
VMOVDQU32 __m128i _mm_mask_loadu_epi32(__m128i s, __mmask8 k, void * sa);
VMOVDQU32 __m128i _mm_maskz_loadu_epi32( __mmask8 k, void * sa);
VMOVDQU32 void _mm_storeu_epi32(void * d, __m128i a);
VMOVDQU32 void _mm_mask_storeu_epi32(void * d, __mmask8 k, __m128i a);
VMOVDQU64 __m512i _mm512_loadu_epi64( void * sa);
VMOVDQU64 __m512i _mm512_mask_loadu_epi64(__m512i s, __mmask8 k, void * sa);
VMOVDQU64 __m512i _mm512_maskz_loadu_epi64( __mmask8 k, void * sa);
VMOVDQU64 void _mm512_storeu_epi64(void * d, __m512i a);
VMOVDQU64 void _mm512_mask_storeu_epi64(void * d, __mmask8 k, __m512i a);
VMOVDQU64 __m256i _mm256_mask_loadu_epi64(__m256i s, __mmask8 k, void * sa);
VMOVDQU64 __m256i _mm256_maskz_loadu_epi64( __mmask8 k, void * sa);
VMOVDQU64 void _mm256_storeu_epi64(void * d, __m256i a);
VMOVDQU64 void _mm256_mask_storeu_epi64(void * d, __mmask8 k, __m256i a);
VMOVDQU64 __m128i _mm_mask_loadu_epi64(__m128i s, __mmask8 k, void * sa);
VMOVDQU64 __m128i _mm_maskz_loadu_epi64( __mmask8 k, void * sa);
VMOVDQU64 void _mm_storeu_epi64(void * d, __m128i a);
VMOVDQU64 void _mm_mask_storeu_epi64(void * d, __mmask8 k, __m128i a);
VMOVDQU8 __m512i _mm512_mask_loadu_epi8(__m512i s, __mmask64 k, void * sa);
VMOVDQU8 __m512i _mm512_maskz_loadu_epi8( __mmask64 k, void * sa);
VMOVDQU8 void _mm512_mask_storeu_epi8(void * d, __mmask64 k, __m512i a);
VMOVDQU8 __m256i _mm256_mask_loadu_epi8(__m256i s, __mmask32 k, void * sa);
VMOVDQU8 __m256i _mm256_maskz_loadu_epi8( __mmask32 k, void * sa);
VMOVDQU8 void _mm256_mask_storeu_epi8(void * d, __mmask32 k, __m256i a);
VMOVDQU8 __m128i _mm_mask_loadu_epi8(__m128i s, __mmask16 k, void * sa);
VMOVDQU8 __m128i _mm_maskz_loadu_epi8( __mmask16 k, void * sa);
VMOVDQU8 void _mm_mask_storeu_epi8(void * d, __mmask16 k, __m128i a);
MOVDQU __m256i _mm256_loadu_si256 (__m256i * p);
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-70
MOVDQU _mm256_storeu_si256(_m256i *p, __m256i a);
MOVDQU __m128i _mm_loadu_si128 (__m128i * p);
MOVDQU _mm_storeu_si128(__m128i *p, __m128i a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded instruction, see Exceptions Type E4.nb in Table 2-51, “Type E4 Class Exception Conditions.”
Additionally:
#UD
If EVEX.vvvv != 1111B or VEX.vvvv != 1111B.
MOVDQU,VMOVDQU8/16/32/64-Move Unaligned Packed Integer Values
Vol. 2B
4-71
MOVHLPS-Move Packed Single Precision Floating-Point Values High to Low
Opcode/
Op /
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature Flag
Support
NP 0F 12 /r
RM
V/V
SSE
Move two packed single precision floating-point values
MOVHLPS xmm1, xmm2
from high quadword of xmm2 to low quadword of xmm1.
VEX.128.0F.WIG 12 /r
RVM
V/V
AVX
Merge two packed single precision floating-point values
VMOVHLPS xmm1, xmm2, xmm3
from high quadword of xmm3 and low quadword of xmm2.
EVEX.128.0F.W0 12 /r
RVM
V/V
AVX512F
Merge two packed single precision floating-point values
VMOVHLPS xmm1, xmm2, xmm3
OR AVX10.1
from high quadword of xmm3 and low quadword of xmm2.
Instruction Operand Encoding1
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
VEX.vvvv (r) /
RVM
ModRM:reg (w)
ModRM:r/m (r)
N/A
EVEX.vvvv (r)
Description
This instruction cannot be used for memory to register moves.
128-bit two-argument form:
Moves two packed single precision floating-point values from the high quadword of the second XMM argument
(second operand) to the low quadword of the first XMM register (first argument). The quadword at bits 127:64 of
the destination operand is left unchanged. Bits (MAXVL-1:128) of the corresponding destination register remain
unchanged.
128-bit and EVEX three-argument form:
Moves two packed single precision floating-point values from the high quadword of the third XMM argument (third
operand) to the low quadword of the destination (first operand). Copies the high quadword from the second XMM
argument (second operand) to the high quadword of the destination (first operand). Bits (MAXVL-1:128) of the
corresponding destination register are zeroed.
If VMOVHLPS is encoded with VEX.L or EVEX.L’L= 1, an attempt to execute the instruction encoded with VEX.L or
EVEX.L’L= 1 will cause an #UD exception.
Operation
MOVHLPS (128-bit Two-Argument Form)
DEST[63:0] := SRC[127:64]
DEST[MAXVL-1:64] (Unmodified)
VMOVHLPS (128-bit Three-Argument Form - VEX & EVEX)
DEST[63:0] := SRC2[127:64]
DEST[127:64] := SRC1[127:64]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
MOVHLPS __m128 _mm_movehl_ps(__m128 a, __m128 b)
SIMD Floating-Point Exceptions
None.
1. ModRM.MOD = 011B required.
MOVHLPS-Move Packed Single Precision Floating-Point Values High to Low
Vol. 2B
4-72
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-24, “Type 7 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
EVEX-encoded instruction, see Exceptions Type E7NM.128 in Table 2-57, “Type E7NM Class Exception Conditions.”
MOVHLPS-Move Packed Single Precision Floating-Point Values High to Low
Vol. 2B
4-73
MOVHPD-Move High Packed Double Precision Floating-Point Value
Opcode/
Op / En
64/32 bit
CPUID
Description
Instruction
Mode
Feature Flag
Support
66 0F 16 /r
A
V/V
SSE2
Move double precision floating-point value from m64
MOVHPD xmm1, m64
to high quadword of xmm1.
VEX.128.66.0F.WIG 16 /r
B
V/V
AVX
Merge double precision floating-point value from m64
VMOVHPD xmm2, xmm1, m64
and the low quadword of xmm1.
EVEX.128.66.0F.W1 16 /r
D
V/V
AVX512F
Merge double precision floating-point value from m64
VMOVHPD xmm2, xmm1, m64
OR AVX10.1
and the low quadword of xmm1.
66 0F 17 /r
C
V/V
SSE2
Move double precision floating-point value from high
MOVHPD m64, xmm1
quadword of xmm1 to m64.
VEX.128.66.0F.WIG 17 /r
C
V/V
AVX
Move double precision floating-point value from high
VMOVHPD m64, xmm1
quadword of xmm1 to m64.
EVEX.128.66.0F.W1 17 /r
E
V/V
AVX512F
Move double precision floating-point value from high
VMOVHPD m64, xmm1
OR AVX10.1
quadword of xmm1 to m64.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
D
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
E
Tuple1 Scalar
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
This instruction cannot be used for register to register or memory to memory moves.
128-bit Legacy SSE load:
Moves a double precision floating-point value from the source 64-bit memory operand and stores it in the high 64-
bits of the destination XMM register. The lower 64bits of the XMM register are preserved. Bits (MAXVL-1:128) of the
corresponding destination register are preserved.
VEX.128 & EVEX encoded load:
Loads a double precision floating-point value from the source 64-bit memory operand (the third operand) and
stores it in the upper 64-bits of the destination XMM register (first operand). The low 64-bits from the first source
operand (second operand) are copied to the low 64-bits of the destination. Bits (MAXVL-1:128) of the corre-
sponding destination register are zeroed.
128-bit store:
Stores a double precision floating-point value from the high 64-bits of the XMM register source (second operand)
to the 64-bit memory location (first operand).
Note: VMOVHPD (store) (VEX.128.66.0F 17 /r) is legal and has the same behavior as the existing 66 0F 17 store.
For VMOVHPD (store) VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instruction will #UD.
If VMOVHPD is encoded with VEX.L or EVEX.L’L= 1, an attempt to execute the instruction encoded with VEX.L or
EVEX.L’L= 1 will cause an #UD exception.
MOVHPD-Move High Packed Double Precision Floating-Point Value
Vol. 2B
4-74
Operation
MOVHPD (128-bit Legacy SSE Load)
DEST[63:0] (Unmodified)
DEST[127:64] := SRC[63:0]
DEST[MAXVL-1:128] (Unmodified)
VMOVHPD (VEX.128 & EVEX Encoded Load)
DEST[63:0] := SRC1[63:0]
DEST[127:64] := SRC2[63:0]
DEST[MAXVL-1:128] := 0
VMOVHPD (Store)
DEST[63:0] := SRC[127:64]
Intel C/C++ Compiler Intrinsic Equivalent
MOVHPD __m128d _mm_loadh_pd ( __m128d a, double *p)
MOVHPD void _mm_storeh_pd (double *p, __m128d a)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
MOVHPD-Move High Packed Double Precision Floating-Point Value
Vol. 2B
4-75
MOVHPS-Move High Packed Single Precision Floating-Point Values
Opcode/
Op / En
64/32 bit
CPUID
Description
Instruction
Mode
Feature Flag
Support
NP 0F 16 /r
A
V/V
SSE
Move two packed single precision floating-point values
MOVHPS xmm1, m64
from m64 to high quadword of xmm1.
VEX.128.0F.WIG 16 /r
B
V/V
AVX
Merge two packed single precision floating-point values
VMOVHPS xmm2, xmm1, m64
from m64 and the low quadword of xmm1.
EVEX.128.0F.W0 16 /r
D
V/V
AVX512F
Merge two packed single precision floating-point values
VMOVHPS xmm2, xmm1, m64
OR AVX10.1
from m64 and the low quadword of xmm1.
NP 0F 17 /r
C
V/V
SSE
Move two packed single precision floating-point values
MOVHPS m64, xmm1
from high quadword of xmm1 to m64.
VEX.128.0F.WIG 17 /r
C
V/V
AVX
Move two packed single precision floating-point values
VMOVHPS m64, xmm1
from high quadword of xmm1 to m64.
EVEX.128.0F.W0 17 /r
E
V/V
AVX512F
Move two packed single precision floating-point values
VMOVHPS m64, xmm1
OR AVX10.1
from high quadword of xmm1 to m64.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
D
Tuple2
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
E
Tuple2
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
This instruction cannot be used for register to register or memory to memory moves.
128-bit Legacy SSE load:
Moves two packed single precision floating-point values from the source 64-bit memory operand and stores them
in the high 64-bits of the destination XMM register. The lower 64bits of the XMM register are preserved. Bits
(MAXVL-1:128) of the corresponding destination register are preserved.
VEX.128 & EVEX encoded load:
Loads two single precision floating-point values from the source 64-bit memory operand (the third operand) and
stores it in the upper 64-bits of the destination XMM register (first operand). The low 64-bits from the first source
operand (the second operand) are copied to the lower 64-bits of the destination. Bits (MAXVL-1:128) of the corre-
sponding destination register are zeroed.
128-bit store:
Stores two packed single precision floating-point values from the high 64-bits of the XMM register source (second
operand) to the 64-bit memory location (first operand).
Note: VMOVHPS (store) (VEX.128.0F 17 /r) is legal and has the same behavior as the existing 0F 17 store. For
VMOVHPS (store) VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instruction will #UD.
If VMOVHPS is encoded with VEX.L or EVEX.L’L= 1, an attempt to execute the instruction encoded with VEX.L or
EVEX.L’L= 1 will cause an #UD exception.
MOVHPS-Move High Packed Single Precision Floating-Point Values
Vol. 2B
4-76
Operation
MOVHPS (128-bit Legacy SSE Load)
DEST[63:0] (Unmodified)
DEST[127:64] := SRC[63:0]
DEST[MAXVL-1:128] (Unmodified)
VMOVHPS (VEX.128 and EVEX Encoded Load)
DEST[63:0] := SRC1[63:0]
DEST[127:64] := SRC2[63:0]
DEST[MAXVL-1:128] := 0
VMOVHPS (Store)
DEST[63:0] := SRC[127:64]
Intel C/C++ Compiler Intrinsic Equivalent
MOVHPS __m128 _mm_loadh_pi ( __m128 a, __m64 *p)
MOVHPS void _mm_storeh_pi (__m64 *p, __m128 a)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
MOVHPS-Move High Packed Single Precision Floating-Point Values
Vol. 2B
4-77
MOVLHPS-Move Packed Single Precision Floating-Point Values Low to High
Opcode/
Op /
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature Flag
Support
NP 0F 16 /r
RM
V/V
SSE
Move two packed single precision floating-point values from
MOVLHPS xmm1, xmm2
low quadword of xmm2 to high quadword of xmm1.
VEX.128.0F.WIG 16 /r
RVM
V/V
AVX
Merge two packed single precision floating-point values
VMOVLHPS xmm1, xmm2, xmm3
from low quadword of xmm3 and low quadword of xmm2.
EVEX.128.0F.W0 16 /r
RVM
V/V
AVX512F
Merge two packed single precision floating-point values
VMOVLHPS xmm1, xmm2, xmm3
OR AVX10.1
from low quadword of xmm3 and low quadword of xmm2.
Instruction Operand Encoding1
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
VEX.vvvv (r) /
RVM
ModRM:reg (w)
ModRM:r/m (r)
N/A
EVEX.vvvv (r)
Description
This instruction cannot be used for memory to register moves.
128-bit two-argument form:
Moves two packed single precision floating-point values from the low quadword of the second XMM argument
(second operand) to the high quadword of the first XMM register (first argument). The low quadword of the desti-
nation operand is left unchanged. Bits (MAXVL-1:128) of the corresponding destination register are unmodified.
128-bit three-argument forms:
Moves two packed single precision floating-point values from the low quadword of the third XMM argument (third
operand) to the high quadword of the destination (first operand). Copies the low quadword from the second XMM
argument (second operand) to the low quadword of the destination (first operand). Bits (MAXVL-1:128) of the
corresponding destination register are zeroed.
If VMOVLHPS is encoded with VEX.L or EVEX.L’L= 1, an attempt to execute the instruction encoded with VEX.L or
EVEX.L’L= 1 will cause an #UD exception.
Operation
MOVLHPS (128-bit Two-Argument Form)
DEST[63:0] (Unmodified)
DEST[127:64] := SRC[63:0]
DEST[MAXVL-1:128] (Unmodified)
VMOVLHPS (128-bit Three-Argument Form - VEX & EVEX)
DEST[63:0] := SRC1[63:0]
DEST[127:64] := SRC2[63:0]
DEST[MAXVL-1:128] := 0
Intel C/C++ Compiler Intrinsic Equivalent
MOVLHPS __m128 _mm_movelh_ps(__m128 a, __m128 b)
SIMD Floating-Point Exceptions
None.
1. ModRM.MOD = 011B required
MOVLHPS-Move Packed Single Precision Floating-Point Values Low to High
Vol. 2B
4-78
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-24, “Type 7 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
EVEX-encoded instruction, see Exceptions Type E7NM.128 in Table 2-57, “Type E7NM Class Exception Conditions.”
MOVLHPS-Move Packed Single Precision Floating-Point Values Low to High
Vol. 2B
4-79
MOVLPD-Move Low Packed Double Precision Floating-Point Value
Opcode/
Op / En
64/32 bit
CPUID
Description
Instruction
Mode
Feature Flag
Support
66 0F 12 /r
A
V/V
SSE2
Move double precision floating-point value from m64 to
MOVLPD xmm1, m64
low quadword of xmm1.
VEX.128.66.0F.WIG 12 /r
B
V/V
AVX
Merge double precision floating-point value from m64 and
VMOVLPD xmm2, xmm1, m64
the high quadword of xmm1.
EVEX.128.66.0F.W1 12 /r
D
V/V
AVX512F
Merge double precision floating-point value from m64 and
VMOVLPD xmm2, xmm1, m64
OR AVX10.1
the high quadword of xmm1.
66 0F 13/r
C
V/V
SSE2
Move double precision floating-point value from low
MOVLPD m64, xmm1
quadword of xmm1 to m64.
VEX.128.66.0F.WIG 13/r
C
V/V
AVX
Move double precision floating-point value from low
VMOVLPD m64, xmm1
quadword of xmm1 to m64.
EVEX.128.66.0F.W1 13/r
E
V/V
AVX512F
Move double precision floating-point value from low
VMOVLPD m64, xmm1
OR AVX10.1
quadword of xmm1 to m64.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:r/m (r)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
D
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
E
Tuple1 Scalar
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
This instruction cannot be used for register to register or memory to memory moves.
128-bit Legacy SSE load:
Moves a double precision floating-point value from the source 64-bit memory operand and stores it in the low 64-
bits of the destination XMM register. The upper 64bits of the XMM register are preserved. Bits (MAXVL-1:128) of the
corresponding destination register are preserved.
VEX.128 & EVEX encoded load:
Loads a double precision floating-point value from the source 64-bit memory operand (third operand), merges it
with the upper 64-bits of the first source XMM register (second operand), and stores it in the low 128-bits of the
destination XMM register (first operand). Bits (MAXVL-1:128) of the corresponding destination register are zeroed.
128-bit store:
Stores a double precision floating-point value from the low 64-bits of the XMM register source (second operand) to
the 64-bit memory location (first operand).
Note: VMOVLPD (store) (VEX.128.66.0F 13 /r) is legal and has the same behavior as the existing 66 0F 13 store.
For VMOVLPD (store) VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instruction will #UD.
If VMOVLPD is encoded with VEX.L or EVEX.L’L= 1, an attempt to execute the instruction encoded with VEX.L or
EVEX.L’L= 1 will cause an #UD exception.
Operation
MOVLPD (128-bit Legacy SSE Load)
DEST[63:0] := SRC[63:0]
DEST[MAXVL-1:64] (Unmodified)
MOVLPD-Move Low Packed Double Precision Floating-Point Value
Vol. 2B
4-80
VMOVLPD (VEX.128 & EVEX Encoded Load)
DEST[63:0] := SRC2[63:0]
DEST[127:64] := SRC1[127:64]
DEST[MAXVL-1:128] := 0
VMOVLPD (Store)
DEST[63:0] := SRC[63:0]
Intel C/C++ Compiler Intrinsic Equivalent
MOVLPD __m128d _mm_loadl_pd ( __m128d a, double *p)
MOVLPD void _mm_storel_pd (double *p, __m128d a)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
MOVLPD-Move Low Packed Double Precision Floating-Point Value
Vol. 2B
4-81
MOVLPS-Move Low Packed Single Precision Floating-Point Values
Opcode/
Op / En
64/32 bit
CPUID
Description
Instruction
Mode
Feature Flag
Support
NP 0F 12 /r
A
V/V
SSE
Move two packed single precision floating-point values
MOVLPS xmm1, m64
from m64 to low quadword of xmm1.
VEX.128.0F.WIG 12 /r
B
V/V
AVX
Merge two packed single precision floating-point values
VMOVLPS xmm2, xmm1, m64
from m64 and the high quadword of xmm1.
EVEX.128.0F.W0 12 /r
D
V/V
AVX512F
Merge two packed single precision floating-point values
VMOVLPS xmm2, xmm1, m64
OR AVX10.1
from m64 and the high quadword of xmm1.
0F 13/r
C
V/V
SSE
Move two packed single precision floating-point values
MOVLPS m64, xmm1
from low quadword of xmm1 to m64.
VEX.128.0F.WIG 13/r
C
V/V
AVX
Move two packed single precision floating-point values
VMOVLPS m64, xmm1
from low quadword of xmm1 to m64.
EVEX.128.0F.W0 13/r
E
V/V
AVX512F
Move two packed single precision floating-point values
VMOVLPS m64, xmm1
OR AVX10.1
from low quadword of xmm1 to m64.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
D
Tuple2
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
E
Tuple2
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
This instruction cannot be used for register to register or memory to memory moves.
128-bit Legacy SSE load:
Moves two packed single precision floating-point values from the source 64-bit memory operand and stores them
in the low 64-bits of the destination XMM register. The upper 64bits of the XMM register are preserved. Bits
(MAXVL-1:128) of the corresponding destination register are preserved.
VEX.128 & EVEX encoded load:
Loads two packed single precision floating-point values from the source 64-bit memory operand (the third
operand), merges them with the upper 64-bits of the first source operand (the second operand), and stores them
in the low 128-bits of the destination register (the first operand). Bits (MAXVL-1:128) of the corresponding desti-
nation register are zeroed.
128-bit store:
Loads two packed single precision floating-point values from the low 64-bits of the XMM register source (second
operand) to the 64-bit memory location (first operand).
Note: VMOVLPS (store) (VEX.128.0F 13 /r) is legal and has the same behavior as the existing 0F 13 store. For
VMOVLPS (store) VEX.vvvv and EVEX.vvvv are reserved and must be 1111b otherwise instruction will #UD.
If VMOVLPS is encoded with VEX.L or EVEX.L’L= 1, an attempt to execute the instruction encoded with VEX.L or
EVEX.L’L= 1 will cause an #UD exception.
Operation
MOVLPS (128-bit Legacy SSE Load)
DEST[63:0] := SRC[63:0]
DEST[MAXVL-1:64] (Unmodified)
MOVLPS-Move Low Packed Single Precision Floating-Point Values
Vol. 2B
4-82
VMOVLPS (VEX.128 & EVEX Encoded Load)
DEST[63:0] := SRC2[63:0]
DEST[127:64] := SRC1[127:64]
DEST[MAXVL-1:128] := 0
VMOVLPS (Store)
DEST[63:0] := SRC[63:0]
Intel C/C++ Compiler Intrinsic Equivalent
MOVLPS __m128 _mm_loadl_pi ( __m128 a, __m64 *p)
MOVLPS void _mm_storel_pi (__m64 *p, __m128 a)
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions,” additionally:
#UD
If VEX.L = 1.
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
MOVLPS-Move Low Packed Single Precision Floating-Point Values
Vol. 2B
4-83
MOVMSKPD-Extract Packed Double Precision Floating-Point Sign Mask
Opcode/
Op/
64/32-bit
CPUID
Description
Instruction
En
Mode
Feature
Flag
66 0F 50 /r
RM
V/V
SSE2
Extract 2-bit sign mask from xmm and store in reg. The
upper bits of r32 or r64 are filled with zeros.
MOVMSKPD reg, xmm
VEX.128.66.0F.WIG 50 /r
RM
V/V
AVX
Extract 2-bit sign mask from xmm2 and store in reg.
The upper bits of r32 or r64 are zeroed.
VMOVMSKPD reg, xmm2
VEX.256.66.0F.WIG 50 /r
RM
V/V
AVX
Extract 4-bit sign mask from ymm2 and store in reg.
The upper bits of r32 or r64 are zeroed.
VMOVMSKPD reg, ymm2
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Extracts the sign bits from the packed double precision floating-point values in the source operand (second
operand), formats them into a 2-bit mask, and stores the mask in the destination operand (first operand). The
source operand is an XMM register, and the destination operand is a general-purpose register. The mask is stored
in the 2 low-order bits of the destination operand. Zero-extend the upper bits of the destination.
In 64-bit mode, the instruction can access additional registers (XMM8-XMM15, R8-R15) when used with a REX.R
prefix. The default operand size is 64-bit in 64-bit mode.
128-bit versions: The source operand is a YMM register. The destination operand is a general purpose register.
VEX.256 encoded version: The source operand is a YMM register. The destination operand is a general purpose
register.
Note: In VEX-encoded versions, VEX.vvvv is reserved and must be 1111b, otherwise instructions will #UD.
Operation
(V)MOVMSKPD (128-bit Versions)
DEST[0] := SRC[63]
DEST[1] := SRC[127]
IF DEST = r32
THEN DEST[31:2] := 0;
ELSE DEST[63:2] := 0;
FI
VMOVMSKPD (VEX.256 Encoded Version)
DEST[0] := SRC[63]
DEST[1] := SRC[127]
DEST[2] := SRC[191]
DEST[3] := SRC[255]
IF DEST = r32
THEN DEST[31:4] := 0;
ELSE DEST[63:4] := 0;
FI
MOVMSKPD-Extract Packed Double Precision Floating-Point Sign Mask
Vol. 2B
4-84
Intel C/C++ Compiler Intrinsic Equivalent
MOVMSKPD int _mm_movemask_pd ( __m128d a)
VMOVMSKPD _mm256_movemask_pd(__m256d a)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-24, “Type 7 Class Exception Conditions,” additionally:
#UD
If VEX.vvvv ≠ 1111B.
MOVMSKPD-Extract Packed Double Precision Floating-Point Sign Mask
Vol. 2B
4-85
MOVMSKPS-Extract Packed Single Precision Floating-Point Sign Mask
Opcode/
Op/
64/32-bit
CPUID
Description
Instruction
En
Mode
Feature
Flag
NP 0F 50 /r
RM
V/V
SSE
Extract 4-bit sign mask from xmm and store in reg.
The upper bits of r32 or r64 are filled with zeros.
MOVMSKPS reg, xmm
VEX.128.0F.WIG 50 /r
RM
V/V
AVX
Extract 4-bit sign mask from xmm2 and store in reg.
The upper bits of r32 or r64 are zeroed.
VMOVMSKPS reg, xmm2
VEX.256.0F.WIG 50 /r
RM
V/V
AVX
Extract 8-bit sign mask from ymm2 and store in reg.
The upper bits of r32 or r64 are zeroed.
VMOVMSKPS reg, ymm2
Instruction Operand Encoding1
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
Extracts the sign bits from the packed single precision floating-point values in the source operand (second
operand), formats them into a 4- or 8-bit mask, and stores the mask in the destination operand (first operand).
The source operand is an XMM or YMM register, and the destination operand is a general-purpose register. The
mask is stored in the 4 or 8 low-order bits of the destination operand. The upper bits of the destination operand
beyond the mask are filled with zeros.
In 64-bit mode, the instruction can access additional registers (XMM8-XMM15, R8-R15) when used with a REX.R
prefix. The default operand size is 64-bit in 64-bit mode.
128-bit versions: The source operand is a YMM register. The destination operand is a general purpose register.
VEX.256 encoded version: The source operand is a YMM register. The destination operand is a general purpose
register.
Note: In VEX-encoded versions, VEX.vvvv is reserved and must be 1111b, otherwise instructions will #UD.
Operation
DEST[0] := SRC[31];
DEST[1] := SRC[63];
DEST[2] := SRC[95];
DEST[3] := SRC[127];
IF DEST = r32
THEN DEST[31:4] := ZeroExtend;
ELSE DEST[63:4] := ZeroExtend;
FI;
1. ModRM.MOD = 011B required
MOVMSKPS-Extract Packed Single Precision Floating-Point Sign Mask
Vol. 2B
4-86
(V)MOVMSKPS (128-bit version)
DEST[0] := SRC[31]
DEST[1] := SRC[63]
DEST[2] := SRC[95]
DEST[3] := SRC[127]
IF DEST = r32
THEN DEST[31:4] := 0;
ELSE DEST[63:4] := 0;
FI
VMOVMSKPS (VEX.256 encoded version)
DEST[0] := SRC[31]
DEST[1] := SRC[63]
DEST[2] := SRC[95]
DEST[3] := SRC[127]
DEST[4] := SRC[159]
DEST[5] := SRC[191]
DEST[6] := SRC[223]
DEST[7] := SRC[255]
IF DEST = r32
THEN DEST[31:8] := 0;
ELSE DEST[63:8] := 0;
FI
Intel C/C++ Compiler Intrinsic Equivalent
int _mm_movemask_ps(__m128 a)
int _mm256_movemask_ps(__m256 a)
SIMD Floating-Point Exceptions
None.
Other Exceptions
See Table 2-24, “Type 7 Class Exception Conditions,” additionally:
#UD
If VEX.vvvv ≠ 1111B.
MOVMSKPS-Extract Packed Single Precision Floating-Point Sign Mask
Vol. 2B
4-87
MOVNTDQ-Store Packed Integers Using Non-Temporal Hint
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0F E7 /r
A
V/V
SSE2
Move packed integer values in xmm1 to m128 using non-
MOVNTDQ m128, xmm1
temporal hint.
VEX.128.66.0F.WIG E7 /r
A
V/V
AVX
Move packed integer values in xmm1 to m128 using non-
VMOVNTDQ m128, xmm1
temporal hint.
VEX.256.66.0F.WIG E7 /r
A
V/V
AVX
Move packed integer values in ymm1 to m256 using non-
VMOVNTDQ m256, ymm1
temporal hint.
EVEX.128.66.0F.W0 E7 /r
B
V/V
(AVX512VL AND
Move packed integer values in xmm1 to m128 using non-
VMOVNTDQ m128, xmm1
AVX512F) OR
temporal hint.
AVX10.1
EVEX.256.66.0F.W0 E7 /r
B
V/V
(AVX512VL AND
Move packed integer values in zmm1 to m256 using non-
VMOVNTDQ m256, ymm1
AVX512F) OR
temporal hint.
AVX10.1
EVEX.512.66.0F.W0 E7 /r
B
V/V
AVX512F
Move packed integer values in zmm1 to m512 using non-
VMOVNTDQ m512, zmm1
OR AVX10.1
temporal hint.
Instruction Operand Encoding1
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
B
Full Mem
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Moves the packed integers in the source operand (second operand) to the destination operand (first operand) using
a non-temporal hint to prevent caching of the data during the write to memory. The source operand is an XMM
register, YMM register or ZMM register, which is assumed to contain integer data (packed bytes, words, double-
words, or quadwords). The destination operand is a 128-bit, 256-bit or 512-bit memory location. The memory
operand must be aligned on a 16-byte (128-bit version), 32-byte (VEX.256 encoded version) or 64-byte (512-bit
version) boundary otherwise a general-protection exception (#GP) will be generated.
The non-temporal hint is implemented by using a write combining (WC) memory type protocol when writing the
data to memory. Using this protocol, the processor does not write the data into the cache hierarchy, nor does it
fetch the corresponding cache line from memory into the cache hierarchy. The memory type of the region being
written to can override the non-temporal hint, if the memory address specified for the non-temporal store is in an
uncacheable (UC) or write protected (WP) memory region. For more information on non-temporal stores, see
“Caching of Temporal vs. Non-Temporal Data” in Chapter 10 in the IA-32 Intel Architecture Software Developer’s
Manual, Volume 1.
Because the WC protocol uses a weakly-ordered memory consistency model, a fencing operation implemented with
the SFENCE or MFENCE instruction should be used in conjunction with VMOVNTDQ instructions if multiple proces-
sors might use different memory types to read/write the destination memory locations.
Note: VEX.vvvv and EVEX.vvvv are reserved and must be 1111b, VEX.L must be 0; otherwise instructions will
#UD.
Operation
VMOVNTDQ(EVEX Encoded Versions)
VL = 128, 256, 512
DEST[VL-1:0] := SRC[VL-1:0]
1. ModRM.MOD != 011B
MOVNTDQ-Store Packed Integers Using Non-Temporal Hint
Vol. 2B
4-88
DEST[MAXVL-1:VL] := 0
MOVNTDQ (Legacy and VEX Versions)
DEST := SRC
Intel C/C++ Compiler Intrinsic Equivalent
VMOVNTDQ void _mm512_stream_si512(void * p, __m512i a);
VMOVNTDQ void _mm256_stream_si256 (__m256i * p, __m256i a);
MOVNTDQ void _mm_stream_si128 (__m128i * p, __m128i a);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Exceptions Type1.SSE2 in Table 2-18, “Type 1 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-47, “Type E1NF Class Exception Conditions.”
Additionally:
#UD
If VEX.vvvv != 1111B or EVEX.vvvv != 1111B.
MOVNTDQ-Store Packed Integers Using Non-Temporal Hint
Vol. 2B
4-89
MOVNTDQA-Load Double Quadword Non-Temporal Aligned Hint
Opcode/
Op /
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0F 38 2A /r
A
V/V
SSE4_1
Move double quadword from m128 to xmm1 using non-
MOVNTDQA xmm1, m128
temporal hint if WC memory type.
VEX.128.66.0F38.WIG 2A /r
A
V/V
AVX
Move double quadword from m128 to xmm1 using non-
VMOVNTDQA xmm1, m128
temporal hint if WC memory type.
VEX.256.66.0F38.WIG 2A /r
A
V/V
AVX2
Move 256-bit data from m256 to ymm1 using non-
VMOVNTDQA ymm1, m256
temporal hint if WC memory type.
EVEX.128.66.0F38.W0 2A /r
B
V/V
(AVX512VL AND
Move 128-bit data from m128 to xmm1 using non-
VMOVNTDQA xmm1, m128
AVX512F) OR
temporal hint if WC memory type.
AVX10.1
EVEX.256.66.0F38.W0 2A /r
B
V/V
(AVX512VL AND
Move 256-bit data from m256 to ymm1 using non-
VMOVNTDQA ymm1, m256
AVX512F) OR
temporal hint if WC memory type.
AVX10.1
EVEX.512.66.0F38.W0 2A /r
B
V/V
AVX512F
Move 512-bit data from m512 to zmm1 using non-
VMOVNTDQA zmm1, m512
OR AVX10.1
temporal hint if WC memory type.
Instruction Operand Encoding1
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
B
Full Mem
ModRM:reg (w)
ModRM:r/m (r)
N/A
N/A
Description
MOVNTDQA loads a double quadword from the source operand (second operand) to the destination operand (first
operand) using a non-temporal hint if the memory source is WC (write combining) memory type. For WC memory
type, the non-temporal hint may be implemented by loading a temporary internal buffer with the equivalent of an
aligned cache line without filling this data to the cache. Any memory-type aliased lines in the cache will be snooped
and flushed. Subsequent MOVNTDQA reads to unread portions of the WC cache line will receive data from the
temporary internal buffer if data is available. The temporary internal buffer may be flushed by the processor at any
time for any reason, for example:
• A load operation other than a MOVNTDQA which references memory already resident in a temporary internal
buffer.
• A non-WC reference to memory already resident in a temporary internal buffer.
• Interleaving of reads and writes to a single temporary internal buffer.
• Repeated (V)MOVNTDQA loads of a particular 16-byte item in a streaming line.
• Certain micro-architectural conditions including resource shortages, detection of a mis-speculation condition,
and various fault conditions.
The non-temporal hint is implemented by using a write combining (WC) memory type protocol when reading the
data from memory. Using this protocol, the processor does not read the data into the cache hierarchy, nor does it
fetch the corresponding cache line from memory into the cache hierarchy. The memory type of the region being
read can override the non-temporal hint, if the memory address specified for the non-temporal read is not a WC
memory region. Information on non-temporal reads and writes can be found in “Caching of Temporal vs. Non-
Temporal Data” in Chapter 10 in the Intel® 64 and IA-32 Architecture Software Developer’s Manual, Volume 3A.
Because the WC protocol uses a weakly-ordered memory consistency model, a fencing operation implemented with
a MFENCE instruction should be used in conjunction with MOVNTDQA instructions if multiple processors might use
different memory types for the referenced memory locations or to synchronize reads of a processor with writes by
1. ModRM.MOD != 011B
MOVNTDQA-Load Double Quadword Non-Temporal Aligned Hint
Vol. 2B
4-90
other agents in the system. A processor’s implementation of the streaming load hint does not override the effective
memory type, but the implementation of the hint is processor dependent. For example, a processor implementa-
tion may choose to ignore the hint and process the instruction as a normal MOVDQA for any memory type. Alter-
natively, another implementation may optimize cache reads generated by MOVNTDQA on WB memory type to
reduce cache evictions.
The 128-bit (V)MOVNTDQA addresses must be 16-byte aligned or the instruction will cause a #GP.
The 256-bit VMOVNTDQA addresses must be 32-byte aligned or the instruction will cause a #GP.
The 512-bit VMOVNTDQA addresses must be 64-byte aligned or the instruction will cause a #GP.
Operation
MOVNTDQA (128bit- Legacy SSE Form)
DEST := SRC
DEST[MAXVL-1:128] (Unmodified)
VMOVNTDQA (VEX.128 and EVEX.128 Encoded Form)
DEST := SRC
DEST[MAXVL-1:128] := 0
VMOVNTDQA (VEX.256 and EVEX.256 Encoded Forms)
DEST[255:0] := SRC[255:0]
DEST[MAXVL-1:256] := 0
VMOVNTDQA (EVEX.512 Encoded Form)
DEST[511:0] := SRC[511:0]
DEST[MAXVL-1:512] := 0
Intel C/C++ Compiler Intrinsic Equivalent
VMOVNTDQA __m512i _mm512_stream_load_si512(__m512i const* p);
MOVNTDQA __m128i _mm_stream_load_si128 (const __m128i *p);
VMOVNTDQA __m256i _mm256_stream_load_si256 (__m256i const* p);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-18, “Type 1 Class Exception Conditions.”
EVEX-encoded instruction, see Table 2-47, “Type E1NF Class Exception Conditions.”
Additionally:
#UD
If VEX.vvvv != 1111B or EVEX.vvvv != 1111B.
MOVNTDQA-Load Double Quadword Non-Temporal Aligned Hint
Vol. 2B
4-91
MOVNTI-Store Doubleword Using Non-Temporal Hint
Opcode /
Op/
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
NP 0F C3 /r
MR
V/V
SSE2
Move doubleword from r32 to m32 using non-temporal
hint.
MOVNTI m32, r32
NP REX.W + 0F C3 /r
MR
V/N.E.
SSE2
Move quadword from r64 to m64 using non-temporal
hint.
MOVNTI m64, r64
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
MR
ModRM:r/m (w)
ModRM:reg (r)
N/A
N/A
Description
Moves the doubleword integer in the source operand (second operand) to the destination operand (first operand)
using a non-temporal hint to minimize cache pollution during the write to memory. The source operand is a
general-purpose register. The destination operand is a 32-bit memory location.
The non-temporal hint is implemented by using a write combining (WC) memory type protocol when writing the
data to memory. Using this protocol, the processor does not write the data into the cache hierarchy, nor does it
fetch the corresponding cache line from memory into the cache hierarchy. The memory type of the region being
written to can override the non-temporal hint, if the memory address specified for the non-temporal store is in an
uncacheable (UC) or write protected (WP) memory region. For more information on non-temporal stores, see
“Caching of Temporal vs. Non-Temporal Data” in Chapter 10 in the Intel® 64 and IA-32 Architectures Software
Developer’s Manual, Volume 1.
Because the WC protocol uses a weakly-ordered memory consistency model, a fencing operation implemented with
the SFENCE or MFENCE instruction should be used in conjunction with MOVNTI instructions if multiple processors
might use different memory types to read/write the destination memory locations.
In 64-bit mode, the instruction’s default operation size is 32 bits. Use of the REX.R prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. See the summary chart at the
beginning of this section for encoding data and limits.
Operation
DEST := SRC;
Intel C/C++ Compiler Intrinsic Equivalent
MOVNTI void _mm_stream_si32 (int *p, int a)
MOVNTI void _mm_stream_si64(__int64 *p, __int64 a)
SIMD Floating-Point Exceptions
None.
Protected Mode Exceptions
#GP(0)
For an illegal memory operand effective address in the CS, DS, ES, FS or GS segments.
#SS(0)
For an illegal address in the SS segment.
#PF(fault-code)
For a page fault.
#UD
If CPUID.01H:EDX.SSE2[26] = 0.
If the LOCK prefix is used.
MOVNTI-Store Doubleword Using Non-Temporal Hint
Vol. 2B
4-92
Real-Address Mode Exceptions
#GP
If any part of the operand lies outside the effective address space from 0 to FFFFH.
#UD
If CPUID.01H:EDX.SSE2[26] = 0.
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
Same exceptions as in real address mode.
#PF(fault-code)
For a page fault.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the memory address is in a non-canonical form.
#PF(fault-code)
For a page fault.
#UD
If CPUID.01H:EDX.SSE2[26] = 0.
If the LOCK prefix is used.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
MOVNTI-Store Doubleword Using Non-Temporal Hint
Vol. 2B
4-93