Intel 64 and IA-32 Architectures. Software Developer’s Manual (2026) - page 17
Operation
CASE (relation of operands) OF
ST > SRC:
C3, C2, C0 := 000;
ST < SRC:
C3, C2, C0 := 001;
ST = SRC:
C3, C2, C0 := 100;
ESAC;
IF ST(0) or SRC = QNaN, but not SNaN or unsupported format
THEN
C3, C2, C0 := 111;
ELSE (* ST(0) or SRC is SNaN or unsupported format *)
#IA;
IF FPUControlWord.IM = 1
THEN
C3, C2, C0 := 111;
FI;
FI;
IF Instruction = FUCOMP
THEN
PopRegisterStack;
FI;
IF Instruction = FUCOMPP
THEN
PopRegisterStack;
FI;
FPU Flags Affected
C1
Set to 0 if stack underflow occurred.
C0, C2, C3
See Table 3-43.
Floating-Point Exceptions
#IS
Stack underflow occurred.
#IA
One or both operands are SNaN values or have unsupported formats. Detection of a QNaN
value in and of itself does not raise an invalid-operand exception.
#D
One or both operands are denormal values.
Protected Mode Exceptions
#NM
CR0.EM[bit 2] or CR0.TS[bit 3] = 1.
#MF
If there is a pending x87 FPU exception.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
FUCOM/FUCOMP/FUCOMPP-Unordered Compare Floating-Point Values
Vol. 2A
3-403
FUCOM/FUCOMP/FUCOMPP-Unordered Compare Floating-Point Values
Vol. 2A
3-404

FXAM-Examine Floating-Point
Opcode
Instruction
64-Bit
Compat/
Description
Mode
Leg Mode
D9 E5
FXAM
Valid
Valid
Classify value or number in ST(0).
Description
Examines the contents of the ST(0) register and sets the condition code flags C0, C2, and C3 in the FPU status word
to indicate the class of value or number in the register (see the table below).
Table 3-44. FXAM Results
Class
C3
C2
C0
Unsupported
0
0
0
NaN
0
0
1
Normal finite number
0
1
0
Infinity
0
1
1
Zero
1
0
0
Empty
1
0
1
Denormal number
1
1
0
The C1 flag is set to the sign of the value in ST(0), regardless of whether the register is empty or full.
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
C1 := sign bit of ST; (* 0 for positive, 1 for negative *)
CASE (class of value or number in ST(0)) OF
Unsupported:C3, C2, C0 := 000;
NaN:
C3, C2, C0 := 001;
Normal:
C3, C2, C0 := 010;
Infinity:
C3, C2, C0 := 011;
Zero:
C3, C2, C0 := 100;
Empty:
C3, C2, C0 := 101;
Denormal:
C3, C2, C0 := 110;
ESAC;
FPU Flags Affected
C1
Sign of value in ST(0).
C0, C2, C3
See Table 3-44.
Floating-Point Exceptions
None.
Protected Mode Exceptions
#NM
CR0.EM[bit 2] or CR0.TS[bit 3] = 1.
#MF
If there is a pending x87 FPU exception.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
FXAM-Examine Floating-Point
Vol. 2A
3-405
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
FXAM-Examine Floating-Point
Vol. 2A
3-406

FXCH-Exchange Register Contents
Opcode
Instruction
64-Bit
Compat/
Description
Mode
Leg Mode
D9 C8+i
FXCH ST(i)
Valid
Valid
Exchange the contents of ST(0) and ST(i).
D9 C9
FXCH
Valid
Valid
Exchange the contents of ST(0) and ST(1).
Description
Exchanges the contents of registers ST(0) and ST(i). If no source operand is specified, the contents of ST(0) and
ST(1) are exchanged.
This instruction provides a simple means of moving values in the FPU register stack to the top of the stack [ST(0)],
so that they can be operated on by those floating-point instructions that can only operate on values in ST(0). For
example, the following instruction sequence takes the square root of the third register from the top of the register
stack:
FXCH ST(3);
FSQRT;
FXCH ST(3);
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
IF (Number-of-operands) is 1
THEN
temp := ST(0);
ST(0) := SRC;
SRC := temp;
ELSE
temp := ST(0);
ST(0) := ST(1);
ST(1) := temp;
FI;
FPU Flags Affected
C1
Set to 0.
C0, C2, C3
Undefined.
Floating-Point Exceptions
#IS
Stack underflow occurred.
Protected Mode Exceptions
#NM
CR0.EM[bit 2] or CR0.TS[bit 3] = 1.
#MF
If there is a pending x87 FPU exception.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
FXCH-Exchange Register Contents
Vol. 2A
3-407
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
FXCH-Exchange Register Contents
Vol. 2A
3-408

FXRSTOR-Restore x87 FPU, MMX, XMM, and MXCSR State
Opcode/
Op/
64-Bit
Compat/
Description
Instruction
En
Mode
Leg Mode
NP 0F AE /1
M
Valid
Valid
Restore the x87 FPU, MMX, XMM, and MXCSR
register state from m512byte.
FXRSTOR m512byte
NP REX.W + 0F AE /1
M
Valid
N.E.
Restore the x87 FPU, MMX, XMM, and MXCSR
FXRSTOR64 m512byte
register state from m512byte.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
M
ModRM:r/m (r)
N/A
N/A
N/A
Description
Reloads the x87 FPU, MMX technology, XMM, and MXCSR registers from the 512-byte memory image specified in
the source operand. This data should have been written to memory previously using the FXSAVE instruction, and
in the same format as required by the operating modes. The first byte of the data should be located on a 16-byte
boundary. There are three distinct layouts of the FXSAVE state map: one for legacy and compatibility mode, a
second format for 64-bit mode FXSAVE/FXRSTOR with REX.W=0, and the third format is for 64-bit mode with
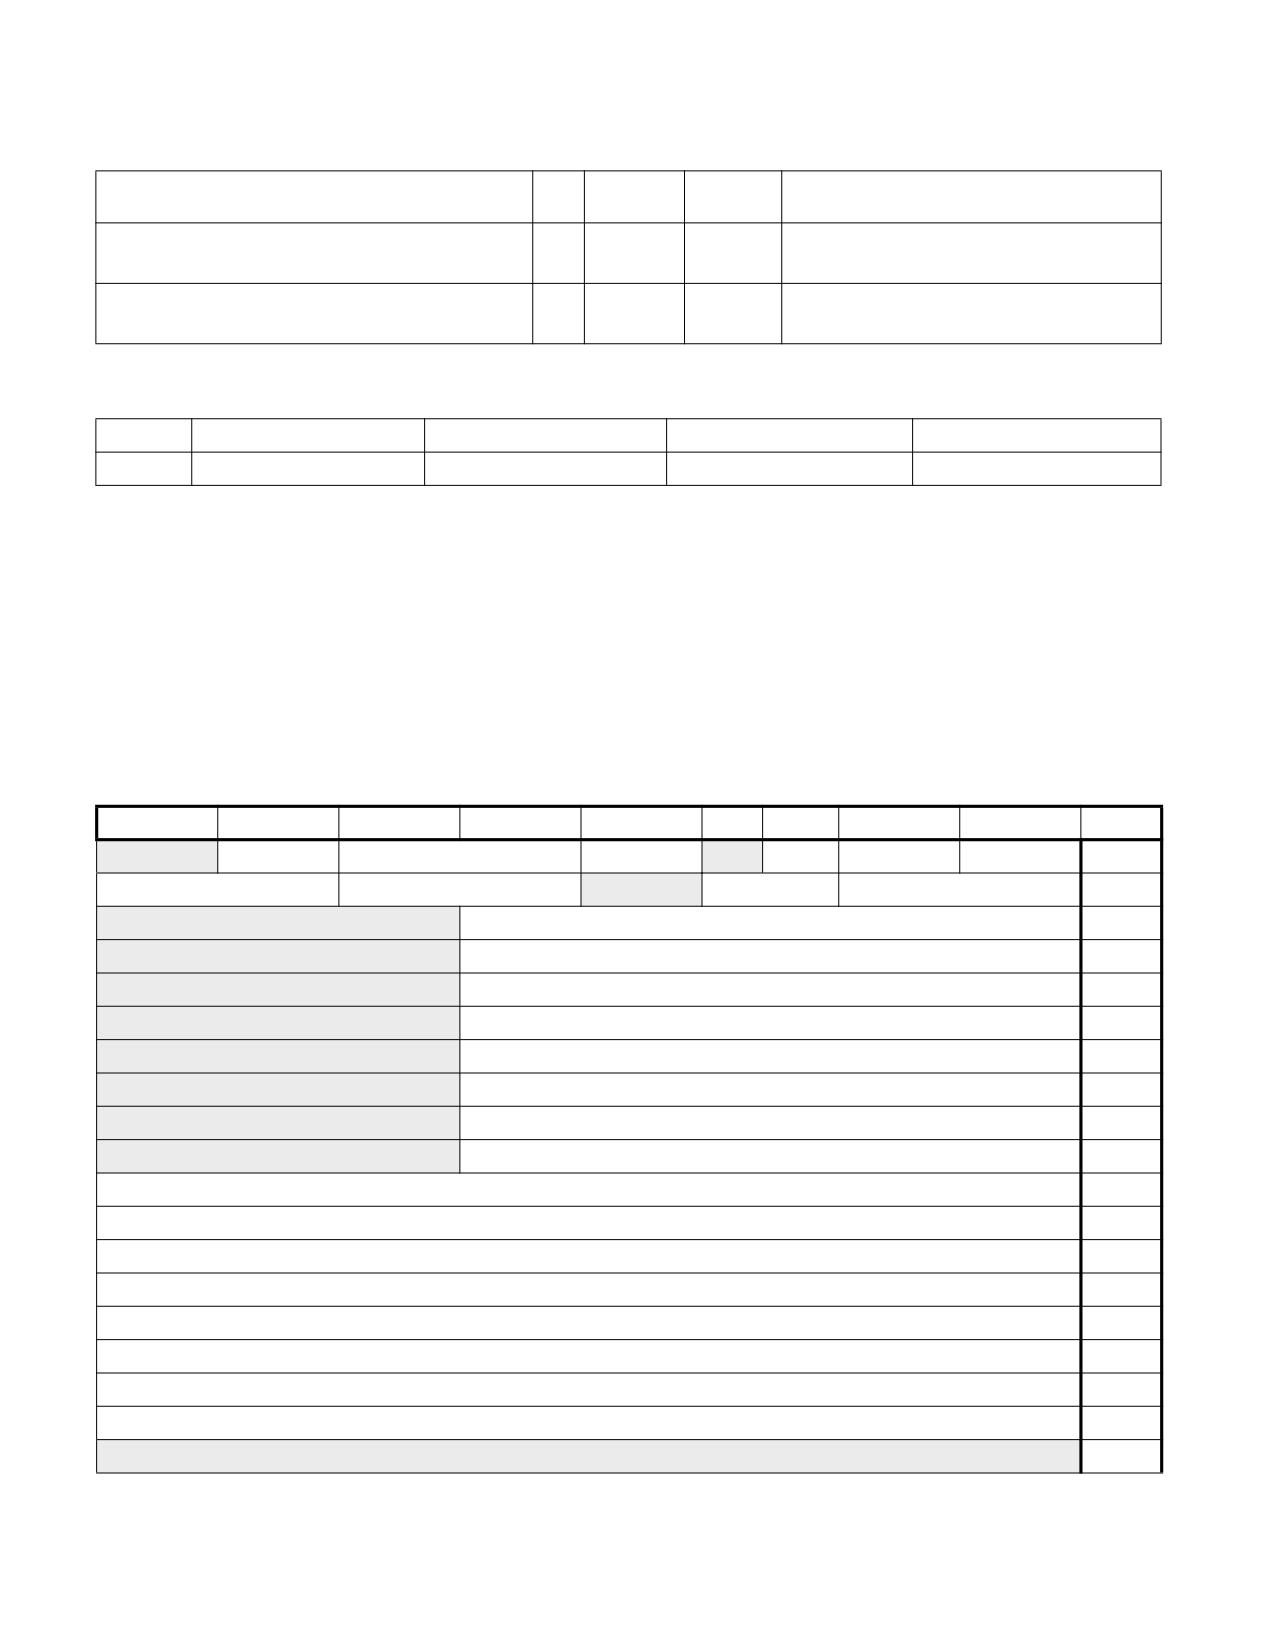
FXSAVE64/FXRSTOR64. Table 3-45 shows the layout of the legacy/compatibility mode state information in
memory and describes the fields in the memory image for the FXRSTOR and FXSAVE instructions. Table 3-48
shows the layout of the 64-bit mode state information when REX.W is set (FXSAVE64/FXRSTOR64). Table 3-49
shows the layout of the 64-bit mode state information when REX.W is clear (FXSAVE/FXRSTOR).
The state image referenced with an FXRSTOR instruction must have been saved using an FXSAVE instruction or be
in the same format as required by Table 3-45, Table 3-48, or Table 3-49. Referencing a state image saved with an
FSAVE, FNSAVE instruction or incompatible field layout will result in an incorrect state restoration.
The FXRSTOR instruction does not flush pending x87 FPU exceptions. To check and raise exceptions when loading
x87 FPU state information with the FXRSTOR instruction, use an FWAIT instruction after the FXRSTOR instruction.
If the OSFXSR bit in control register CR4 is not set, the FXRSTOR instruction may not restore the states of the XMM
and MXCSR registers. This behavior is implementation dependent.
If the MXCSR state contains an unmasked exception with a corresponding status flag also set, loading the register
with the FXRSTOR instruction will not result in a SIMD floating-point error condition being generated. Only the next
occurrence of this unmasked exception will result in the exception being generated.
Bits 16 through 32 of the MXCSR register are defined as reserved and should be set to 0. Attempting to write a 1
in any of these bits from the saved state image will result in a general protection exception (#GP) being generated.
Bytes 464:511 of an FXSAVE image are available for software use. FXRSTOR ignores the content of bytes 464:511
in an FXSAVE state image.
Operation
IF 64-Bit Mode
THEN
(x87 FPU, MMX, XMM15-XMM0, MXCSR) Load(SRC);
ELSE
(x87 FPU, MMX, XMM7-XMM0, MXCSR) := Load(SRC);
FI;
x87 FPU and SIMD Floating-Point Exceptions
None.
FXRSTOR-Restore x87 FPU, MMX, XMM, and MXCSR State
Vol. 2A
3-409
Protected Mode Exceptions
#GP(0)
For an illegal memory operand effective address in the CS, DS, ES, FS or GS segments.
If a memory operand is not aligned on a 16-byte boundary, regardless of segment. (See align-
ment check exception [#AC] below.)
For an attempt to set reserved bits in MXCSR.
#SS(0)
For an illegal address in the SS segment.
#PF(fault-code)
For a page fault.
#NM
If CR0.TS[bit 3] = 1.
If CR0.EM[bit 2] = 1.
#UD
If CPUID.01H:EDX.FXSR[24] = 0.
If instruction is preceded by a LOCK prefix.
#AC
If this exception is disabled a general protection exception (#GP) is signaled if the memory
operand is not aligned on a 16-byte boundary, as described above. If the alignment check
exception (#AC) is enabled (and the CPL is 3), signaling of #AC is not guaranteed and may
vary with implementation, as follows. In all implementations where #AC is not signaled, a
general protection exception is signaled in its place. In addition, the width of the alignment
check may also vary with implementation. For instance, for a given implementation, an align-
ment check exception might be signaled for a 2-byte misalignment, whereas a general protec-
tion exception might be signaled for all other misalignments (4-, 8-, or 16-byte
misalignments).
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
#GP
If a memory operand is not aligned on a 16-byte boundary, regardless of segment.
If any part of the operand lies outside the effective address space from 0 to FFFFH.
For an attempt to set reserved bits in MXCSR.
#NM
If CR0.TS[bit 3] = 1.
If CR0.EM[bit 2] = 1.
#UD
If CPUID.01H:EDX.FXSR[24] = 0.
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
Same exceptions as in real address mode.
#PF(fault-code)
For a page fault.
#AC
For unaligned memory reference.
#UD
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
FXRSTOR-Restore x87 FPU, MMX, XMM, and MXCSR State
Vol. 2A
3-410
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the memory address is in a non-canonical form.
If memory operand is not aligned on a 16-byte boundary, regardless of segment.
For an attempt to set reserved bits in MXCSR.
#PF(fault-code)
For a page fault.
#NM
If CR0.TS[bit 3] = 1.
If CR0.EM[bit 2] = 1.
#UD
If CPUID.01H:EDX.FXSR[24] = 0.
If instruction is preceded by a LOCK prefix.
#AC
If this exception is disabled a general protection exception (#GP) is signaled if the memory
operand is not aligned on a 16-byte boundary, as described above. If the alignment check
exception (#AC) is enabled (and the CPL is 3), signaling of #AC is not guaranteed and may
vary with implementation, as follows. In all implementations where #AC is not signaled, a
general protection exception is signaled in its place. In addition, the width of the alignment
check may also vary with implementation. For instance, for a given implementation, an align-
ment check exception might be signaled for a 2-byte misalignment, whereas a general protec-
tion exception might be signaled for all other misalignments (4-, 8-, or 16-byte
misalignments).
FXRSTOR-Restore x87 FPU, MMX, XMM, and MXCSR State
Vol. 2A
3-411
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Opcode/
Op/
64-Bit
Compat/
Description
Instruction
En
Mode
Leg Mode
NP 0F AE /0
M
Valid
Valid
Save the x87 FPU, MMX, XMM, and MXCSR
register state to m512byte.
FXSAVE m512byte
NP REX.W + 0F AE /0
M
Valid
N.E.
Save the x87 FPU, MMX, XMM, and MXCSR
register state to m512byte.
FXSAVE64 m512byte
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
M
ModRM:r/m (w)
N/A
N/A
N/A
Description
Saves the current state of the x87 FPU, MMX technology, XMM, and MXCSR registers to a 512-byte memory loca-
tion specified in the destination operand. The content layout of the 512 byte region depends on whether the
processor is operating in non-64-bit operating modes or 64-bit sub-mode of IA-32e mode.
Bytes 464:511 are available to software use. The processor does not write to bytes 464:511 of an FXSAVE area.
The operation of FXSAVE in non-64-bit modes is described first.
Non-64-Bit Mode Operation
Table 3-45 shows the layout of the state information in memory when the processor is operating in legacy modes.
Table 3-45. Non-64-Bit-Mode Layout of FXSAVE and FXRSTOR Memory Region
15
14
13
12
11
10
9
8
7
6
5
4
3
2
1
0
Rsvd
FCS
FIP[31:0]
FOP
Rsvd
FTW
FSW
FCW
0
MXCSR_MASK
MXCSR
Rsrvd
FDS
FDP[31:0]
16
Reserved
ST0/MM0
32
Reserved
ST1/MM1
48
Reserved
ST2/MM2
64
Reserved
ST3/MM3
80
Reserved
ST4/MM4
96
Reserved
ST5/MM5
112
Reserved
ST6/MM6
128
Reserved
ST7/MM7
144
XMM0
160
XMM1
176
XMM2
192
XMM3
208
XMM4
224
XMM5
240
XMM6
256
XMM7
272
Reserved
288
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-412
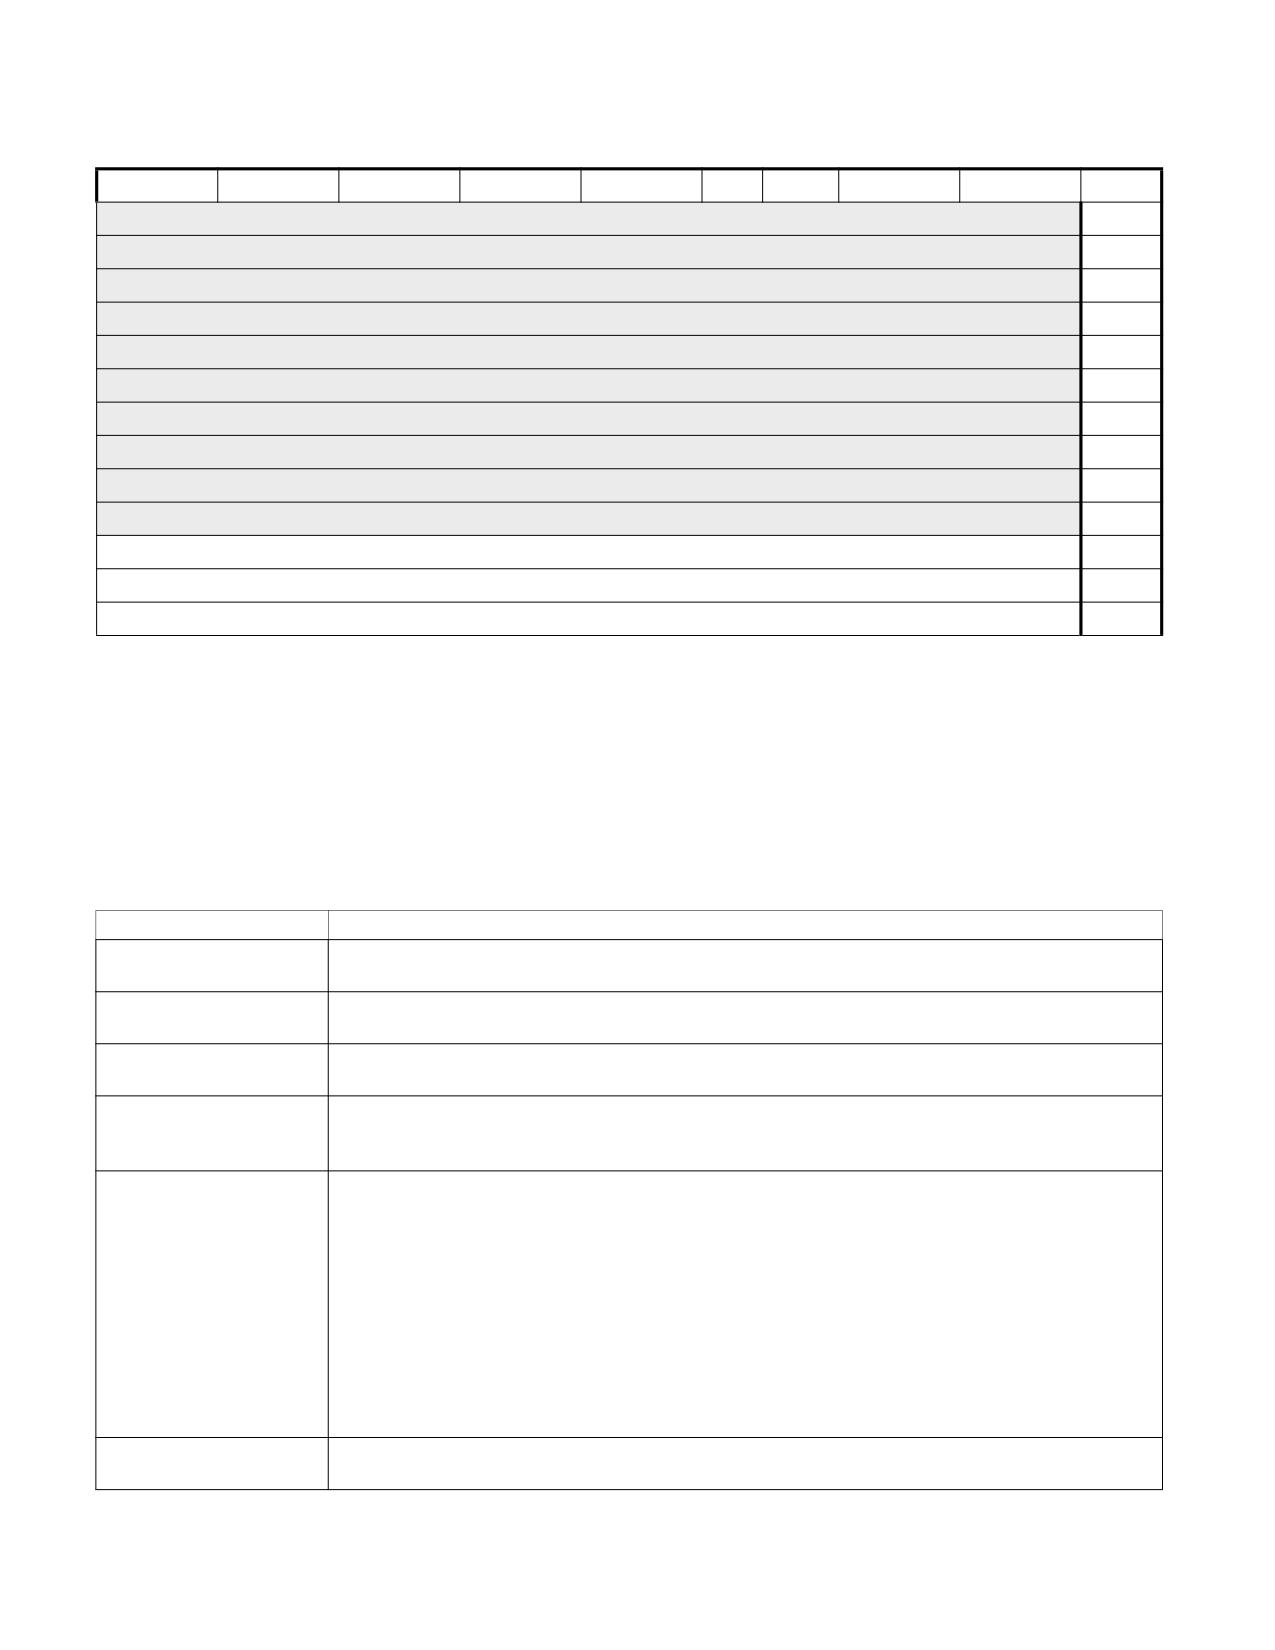
Table 3-45. Non-64-Bit-Mode Layout of FXSAVE and FXRSTOR Memory Region (Contd.)
15
14
13
12
11
10
9
8
7
6
5
4
3
2
1
0
Reserved
304
Reserved
320
Reserved
336
Reserved
352
Reserved
368
Reserved
384
Reserved
400
Reserved
416
Reserved
432
Reserved
448
Available
464
Available
480
Available
496
The destination operand contains the first byte of the memory image, and it must be aligned on a 16-byte
boundary. A misaligned destination operand will result in a general-protection (#GP) exception being generated (or
in some cases, an alignment check exception [#AC]).
The FXSAVE instruction is used when an operating system needs to perform a context switch or when an exception
handler needs to save and examine the current state of the x87 FPU, MMX technology, and/or XMM and MXCSR
registers.
The fields in Table 3-45 are defined in Table 3-46.
Table 3-46. Field Definitions
Field
Definition
FCW
x87 FPU Control Word (16 bits). See Figure 8-6 in the Intel® 64 and IA-32 Architectures Software
Developer’s Manual, Volume 1, for the layout of the x87 FPU control word.
FSW
x87 FPU Status Word (16 bits). See Figure 8-4 in the Intel® 64 and IA-32 Architectures Software
Developer’s Manual, Volume 1, for the layout of the x87 FPU status word.
Abridged FTW
x87 FPU Tag Word (8 bits). The tag information saved here is abridged, as described in the following
paragraphs.
FOP
x87 FPU Opcode (16 bits). The lower 11 bits of this field contain the opcode, upper 5 bits are reserved.
See Figure 8-8 in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 1, for
the layout of the x87 FPU opcode field.
FIP
x87 FPU Instruction Pointer Offset (64 bits). The contents of this field differ depending on the current
addressing mode (32-bit, 16-bit, or 64-bit) of the processor when the FXSAVE instruction was
executed:
32-bit mode - 32-bit IP offset.
16-bit mode - low 16 bits are IP offset; high 16 bits are reserved.
64-bit mode with REX.W - 64-bit IP offset.
64-bit mode without REX.W - 32-bit IP offset.
See “x87 FPU Instruction and Operand (Data) Pointers” in Chapter 8 of the Intel® 64 and IA-32
Architectures Software Developer’s Manual, Volume 1, for a description of the x87 FPU instruction
pointer.
FCS
x87 FPU Instruction Pointer Selector (16 bits). If CPUID.07H.00H:EBX[13] = 1, the processor
deprecates FCS and FDS, and this field is saved as 0000H.
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-413

Table 3-46. Field Definitions (Contd.)
Field
Definition
FDP
x87 FPU Instruction Operand (Data) Pointer Offset (64 bits). The contents of this field differ
depending on the current addressing mode (32-bit, 16-bit, or 64-bit) of the processor when the
FXSAVE instruction was executed:
32-bit mode - 32-bit DP offset.
16-bit mode - low 16 bits are DP offset; high 16 bits are reserved.
64-bit mode with REX.W - 64-bit DP offset.
64-bit mode without REX.W - 32-bit DP offset.
See “x87 FPU Instruction and Operand (Data) Pointers” in Chapter 8 of the Intel® 64 and IA-32
Architectures Software Developer’s Manual, Volume 1, for a description of the x87 FPU operand
pointer.
FDS
x87 FPU Instruction Operand (Data) Pointer Selector (16 bits). If CPUID.07H.00H:EBX[13] = 1, the
processor deprecates FCS and FDS, and this field is saved as 0000H.
MXCSR
MXCSR Register State (32 bits). See Figure 10-3 in the Intel® 64 and IA-32 Architectures Software
Developer’s Manual, Volume 1, for the layout of the MXCSR register. If the OSFXSR bit in control
register CR4 is not set, the FXSAVE instruction may not save this register. This behavior is
implementation dependent.
MXCSR_
MXCSR_MASK (32 bits). This mask can be used to adjust values written to the MXCSR register,
MASK
ensuring that reserved bits are set to 0. Set the mask bits and flags in MXCSR to the mode of
operation desired for SSE and SSE2 SIMD floating-point instructions. See “Guidelines for Writing to the
MXCSR Register” in Chapter 11 of the Intel® 64 and IA-32 Architectures Software Developer’s Manual,
Volume 1, for instructions for how to determine and use the MXCSR_MASK value.
ST0/MM0 through
x87 FPU or MMX technology registers. These 80-bit fields contain the x87 FPU data registers or the
ST7/MM7
MMX technology registers, depending on the state of the processor prior to the execution of the
FXSAVE instruction. If the processor had been executing x87 FPU instruction prior to the FXSAVE
instruction, the x87 FPU data registers are saved; if it had been executing MMX instructions (or SSE or
SSE2 instructions that operated on the MMX technology registers), the MMX technology registers are
saved. When the MMX technology registers are saved, the high 16 bits of the field are reserved.
XMM0 through XMM7
XMM registers (128 bits per field). If the OSFXSR bit in control register CR4 is not set, the FXSAVE
instruction may not save these registers. This behavior is implementation dependent.
The FXSAVE instruction saves an abridged version of the x87 FPU tag word in the FTW field (unlike the FSAVE
instruction, which saves the complete tag word). The tag information is saved in physical register order (R0
through R7), rather than in top-of-stack (TOS) order. With the FXSAVE instruction, however, only a single bit (1 for
valid or 0 for empty) is saved for each tag. For example, assume that the tag word is currently set as follows:
R7
R6
R5
R4
R3
R2
R1
R0
11
xx
xx
xx
11
11
11
11
Here, 11B indicates empty stack elements and “xx” indicates valid (00B), zero (01B), or special (10B).
For this example, the FXSAVE instruction saves only the following 8 bits of information:
R7
R6
R5
R4
R3
R2
R1
R0
0
1
1
1
0
0
0
0
Here, a 1 is saved for any valid, zero, or special tag, and a 0 is saved for any empty tag.
The operation of the FXSAVE instruction differs from that of the FSAVE instruction, the as follows:
• FXSAVE instruction does not check for pending unmasked floating-point exceptions. (The FXSAVE operation in
this regard is similar to the operation of the FNSAVE instruction).
• After the FXSAVE instruction has saved the state of the x87 FPU, MMX technology, XMM, and MXCSR registers,
the processor retains the contents of the registers. Because of this behavior, the FXSAVE instruction cannot be
used by an application program to pass a “clean” x87 FPU state to a procedure, since it retains the current
state. To clean the x87 FPU state, an application must explicitly execute an FINIT instruction after an FXSAVE
instruction to reinitialize the x87 FPU state.
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-414

• The format of the memory image saved with the FXSAVE instruction is the same regardless of the current
addressing mode (32-bit or 16-bit) and operating mode (protected, real address, or system management).
This behavior differs from the FSAVE instructions, where the memory image format is different depending on
the addressing mode and operating mode. Because of the different image formats, the memory image saved
with the FXSAVE instruction cannot be restored correctly with the FRSTOR instruction, and likewise the state
saved with the FSAVE instruction cannot be restored correctly with the FXRSTOR instruction.
The FSAVE format for FTW can be recreated from the FTW valid bits and the stored 80-bit floating-point data
(assuming the stored data was not the contents of MMX technology registers) using Table 3-47.
Table 3-47. Recreating FSAVE Format
Exponent
Exponent
Fraction
J and M
FTW valid bit
all 1’s
all 0’s
all 0’s
bits
x87 FTW
0
0
0
0x
1
Special
10
0
0
0
1x
1
Valid
00
0
0
1
00
1
Special
10
0
0
1
10
1
Valid
00
0
1
0
0x
1
Special
10
0
1
0
1x
1
Special
10
0
1
1
00
1
Zero
01
0
1
1
10
1
Special
10
1
0
0
1x
1
Special
10
1
0
0
1x
1
Special
10
1
0
1
00
1
Special
10
1
0
1
10
1
Special
10
For all legal combinations above.
0
Empty
11
The J-bit is defined to be the 1-bit binary integer to the left of the decimal place in the significand. The M-bit is
defined to be the most significant bit of the fractional portion of the significand (i.e., the bit immediately to the right
of the decimal place).
When the M-bit is the most significant bit of the fractional portion of the significand, it must be 0 if the fraction is
all 0’s.
IA-32e Mode Operation
In compatibility sub-mode of IA-32e mode, legacy SSE registers, XMM0 through XMM7, are saved according to the
legacy FXSAVE map. In 64-bit mode, all of the SSE registers, XMM0 through XMM15, are saved. Additionally, there
are two different layouts of the FXSAVE map in 64-bit mode, corresponding to FXSAVE64 (which requires
REX.W=1) and FXSAVE (REX.W=0). In the FXSAVE64 map (Table 3-48), the FPU IP and FPU DP pointers are 64-bit
wide. In the FXSAVE map for 64-bit mode (Table 3-49), the FPU IP and FPU DP pointers are 32-bits.
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-415
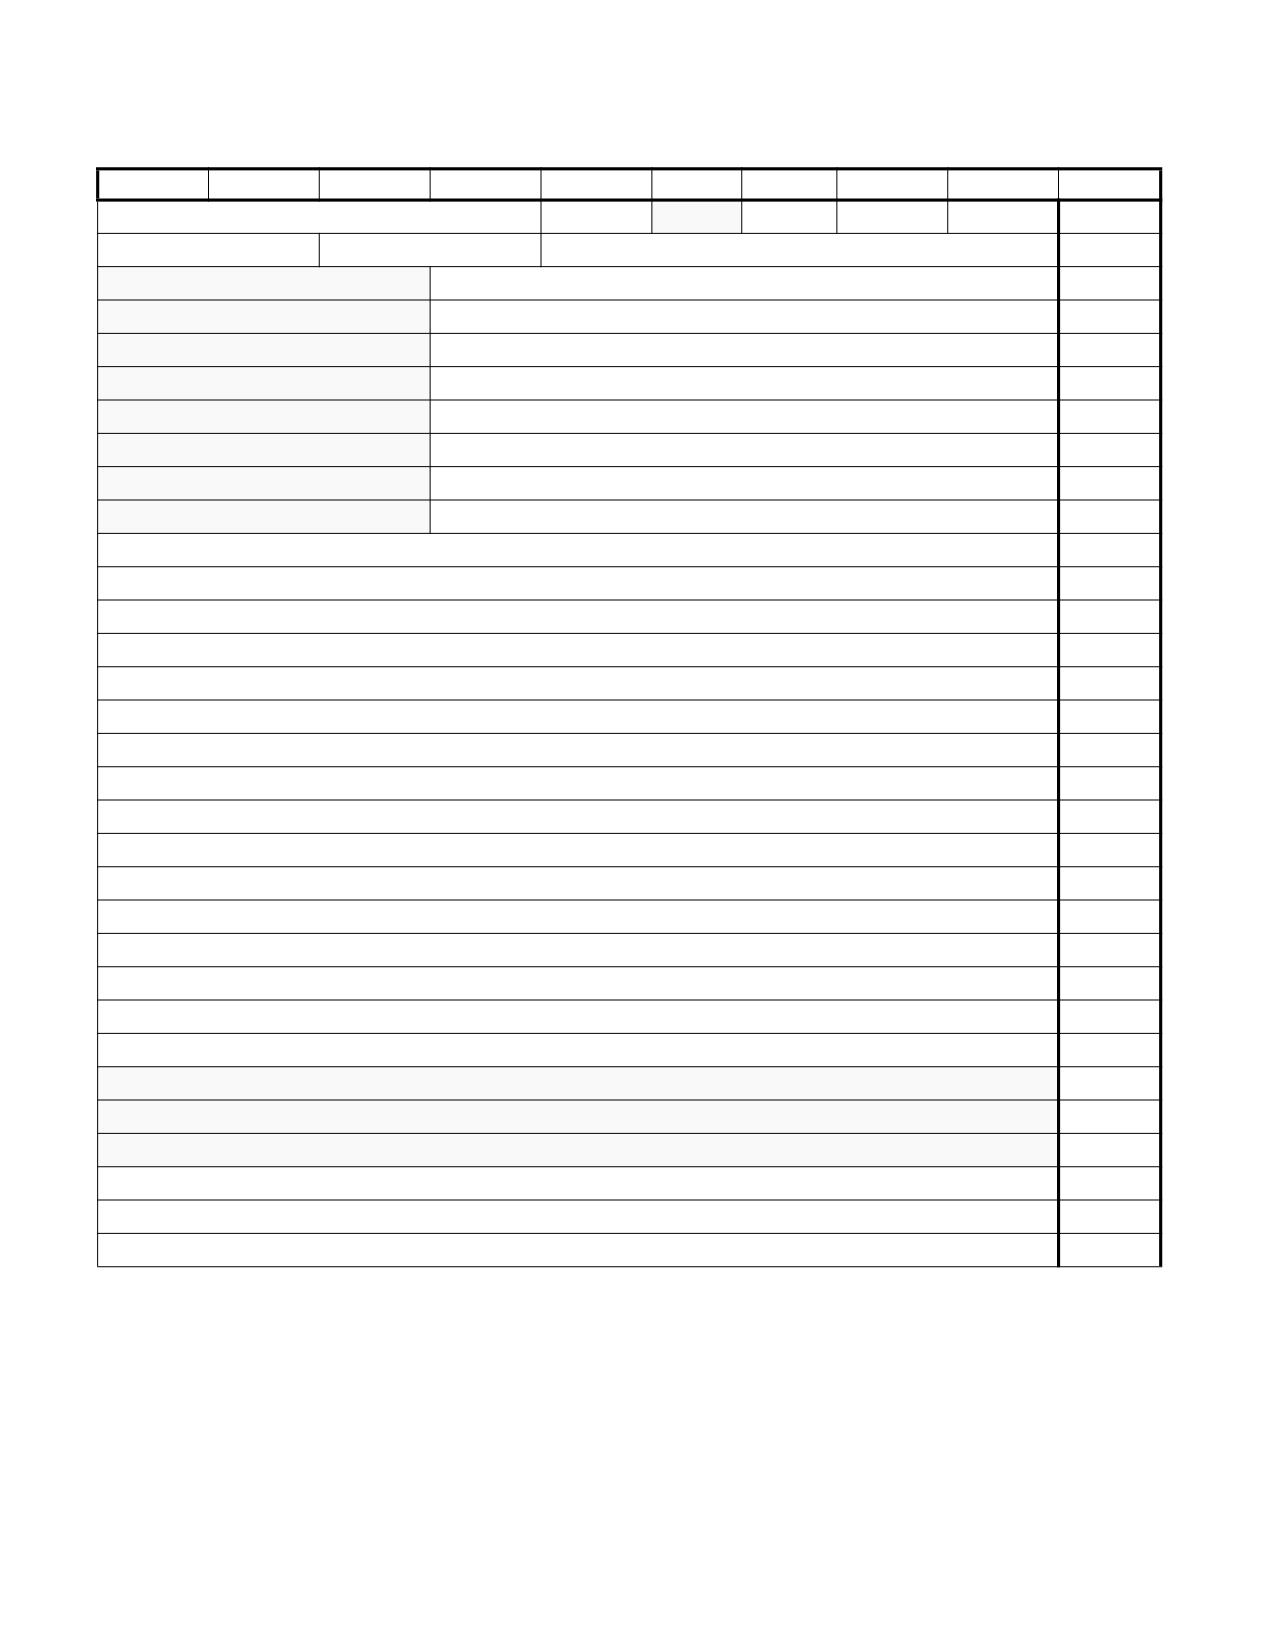
Table 3-48. Layout of the 64-Bit Mode FXSAVE64 Map (Requires REX.W = 1)
15
14
13
12
11
10
9
8
7
6
5
4
3
2
1
0
FIP
FOP
Reserved
FTW
FSW
FCW
0
MXCSR_MASK
MXCSR
FDP
16
Reserved
ST0/MM0
32
Reserved
ST1/MM1
48
Reserved
ST2/MM2
64
Reserved
ST3/MM3
80
Reserved
ST4/MM4
96
Reserved
ST5/MM5
112
Reserved
ST6/MM6
128
Reserved
ST7/MM7
144
XMM0
160
XMM1
176
XMM2
192
XMM3
208
XMM4
224
XMM5
240
XMM6
256
XMM7
272
XMM8
288
XMM9
304
XMM10
320
XMM11
336
XMM12
352
XMM13
368
XMM14
384
XMM15
400
Reserved
416
Reserved
432
Reserved
448
Available
464
Available
480
Available
496
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-416
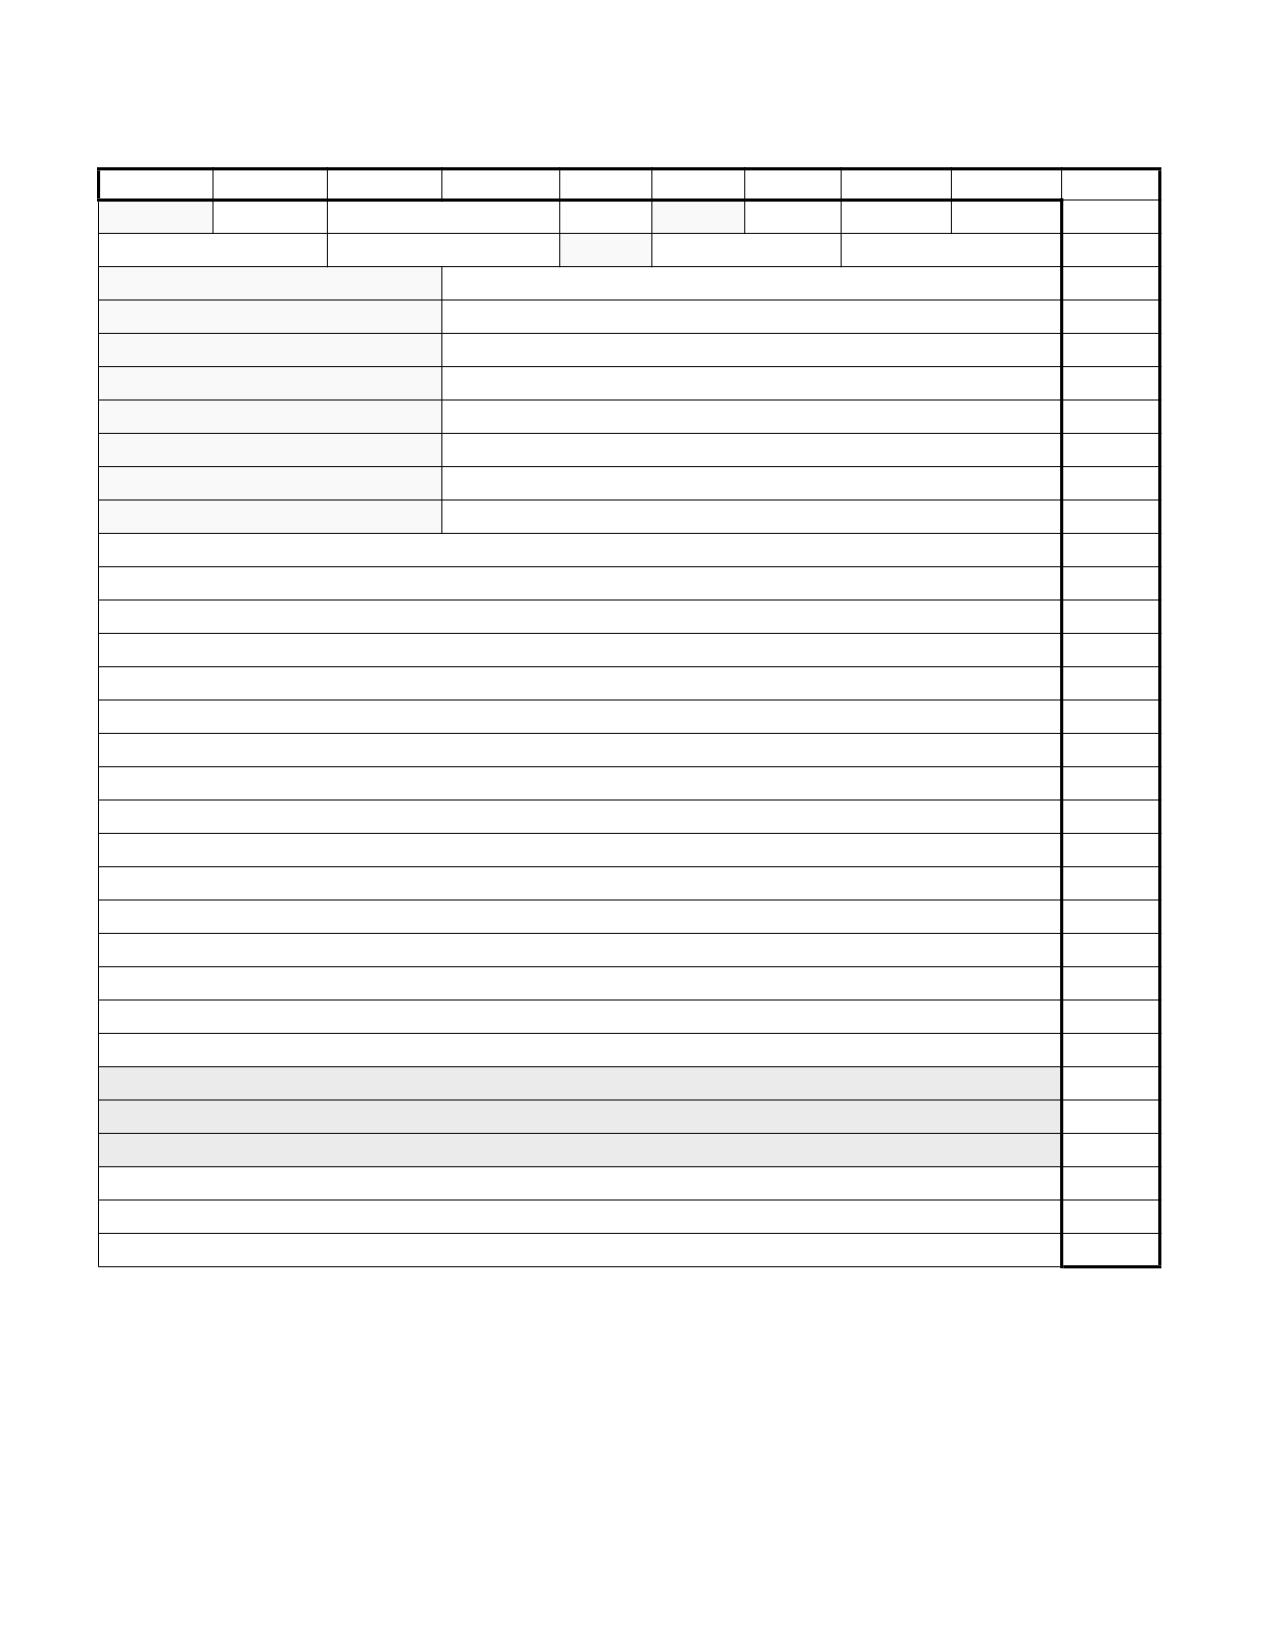
Table 3-49. Layout of the 64-Bit Mode FXSAVE Map (REX.W = 0)
15
14
13
12
11
10
9
8
7
6
5
4
3
2
1
0
Reserved
FCS
FIP[31:0]
FOP
Reserved
FTW
FSW
FCW
0
MXCSR_MASK
MXCSR
Reserved
FDS
FDP[31:0]
16
Reserved
ST0/MM0
32
Reserved
ST1/MM1
48
Reserved
ST2/MM2
64
Reserved
ST3/MM3
80
Reserved
ST4/MM4
96
Reserved
ST5/MM5
112
Reserved
ST6/MM6
128
Reserved
ST7/MM7
144
XMM0
160
XMM1
176
XMM2
192
XMM3
208
XMM4
224
XMM5
240
XMM6
256
XMM7
272
XMM8
288
XMM9
304
XMM10
320
XMM11
336
XMM12
352
XMM13
368
XMM14
384
XMM15
400
Reserved
416
Reserved
432
Reserved
448
Available
464
Available
480
Available
496
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-417
Operation
IF 64-Bit Mode
THEN
IF REX.W = 1
THEN
DEST := Save64BitPromotedFxsave(x87 FPU, MMX, XMM15-XMM0,
MXCSR);
ELSE
DEST := Save64BitDefaultFxsave(x87 FPU, MMX, XMM15-XMM0, MXCSR);
FI;
ELSE
DEST := SaveLegacyFxsave(x87 FPU, MMX, XMM7-XMM0, MXCSR);
FI;
Protected Mode Exceptions
#GP(0)
For an illegal memory operand effective address in the CS, DS, ES, FS or GS segments.
If a memory operand is not aligned on a 16-byte boundary, regardless of segment. (See the
description of the alignment check exception [#AC] below.)
#SS(0)
For an illegal address in the SS segment.
#PF(fault-code)
For a page fault.
#NM
If CR0.TS[bit 3] = 1.
If CR0.EM[bit 2] = 1.
#UD
If CPUID.01H:EDX.FXSR[24] = 0.
#UD
If the LOCK prefix is used.
#AC
If this exception is disabled a general protection exception (#GP) is signaled if the memory
operand is not aligned on a 16-byte boundary, as described above. If the alignment check
exception (#AC) is enabled (and the CPL is 3), signaling of #AC is not guaranteed and may
vary with implementation, as follows. In all implementations where #AC is not signaled, a
general protection exception is signaled in its place. In addition, the width of the alignment
check may also vary with implementation. For instance, for a given implementation, an align-
ment check exception might be signaled for a 2-byte misalignment, whereas a general protec-
tion exception might be signaled for all other misalignments (4-, 8-, or 16-byte
misalignments).
Real-Address Mode Exceptions
#GP
If a memory operand is not aligned on a 16-byte boundary, regardless of segment.
If any part of the operand lies outside the effective address space from 0 to FFFFH.
#NM
If CR0.TS[bit 3] = 1.
If CR0.EM[bit 2] = 1.
#UD
If CPUID.01H:EDX.FXSR[24] = 0.
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
Same exceptions as in real address mode.
#PF(fault-code)
For a page fault.
#AC
For unaligned memory reference.
#UD
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-418
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the memory address is in a non-canonical form.
If memory operand is not aligned on a 16-byte boundary, regardless of segment.
#PF(fault-code)
For a page fault.
#NM
If CR0.TS[bit 3] = 1.
If CR0.EM[bit 2] = 1.
#UD
If CPUID.01H:EDX.FXSR[24] = 0.
If the LOCK prefix is used.
#AC
If this exception is disabled a general protection exception (#GP) is signaled if the memory
operand is not aligned on a 16-byte boundary, as described above. If the alignment check
exception (#AC) is enabled (and the CPL is 3), signaling of #AC is not guaranteed and may
vary with implementation, as follows. In all implementations where #AC is not signaled, a
general protection exception is signaled in its place. In addition, the width of the alignment
check may also vary with implementation. For instance, for a given implementation, an align-
ment check exception might be signaled for a 2-byte misalignment, whereas a general protec-
tion exception might be signaled for all other misalignments (4-, 8-, or 16-byte
misalignments).
Implementation Note
The order in which the processor signals general-protection (#GP) and page-fault (#PF) exceptions when they both
occur on an instruction boundary is given in Table 5-2 in the Intel® 64 and IA-32 Architectures Software Devel-
oper’s Manual, Volume 3B. This order vary for FXSAVE for different processor implementations.
FXSAVE-Save x87 FPU, MMX Technology, and SSE State
Vol. 2A
3-419

FXTRACT-Extract Exponent and Significand
Opcode/
64-Bit
Compat/
Description
Instruction
Mode
Leg Mode
D9 F4
Valid
Valid
Separate value in ST(0) into exponent and significand, store
exponent in ST(0), and push the significand onto the register
FXTRACT
stack.
Description
Separates the source value in the ST(0) register into its exponent and significand, stores the exponent in ST(0),
and pushes the significand onto the register stack. Following this operation, the new top-of-stack register ST(0)
contains the value of the original significand expressed as a floating-point value. The sign and significand of this
value are the same as those found in the source operand, and the exponent is 3FFFH (biased value for a true expo-
nent of zero). The ST(1) register contains the value of the original operand’s true (unbiased) exponent expressed
as a floating-point value. (The operation performed by this instruction is a superset of the IEEE-recommended
logb(x) function.)
This instruction and the F2XM1 instruction are useful for performing power and range scaling operations. The
FXTRACT instruction is also useful for converting numbers in double extended-precision floating-point format to
decimal representations (e.g., for printing or displaying).
If the floating-point zero-divide exception (#Z) is masked and the source operand is zero, an exponent value of -
∞ is stored in register ST(1) and 0 with the sign of the source operand is stored in register ST(0).
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
TEMP := Significand(ST(0));
ST(0) := Exponent(ST(0));
TOP := TOP - 1;
ST(0) := TEMP;
FPU Flags Affected
C1
Set to 0 if stack underflow occurred; set to 1 if stack overflow occurred.
C0, C2, C3
Undefined.
Floating-Point Exceptions
#IS
Stack underflow or overflow occurred.
#IA
Source operand is an SNaN value or unsupported format.
#Z
ST(0) operand is ±0.
#D
Source operand is a denormal value.
Protected Mode Exceptions
#NM
CR0.EM[bit 2] or CR0.TS[bit 3] = 1.
#MF
If there is a pending x87 FPU exception.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
FXTRACT-Extract Exponent and Significand
Vol. 2A
3-420
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
FXTRACT-Extract Exponent and Significand
Vol. 2A
3-421
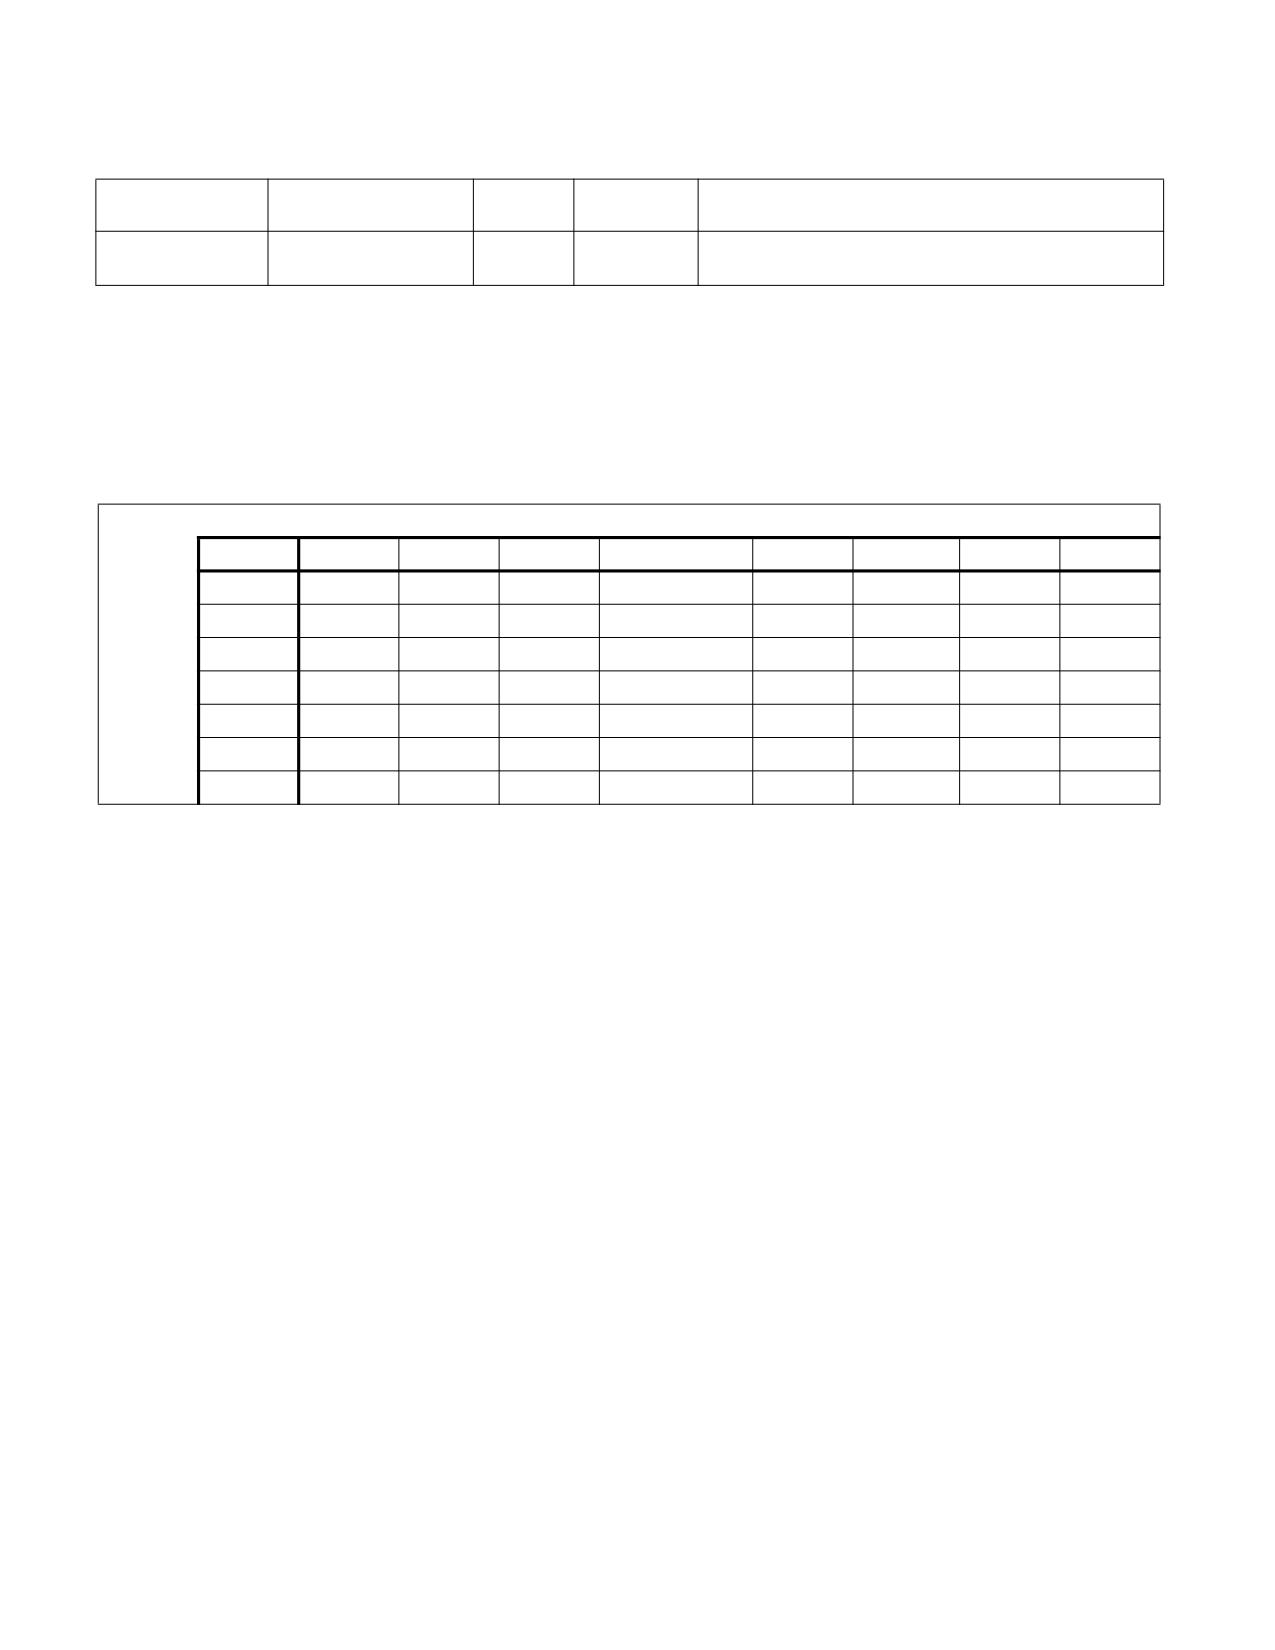
FYL2X-Compute y ∗ log2x
Opcode
Instruction
64-Bit
Compat/
Description
Mode
Leg Mode
D9 F1
FYL2X
Valid
Valid
Replace ST(1) with (ST(1) ∗ log2ST(0)) and pop the
register stack.
Description
Computes (ST(1) ∗ log2 (ST(0))), stores the result in register ST(1), and pops the FPU register stack. The source
operand in ST(0) must be a non-zero positive number.
The following table shows the results obtained when taking the log of various classes of numbers, assuming that
neither overflow nor underflow occurs.
Table 3-50. FYL2X Results
ST(0)
- ∞
- F
±0
+0<+F<+1
+ 1
+ F > + 1
+ ∞
NaN
− ∞
*
*
+ ∞
+ ∞
*
- ∞
- ∞
NaN
ST(1)
- F
*
*
**
+ F
- 0
- F
- ∞
NaN
− 0
*
*
*
+ 0
- 0
- 0
*
NaN
+ 0
*
*
*
- 0
+ 0
+ 0
*
NaN
+ F
*
*
**
- F
+ 0
+ F
+ ∞
NaN
+ ∞
*
*
- ∞
- ∞
*
+ ∞
+ ∞
NaN
NaN
NaN
NaN
NaN
NaN
NaN
NaN
NaN
NaN
NOTES:
F Means finite floating-point value.
* Indicates floating-point invalid-operation (#IA) exception.
** Indicates floating-point zero-divide (#Z) exception.
If the divide-by-zero exception is masked and register ST(0) contains ±0, the instruction returns ∞ with a sign that
is the opposite of the sign of the source operand in register ST(1).
The FYL2X instruction is designed with a built-in multiplication to optimize the calculation of logarithms with an
arbitrary positive base (b):
logbx := (log2b)-1 ∗ log2x
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
ST(1) := ST(1) ∗ log2ST(0);
PopRegisterStack;
FPU Flags Affected
C1
Set to 0 if stack underflow occurred.
Set if result was rounded up; cleared otherwise.
C0, C2, C3
Undefined.
FYL2X-Compute y * log2x
Vol. 2A
3-422
Floating-Point Exceptions
#IS
Stack underflow occurred.
#IA
Either operand is an SNaN or unsupported format.
Source operand in register ST(0) is a negative finite value
(not -0).
#Z
Source operand in register ST(0) is ±0.
#D
Source operand is a denormal value.
#U
Result is too small for destination format.
#O
Result is too large for destination format.
#P
Value cannot be represented exactly in destination format.
Protected Mode Exceptions
#NM
CR0.EM[bit 2] or CR0.TS[bit 3] = 1.
#MF
If there is a pending x87 FPU exception.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
FYL2X-Compute y * log2x
Vol. 2A
3-423
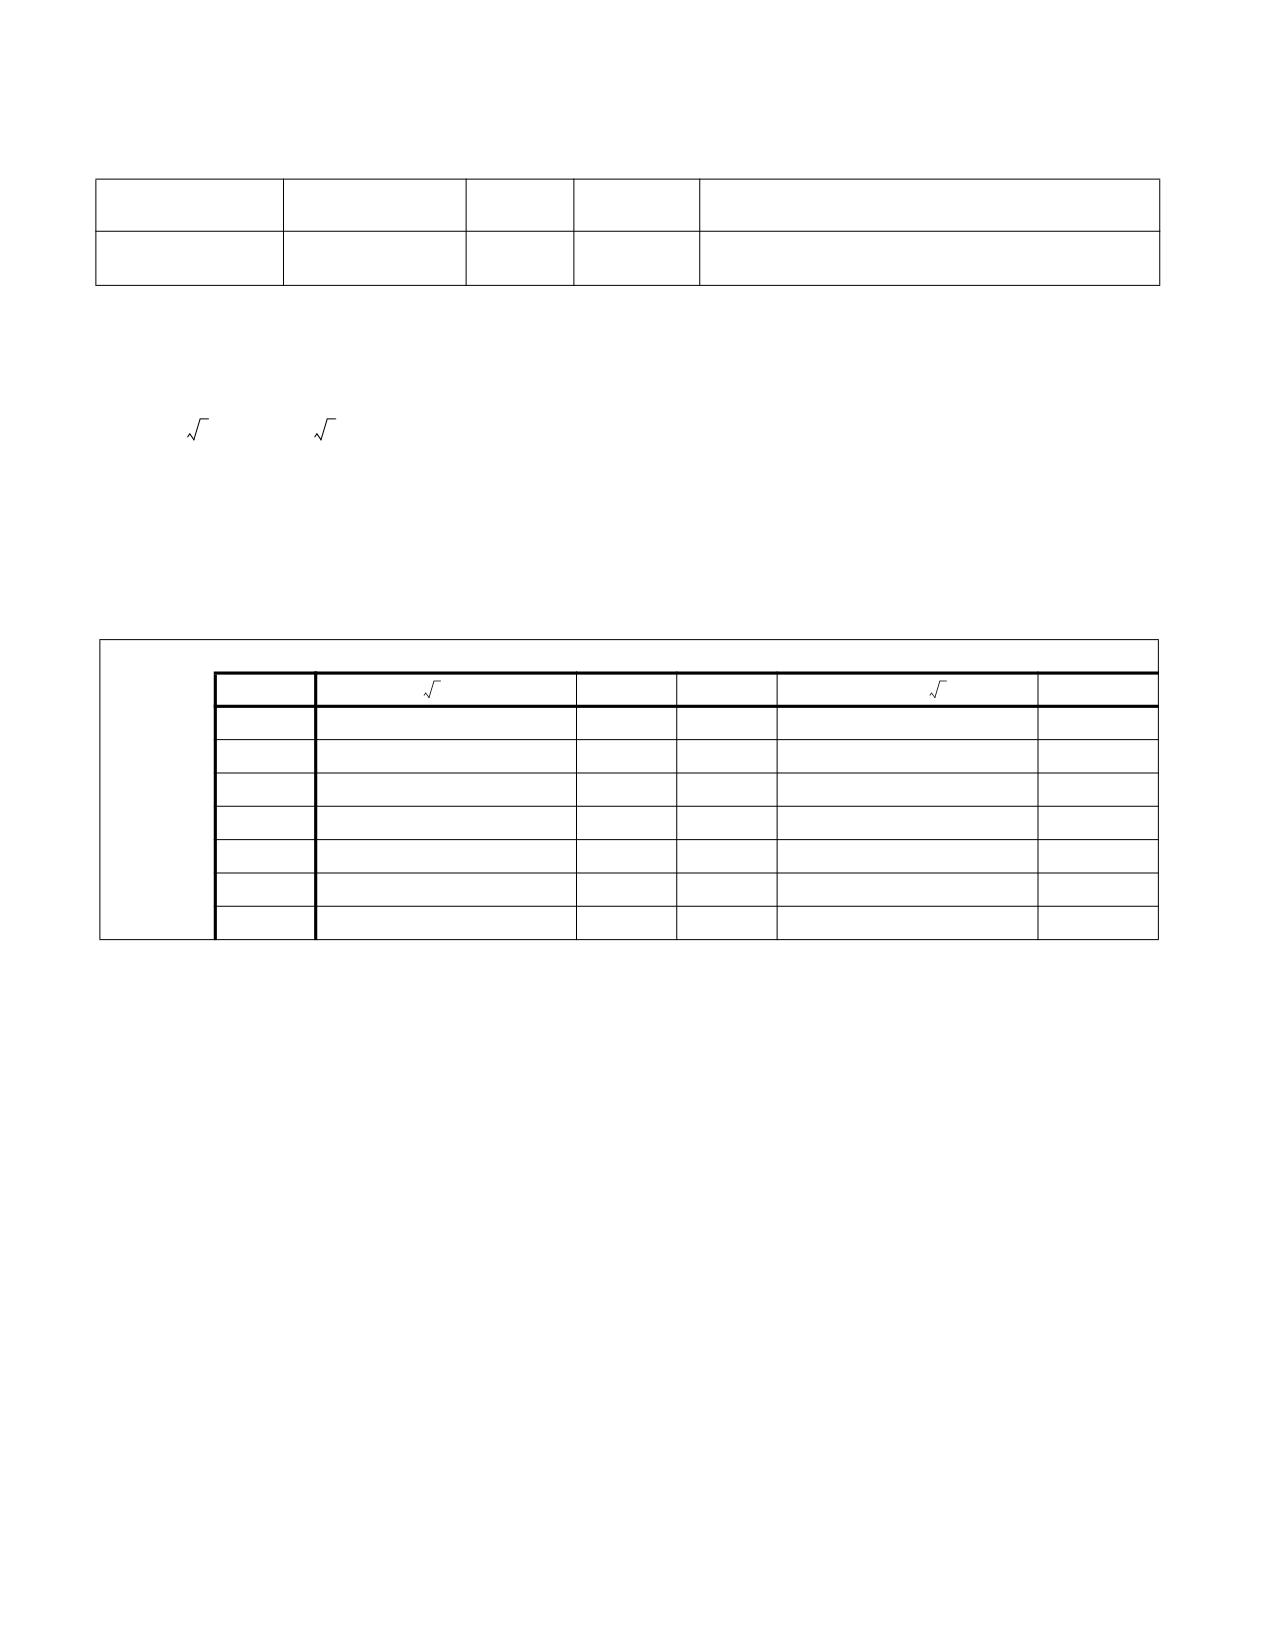
FYL2XP1-Compute y ∗ log2(x +1)
Opcode
Instruction
64-Bit
Compat/
Description
Mode
Leg Mode
D9 F9
FYL2XP1
Valid
Valid
Replace ST(1) with ST(1) ∗ log2(ST(0) + 1.0) and pop the
register stack.
Description
Computes (ST(1) ∗ log2(ST(0) + 1.0)), stores the result in register ST(1), and pops the FPU register stack. The
source operand in ST(0) must be in the range:
-(1 -
2⁄2))to(1-
2⁄2)
The source operand in ST(1) can range from -∞ to +∞. If the ST(0) operand is outside of its acceptable range, the
result is undefined and software should not rely on an exception being generated. Under some circumstances
exceptions may be generated when ST(0) is out of range, but this behavior is implementation specific and not
guaranteed.
The following table shows the results obtained when taking the log epsilon of various classes of numbers, assuming
that underflow does not occur.
Table 3-51. FYL2XP1 Results
ST(0)
-(1 - (
2⁄2
)) to -0
-0
+0
+0 to +(1 - (
2⁄2
))
NaN
− ∞
+∞
*
*
- ∞
NaN
ST(1)
- F
+F
+0
-0
- F
NaN
− 0
+0
+0
-0
- 0
NaN
+0
- 0
- 0
+0
+0
NaN
+F
- F
- 0
+0
+F
NaN
+∞
- ∞
*
*
+∞
NaN
NaN
NaN
NaN
NaN
NaN
NaN
NOTES:
F Means finite floating-point value.
* Indicates floating-point invalid-operation (#IA) exception.
This instruction provides optimal accuracy for values of epsilon [the value in register ST(0)] that are close to 0. For
small epsilon (ε) values, more significant digits can be retained by using the FYL2XP1 instruction than by using
(ε+1) as an argument to the FYL2X instruction. The (ε+1) expression is commonly found in compound interest and
annuity calculations. The result can be simply converted into a value in another logarithm base by including a scale
factor in the ST(1) source operand. The following equation is used to calculate the scale factor for a particular loga-
rithm base, where n is the logarithm base desired for the result of the FYL2XP1 instruction:
scale factor := logn 2
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
ST(1) := ST(1) ∗ log2(ST(0) + 1.0);
PopRegisterStack;
FYL2XP1-Compute y * log2(x +1)
Vol. 2A
3-424
FPU Flags Affected
C1
Set to 0 if stack underflow occurred.
Set if result was rounded up; cleared otherwise.
C0, C2, C3
Undefined.
Floating-Point Exceptions
#IS
Stack underflow occurred.
#IA
Either operand is an SNaN value or unsupported format.
#D
Source operand is a denormal value.
#U
Result is too small for destination format.
#O
Result is too large for destination format.
#P
Value cannot be represented exactly in destination format.
Protected Mode Exceptions
#NM
CR0.EM[bit 2] or CR0.TS[bit 3] = 1.
#MF
If there is a pending x87 FPU exception.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
FYL2XP1-Compute y * log2(x +1)
Vol. 2A
3-425

GF2P8AFFINEINVQB-Galois Field Affine Transformation Inverse
Opcode/
Op/
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0F3A CF /r /ib
A
V/V
GFNI
Computes inverse affine transformation in the
GF2P8AFFINEINVQB xmm1,
finite field GF(2^8).
xmm2/m128, imm8
VEX.128.66.0F3A.W1 CF /r /ib
B
V/V
AVX
Computes inverse affine transformation in the
VGF2P8AFFINEINVQB xmm1, xmm2,
GFNI
finite field GF(2^8).
xmm3/m128, imm8
VEX.256.66.0F3A.W1 CF /r /ib
B
V/V
AVX
Computes inverse affine transformation in the
VGF2P8AFFINEINVQB ymm1, ymm2,
GFNI
finite field GF(2^8).
ymm3/m256, imm8
EVEX.128.66.0F3A.W1 CF /r /ib
C
V/V
(AVX512VL
Computes inverse affine transformation in the
VGF2P8AFFINEINVQB xmm1{k1}{z},
OR AVX10.1)
finite field GF(2^8).
xmm2, xmm3/m128/m64bcst, imm8
GFNI
EVEX.256.66.0F3A.W1 CF /r /ib
C
V/V
(AVX512VL
Computes inverse affine transformation in the
VGF2P8AFFINEINVQB ymm1{k1}{z},
OR AVX10.1)
finite field GF(2^8).
ymm2, ymm3/m256/m64bcst, imm8
GFNI
EVEX.512.66.0F3A.W1 CF /r /ib
C
V/V
(AVX512F
Computes inverse affine transformation in the
VGF2P8AFFINEINVQB zmm1{k1}{z},
OR AVX10.1)
finite field GF(2^8).
zmm2, zmm3/m512/m64bcst, imm8
GFNI
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
imm8 (r)
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8 (r)
C
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8 (r)
Description
The AFFINEINVB instruction computes an affine transformation in the Galois Field 28. For this instruction, an affine
transformation is defined by A * inv(x) + b where “A” is an 8 by 8 bit matrix, and “x” and “b” are 8-bit vectors. The
inverse of the bytes in x is defined with respect to the reduction polynomial x8 + x4 + x3 + x + 1.
One SIMD register (operand 1) holds “x” as either 16, 32 or 64 8-bit vectors. A second SIMD (operand 2) register
or memory operand contains 2, 4, or 8 “A” values, which are operated upon by the correspondingly aligned 8 “x”
values in the first register. The “b” vector is constant for all calculations and contained in the immediate byte.
The EVEX encoded form of this instruction does not support memory fault suppression. The SSE encoded forms of
the instruction require 16B alignment on their memory operations.
The inverse of each byte is given by the following table. The upper nibble is on the vertical axis and the lower nibble
is on the horizontal axis. For example, the inverse of 0x95 is 0x8A.
GF2P8AFFINEINVQB-Galois Field Affine Transformation Inverse
Vol. 2A
3-426

Table 3-52. Inverse Byte Listings
-
0
1
2
3
4
5
6
7
8
9
A
B
C
D
E
F
0
0
1
8D
F6
CB
52
7B
D1
E8
4F
29
C0
B0
E1
E5
C7
1
74
B4
AA
4B
99
2B
60
5F
58
3F
FD
CC
FF
40
EE
B2
2
3A
6E
5A
F1
55
4D
A8
C9
C1
A
98
15
30
44
A2
C2
3
2C
45
92
6C
F3
39
66
42
F2
35
20
6F
77
BB
59
19
4
1D
FE
37
67
2D
31
F5
69
A7
64
AB
13
54
25
E9
9
5
ED
5C
5
CA
4C
24
87
BF
18
3E
22
F0
51
EC
61
17
6
16
5E
AF
D3
49
A6
36
43
F4
47
91
DF
33
93
21
3B
7
79
B7
97
85
10
B5
BA
3C
B6
70
D0
6
A1
FA
81
82
8
83
7E
7F
80
96
73
BE
56
9B
9E
95
D9
F7
2
B9
A4
9
DE
6A
32
6D
D8
8A
84
72
2A
14
9F
88
F9
DC
89
9A
A
FB
7C
2E
C3
8F
B8
65
48
26
C8
12
4A
CE
E7
D2
62
B
C
E0
1F
EF
11
75
78
71
A5
8E
76
3D
BD
BC
86
57
C
B
28
2F
A3
DA
D4
E4
F
A9
27
53
4
1B
FC
AC
E6
D
7A
7
AE
63
C5
DB
E2
EA
94
8B
C4
D5
9D
F8
90
6B
E
B1
D
D6
EB
C6
E
CF
AD
8
4E
D7
E3
5D
50
1E
B3
F
5B
23
38
34
68
46
3
8C
DD
9C
7D
A0
CD
1A
41
1C
Operation
define affine_inverse_byte(tsrc2qw, src1byte, imm):
FOR i := 0 to 7:
* parity(x) = 1 if x has an odd number of 1s in it, and 0 otherwise.*
* inverse(x) is defined in the table above *
retbyte.bit[i] := parity(tsrc2qw.byte[7-i] AND inverse(src1byte)) XOR imm8.bit[i]
return retbyte
VGF2P8AFFINEINVQB dest, src1, src2, imm8 (EVEX Encoded Version)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1:
IF SRC2 is memory and EVEX.b==1:
tsrc2 := SRC2.qword[0]
ELSE:
tsrc2 := SRC2.qword[j]
FOR b := 0 to 7:
IF k1[j*8+b] OR *no writemask*:
FOR i := 0 to 7:
DEST.qword[j].byte[b] := affine_inverse_byte(tsrc2, SRC1.qword[j].byte[b], imm8)
ELSE IF *zeroing*:
DEST.qword[j].byte[b] := 0
*ELSE DEST.qword[j].byte[b] remains unchanged*
DEST[MAX_VL-1:VL] := 0
GF2P8AFFINEINVQB-Galois Field Affine Transformation Inverse
Vol. 2A
3-427
VGF2P8AFFINEINVQB dest, src1, src2, imm8 (128b and 256b VEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256)
FOR j := 0 TO KL-1:
FOR b := 0 to 7:
DEST.qword[j].byte[b] := affine_inverse_byte(SRC2.qword[j], SRC1.qword[j].byte[b], imm8)
DEST[MAX_VL-1:VL] := 0
GF2P8AFFINEINVQB srcdest, src1, imm8 (128b SSE Encoded Version)
FOR j := 0 TO 1:
FOR b := 0 to 7:
SRCDEST.qword[j].byte[b] := affine_inverse_byte(SRC1.qword[j], SRCDEST.qword[j].byte[b], imm8)
Intel C/C++ Compiler Intrinsic Equivalent
(V)GF2P8AFFINEINVQB __m128i _mm_gf2p8affineinv_epi64_epi8(__m128i, __m128i, int);
(V)GF2P8AFFINEINVQB __m128i _mm_mask_gf2p8affineinv_epi64_epi8(__m128i, __mmask16, __m128i, __m128i, int);
(V)GF2P8AFFINEINVQB __m128i _mm_maskz_gf2p8affineinv_epi64_epi8(__mmask16, __m128i, __m128i, int);
VGF2P8AFFINEINVQB __m256i _mm256_gf2p8affineinv_epi64_epi8(__m256i, __m256i, int);
VGF2P8AFFINEINVQB __m256i _mm256_mask_gf2p8affineinv_epi64_epi8(__m256i, __mmask32, __m256i, __m256i, int);
VGF2P8AFFINEINVQB __m256i _mm256_maskz_gf2p8affineinv_epi64_epi8(__mmask32, __m256i, __m256i, int);
VGF2P8AFFINEINVQB __m512i _mm512_gf2p8affineinv_epi64_epi8(__m512i, __m512i, int);
VGF2P8AFFINEINVQB __m512i _mm512_mask_gf2p8affineinv_epi64_epi8(__m512i, __mmask64, __m512i, __m512i, int);
VGF2P8AFFINEINVQB __m512i _mm512_maskz_gf2p8affineinv_epi64_epi8(__mmask64, __m512i, __m512i, int);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Legacy-encoded and VEX-encoded: See Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded: See Table 2-52, “Type E4NF Class Exception Conditions.”
GF2P8AFFINEINVQB-Galois Field Affine Transformation Inverse
Vol. 2A
3-428

GF2P8AFFINEQB-Galois Field Affine Transformation
Opcode/
Op/
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0F3A CE /r /ib
A
V/V
GFNI
Computes affine transformation in the finite
GF2P8AFFINEQB xmm1,
field GF(2^8).
xmm2/m128, imm8
VEX.128.66.0F3A.W1 CE /r /ib
B
V/V
AVX
Computes affine transformation in the finite
VGF2P8AFFINEQB xmm1, xmm2,
GFNI
field GF(2^8).
xmm3/m128, imm8
VEX.256.66.0F3A.W1 CE /r /ib
B
V/V
AVX
Computes affine transformation in the finite
VGF2P8AFFINEQB ymm1, ymm2,
GFNI
field GF(2^8).
ymm3/m256, imm8
EVEX.128.66.0F3A.W1 CE /r /ib
C
V/V
(AVX512VL
Computes affine transformation in the finite
VGF2P8AFFINEQB xmm1{k1}{z},
OR AVX10.1)
field GF(2^8).
xmm2, xmm3/m128/m64bcst, imm8
GFNI
EVEX.256.66.0F3A.W1 CE /r /ib
C
V/V
(AVX512VL
Computes affine transformation in the finite
VGF2P8AFFINEQB ymm1{k1}{z},
OR AVX10.1)
field GF(2^8).
ymm2, ymm3/m256/m64bcst, imm8
GFNI
EVEX.512.66.0F3A.W1 CE /r /ib
C
V/V
(AVX512F
Computes affine transformation in the finite
VGF2P8AFFINEQB zmm1{k1}{z},
OR AVX10.1)
field GF(2^8).
zmm2, zmm3/m512/m64bcst, imm8
GFNI
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
imm8 (r)
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8 (r)
C
Full
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8 (r)
Description
The AFFINEB instruction computes an affine transformation in the Galois Field 28. For this instruction, an affine
transformation is defined by A * x + b where “A” is an 8 by 8 bit matrix, and “x” and “b” are 8-bit vectors. One SIMD
register (operand 1) holds “x” as either 16, 32 or 64 8-bit vectors. A second SIMD (operand 2) register or memory
operand contains 2, 4, or 8 “A” values, which are operated upon by the correspondingly aligned 8 “x” values in the
first register. The “b” vector is constant for all calculations and contained in the immediate byte.
The EVEX encoded form of this instruction does not support memory fault suppression. The SSE encoded forms of
the instruction require16B alignment on their memory operations.
Operation
define parity(x):
t := 0
// single bit
FOR i := 0 to 7:
t = t xor x.bit[i]
return t
define affine_byte(tsrc2qw, src1byte, imm):
FOR i := 0 to 7:
* parity(x) = 1 if x has an odd number of 1s in it, and 0 otherwise.*
retbyte.bit[i] := parity(tsrc2qw.byte[7-i] AND src1byte) XOR imm8.bit[i]
return retbyte
GF2P8AFFINEQB-Galois Field Affine Transformation
Vol. 2A
3-429
VGF2P8AFFINEQB dest, src1, src2, imm8 (EVEX Encoded Version)
(KL, VL) = (2, 128), (4, 256), (8, 512)
FOR j := 0 TO KL-1:
IF SRC2 is memory and EVEX.b==1:
tsrc2 := SRC2.qword[0]
ELSE:
tsrc2 := SRC2.qword[j]
FOR b := 0 to 7:
IF k1[j*8+b] OR *no writemask*:
DEST.qword[j].byte[b] := affine_byte(tsrc2, SRC1.qword[j].byte[b], imm8)
ELSE IF *zeroing*:
DEST.qword[j].byte[b] := 0
*ELSE DEST.qword[j].byte[b] remains unchanged*
DEST[MAX_VL-1:VL] := 0
VGF2P8AFFINEQB dest, src1, src2, imm8 (128b and 256b VEX Encoded Versions)
(KL, VL) = (2, 128), (4, 256)
FOR j := 0 TO KL-1:
FOR b := 0 to 7:
DEST.qword[j].byte[b] := affine_byte(SRC2.qword[j], SRC1.qword[j].byte[b], imm8)
DEST[MAX_VL-1:VL] := 0
GF2P8AFFINEQB srcdest, src1, imm8 (128b SSE Encoded Version)
FOR j := 0 TO 1:
FOR b := 0 to 7:
SRCDEST.qword[j].byte[b] := affine_byte(SRC1.qword[j], SRCDEST.qword[j].byte[b], imm8)
Intel C/C++ Compiler Intrinsic Equivalent
(V)GF2P8AFFINEQB __m128i _mm_gf2p8affine_epi64_epi8(__m128i, __m128i, int);
(V)GF2P8AFFINEQB __m128i _mm_mask_gf2p8affine_epi64_epi8(__m128i, __mmask16, __m128i, __m128i, int);
(V)GF2P8AFFINEQB __m128i _mm_maskz_gf2p8affine_epi64_epi8(__mmask16, __m128i, __m128i, int);
VGF2P8AFFINEQB __m256i _mm256_gf2p8affine_epi64_epi8(__m256i, __m256i, int);
VGF2P8AFFINEQB __m256i _mm256_mask_gf2p8affine_epi64_epi8(__m256i, __mmask32, __m256i, __m256i, int);
VGF2P8AFFINEQB __m256i _mm256_maskz_gf2p8affine_epi64_epi8(__mmask32, __m256i, __m256i, int);
VGF2P8AFFINEQB __m512i _mm512_gf2p8affine_epi64_epi8(__m512i, __m512i, int);
VGF2P8AFFINEQB __m512i _mm512_mask_gf2p8affine_epi64_epi8(__m512i, __mmask64, __m512i, __m512i, int);
VGF2P8AFFINEQB __m512i _mm512_maskz_gf2p8affine_epi64_epi8(__mmask64, __m512i, __m512i, int);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Legacy-encoded and VEX-encoded: See Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded: See Table 2-52, “Type E4NF Class Exception Conditions.”
GF2P8AFFINEQB-Galois Field Affine Transformation
Vol. 2A
3-430

GF2P8MULB-Galois Field Multiply Bytes
Opcode/
Op/
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
66 0F38 CF /r
A
V/V
GFNI
Multiplies elements in the finite field GF(2^8).
GF2P8MULB xmm1, xmm2/m128
VEX.128.66.0F38.W0 CF /r
B
V/V
AVX
Multiplies elements in the finite field GF(2^8).
VGF2P8MULB xmm1, xmm2,
GFNI
xmm3/m128
VEX.256.66.0F38.W0 CF /r
B
V/V
AVX
Multiplies elements in the finite field GF(2^8).
VGF2P8MULB ymm1, ymm2,
GFNI
ymm3/m256
EVEX.128.66.0F38.W0 CF /r
C
V/V
(AVX512VL
Multiplies elements in the finite field GF(2^8).
VGF2P8MULB xmm1{k1}{z}, xmm2,
OR AVX10.1)
xmm3/m128
GFNI
EVEX.256.66.0F38.W0 CF /r
C
V/V
(AVX512VL
Multiplies elements in the finite field GF(2^8).
VGF2P8MULB ymm1{k1}{z}, ymm2,
OR AVX10.1)
ymm3/m256
GFNI
EVEX.512.66.0F38.W0 CF /r
C
V/V
(AVX512F
Multiplies elements in the finite field GF(2^8).
VGF2P8MULB zmm1{k1}{z}, zmm2,
OR AVX10.1)
zmm3/m512
GFNI
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
C
Full Mem
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
The instruction multiplies elements in the finite field GF(28), operating on a byte (field element) in the first source
operand and the corresponding byte in a second source operand. The field GF(28) is represented in polynomial
representation with the reduction polynomial x8 + x4 + x3 + x + 1.
This instruction does not support broadcasting.
The EVEX encoded form of this instruction supports memory fault suppression. The SSE encoded forms of the
instruction require16B alignment on their memory operations.
GF2P8MULB-Galois Field Multiply Bytes
Vol. 2A
3-431
Operation
define gf2p8mul_byte(src1byte, src2byte):
tword := 0
FOR i := 0 to 7:
IF src2byte.bit[i]:
tword := tword XOR (src1byte<< i)
* carry out polynomial reduction by the characteristic polynomial p*
FOR i := 14 downto 8:
p := 0x11B << (i-8)
*0x11B = 0000_0001_0001_1011 in binary*
IF tword.bit[i]:
tword := tword XOR p
return tword.byte[0]
VGF2P8MULB dest, src1, src2 (EVEX Encoded Version)
(KL, VL) = (16, 128), (32, 256), (64, 512)
FOR j := 0 TO KL-1:
IF k1[j] OR *no writemask*:
DEST.byte[j] := gf2p8mul_byte(SRC1.byte[j], SRC2.byte[j])
ELSE IF *zeroing*:
DEST.byte[j] := 0
* ELSE DEST.byte[j] remains unchanged*
DEST[MAX_VL-1:VL] := 0
VGF2P8MULB dest, src1, src2 (128b and 256b VEX Encoded Versions)
(KL, VL) = (16, 128), (32, 256)
FOR j := 0 TO KL-1:
DEST.byte[j] := gf2p8mul_byte(SRC1.byte[j], SRC2.byte[j])
DEST[MAX_VL-1:VL] := 0
GF2P8MULB srcdest, src1 (128b SSE Encoded Version)
FOR j := 0 TO 15:
SRCDEST.byte[j] :=gf2p8mul_byte(SRCDEST.byte[j], SRC1.byte[j])
Intel C/C++ Compiler Intrinsic Equivalent
(V)GF2P8MULB __m128i _mm_gf2p8mul_epi8(__m128i, __m128i);
(V)GF2P8MULB __m128i _mm_mask_gf2p8mul_epi8(__m128i, __mmask16, __m128i, __m128i);
(V)GF2P8MULB __m128i _mm_maskz_gf2p8mul_epi8(__mmask16, __m128i, __m128i);
VGF2P8MULB __m256i _mm256_gf2p8mul_epi8(__m256i, __m256i);
VGF2P8MULB __m256i _mm256_mask_gf2p8mul_epi8(__m256i, __mmask32, __m256i, __m256i);
VGF2P8MULB __m256i _mm256_maskz_gf2p8mul_epi8(__mmask32, __m256i, __m256i);
VGF2P8MULB __m512i _mm512_gf2p8mul_epi8(__m512i, __m512i);
VGF2P8MULB __m512i _mm512_mask_gf2p8mul_epi8(__m512i, __mmask64, __m512i, __m512i);
VGF2P8MULB __m512i _mm512_maskz_gf2p8mul_epi8(__mmask64, __m512i, __m512i);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Legacy-encoded and VEX-encoded: See Table 2-21, “Type 4 Class Exception Conditions.”
EVEX-encoded: See Table 2-51, “Type E4 Class Exception Conditions.”
GF2P8MULB-Galois Field Multiply Bytes
Vol. 2A
3-432
HADDPD-Packed Double Precision Floating-Point Horizontal Add
Opcode/
Op/
64/32-bit
CPUID
Description
Instruction
En
Mode
Feature
Flag
66 0F 7C /r
RM
V/V
SSE3
Horizontal add packed double precision
floating-point values from xmm2/m128 to
HADDPD xmm1, xmm2/m128
xmm1.
VEX.128.66.0F.WIG 7C /r
RVM
V/V
AVX
Horizontal add packed double precision
floating-point values from xmm2 and
VHADDPD xmm1,xmm2, xmm3/m128
xmm3/mem.
VEX.256.66.0F.WIG 7C /r
RVM
V/V
AVX
Horizontal add packed double precision
floating-point values from ymm2 and
VHADDPD ymm1, ymm2, ymm3/m256
ymm3/mem.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
RVM
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Adds the double precision floating-point values in the high and low quadwords of the destination operand and
stores the result in the low quadword of the destination operand.
Adds the double precision floating-point values in the high and low quadwords of the source operand and stores the
result in the high quadword of the destination operand.
In 64-bit mode, use of the REX.R prefix permits this instruction to access additional registers (XMM8-XMM15).
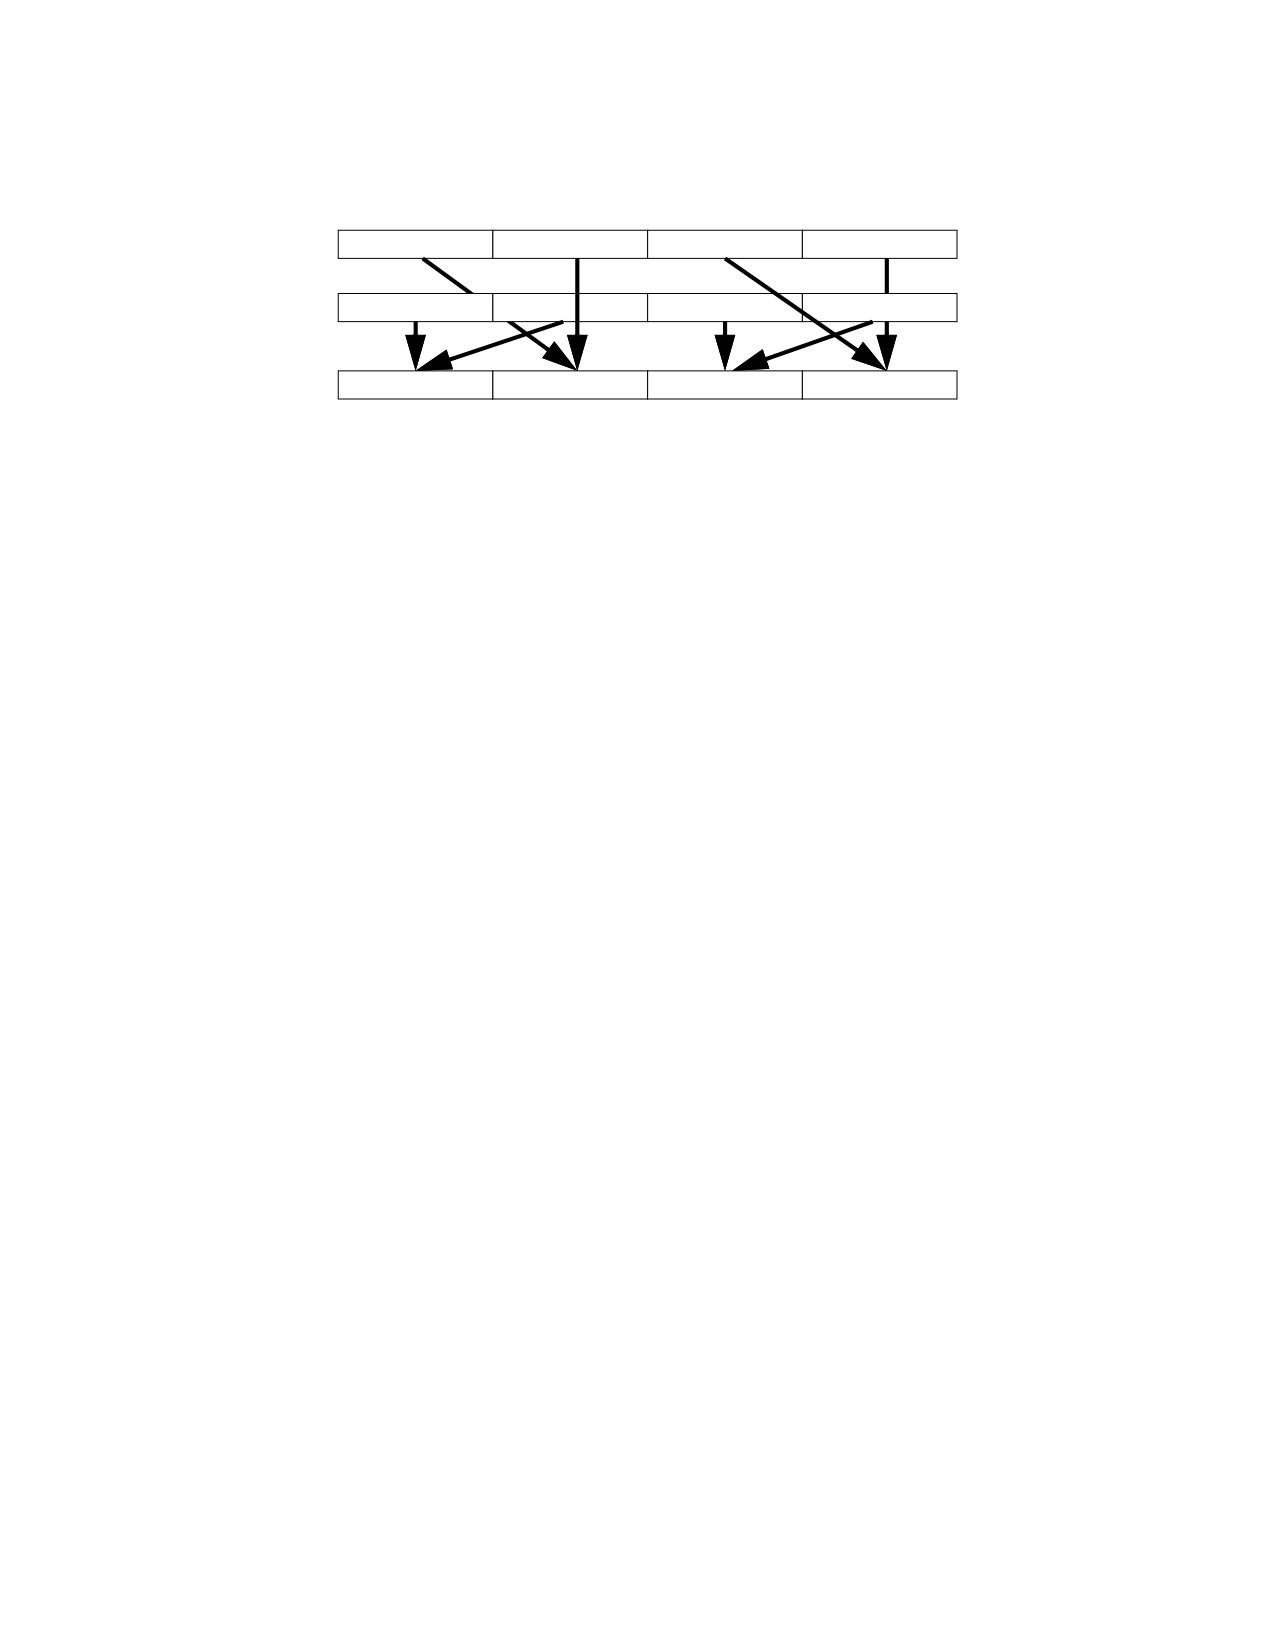
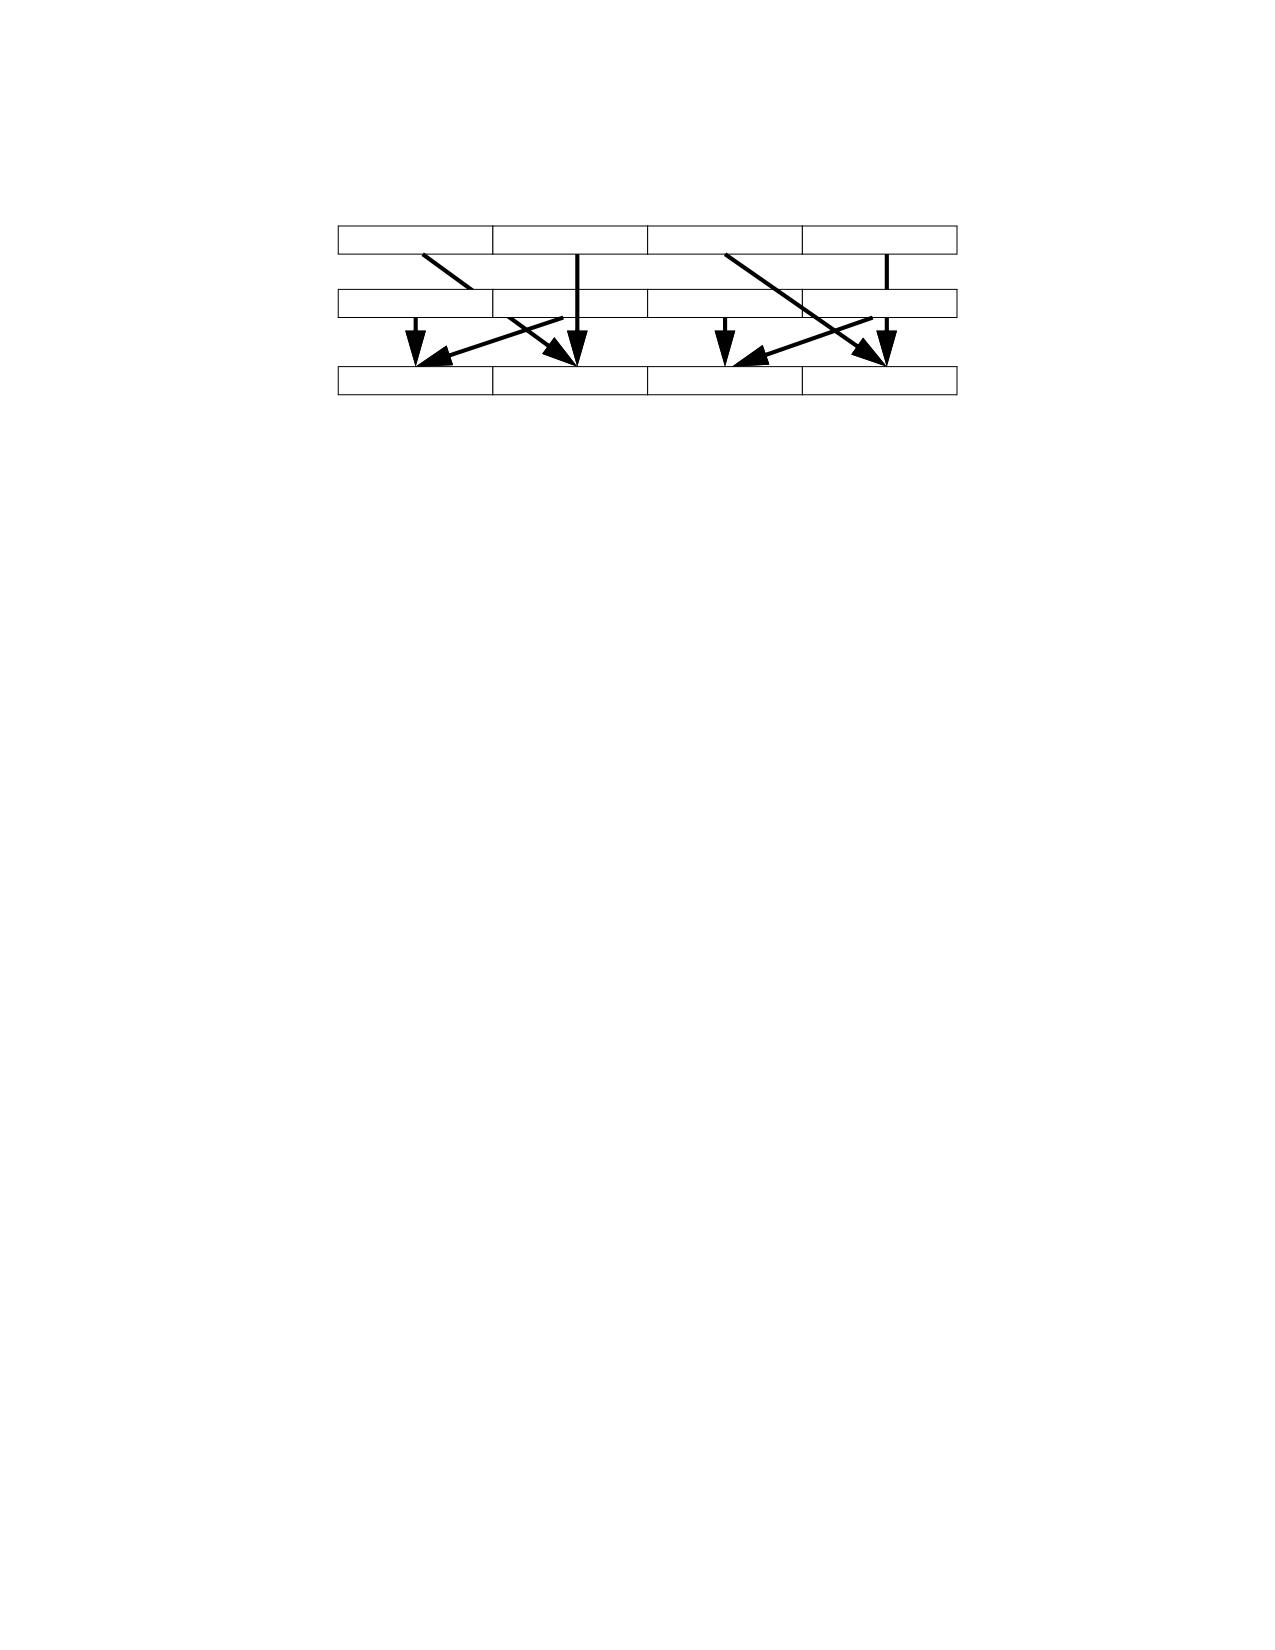
See Figure 3-12 for HADDPD; see Figure 3-13 for VHADDPD.
HADDPD xmm1, xmm2/m128
xmm2
[127:64]
[63:0]
/m128
[127:64]
[63:0]
xmm1
xmm2/m128[63:0] +
Result:
xmm1[63:0] + xmm1[127:64]
xmm2/m128[127:64]
xmm1
[127:64]
[63:0]
OM15993
Figure 3-12. HADDPD-Packed Double Precision Floating-Point Horizontal Add
HADDPD-Packed Double Precision Floating-Point Horizontal Add
Vol. 2A
3-433
SRC1
X3
X2
X1
X0
SRC2
Y3
Y
2
Y1
Y0
DEST
Y2 + Y3
X2 + X3
Y0 + Y1
X0 + X1
Figure 3-13. VHADDPD Operation
128-bit Legacy SSE version: The second source can be an XMM register or an 128-bit memory location. The desti-
nation is not distinct from the first source XMM register and the upper bits (MAXVL-1:128) of the corresponding
YMM register destination are unmodified.
VEX.128 encoded version: the first source operand is an XMM register or 128-bit memory location. The destination
operand is an XMM register. The upper bits (MAXVL-1:128) of the corresponding YMM register destination are
zeroed.
VEX.256 encoded version: The first source operand is a YMM register. The second source operand can be a YMM
register or a 256-bit memory location. The destination operand is a YMM register.
Operation
HADDPD (128-bit Legacy SSE Version)
DEST[63:0] := SRC1[127:64] + SRC1[63:0]
DEST[127:64] := SRC2[127:64] + SRC2[63:0]
DEST[MAXVL-1:128] (Unmodified)
VHADDPD (VEX.128 Encoded Version)
DEST[63:0] := SRC1[127:64] + SRC1[63:0]
DEST[127:64] := SRC2[127:64] + SRC2[63:0]
DEST[MAXVL-1:128] := 0
VHADDPD (VEX.256 Encoded Version)
DEST[63:0] := SRC1[127:64] + SRC1[63:0]
DEST[127:64] := SRC2[127:64] + SRC2[63:0]
DEST[191:128] := SRC1[255:192] + SRC1[191:128]
DEST[255:192] := SRC2[255:192] + SRC2[191:128]
Intel C/C++ Compiler Intrinsic Equivalent
VHADDPD __m256d _mm256_hadd_pd (__m256d a, __m256d b);
HADDPD __m128d _mm_hadd_pd (__m128d a, __m128d b);
Exceptions
When the source operand is a memory operand, the operand must be aligned on a 16-byte boundary or a general-
protection exception (#GP) will be generated.
Numeric Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
HADDPD-Packed Double Precision Floating-Point Horizontal Add
Vol. 2A
3-434
Other Exceptions
See Table 2-19, “Type 2 Class Exception Conditions.”
HADDPD-Packed Double Precision Floating-Point Horizontal Add
Vol. 2A
3-435
HADDPS-Packed Single Precision Floating-Point Horizontal Add
Opcode/
Op/
64/32-bit
CPUID
Description
Instruction
En
Mode
Feature
Flag
F2 0F 7C /r
RM
V/V
SSE3
Horizontal add packed single precision
floating-point values from xmm2/m128 to
HADDPS xmm1, xmm2/m128
xmm1.
VEX.128.F2.0F.WIG 7C /r
RVM
V/V
AVX
Horizontal add packed single precision floating-
point values from xmm2 and xmm3/mem.
VHADDPS xmm1, xmm2, xmm3/m128
VEX.256.F2.0F.WIG 7C /r
RVM
V/V
AVX
Horizontal add packed single precision floating-
point values from ymm2 and ymm3/mem.
VHADDPS ymm1, ymm2, ymm3/m256
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
RVM
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Adds the single precision floating-point values in the first and second dwords of the destination operand and stores
the result in the first dword of the destination operand.
Adds single precision floating-point values in the third and fourth dword of the destination operand and stores the
result in the second dword of the destination operand.
Adds single precision floating-point values in the first and second dword of the source operand and stores the result
in the third dword of the destination operand.
Adds single precision floating-point values in the third and fourth dword of the source operand and stores the result
in the fourth dword of the destination operand.
In 64-bit mode, use of the REX.R prefix permits this instruction to access additional registers (XMM8-XMM15).
HADDPS-Packed Single Precision Floating-Point Horizontal Add
Vol. 2A
3-436
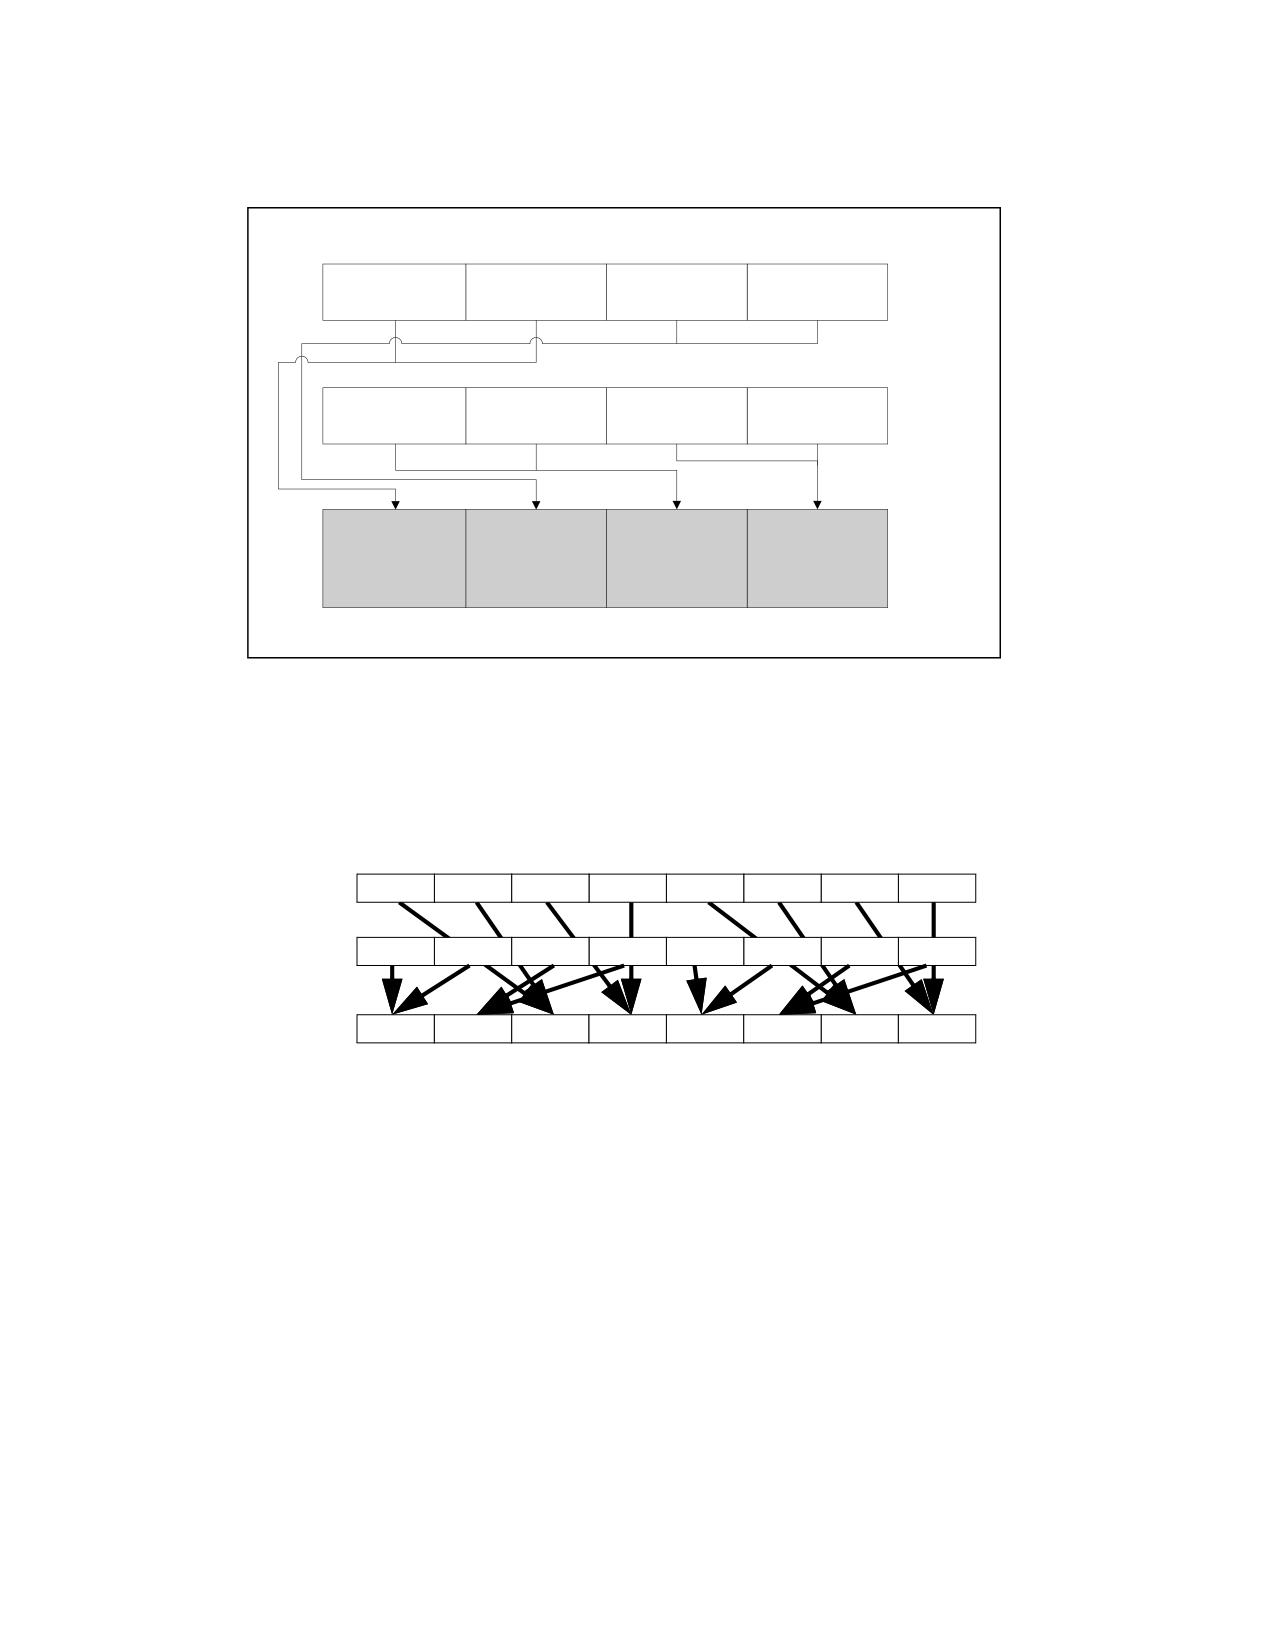
See Figure 3-14 for HADDPS; see Figure 3-15 for VHADDPS.
HADDPS xmm1, xmm2/m128
xmm2/
[127:96]
[95:64]
[63:32]
[31:0]
m128
[127:96]
[95:64]
[63:32]
[31:0]
xmm1
xmm2/m128
xmm2/m128
xmm1[95:64] +
xmm1[31:0] +
RESULT:
[95:64] + xmm2/
[31:0] + xmm2/
xmm1[127:96]
xmm1[63:32]
xmm1
m128[127:96]
m128[63:32]
[127:96]
[95:64]
[63:32]
[31:0]
OM15994
Figure 3-14. HADDPS-Packed Single Precision Floating-Point Horizontal Add
SRC1
X7
X6
X5
X4
X3
X2
X1
X0
SRC2
Y7
Y6
Y5
Y4
Y3
Y2
Y1
Y0
DEST
Y6+Y7
Y4+Y5
X6+X7
X4+X5
Y2+Y3
Y0+Y1
X2+X3
X0+X1
Figure 3-15. VHADDPS Operation
128-bit Legacy SSE version: The second source can be an XMM register or an 128-bit memory location. The desti-
nation is not distinct from the first source XMM register and the upper bits (MAXVL-1:128) of the corresponding
YMM register destination are unmodified.
VEX.128 encoded version: the first source operand is an XMM register or 128-bit memory location. The destination
operand is an XMM register. The upper bits (MAXVL-1:128) of the corresponding YMM register destination are
zeroed.
VEX.256 encoded version: The first source operand is a YMM register. The second source operand can be a YMM
register or a 256-bit memory location. The destination operand is a YMM register.
HADDPS-Packed Single Precision Floating-Point Horizontal Add
Vol. 2A
3-437
Operation
HADDPS (128-bit Legacy SSE Version)
DEST[31:0] := SRC1[63:32] + SRC1[31:0]
DEST[63:32] := SRC1[127:96] + SRC1[95:64]
DEST[95:64] := SRC2[63:32] + SRC2[31:0]
DEST[127:96] := SRC2[127:96] + SRC2[95:64]
DEST[MAXVL-1:128] (Unmodified)
VHADDPS (VEX.128 Encoded Version)
DEST[31:0] := SRC1[63:32] + SRC1[31:0]
DEST[63:32] := SRC1[127:96] + SRC1[95:64]
DEST[95:64] := SRC2[63:32] + SRC2[31:0]
DEST[127:96] := SRC2[127:96] + SRC2[95:64]
DEST[MAXVL-1:128] := 0
VHADDPS (VEX.256 Encoded Version)
DEST[31:0] := SRC1[63:32] + SRC1[31:0]
DEST[63:32] := SRC1[127:96] + SRC1[95:64]
DEST[95:64] := SRC2[63:32] + SRC2[31:0]
DEST[127:96] := SRC2[127:96] + SRC2[95:64]
DEST[159:128] := SRC1[191:160] + SRC1[159:128]
DEST[191:160] := SRC1[255:224] + SRC1[223:192]
DEST[223:192] := SRC2[191:160] + SRC2[159:128]
DEST[255:224] := SRC2[255:224] + SRC2[223:192]
Intel C/C++ Compiler Intrinsic Equivalent
HADDPS __m128 _mm_hadd_ps (__m128 a, __m128 b);
VHADDPS __m256 _mm256_hadd_ps (__m256 a, __m256 b);
Exceptions
When the source operand is a memory operand, the operand must be aligned on a 16-byte boundary or a general-
protection exception (#GP) will be generated.
Numeric Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
See Table 2-19, “Type 2 Class Exception Conditions.”
HADDPS-Packed Single Precision Floating-Point Horizontal Add
Vol. 2A
3-438

HLT-Halt
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
F4
HLT
ZO
Valid
Valid
Halt
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
ZO
N/A
N/A
N/A
N/A
Description
Stops instruction execution and places the processor in a HALT state. An enabled interrupt (including NMI and
SMI), a debug exception, the BINIT# signal, the INIT# signal, or the RESET# signal will resume execution. If an
interrupt (including NMI) is used to resume execution after a HLT instruction, the saved instruction pointer
(CS:EIP) points to the instruction following the HLT instruction.
When a HLT instruction is executed on an Intel 64 or IA-32 processor supporting Intel Hyper-Threading Technology,
only the logical processor that executes the instruction is halted. The other logical processors in the physical
processor remain active, unless they are each individually halted by executing a HLT instruction.
The HLT instruction is a privileged instruction. When the processor is running in protected or virtual-8086 mode,
the privilege level of a program or procedure must be 0 to execute the HLT instruction.
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
Enter Halt state;
Flags Affected
None.
Protected Mode Exceptions
#GP(0)
If the current privilege level is not 0.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
None.
Virtual-8086 Mode Exceptions
Same exceptions as in protected mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
HLT-Halt
Vol. 2A
3-439
HRESET-History Reset
Opcode/
Op/
64/32 bit
CPUID Feature
Description
Instruction
En
Mode
Flag
Support
F3 0F 3A F0 C0 /ib
A
V/V
HRESET
Processor history reset request. Controlled by the
HRESET imm8, <EAX>
EAX implicit operand.
Instruction Operand Encoding
Op/En
Tuple
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:r/m (r)
N/A
N/A
N/A
Description
Requests the processor to selectively reset selected components of hardware history maintained by the current
logical processor. HRESET operation is controlled by the implicit EAX operand. The value of the explicit imm8
operand is ignored. This instruction can only be executed at privilege level 0.
The HRESET instruction can be used to request reset of multiple components of hardware history. Prior to the
execution of HRESET, the system software must take the following steps:
1. Enumerate the HRESET capabilities via CPUID.20H.00H:EBX, which indicates what components of hardware
history can be reset.
2. Only the bits enumerated by CPUID.20H.00H:EBX can be set in the IA32_HRESET_ENABLE MSR.
HRESET causes a general-protection exception (#GP) if EAX sets any bits that are not set in the IA32_HRESET_EN-
ABLE MSR.
Any attempt to execute the HRESET instruction inside a transactional region will result in a transaction abort.
Operation
IF EAX = 0
THEN NOP
ELSE
FOREACH i such that EAX[i] = 1
Reset prediction history for feature i
FI
Flags Affected
None.
Protected Mode Exceptions
#GP(0)
If CPL > 0 or (EAX AND NOT IA32_HRESET_ENABLE) ≠0.
#UD
If CPUID.07H.01H:EAX.HRESET[22] = 0.
Real-Address Mode Exceptions
Same exceptions as in protected mode.
Virtual-8086 Mode Exceptions
#GP(0)
HRESET instruction is not recognized in virtual-8086 mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
HRESET-History Reset
Vol. 2A
3-440
64-Bit Mode Exceptions
Same exceptions as in protected mode.
HRESET-History Reset
Vol. 2A
3-441
HSUBPD-Packed Double Precision Floating-Point Horizontal Subtract
Opcode/
Op/
64/32-bit
CPUID
Description
Instruction
En
Mode
Feature
Flag
66 0F 7D /r
RM
V/V
SSE3
Horizontal subtract packed double precision
floating-point values from xmm2/m128 to
HSUBPD xmm1, xmm2/m128
xmm1.
VEX.128.66.0F.WIG 7D /r
RVM
V/V
AVX
Horizontal subtract packed double precision
VHSUBPD xmm1,xmm2, xmm3/m128
floating-point values from xmm2 and
xmm3/mem.
VEX.256.66.0F.WIG 7D /r
RVM
V/V
AVX
Horizontal subtract packed double precision
VHSUBPD ymm1, ymm2, ymm3/m256
floating-point values from ymm2 and
ymm3/mem.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
RVM
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
The HSUBPD instruction subtracts horizontally the packed double precision floating-point numbers of both oper-
ands.
Subtracts the double precision floating-point value in the high quadword of the destination operand from the low
quadword of the destination operand and stores the result in the low quadword of the destination operand.
Subtracts the double precision floating-point value in the high quadword of the source operand from the low quad-
word of the source operand and stores the result in the high quadword of the destination operand.
In 64-bit mode, use of the REX.R prefix permits this instruction to access additional registers (XMM8-XMM15).
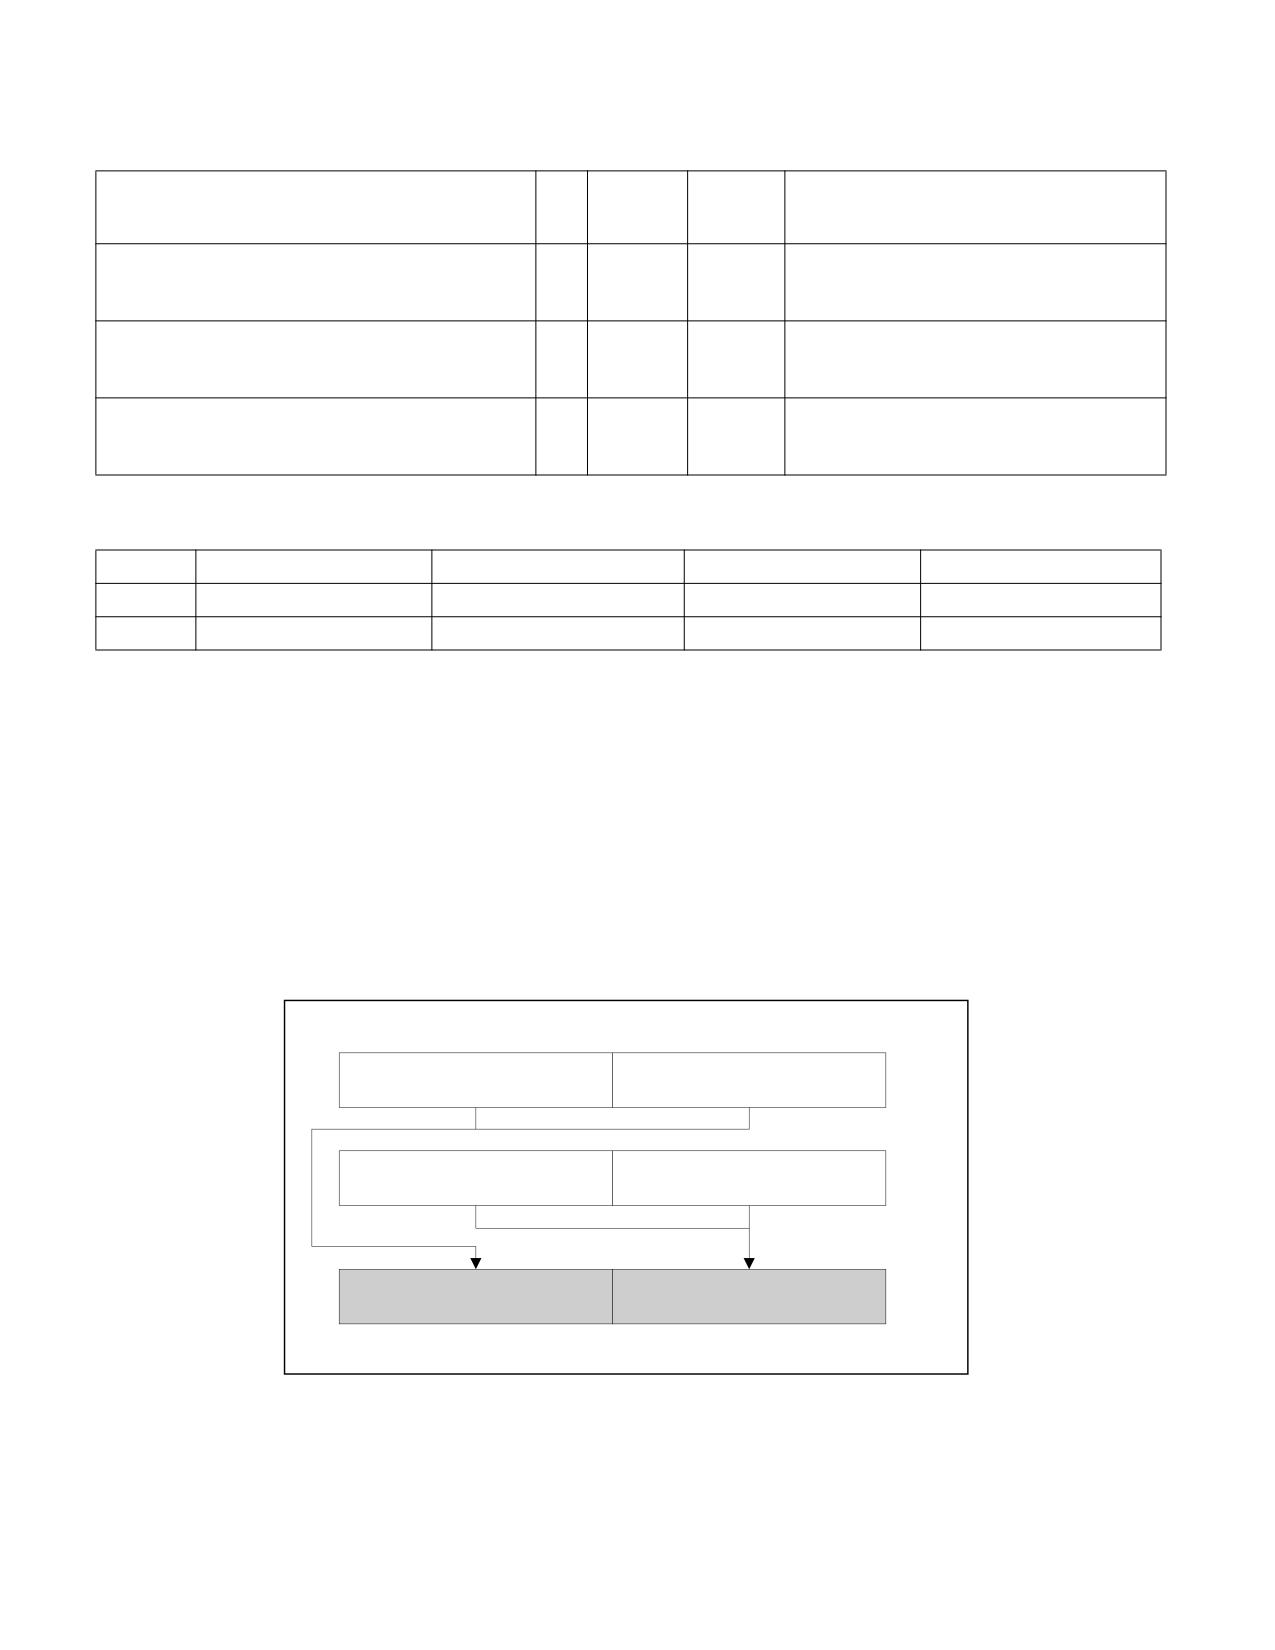
See Figure 3-16 for HSUBPD; see Figure 3-17 for VHSUBPD.
HSUBPD xmm1, xmm2/m128
xmm2
[127:64]
[63:0]
/m128
[127:64]
[63:0]
xmm1
xmm2/m128[63:0] -
Result:
xmm1[63:0] - xmm1[127:64]
xmm2/m128[127:64]
xmm1
[127:64]
[63:0]
OM15995
Figure 3-16. HSUBPD-Packed Double Precision Floating-Point Horizontal Subtract
HSUBPD-Packed Double Precision Floating-Point Horizontal Subtract
Vol. 2A
3-442
SRC1
X3
X2
X1
X0
SRC2
Y3
Y
2
Y1
Y0
DEST
Y2 - Y3
X2 - X3
Y0 - Y1
X0 - X1
Figure 3-17. VHSUBPD operation
128-bit Legacy SSE version: The second source can be an XMM register or an 128-bit memory location. The desti-
nation is not distinct from the first source XMM register and the upper bits (MAXVL-1:128) of the corresponding
YMM register destination are unmodified.
VEX.128 encoded version: the first source operand is an XMM register or 128-bit memory location. The destination
operand is an XMM register. The upper bits (MAXVL-1:128) of the corresponding YMM register destination are
zeroed.
VEX.256 encoded version: The first source operand is a YMM register. The second source operand can be a YMM
register or a 256-bit memory location. The destination operand is a YMM register.
Operation
HSUBPD (128-bit Legacy SSE Version)
DEST[63:0] := SRC1[63:0] - SRC1[127:64]
DEST[127:64] := SRC2[63:0] - SRC2[127:64]
DEST[MAXVL-1:128] (Unmodified)
VHSUBPD (VEX.128 Encoded Version)
DEST[63:0] := SRC1[63:0] - SRC1[127:64]
DEST[127:64] := SRC2[63:0] - SRC2[127:64]
DEST[MAXVL-1:128] := 0
VHSUBPD (VEX.256 Encoded Version)
DEST[63:0] := SRC1[63:0] - SRC1[127:64]
DEST[127:64] := SRC2[63:0] - SRC2[127:64]
DEST[191:128] := SRC1[191:128] - SRC1[255:192]
DEST[255:192] := SRC2[191:128] - SRC2[255:192]
Intel C/C++ Compiler Intrinsic Equivalent
HSUBPD __m128d _mm_hsub_pd(__m128d a, __m128d b)
VHSUBPD __m256d _mm256_hsub_pd (__m256d a, __m256d b);
Exceptions
When the source operand is a memory operand, the operand must be aligned on a 16-byte boundary or a general-
protection exception (#GP) will be generated.
Numeric Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
HSUBPD-Packed Double Precision Floating-Point Horizontal Subtract
Vol. 2A
3-443
Other Exceptions
See Table 2-19, “Type 2 Class Exception Conditions.”
HSUBPD-Packed Double Precision Floating-Point Horizontal Subtract
Vol. 2A
3-444
HSUBPS-Packed Single Precision Floating-Point Horizontal Subtract
Opcode/
Op/
64/32-bit
CPUID
Description
Instruction
En
Mode
Feature
Flag
F2 0F 7D /r
RM
V/V
SSE3
Horizontal subtract packed single precision
floating-point values from xmm2/m128 to
HSUBPS xmm1, xmm2/m128
xmm1.
VEX.128.F2.0F.WIG 7D /r
RVM
V/V
AVX
Horizontal subtract packed single precision
floating-point values from xmm2 and
VHSUBPS xmm1, xmm2, xmm3/m128
xmm3/mem.
VEX.256.F2.0F.WIG 7D /r
RVM
V/V
AVX
Horizontal subtract packed single precision
VHSUBPS ymm1, ymm2, ymm3/m256
floating-point values from ymm2 and
ymm3/mem.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
RM
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
RVM
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
N/A
Description
Subtracts the single precision floating-point value in the second dword of the destination operand from the first
dword of the destination operand and stores the result in the first dword of the destination operand.
Subtracts the single precision floating-point value in the fourth dword of the destination operand from the third
dword of the destination operand and stores the result in the second dword of the destination operand.
Subtracts the single precision floating-point value in the second dword of the source operand from the first dword
of the source operand and stores the result in the third dword of the destination operand.
Subtracts the single precision floating-point value in the fourth dword of the source operand from the third dword
of the source operand and stores the result in the fourth dword of the destination operand.
In 64-bit mode, use of the REX.R prefix permits this instruction to access additional registers (XMM8-XMM15).
See Figure 3-18 for HSUBPS; see Figure 3-19 for VHSUBPS.
HSUBPS-Packed Single Precision Floating-Point Horizontal Subtract
Vol. 2A
3-445
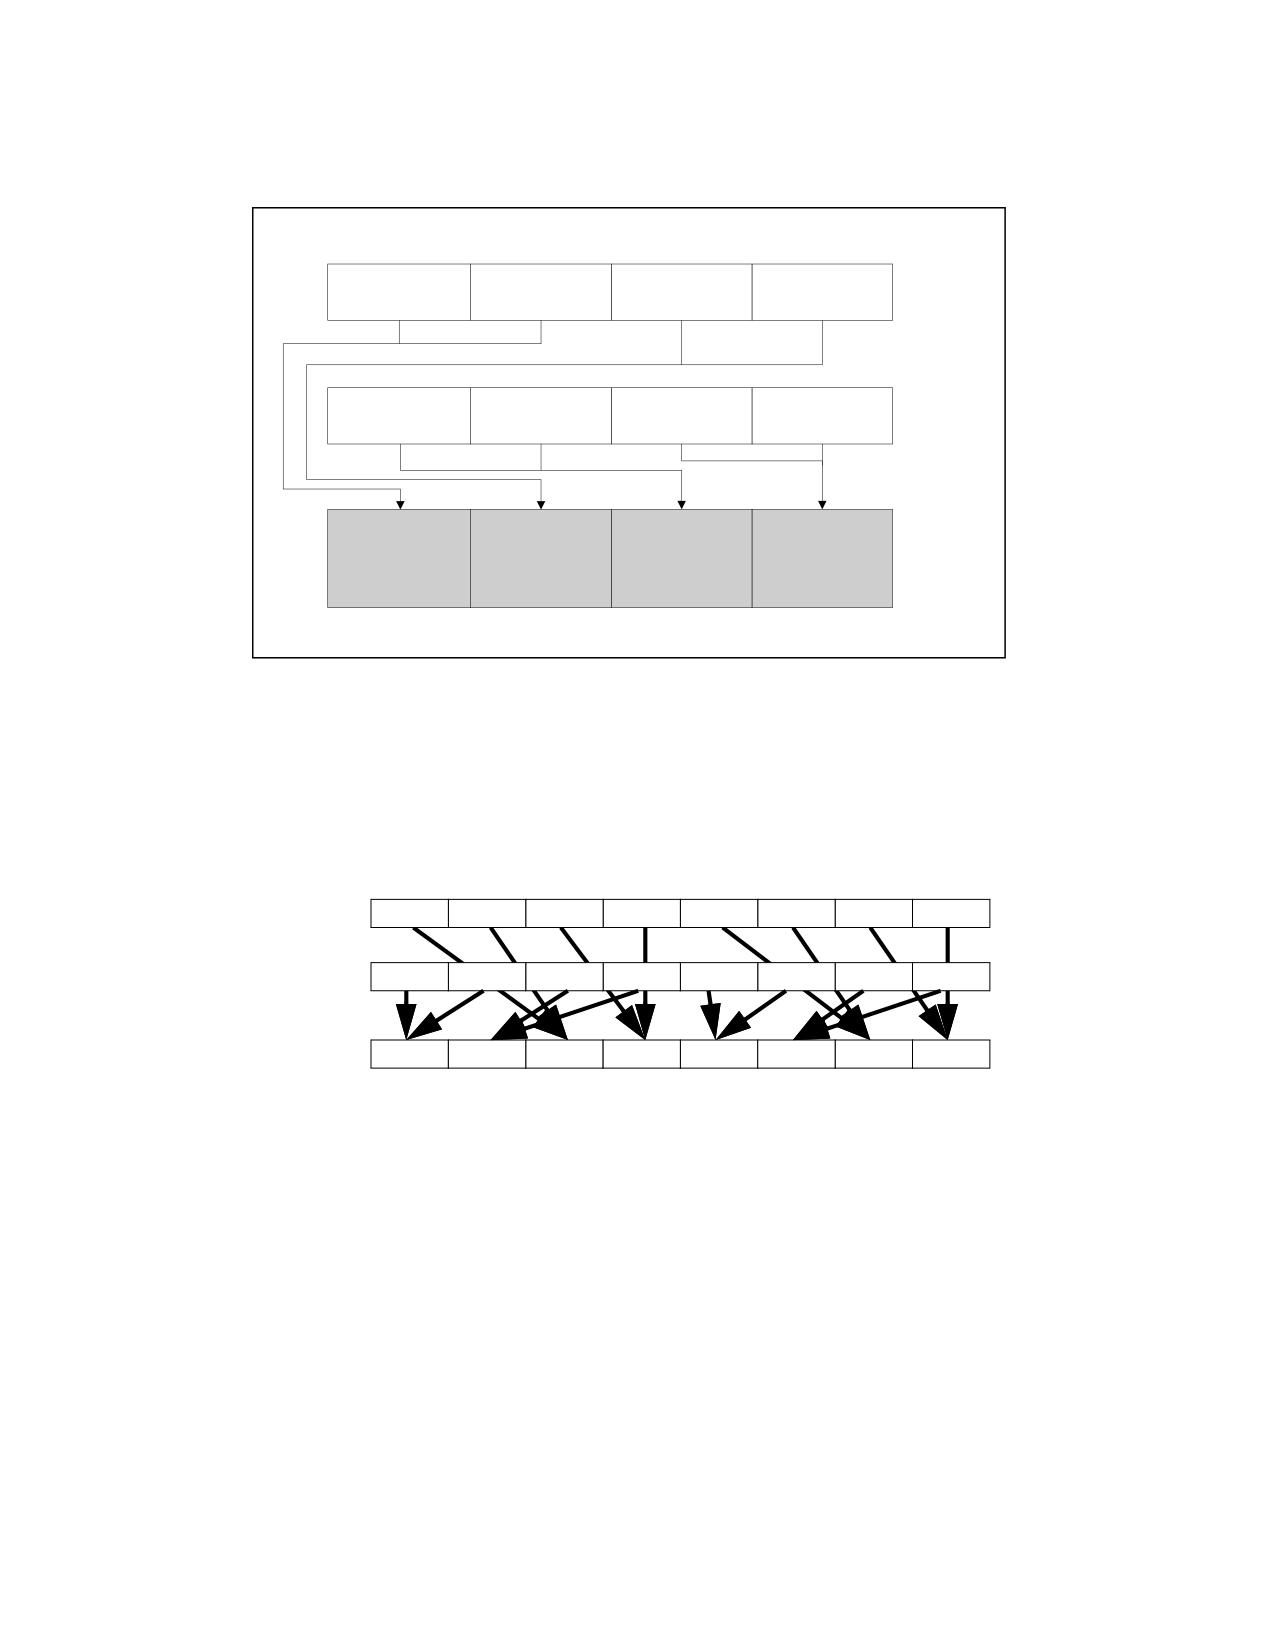
HSUBPS xmm1, xmm2/m128
xmm2/
[127:96]
[95:64]
[63:32]
[31:0]
m128
[127:96]
[95:64]
[63:32]
[31:0]
xmm1
xmm2/m128
xmm2/m128
xmm1[95:64] -
xmm1[31:0] -
RESULT:
[95:64] - xmm2/
[31:0] - xmm2/
xmm1[127:96]
xmm1[63:32]
xmm1
m128[127:96]
m128[63:32]
[127:96]
[95:64]
[63:32]
[31:0]
OM15996
Figure 3-18. HSUBPS-Packed Single Precision Floating-Point Horizontal Subtract
SRC1
X7
X6
X5
X4
X3
X2
X1
X0
SRC2
Y7
Y6
Y5
Y4
Y3
Y2
Y1
Y0
DEST
Y6-Y7
Y4-Y5
X6-X7
X4-X5
Y2-Y3
Y0-Y1
X2-X3
X0-X1
Figure 3-19. VHSUBPS Operation
128-bit Legacy SSE version: The second source can be an XMM register or an 128-bit memory location. The desti-
nation is not distinct from the first source XMM register and the upper bits (MAXVL-1:128) of the corresponding
YMM register destination are unmodified.
VEX.128 encoded version: the first source operand is an XMM register or 128-bit memory location. The destination
operand is an XMM register. The upper bits (MAXVL-1:128) of the corresponding YMM register destination are
zeroed.
VEX.256 encoded version: The first source operand is a YMM register. The second source operand can be a YMM
register or a 256-bit memory location. The destination operand is a YMM register.
HSUBPS-Packed Single Precision Floating-Point Horizontal Subtract
Vol. 2A
3-446
Operation
HSUBPS (128-bit Legacy SSE Version)
DEST[31:0] := SRC1[31:0] - SRC1[63:32]
DEST[63:32] := SRC1[95:64] - SRC1[127:96]
DEST[95:64] := SRC2[31:0] - SRC2[63:32]
DEST[127:96] := SRC2[95:64] - SRC2[127:96]
DEST[MAXVL-1:128] (Unmodified)
VHSUBPS (VEX.128 Encoded Version)
DEST[31:0] := SRC1[31:0] - SRC1[63:32]
DEST[63:32] := SRC1[95:64] - SRC1[127:96]
DEST[95:64] := SRC2[31:0] - SRC2[63:32]
DEST[127:96] := SRC2[95:64] - SRC2[127:96]
DEST[MAXVL-1:128] := 0
VHSUBPS (VEX.256 Encoded Version)
DEST[31:0] := SRC1[31:0] - SRC1[63:32]
DEST[63:32] := SRC1[95:64] - SRC1[127:96]
DEST[95:64] := SRC2[31:0] - SRC2[63:32]
DEST[127:96] := SRC2[95:64] - SRC2[127:96]
DEST[159:128] := SRC1[159:128] - SRC1[191:160]
DEST[191:160] := SRC1[223:192] - SRC1[255:224]
DEST[223:192] := SRC2[159:128] - SRC2[191:160]
DEST[255:224] := SRC2[223:192] - SRC2[255:224]
Intel C/C++ Compiler Intrinsic Equivalent
HSUBPS __m128 _mm_hsub_ps(__m128 a, __m128 b);
VHSUBPS __m256 _mm256_hsub_ps (__m256 a, __m256 b);
Exceptions
When the source operand is a memory operand, the operand must be aligned on a 16-byte boundary or a general-
protection exception (#GP) will be generated.
Numeric Exceptions
Overflow, Underflow, Invalid, Precision, Denormal.
Other Exceptions
See Table 2-19, “Type 2 Class Exception Conditions.”
HSUBPS-Packed Single Precision Floating-Point Horizontal Subtract
Vol. 2A
3-447
IDIV-Signed Divide
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
F6 /7
IDIV r/m81
M
Valid
Valid
Signed divide AX by r/m8, with result stored in:
AL := Quotient, AH := Remainder.
F7 /7
IDIV r/m16
M
Valid
Valid
Signed divide DX:AX by r/m16, with result
stored in AX := Quotient, DX := Remainder.
F7 /7
IDIV r/m32
M
Valid
Valid
Signed divide EDX:EAX by r/m32, with result
stored in EAX := Quotient, EDX := Remainder.
REX.W + F7 /7
IDIV r/m64
M
Valid
N.E.
Signed divide RDX:RAX by r/m64, with result
stored in RAX := Quotient, RDX := Remainder.
NOTES:
1. With a REX prefix in 64-bit mode, attempts to access AH, BH, CH, or DH will instead access SPL, DIL, BPL, or SIL, respectively.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
M
ModRM:r/m (r)
N/A
N/A
N/A
Description
Divides the (signed) value in the AX, DX:AX, or EDX:EAX (dividend) by the source operand (divisor) and stores the
result in the AX (AH:AL), DX:AX, or EDX:EAX registers. The source operand can be a general-purpose register or a
memory location. The action of this instruction depends on the operand size (dividend/divisor).
Non-integral results are truncated (chopped) towards 0. The remainder is always less than the divisor in magni-
tude. Overflow is indicated with the #DE (divide error) exception rather than with the CF flag.
In 64-bit mode, the instruction’s default operation size is 32 bits. Use of the REX.R prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. In 64-bit mode when REX.W is
applied, the instruction divides the signed value in RDX:RAX by the source operand. RAX contains a 64-bit
quotient; RDX contains a 64-bit remainder.
See the summary chart at the beginning of this section for encoding data and limits. See Table 3-53.
Table 3-53. IDIV Results
Operand Size
Dividend
Divisor
Quotient
Remainder
Quotient Range
Word/byte
AX
r/m8
AL
AH
-128 to +127
Doubleword/word
DX:AX
r/m16
AX
DX
-32,768 to +32,767
Quadword/doubleword
EDX:EAX
r/m32
EAX
EDX
-231 to 231 - 1
Doublequadword/ quadword
RDX:RAX
r/m64
RAX
RDX
-263 to 263 - 1
IDIV-Signed Divide
Vol. 2A
3-448
Operation
IF SRC = 0
THEN #DE; (* Divide error *)
FI;
IF OperandSize = 8 (* Word/byte operation *)
THEN
temp := AX / SRC; (* Signed division *)
IF (temp > 7FH) or (temp < 80H)
(* If a positive result is greater than 7FH or a negative result is less than 80H *)
THEN #DE; (* Divide error *)
ELSE
AL := temp;
AH := AX SignedModulus SRC;
FI;
ELSE IF OperandSize = 16 (* Doubleword/word operation *)
THEN
temp := DX:AX / SRC; (* Signed division *)
IF (temp > 7FFFH) or (temp < 8000H)
(* If a positive result is greater than 7FFFH
or a negative result is less than 8000H *)
THEN
#DE; (* Divide error *)
ELSE
AX := temp;
DX := DX:AX SignedModulus SRC;
FI;
FI;
ELSE IF OperandSize = 32 (* Quadword/doubleword operation *)
THEN
temp := EDX:EAX / SRC; (* Signed division *)
IF (temp > 7FFFFFFFH) or (temp < 80000000H)
(* If a positive result is greater than 7FFFFFFFH
or a negative result is less than 80000000H *)
THEN
#DE; (* Divide error *)
ELSE
EAX := temp;
EDX := EDX:EAX SignedModulus SRC;
FI;
FI;
ELSE IF OperandSize = 64 (* Doublequadword/quadword operation *)
THEN
temp := RDX:RAX / SRC; (* Signed division *)
IF (temp > 7FFFFFFFFFFFFFFFH) or (temp < 8000000000000000H)
(* If a positive result is greater than 7FFFFFFFFFFFFFFFH
or a negative result is less than 8000000000000000H *)
THEN
#DE; (* Divide error *)
ELSE
RAX := temp;
RDX := RDX:RAX SignedModulus SRC;
FI;
FI;
IDIV-Signed Divide
Vol. 2A
3-449
FI;
Flags Affected
The CF, OF, SF, ZF, AF, and PF flags are undefined.
Protected Mode Exceptions
#DE
If the source operand (divisor) is 0.
The signed result (quotient) is too large for the destination.
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
If the DS, ES, FS, or GS register is used to access memory and it contains a NULL segment
selector.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
#DE
If the source operand (divisor) is 0.
The signed result (quotient) is too large for the destination.
#GP
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS
If a memory operand effective address is outside the SS segment limit.
#UD
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
#DE
If the source operand (divisor) is 0.
The signed result (quotient) is too large for the destination.
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made.
#UD
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the memory address is in a non-canonical form.
#DE
If the source operand (divisor) is 0
If the quotient is too large for the designated register.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used.
IDIV-Signed Divide
Vol. 2A
3-450

IMUL-Signed Multiply
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
F6 /5
IMUL r/m81
M
Valid
Valid
AX:= AL ∗ r/m byte.
F7 /5
IMUL r/m16
M
Valid
Valid
DX:AX := AX ∗ r/m word.
F7 /5
IMUL r/m32
M
Valid
Valid
EDX:EAX := EAX ∗ r/m32.
REX.W + F7 /5
IMUL r/m64
M
Valid
N.E.
RDX:RAX := RAX ∗ r/m64.
0F AF /r
IMUL r16, r/m16
RM
Valid
Valid
Word register := word register ∗ r/m16.
0F AF /r
IMUL r32, r/m32
RM
Valid
Valid
Doubleword register := doubleword register ∗
r/m32.
REX.W + 0F AF /r
IMUL r64, r/m64
RM
Valid
N.E.
Quadword register := Quadword register ∗
r/m64.
6B /r ib
IMUL r16, r/m16, imm8
RMI
Valid
Valid
Word register := r/m16 ∗ sign-extended
immediate byte.
6B /r ib
IMUL r32, r/m32, imm8
RMI
Valid
Valid
Doubleword register := r/m32 ∗ sign-
extended immediate byte.
REX.W + 6B /r ib
IMUL r64, r/m64, imm8
RMI
Valid
N.E.
Quadword register := r/m64 ∗ sign-extended
immediate byte.
69 /r iw
IMUL r16, r/m16, imm16
RMI
Valid
Valid
Word register := r/m16 ∗ immediate word.
69 /r id
IMUL r32, r/m32, imm32
RMI
Valid
Valid
Doubleword register := r/m32 ∗ immediate
doubleword.
REX.W + 69 /r id
IMUL r64, r/m64, imm32
RMI
Valid
N.E.
Quadword register := r/m64 ∗ immediate
doubleword.
NOTES:
1. With a REX prefix in 64-bit mode, attempts to access AH, BH, CH, or DH will instead access SPL, DIL, BPL, or SIL, respectively.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
M
ModRM:r/m (r, w)
N/A
N/A
N/A
RM
ModRM:reg (r, w)
ModRM:r/m (r)
N/A
N/A
RMI
ModRM:reg (r, w)
ModRM:r/m (r)
imm8/16/32
N/A
Description
Performs a signed multiplication of two operands. This instruction has three forms, depending on the number of
operands.
• One-operand form - This form is identical to that used by the MUL instruction. Here, the source operand (in
a general-purpose register or memory location) is multiplied by the value in the AL, AX, EAX, or RAX register
(depending on the operand size) and the product (twice the size of the input operand) is stored in the AX,
DX:AX, EDX:EAX, or RDX:RAX registers, respectively.
• Two-operand form - With this form the destination operand (the first operand) is multiplied by the source
operand (second operand). The destination operand is a general-purpose register and the source operand is an
immediate value, a general-purpose register, or a memory location. The intermediate product (twice the size of
the input operand) is truncated and stored in the destination operand location.
• Three-operand form - This form requires a destination operand (the first operand) and two source operands
(the second and the third operands). Here, the first source operand (which can be a general-purpose register
or a memory location) is multiplied by the second source operand (an immediate value). The intermediate
product (twice the size of the first source operand) is truncated and stored in the destination operand (a
general-purpose register).
IMUL-Signed Multiply
Vol. 2A
3-451
When an immediate value is used as an operand, it is sign-extended to the length of the destination operand
format.
The CF and OF flags are set when the signed integer value of the intermediate product differs from the sign
extended operand-size-truncated product, otherwise the CF and OF flags are cleared.
The three forms of the IMUL instruction are similar in that the length of the product is calculated to twice the length
of the operands. With the one-operand form, the product is stored exactly in the destination. With the two- and
three- operand forms, however, the result is truncated to the length of the destination before it is stored in the
destination register. Because of this truncation, the CF or OF flag should be tested to ensure that no significant bits
are lost.
The two- and three-operand forms may also be used with unsigned operands because the lower half of the product
is the same regardless if the operands are signed or unsigned. The CF and OF flags, however, cannot be used to
determine if the upper half of the result is non-zero.
In 64-bit mode, the instruction’s default operation size is 32 bits. Use of the REX.R prefix permits access to addi-
tional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits. Use of REX.W modifies the three
forms of the instruction as follows.
• One-operand form -The source operand (in a 64-bit general-purpose register or memory location) is
multiplied by the value in the RAX register and the product is stored in the RDX:RAX registers.
• Two-operand form - The source operand is promoted to 64 bits if it is a register or a memory location. The
destination operand is promoted to 64 bits.
• Three-operand form - The first source operand (either a register or a memory location) and destination
operand are promoted to 64 bits. If the source operand is an immediate, it is sign extended to 64 bits.
Operation
IF (NumberOfOperands = 1)
THEN IF (OperandSize = 8)
THEN
TMP_XP := AL ∗ SRC (* Signed multiplication; TMP_XP is a signed integer at twice the width of the SRC *);
AX := TMP_XP[15:0];
IF SignExtend(TMP_XP[7:0]) = TMP_XP
THEN CF := 0; OF := 0;
ELSE CF := 1; OF := 1; FI;
ELSE IF OperandSize = 16
THEN
TMP_XP := AX ∗ SRC (* Signed multiplication; TMP_XP is a signed integer at twice the width of the SRC *)
DX:AX := TMP_XP[31:0];
IF SignExtend(TMP_XP[15:0]) = TMP_XP
THEN CF := 0; OF := 0;
ELSE CF := 1; OF := 1; FI;
ELSE IF OperandSize = 32
THEN
TMP_XP := EAX ∗ SRC (* Signed multiplication; TMP_XP is a signed integer at twice the width of the SRC*)
EDX:EAX := TMP_XP[63:0];
IF SignExtend(TMP_XP[31:0]) = TMP_XP
THEN CF := 0; OF := 0;
ELSE CF := 1; OF := 1; FI;
ELSE (* OperandSize = 64 *)
TMP_XP := RAX ∗ SRC (* Signed multiplication; TMP_XP is a signed integer at twice the width of the SRC *)
RDX:RAX := TMP_XP[127:0];
IF SignExtend(TMP_XP[63:0]) = TMP_XP
THEN CF := 0; OF := 0;
ELSE CF := 1; OF := 1; FI;
FI;
FI;
IMUL-Signed Multiply
Vol. 2A
3-452
ELSE IF (NumberOfOperands = 2)
THEN
TMP_XP := DEST ∗ SRC (* Signed multiplication; TMP_XP is a signed integer at twice the width of the SRC *)
DEST := TruncateToOperandSize(TMP_XP);
IF SignExtend(DEST) ≠ TMP_XP
THEN CF := 1; OF := 1;
ELSE CF := 0; OF := 0; FI;
ELSE (* NumberOfOperands = 3 *)
TMP_XP := SRC1 ∗ SRC2 (* Signed multiplication; TMP_XP is a signed integer at twice the width of the SRC1 *)
DEST := TruncateToOperandSize(TMP_XP);
IF SignExtend(DEST) ≠ TMP_XP
THEN CF := 1; OF := 1;
ELSE CF := 0; OF := 0; FI;
FI;
FI;
Flags Affected
For the one operand form of the instruction, the CF and OF flags are set when significant bits are carried into the
upper half of the result and cleared when the result fits exactly in the lower half of the result. For the two- and
three-operand forms of the instruction, the CF and OF flags are set when the result must be truncated to fit in the
destination operand size and cleared when the result fits exactly in the destination operand size. The SF, ZF, AF, and
PF flags are undefined.
Protected Mode Exceptions
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
If the DS, ES, FS, or GS register is used to access memory and it contains a NULL NULL
segment selector.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
#GP
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS
If a memory operand effective address is outside the SS segment limit.
#UD
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made.
#UD
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
IMUL-Signed Multiply
Vol. 2A
3-453
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the memory address is in a non-canonical form.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used.
IMUL-Signed Multiply
Vol. 2A
3-454
IN-Input From Port
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
E4 ib
IN AL, imm8
I
Valid
Valid
Input byte from imm8 I/O port address into
AL.
E5 ib
IN AX, imm8
I
Valid
Valid
Input word from imm8 I/O port address into
AX.
E5 ib
IN EAX, imm8
I
Valid
Valid
Input dword from imm8 I/O port address into
EAX.
EC
IN AL,DX
ZO
Valid
Valid
Input byte from I/O port in DX into AL.
ED
IN AX,DX
ZO
Valid
Valid
Input word from I/O port in DX into AX.
ED
IN EAX,DX
ZO
Valid
Valid
Input doubleword from I/O port in DX into
EAX.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
I
imm8
N/A
N/A
N/A
ZO
N/A
N/A
N/A
N/A
Description
Copies the value from the I/O port specified with the second operand (source operand) to the destination operand
(first operand). The source operand can be a byte-immediate or the DX register; the destination operand can be
register AL, AX, or EAX, depending on the size of the port being accessed (8, 16, or 32 bits, respectively). Using the
DX register as a source operand allows I/O port addresses from 0 to 65,535 to be accessed; using a byte imme-
diate allows I/O port addresses 0 to 255 to be accessed.
When accessing an 8-bit I/O port, the opcode determines the port size; when accessing a 16- and 32-bit I/O port,
the operand-size attribute determines the port size. At the machine code level, I/O instructions are shorter when
accessing 8-bit I/O ports. Here, the upper eight bits of the port address will be 0.
This instruction is only useful for accessing I/O ports located in the processor’s I/O address space. See Chapter 20,
“Input/Output,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 1, for more infor-
mation on accessing I/O ports in the I/O address space.
This instruction’s operation is the same in non-64-bit modes and 64-bit mode.
Operation
IF ((PE = 1) and ((CPL > IOPL) or (VM = 1)))
THEN (* Protected mode with CPL > IOPL or virtual-8086 mode *)
IF (Any I/O Permission Bit for I/O port being accessed = 1)
THEN (* I/O operation is not allowed *)
#GP(0);
ELSE ( * I/O operation is allowed *)
DEST := SRC; (* Read from selected I/O port *)
FI;
ELSE (Real Mode or Protected Mode with CPL ≤ IOPL *)
DEST := SRC; (* Read from selected I/O port *)
FI;
Flags Affected
None.
IN-Input From Port
Vol. 2A
3-455
Protected Mode Exceptions
#GP(0)
If the CPL is greater than (has less privilege) the I/O privilege level (IOPL) and any of the
corresponding I/O permission bits in TSS for the I/O port being accessed is 1.
#PF(fault-code)
If a page fault occurs.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
#UD
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
#GP(0)
If any of the I/O permission bits in the TSS for the I/O port being accessed is 1.
#PF(fault-code)
If a page fault occurs.
#UD
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#GP(0)
If the CPL is greater than (has less privilege) the I/O privilege level (IOPL) and any of the
corresponding I/O permission bits in TSS for the I/O port being accessed is 1.
#PF(fault-code)
If a page fault occurs.
#UD
If the LOCK prefix is used.
IN-Input From Port
Vol. 2A
3-456
INC-Increment by 1
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
FE /0
INC r/m81
M
Valid
Valid
Increment r/m byte by 1.
FF /0
INC r/m16
M
Valid
Valid
Increment r/m word by 1.
FF /0
INC r/m32
M
Valid
Valid
Increment r/m doubleword by 1.
REX.W + FF /0
INC r/m64
M
Valid
N.E.
Increment r/m quadword by 1.
40+ rw2
INC r16
O
N.E.
Valid
Increment word register by 1.
40+ rd
INC r32
O
N.E.
Valid
Increment doubleword register by 1.
NOTES:
1. With a REX prefix in 64-bit mode, attempts to access AH, BH, CH, or DH will instead access SPL, DIL, BPL, or SIL, respectively.
2. 40H through 47H are REX prefixes in 64-bit mode.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
M
ModRM:r/m (r, w)
N/A
N/A
N/A
O
opcode + rd (r, w)
N/A
N/A
N/A
Description
Adds 1 to the destination operand, while preserving the state of the CF flag. The destination operand can be a
register or a memory location. This instruction allows a loop counter to be updated without disturbing the CF flag.
(Use a ADD instruction with an immediate operand of 1 to perform an increment operation that does updates the
CF flag.)
This instruction can be used with a LOCK prefix to allow the instruction to be executed atomically.
In 64-bit mode, INC r16 and INC r32 are not encodable (because opcodes 40H through 47H are REX prefixes).
Otherwise, the instruction’s 64-bit mode default operation size is 32 bits. Use of the REX.R prefix permits access to
additional registers (R8-R15). Use of the REX.W prefix promotes operation to 64 bits.
Operation
DEST := DEST + 1;
Flags Affected
The CF flag is not affected. The OF, SF, ZF, AF, and PF flags are set according to the result.
Protected Mode Exceptions
#GP(0)
If the destination operand is located in a non-writable segment.
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
If the DS, ES, FS, or GS register is used to access memory and it contains a NULLsegment
selector.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used but the destination is not a memory operand.
Real-Address Mode Exceptions
#GP
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
INC-Increment by 1
Vol. 2A
3-457
#SS
If a memory operand effective address is outside the SS segment limit.
#UD
If the LOCK prefix is used but the destination is not a memory operand.
Virtual-8086 Mode Exceptions
#GP(0)
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS(0)
If a memory operand effective address is outside the SS segment limit.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made.
#UD
If the LOCK prefix is used but the destination is not a memory operand.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the memory address is in a non-canonical form.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used but the destination is not a memory operand.
INC-Increment by 1
Vol. 2A
3-458
INCSSPD/INCSSPQ-Increment Shadow Stack Pointer
Opcode/
Op /
64/32 bit
CPUID
Description
Instruction
En
Mode
Feature
Support
Flag
F3 0F AE /5
R
V/V
CET_SS
Increment SSP by 4 * r32[7:0].
INCSSPD r32
F3 REX.W 0F AE /5
R
V/N.E.
CET_SS
Increment SSP by 8 * r64[7:0].
INCSSPQ r64
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
R
N/A
ModRM:r/m (r)
N/A
N/A
N/A
Description
This instruction can be used to increment the current shadow stack pointer by the operand size of the instruction
times the unsigned 8-bit value specified by bits 7:0 in the source operand. The instruction performs a pop and
discard of the first and last element on the shadow stack in the range specified by the unsigned 8-bit value in bits
7:0 of the source operand.
Operation
IF CPL = 3
IF (CR4.CET & IA32_U_CET.SH_STK_EN) = 0
THEN #UD; FI;
ELSE
IF (CR4.CET & IA32_S_CET.SH_STK_EN) = 0
THEN #UD; FI;
FI;
IF (operand size is 64-bit)
THEN
Range := R64[7:0];
shadow_stack_load 8 bytes from SSP;
IF Range > 0
THEN shadow_stack_load 8 bytes from SSP + 8 * (Range - 1);
FI;
SSP := SSP + Range * 8;
ELSE
Range := R32[7:0];
shadow_stack_load 4 bytes from SSP;
IF Range > 0
THEN shadow_stack_load 4 bytes from SSP + 4 * (Range - 1);
FI;
SSP := SSP + Range * 4;
FI;
Flags Affected
None.
Intel C/C++ Compiler Intrinsic Equivalent
INCSSPD void _incsspd(int);
INCSSPQ void _incsspq(int);
INCSSPD/INCSSPQ-Increment Shadow Stack Pointer
Vol. 2A
3-459
Protected Mode Exceptions
#UD
If the LOCK prefix is used.
If CR4.CET = 0.
IF CPL = 3 and IA32_U_CET.SH_STK_EN = 0.
IF CPL < 3 and IA32_S_CET.SH_STK_EN = 0.
#PF(fault-code)
If a page fault occurs.
Real-Address Mode Exceptions
#UD
The INCSSP instruction is not recognized in real-address mode.
Virtual-8086 Mode Exceptions
#UD
The INCSSP instruction is not recognized in virtual-8086 mode.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
Same exceptions as in protected mode.
INCSSPD/INCSSPQ-Increment Shadow Stack Pointer
Vol. 2A
3-460
INS/INSB/INSW/INSD-Input from Port to String
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
6C
INS m8, DX
ZO
Valid
Valid
Input byte from I/O port specified in DX into
memory location specified in ES:(E)DI or RDI.1
6D
INS m16, DX
ZO
Valid
Valid
Input word from I/O port specified in DX into
memory location specified in ES:(E)DI or RDI.1
6D
INS m32, DX
ZO
Valid
Valid
Input doubleword from I/O port specified in DX
into memory location specified in ES:(E)DI or
RDI.1
6C
INSB
ZO
Valid
Valid
Input byte from I/O port specified in DX into
memory location specified with ES:(E)DI or
RDI.1
6D
INSW
ZO
Valid
Valid
Input word from I/O port specified in DX into
memory location specified in ES:(E)DI or RDI.1
6D
INSD
ZO
Valid
Valid
Input doubleword from I/O port specified in DX
into memory location specified in ES:(E)DI or
RDI.1
NOTES:
1. In 64-bit mode, only 64-bit (RDI) and 32-bit (EDI) address sizes are supported. In non-64-bit mode, only 32-bit (EDI) and 16-bit (DI)
address sizes are supported.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
ZO
N/A
N/A
N/A
N/A
Description
Copies the data from the I/O port specified with the source operand (second operand) to the destination operand
(first operand). The source operand is an I/O port address (from 0 to 65,535) that is read from the DX register. The
destination operand is a memory location, the address of which is read from either the ES:DI, ES:EDI or the RDI
registers (depending on the address-size attribute of the instruction, 16, 32 or 64, respectively). (The ES segment
cannot be overridden with a segment override prefix.) The size of the I/O port being accessed (that is, the size of
the source and destination operands) is determined by the opcode for an 8-bit I/O port or by the operand-size attri-
bute of the instruction for a 16- or 32-bit I/O port.
At the assembly-code level, two forms of this instruction are allowed: the “explicit-operands” form and the “no-
operands” form. The explicit-operands form (specified with the INS mnemonic) allows the source and destination
operands to be specified explicitly. Here, the source operand must be “DX,” and the destination operand should be
a symbol that indicates the size of the I/O port and the destination address. This explicit-operands form is provided
to allow documentation; however, note that the documentation provided by this form can be misleading. That is,
the destination operand symbol must specify the correct type (size) of the operand (byte, word, or doubleword),
but it does not have to specify the correct location. The location is always specified by the ES:(E)DI registers,
which must be loaded correctly before the INS instruction is executed.
The no-operands form provides “short forms” of the byte, word, and doubleword versions of the INS instructions.
Here also DX is assumed by the processor to be the source operand and ES:(E)DI is assumed to be the destination
operand. The size of the I/O port is specified with the choice of mnemonic: INSB (byte), INSW (word), or INSD
(doubleword).
After the byte, word, or doubleword is transfer from the I/O port to the memory location, the DI/EDI/RDI register
is incremented or decremented automatically according to the setting of the DF flag in the EFLAGS register. (If the
DF flag is 0, the (E)DI register is incremented; if the DF flag is 1, the (E)DI register is decremented.) The (E)DI
register is incremented or decremented by 1 for byte operations, by 2 for word operations, or by 4 for doubleword
operations.
INS/INSB/INSW/INSD-Input from Port to String
Vol. 2A
3-464
The INS, INSB, INSW, and INSD instructions can be preceded by the REP prefix for block input of ECX bytes, words,
or doublewords. See “REP-Repeat String Operation (Prefix)” in Chapter 4 of the Intel® 64 and IA-32 Architectures
Software Developer’s Manual, Volume 2B, for a description of the REP prefix.
These instructions are only useful for accessing I/O ports located in the processor’s I/O address space. See Chapter
20, “Input/Output,” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 1, for more
information on accessing I/O ports in the I/O address space.
In 64-bit mode, default address size is 64 bits, 32 bit address size is supported using the prefix 67H. The address
of the memory destination is specified by RDI or EDI. 16-bit address size is not supported in 64-bit mode. The
operand size is not promoted.
These instructions may read from the I/O port without writing to the memory location if an exception or VM exit
occurs due to the write (e.g. #PF). If this would be problematic, for example because the I/O port read has side-
effects, software should ensure the write to the memory location does not cause an exception or VM exit.
Operation
IF ((PE = 1) and ((CPL > IOPL) or (VM = 1)))
THEN (* Protected mode with CPL > IOPL or virtual-8086 mode *)
IF (Any I/O Permission Bit for I/O port being accessed = 1)
THEN (* I/O operation is not allowed *)
#GP(0);
ELSE (* I/O operation is allowed *)
DEST := SRC; (* Read from I/O port *)
FI;
ELSE (Real Mode or Protected Mode with CPL IOPL *)
DEST := SRC; (* Read from I/O port *)
FI;
Non-64-bit Mode:
IF (Byte transfer)
THEN IF DF = 0
THEN (E)DI := (E)DI + 1;
ELSE (E)DI := (E)DI - 1; FI;
ELSE IF (Word transfer)
THEN IF DF = 0
THEN (E)DI := (E)DI + 2;
ELSE (E)DI := (E)DI - 2; FI;
ELSE (* Doubleword transfer *)
THEN IF DF = 0
THEN (E)DI := (E)DI + 4;
ELSE (E)DI := (E)DI - 4; FI;
FI;
FI;
FI64-bit Mode:
IF (Byte transfer)
THEN IF DF = 0
THEN (E|R)DI := (E|R)DI + 1;
ELSE (E|R)DI := (E|R)DI - 1; FI;
ELSE IF (Word transfer)
THEN IF DF = 0
THEN (E)DI := (E)DI + 2;
ELSE (E)DI := (E)DI - 2; FI;
ELSE (* Doubleword transfer *)
THEN IF DF = 0
THEN (E|R)DI := (E|R)DI + 4;
INS/INSB/INSW/INSD-Input from Port to String
Vol. 2A
3-465
ELSE (E|R)DI := (E|R)DI - 4; FI;
FI;
FI;
Flags Affected
None.
Protected Mode Exceptions
#GP(0)
If the CPL is greater than (has less privilege) the I/O privilege level (IOPL) and any of the
corresponding I/O permission bits in TSS for the I/O port being accessed is 1.
If the destination is located in a non-writable segment.
If an illegal memory operand effective address in the ES segments is given.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used.
Real-Address Mode Exceptions
#GP
If a memory operand effective address is outside the CS, DS, ES, FS, or GS segment limit.
#SS
If a memory operand effective address is outside the SS segment limit.
#UD
If the LOCK prefix is used.
Virtual-8086 Mode Exceptions
#GP(0)
If any of the I/O permission bits in the TSS for the I/O port being accessed is 1.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made.
#UD
If the LOCK prefix is used.
Compatibility Mode Exceptions
Same exceptions as in protected mode.
64-Bit Mode Exceptions
#SS(0)
If a memory address referencing the SS segment is in a non-canonical form.
#GP(0)
If the CPL is greater than (has less privilege) the I/O privilege level (IOPL) and any of the
corresponding I/O permission bits in TSS for the I/O port being accessed is 1.
If the memory address is in a non-canonical form.
#PF(fault-code)
If a page fault occurs.
#AC(0)
If alignment checking is enabled and an unaligned memory reference is made while the
current privilege level is 3.
#UD
If the LOCK prefix is used.
INS/INSB/INSW/INSD-Input from Port to String
Vol. 2A
3-466
INSERTPS-Insert Scalar Single Precision Floating-Point Value
Opcode/
Op / En
64/32 bit
CPUID
Description
Instruction
Mode
Feature Flag
Support
66 0F 3A 21 /r ib
A
V/V
SSE4_1
Insert a single precision floating-point value selected
INSERTPS xmm1, xmm2/m32, imm8
by imm8 from xmm2/m32 into xmm1 at the specified
destination element specified by imm8 and zero out
destination elements in xmm1 as indicated in imm8.
VEX.128.66.0F3A.WIG 21 /r ib
B
V/V
AVX
Insert a single precision floating-point value selected
VINSERTPS xmm1, xmm2, xmm3/m32,
by imm8 from xmm3/m32 and merge with values in
imm8
xmm2 at the specified destination element specified
by imm8 and write out the result and zero out
destination elements in xmm1 as indicated in imm8.
EVEX.128.66.0F3A.W0 21 /r ib
C
V/V
AVX512F
Insert a single precision floating-point value selected
VINSERTPS xmm1, xmm2, xmm3/m32,
OR AVX10.1
by imm8 from xmm3/m32 and merge with values in
imm8
xmm2 at the specified destination element specified
by imm8 and write out the result and zero out
destination elements in xmm1 as indicated in imm8.
Instruction Operand Encoding
Op/En
Tuple Type
Operand 1
Operand 2
Operand 3
Operand 4
A
N/A
ModRM:reg (r, w)
ModRM:r/m (r)
imm8
N/A
B
N/A
ModRM:reg (w)
VEX.vvvv (r)
ModRM:r/m (r)
imm8
C
Tuple1 Scalar
ModRM:reg (w)
EVEX.vvvv (r)
ModRM:r/m (r)
imm8
Description
(register source form)
Copy a single precision scalar floating-point element into a 128-bit vector register. The immediate operand has
three fields, where the ZMask bits specify which elements of the destination will be set to zero, the Count_D bits
specify which element of the destination will be overwritten with the scalar value, and for vector register sources
the Count_S bits specify which element of the source will be copied. When the scalar source is a memory operand
the Count_S bits are ignored.
(memory source form)
Load a floating-point element from a 32-bit memory location and destination operand it into the first source at the
location indicated by the Count_D bits of the immediate operand. Store in the destination and zero out destination
elements based on the ZMask bits of the immediate operand.
128-bit Legacy SSE version: The first source register is an XMM register. The second source operand is either an
XMM register or a 32-bit memory location. The destination is not distinct from the first source XMM register and the
upper bits (MAXVL-1:128) of the corresponding register destination are unmodified.
VEX.128 and EVEX encoded version: The destination and first source register is an XMM register. The second
source operand is either an XMM register or a 32-bit memory location. The upper bits (MAXVL-1:128) of the corre-
sponding register destination are zeroed.
If VINSERTPS is encoded with VEX.L= 1, an attempt to execute the instruction encoded with VEX.L= 1 will cause
an #UD exception.
INSERTPS-Insert Scalar Single Precision Floating-Point Value
Vol. 2A
3-461
Operation
VINSERTPS (VEX.128 and EVEX Encoded Version)
IF (SRC = REG) THEN COUNT_S := imm8[7:6]
ELSE COUNT_S := 0
COUNT_D := imm8[5:4]
ZMASK := imm8[3:0]
CASE (COUNT_S) OF
0: TMP := SRC2[31:0]
1: TMP := SRC2[63:32]
2: TMP := SRC2[95:64]
3: TMP := SRC2[127:96]
ESAC;
CASE (COUNT_D) OF
0: TMP2[31:0] := TMP
TMP2[127:32] := SRC1[127:32]
1: TMP2[63:32] := TMP
TMP2[31:0] := SRC1[31:0]
TMP2[127:64] := SRC1[127:64]
2: TMP2[95:64] := TMP
TMP2[63:0] := SRC1[63:0]
TMP2[127:96] := SRC1[127:96]
3: TMP2[127:96] := TMP
TMP2[95:0] := SRC1[95:0]
ESAC;
IF (ZMASK[0] = 1) THEN DEST[31:0] := 00000000H
ELSE DEST[31:0] := TMP2[31:0]
IF (ZMASK[1] = 1) THEN DEST[63:32] := 00000000H
ELSE DEST[63:32] := TMP2[63:32]
IF (ZMASK[2] = 1) THEN DEST[95:64] := 00000000H
ELSE DEST[95:64] := TMP2[95:64]
IF (ZMASK[3] = 1) THEN DEST[127:96] := 00000000H
ELSE DEST[127:96] := TMP2[127:96]
DEST[MAXVL-1:128] := 0
INSERTPS (128-bit Legacy SSE Version)
IF (SRC = REG) THEN COUNT_S :=imm8[7:6]
ELSE COUNT_S :=0
COUNT_D := imm8[5:4]
ZMASK := imm8[3:0]
CASE (COUNT_S) OF
0: TMP := SRC[31:0]
1: TMP := SRC[63:32]
2: TMP := SRC[95:64]
3: TMP := SRC[127:96]
ESAC;
CASE (COUNT_D) OF
0: TMP2[31:0] := TMP
TMP2[127:32] := DEST[127:32]
1: TMP2[63:32] := TMP
TMP2[31:0] := DEST[31:0]
TMP2[127:64] := DEST[127:64]
2: TMP2[95:64] := TMP
INSERTPS-Insert Scalar Single Precision Floating-Point Value
Vol. 2A
3-462
TMP2[63:0] := DEST[63:0]
TMP2[127:96] := DEST[127:96]
3: TMP2[127:96] := TMP
TMP2[95:0] := DEST[95:0]
ESAC;
IF (ZMASK[0] = 1) THEN DEST[31:0] := 00000000H
ELSE DEST[31:0] := TMP2[31:0]
IF (ZMASK[1] = 1) THEN DEST[63:32] := 00000000H
ELSE DEST[63:32] := TMP2[63:32]
IF (ZMASK[2] = 1) THEN DEST[95:64] := 00000000H
ELSE DEST[95:64] := TMP2[95:64]
IF (ZMASK[3] = 1) THEN DEST[127:96] := 00000000H
ELSE DEST[127:96] := TMP2[127:96]
DEST[MAXVL-1:128] (Unmodified)
Intel C/C++ Compiler Intrinsic Equivalent
VINSERTPS __m128 _mm_insert_ps(__m128 dst, __m128 src, const int nidx);
INSETRTPS __m128 _mm_insert_ps(__m128 dst, __m128 src, const int nidx);
SIMD Floating-Point Exceptions
None.
Other Exceptions
Non-EVEX-encoded instruction, see Table 2-22, “Type 5 Class Exception Conditions,” additionally:
#UD
If VEX.L = 0.
EVEX-encoded instruction, see Table 2-59, “Type E9NF Class Exception Conditions.”
INSERTPS-Insert Scalar Single Precision Floating-Point Value
Vol. 2A
3-463
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Opcode
Instruction
Op/
64-Bit
Compat/
Description
En
Mode
Leg Mode
CC
INT3
ZO
Valid
Valid
Generate breakpoint trap.
CD ib
INT imm8
I
Valid
Valid
Generate software interrupt with vector
specified by immediate byte.
CE
INTO
ZO
Invalid
Valid
Generate overflow trap if overflow flag is 1.
F1
INT1
ZO
Valid
Valid
Generate debug trap.
Instruction Operand Encoding
Op/En
Operand 1
Operand 2
Operand 3
Operand 4
ZO
N/A
N/A
N/A
N/A
I
imm8
N/A
N/A
N/A
Description
The INT n instruction generates a call to the interrupt or exception handler specified with the destination operand
(see the section titled “Interrupts and Exceptions” in Chapter 6 of the Intel® 64 and IA-32 Architectures Software
Developer’s Manual, Volume 1). The destination operand specifies a vector from 0 to 255, encoded as an 8-bit
unsigned intermediate value. Each vector provides an index to a gate descriptor in the IDT. The first 32 vectors are
reserved by Intel for system use. Some of these vectors are used for internally generated exceptions.
When IDT event delivery is used, the vector provides an index to a gate descriptor in the IDT. The first 32 vectors
are reserved by Intel for system use. Some of these vectors are used for internally generated exceptions. When
FRED event delivery is used, the vector is saved on the stack of the event handler.
The INT n instruction is the general mnemonic for executing a software-generated call to an interrupt handler. The
INTO instruction is a special mnemonic for calling overflow exception (#OF), exception 4. The overflow interrupt
checks the OF flag in the EFLAGS register and calls the overflow interrupt handler if the OF flag is set to 1. (The
INTO instruction cannot be used in 64-bit mode.)
The INT3 instruction uses a one-byte opcode (CC) and is intended for calling the debug exception handler with a
breakpoint exception (#BP). (This one-byte form is useful because it can replace the first byte of any instruction at
which a breakpoint is desired, including other one-byte instructions, without overwriting other instructions.)
The INT1 instruction also uses a one-byte opcode (F1) and generates a debug exception (#DB) without setting any
bits in DR6.1 Hardware vendors may use the INT1 instruction for hardware debug. For that reason, Intel recom-
mends software vendors instead use the INT3 instruction for software breakpoints.
An interrupt generated by the INTO, INT3, or INT1 instruction differs from one generated by INT n in the following
ways:
• The normal IOPL checks do not occur in virtual-8086 mode. The interrupt is taken (without fault) with any IOPL
value.
• The interrupt redirection enabled by the virtual-8086 mode extensions (VME) does not occur. The interrupt is
always handled by a protected-mode handler.
• FRED event delivery uses event type 4 (software interrupt) for INT n but uses event type 5 (privileged software
exception) for INT1 and event type 6 (software exception) for INT3 and INTO.
(These features do not pertain to CD01, CD03, or CD04, the “normal” 2-byte opcodes for INT 1, INT 3, and INT 4,
respectively. Intel and Microsoft assemblers will not generate the CD03 opcode from any mnemonic, but this
opcode can be created by direct numeric code definition or by self-modifying code.)
The operation and use of these instructions depends significantly on whether FRED transitions have been enabled
by setting CR4.FRED. If CR4.FRED = 0, IDT event delivery is used; otherwise, FRED event delivery is used. The
following sections apply as indicated.
1. The mnemonic ICEBP has also been used for the instruction with opcode F1.
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Vol. 2A
3-467
With IDT Event Delivery
With IDT event delivery, the action of the INT n instruction (including the INTO, INT3, and INT1 instructions) is
similar to that of a far call made with the CALL instruction. The primary difference is that with the INT n instruction,
the EFLAGS register is pushed onto the stack before the return address. (The return address is a far address
consisting of the current values of the CS and EIP registers.) Returns from interrupt procedures are handled with
the IRET instruction, which pops the EFLAGS information and return address from the stack.
Each of the INT n, INTO, and INT3 instructions generates a general-protection exception (#GP) if the CPL is greater
than the DPL value in the selected gate descriptor in the IDT. In contrast, the INT1 instruction can deliver a #DB
even if the CPL is greater than the DPL of descriptor 1 in the IDT. (This behavior supports the use of INT1 by hard-
ware vendors performing hardware debug.)
The vector specifies an interrupt descriptor in the interrupt descriptor table (IDT); that is, it provides index into the
IDT. The selected interrupt descriptor in turn contains a pointer to an interrupt or exception handler procedure.
In protected mode, the IDT contains an array of 8-byte descriptors, each of which is an interrupt gate, trap gate,
or task gate. In real-address mode, the IDT is an array of 4-byte far pointers (2-byte code segment selector and
a 2-byte instruction pointer), each of which point directly to a procedure in the selected segment. (Note that in
real-address mode, the IDT is called the interrupt vector table, and its pointers are called interrupt vectors.)
The following decision table indicates which action in the lower portion of the table is taken given the conditions in
the upper portion of the table. Each Y in the lower section of the decision table represents a procedure defined in
the “Operation” section for this instruction (except #GP).
Table 3-54. Decision Table
PE
0
1
1
1
1
1
1
1
VM
-
-
-
-
-
0
1
1
IOPL
-
-
-
-
-
-
<3
=3
DPL/CPL
-
DPL<
-
DPL>
DPL=
DPL<
-
-
RELATIONSHIP
CPL
CPL
CPL or C
CPL & NC
INTERRUPT TYPE
-
S/W
-
-
-
-
-
-
GATE TYPE
-
-
Task
Trap or
Trap or
Trap or
Trap or
Trap or
Interrupt
Interrupt
Interrupt
Interrupt
Interrupt
REAL-ADDRESS-MODE
Y
PROTECTED-MODE
Y
Y
Y
Y
Y
Y
Y
TRAP-OR-INTERRUPT-
Y
Y
Y
Y
Y
GATE
INTER-PRIVILEGE-LEVEL-
Y
INTERRUPT
INTRA-PRIVILEGE-LEVEL-
Y
INTERRUPT
INTERRUPT-FROM-
Y
VIRTUAL-8086-MODE
TASK-GATE
Y
#GP
Y
Y
Y
NOTES:
-
Don't Care.
Y
Yes, action taken.
Blank Action not taken.
S/W
Applies to INT n, INT3, and INTO, but not to INT1.
When the processor is executing in virtual-8086 mode, the IOPL determines the action of the INT n instruction. If
the IOPL is less than 3, the processor generates a #GP(selector) exception; if the IOPL is 3, the processor executes
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Vol. 2A
3-468
a protected mode interrupt to privilege level 0. The interrupt gate's DPL must be set to 3 and the target CPL of the
interrupt handler procedure must be 0 to execute the protected mode interrupt to privilege level 0.
The interrupt descriptor table register (IDTR) specifies the base linear address and limit of the IDT. The initial base
address value of the IDTR after the processor is powered up or reset is 0.
Refer to Chapter 6, “Procedure Calls, Interrupts, and Exceptions” and Chapter 18, “Control-flow Enforcement Tech-
nology (CET)” in the Intel® 64 and IA-32 Architectures Software Developer’s Manual, Volume 1, for CET details.
With FRED Event Delivery
When FRED transitions are enabled, all of these are events are delivered using FRED event delivery. Chapter 8,
“Flexible Return and Event Delivery (FRED)‚” in the Intel® 64 and IA-32 Architectures Software Developer’s
Manual, Volume 3 provides details. Like IDT event delivery, FRED event delivery is similar to a far call made with
the CALL instruction, but the FRED stack frame is different. Returns from FRED event delivery use either the ERETS
instruction or the ERETU instruction, depending on the CPL at the time of the original event.
FRED transitions can be enabled only in IA-32e mode. They cannot be enabled in real-address mode, protected
mode, or virtual-8086 mode. FRED event delivery does not use the IDT, and its operation thus does not depend on
any descriptor or DPL value or the value of IOPL.
Instruction ordering. Instructions following an INT n may be fetched from memory before earlier instructions
complete execution, but they will not execute (even speculatively) until all instructions prior to the INT n have
completed execution (the later instructions may execute before data stored by the earlier instructions have
become globally visible). This applies also to the INTO, INT3, and INT1 instructions, but not to executions of INTO
when EFLAGS.OF = 0.
Operation
The following operational description applies not only to the INT n, INTO, INT3, or INT1 instructions, but also to the
delivery of external interrupts, nonmaskable interrupts (NMIs), and exceptions. Some of these events push onto
the stack an error code.
The operational description specifies numerous checks whose failure may result in delivery of a nested exception.
In these cases, the original event is not delivered.
The operational description specifies the error code delivered by any nested exception. In some cases, the error
code is specified with a pseudofunction error_code(num,idt,ext), where idt and ext are bit values. The pseudofunc-
tion produces an error code as follows: (1) if idt is 0, the error code is (num & FCH) | ext; (2) if idt is 1, the error
code is (num « 3) | 2 | ext.
In many cases, the pseudofunction error_code is invoked with a pseudovariable EXT. The value of EXT depends on
the nature of the event whose delivery encountered a nested exception: if that event is a software interrupt (INT n,
INT3, or INTO), EXT is 0; otherwise (including INT1), EXT is 1.
IF PE = 0
THEN
GOTO REAL-ADDRESS-MODE;
ELSE (* PE = 1 *)
IF (EFLAGS.VM = 1 AND CR4.VME = 0 AND IOPL < 3 AND INT n)
THEN
#GP(0); (* Bit 0 of error code is 0 because INT n *)
ELSE
IF (EFLAGS.VM = 1 AND CR4.VME = 1 AND INT n)
THEN
Consult bit n of the software interrupt redirection bit map in the TSS;
IF bit n is clear
THEN (* redirect interrupt to 8086 program interrupt handler *)
Push EFLAGS[15:0];
(* if IOPL < 3, save VIF in IF position and save IOPL position as 3 *)
Push CS;
Push IP;
IF IOPL = 3
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Vol. 2A
3-469
THEN IF := 0; (* Clear interrupt flag *)
ELSE VIF := 0; (* Clear virtual interrupt flag *)
FI;
TF := 0; (* Clear trap flag *)
load CS and EIP (lower 16 bits only) from entry n in interrupt vector table referenced from TSS;
ELSE
IF IOPL = 3
THEN GOTO PROTECTED-MODE;
ELSE #GP(0); (* Bit 0 of error code is 0 because INT n *)
FI;
FI;
ELSE (* Protected mode, IA-32e mode, or virtual-8086 mode interrupt *)
IF (IA32_EFER.LMA = 0)
THEN (* Protected mode, or virtual-8086 mode interrupt *)
GOTO PROTECTED-MODE;
ELSE (* IA-32e mode interrupt *)
GOTO IA-32e-MODE;
FI;
FI;
FI;
FI;
REAL-ADDRESS-MODE:
IF ((vector_number « 2) + 3) is not within IDT limit
THEN #GP; FI;
IF stack not large enough for a 6-byte return information
THEN #SS; FI;
Push (EFLAGS[15:0]);
IF := 0; (* Clear interrupt flag *)
TF := 0; (* Clear trap flag *)
AC := 0; (* Clear AC flag *)
Push(CS);
Push(IP);
(* No error codes are pushed in real-address mode*)
CS := IDT(Descriptor (vector_number « 2), selector));
EIP := IDT(Descriptor (vector_number « 2), offset)); (* 16 bit offset AND 0000FFFFH *)
END;
PROTECTED-MODE:
IF ((vector_number « 3) + 7) is not within IDT limits
or selected IDT descriptor is not an interrupt-, trap-, or task-gate type
THEN #GP(error_code(vector_number,1,EXT)); FI;
(* idt operand to error_code set because vector is used *)
IF software interrupt (* Generated by INT n, INT3, or INTO; does not apply to INT1 *)
THEN
IF gate DPL < CPL (* PE = 1, DPL < CPL, software interrupt *)
THEN #GP(error_code(vector_number,1,0)); FI;
(* idt operand to error_code set because vector is used *)
(* ext operand to error_code is 0 because INT n, INT3, or INTO*)
FI;
IF gate not present
THEN #NP(error_code(vector_number,1,EXT)); FI;
(* idt operand to error_code set because vector is used *)
IF task gate (* Specified in the selected interrupt table descriptor *)
THEN GOTO TASK-GATE;
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Vol. 2A
3-470
ELSE GOTO TRAP-OR-INTERRUPT-GATE; (* PE = 1, trap/interrupt gate *)
FI;
END;
IA-32e-MODE:
IF INTO and CS.L = 1 (64-bit mode)
THEN #UD;
FI;
IF CR4.FRED = 0
THEN
IF ((vector_number « 4) + 15) is not in IDT limits
or selected IDT descriptor is not an interrupt-, or trap-gate type
THEN #GP(error_code(vector_number,1,EXT));
(* idt operand to error_code set because vector is used *)
FI;
IF software interrupt (* Generated by INT n, INT3, or INTO; does not apply to INT1 *)
THEN
IF gate DPL < CPL (* PE = 1, DPL < CPL, software interrupt *)
THEN #GP(error_code(vector_number,1,0));
(* idt operand to error_code set because vector is used *)
(* ext operand to error_code is 0 because INT n, INT3, or INTO*)
FI;
FI;
IF gate not present
THEN #NP(error_code(vector_number,1,EXT));
(* idt operand to error_code set because vector is used *)
FI;
GOTO TRAP-OR-INTERRUPT-GATE; (* Trap/interrupt gate *)
ELSE (* CR4.FRED = 1 *)
FRED event delivery of software interrupt, exception, hardware interrupt, or non-maskable interrupt;
END;
TASK-GATE: (* PE = 1, task gate *)
Read TSS selector in task gate (IDT descriptor);
IF local/global bit is set to local or index not within GDT limits
THEN #GP(error_code(TSS selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
Access TSS descriptor in GDT;
IF TSS descriptor specifies that the TSS is busy (low-order 5 bits set to 00001)
THEN #GP(error_code(TSS selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
IF TSS not present
THEN #NP(error_code(TSS selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
SWITCH-TASKS (with nesting) to TSS;
IF interrupt caused by fault with error code
THEN
IF stack limit does not allow push of error code
THEN #SS(EXT); FI;
Push(error code);
FI;
IF EIP not within code segment limit
THEN #GP(EXT); FI;
END;
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Vol. 2A
3-471
TRAP-OR-INTERRUPT-GATE:
Read new code-segment selector for trap or interrupt gate (IDT descriptor);
IF new code-segment selector is NULL
THEN #GP(EXT); FI; (* Error code contains NULL selector *)
IF new code-segment selector is not within its descriptor table limits
THEN #GP(error_code(new code-segment selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
Read descriptor referenced by new code-segment selector;
IF descriptor does not indicate a code segment or new code-segment DPL > CPL
THEN #GP(error_code(new code-segment selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
IF new code-segment descriptor is not present,
THEN #NP(error_code(new code-segment selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
IF new code segment is non-conforming with DPL < CPL
THEN
IF VM = 0
THEN
GOTO INTER-PRIVILEGE-LEVEL-INTERRUPT;
(* PE = 1, VM = 0, interrupt or trap gate, nonconforming code segment,
DPL < CPL *)
ELSE (* VM = 1 *)
IF new code-segment DPL ≠ 0
THEN #GP(error_code(new code-segment selector,0,EXT));
(* idt operand to error_code is 0 because selector is used *)
GOTO INTERRUPT-FROM-VIRTUAL-8086-MODE; FI;
(* PE = 1, interrupt or trap gate, DPL < CPL, VM = 1 *)
FI;
ELSE (* PE = 1, interrupt or trap gate, DPL ≥ CPL *)
IF VM = 1
THEN #GP(error_code(new code-segment selector,0,EXT));
(* idt operand to error_code is 0 because selector is used *)
IF new code segment is conforming or new code-segment DPL = CPL
THEN
GOTO INTRA-PRIVILEGE-LEVEL-INTERRUPT;
ELSE (* PE = 1, interrupt or trap gate, nonconforming code segment, DPL > CPL *)
#GP(error_code(new code-segment selector,0,EXT));
(* idt operand to error_code is 0 because selector is used *)
FI;
FI;
END;
INTER-PRIVILEGE-LEVEL-INTERRUPT:
(* PE = 1, interrupt or trap gate, non-conforming code segment, DPL < CPL *)
IF (IA32_EFER.LMA = 0) (* Not IA-32e mode *)
THEN
(* Identify stack-segment selector for new privilege level in current TSS *)
IF current TSS is 32-bit
THEN
TSSstackAddress := (new code-segment DPL « 3) + 4;
IF (TSSstackAddress + 5) > current TSS limit
THEN #TS(error_code(current TSS selector,0,EXT)); FI;
(* idt operand to error_code is 0 because selector is used *)
INT n/INTO/INT3/INT1-Call to Interrupt Procedure
Vol. 2A
3-472